Zhenzhen's AI Radar · MiniMax H3 · 2026-11-12 Morning Report
This issue features 13 new versions: Strongly Recommended 0 · Recommended 4 · Worth Watching 5 · Included Only 4
Editor's Note This issue reviews 13 new H3 versions: 0 S-tier, 4 A-tier, 5 B-tier, and 4 C-tier. The top recommendation is MiniMax Showrunner V3.1: write actors, scenes, and each shot in a single node, generate shot-by-shot, and assemble into a multi-shot final cut with dialogue. This version adds Relay VSR upscaling and fixes real-time preview. Simply Advanced v1.6 adds Force Video (locks input video to generate audio only, adding sound to existing videos), along with two style LoRAs—a pink neon outline and a 2017 Ghost in the Shell style—also listed as A-tier; 4 Persona voice LoRAs involve voice actor rights and the scene planner lacks visible examples, listed as B-tier; 4 original character ports as standard character LoRAs are listed as C-tier.
Recommended (4)
[A] MiniMax Showrunner: Pro-Grade Video Director | Professional-Grade Video Director. · V3.1 Relay VSR & Updates
Workflow · Version Update · Author lonecatone23 · Published 11-12 07:43 · Downloads 15
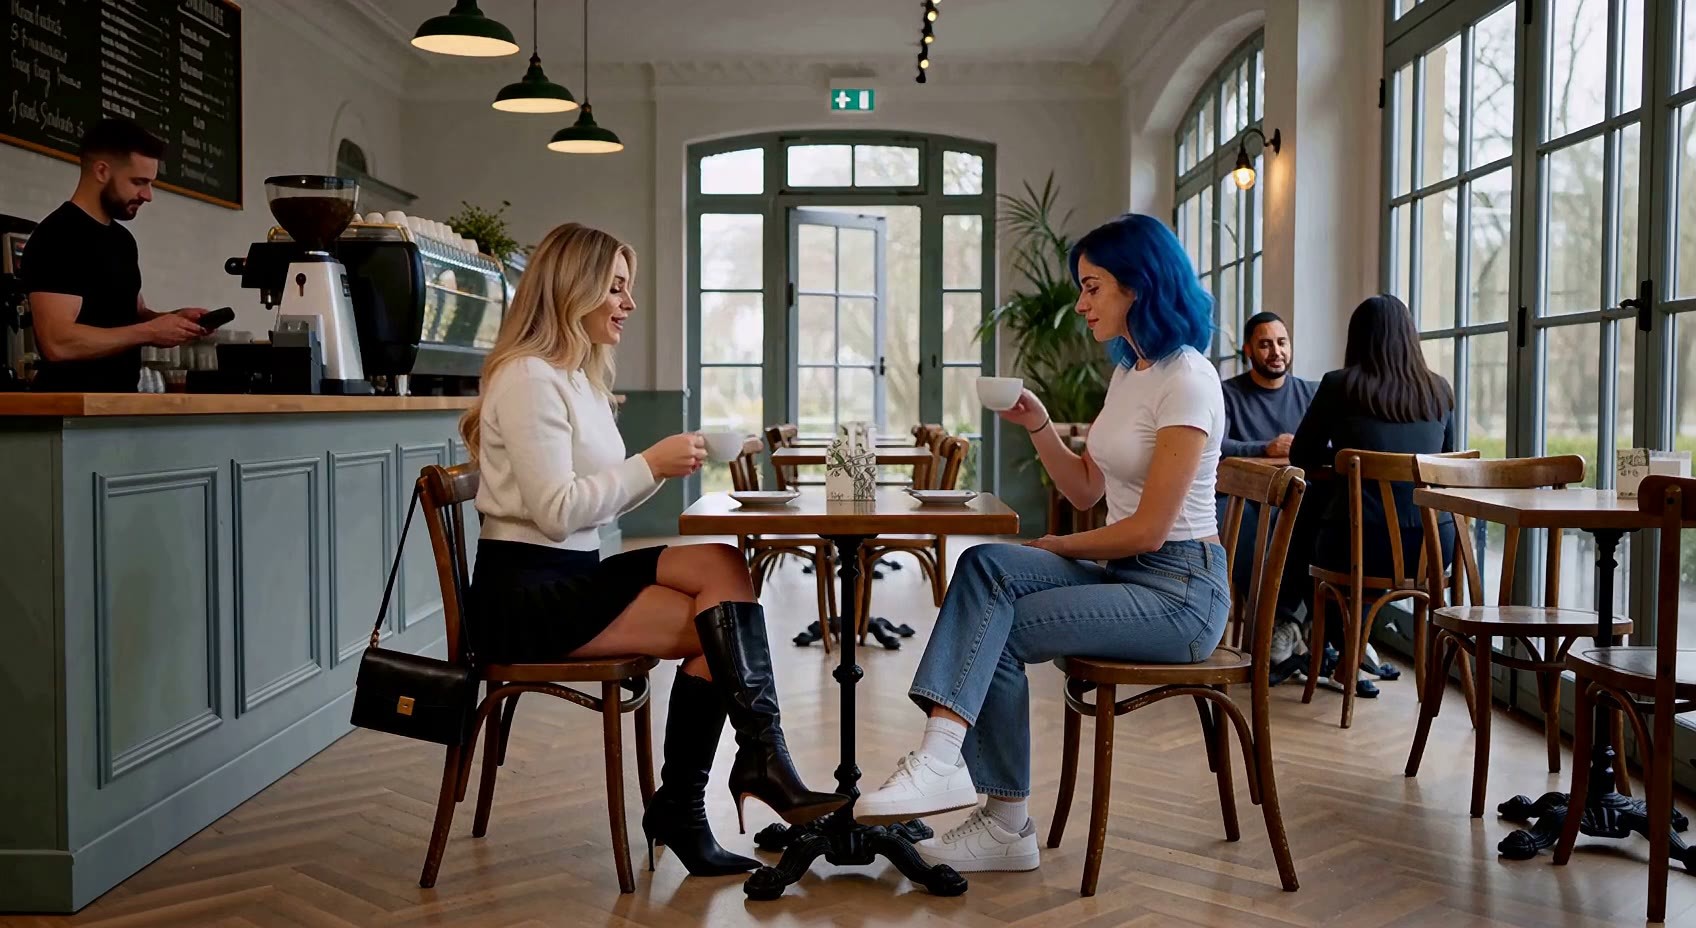
H3 multi-shot final cut workflow V3.1 that writes the entire film (actors, scenes, each shot) on a single node, with new Relay VSR upscaling.
Image
Reasons for Recommendation
- Version update: Added Relay VSR upscaling; because the old version broke after the upstream Live Preview node update, the author modified the preview section, installed the VAE required for this upscaling, and fixed node comments
- The workflow itself creates continuous multi-shot final cuts: generates shots one by one and assembles them into a film with sound and dialogue; maintains character consistency using avatars, costume images, and first-shot memory, allows redoing individual shots, supports attaching character/costume/style LoRAs to single shots, and supports 360 panoramic scenes so reverse shots remain in the same room
- The post-processing section includes frame interpolation to 48 fps, RTX deblurring and upscaling, and audio processing; includes 1 visible example videos and 1 images
How to Use
- Import MMH3 Showrunner V3.1.json; the author's four node packages LC123, AV, Vision, and maskmaker must all be updated to the latest version. If ComfyUI Manager is slow to list them, install directly from the author's GitHub
- The author recommends running the built-in example story directly without changing any settings first, then following the guided tutorial in the Vision Assistant; parameters such as sampling steps are found in the user guide and prompt guide on the author's GitHub
Risks and Limitations
- Depends on the author's own 4 node packages; it won't run if nodes are missing or versions are incorrect; the Size Requirements section in the description is empty, and VRAM requirements are not stated
- What exactly Relay VSR is as an upscaler is not specified; the description only provides a link, and the content is not visible in the API
- This update note is very short, mainly consisting of fixes; the previous version on the page was V2.5.2, and intermediate versions were not released separately
- 1 examples are hidden
[A] Neon BlackPink: Pink Edge Glow Style [H3] · V1
LoRA · New Model · Author CitronLegacy · Published 11-12 07:19 · Downloads 17
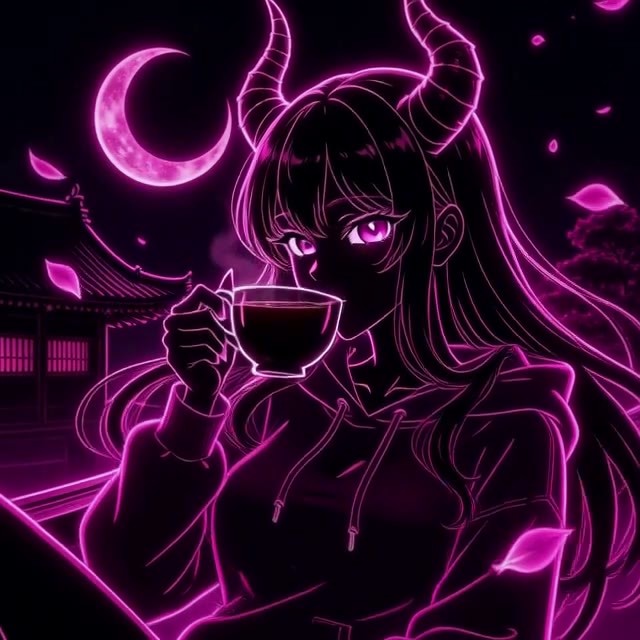
Pink neon outline style LoRA: compresses the image into a black background with pink light, or overlays a layer of pink edge glow on your specified color scheme.
Image
Reasons for Recommendation
- New model; serves stylization for text-to-video: the author claims all examples are pure text-to-video, requiring no first frame, and image-to-video should also work
- Training data consists only of pink neon videos, including some neon dance moves; the author claims audio was removed from the training set to minimize impact on H3's audio
- Trigger words and strength are provided, with 2 visible example videos
How to Use
- Strength 1.0; start the prompt with Anime style, n30nC1tron, neon-pink outlined
- If you don't want the black-pink color scheme, write colors as usual, and the LoRA will add pink outline glow on top
Risks and Limitations
- The author claims neon processing for other colors is poor, and dance moves are inferior to dedicated motion LoRAs
- 10 examples are hidden, with only 2 visible
- The license does not allow publishing derivative models
Trigger Words: n30nC1tron,, Anime style, n30nC1tron, neon-pink outlined,
[A] Simply Advanced - MiniMax H3 · v1.6
Workflow · Version Update · Author altoiddealer · Published 11-12 05:56 · Downloads 25
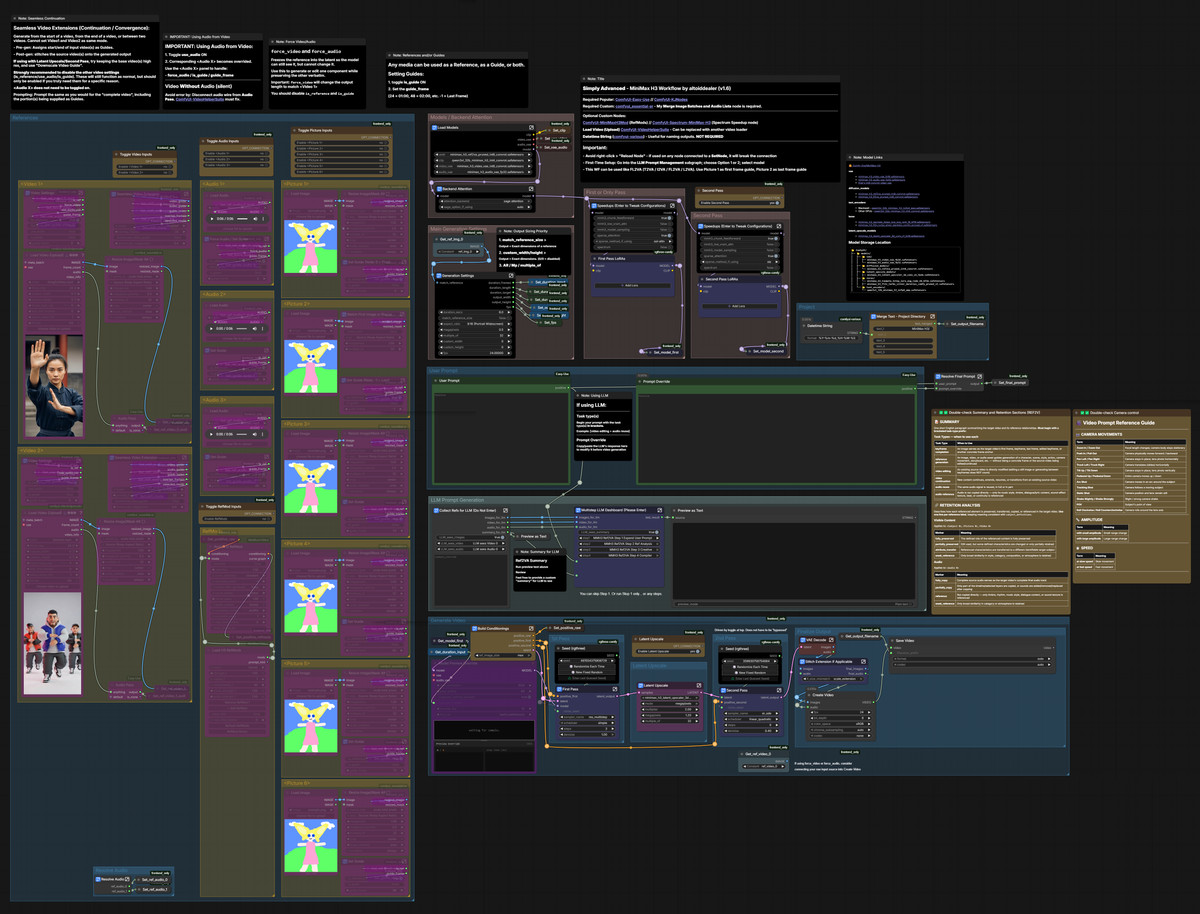
Full-featured H3 workflow v1.6: adds Force Video, locking the input video's visuals to generate audio only, effectively adding sound to existing videos.
Image
Reasons for Recommendation
- Version update: Added Force Video (freezes video latent, the model still "looks at" your video, generating audio only); fixed an issue where video continuation/convergence saved the video three times repeatedly after a certain ComfyUI update, and a wiring error in convergence mode; upscaling now uses ComfyUI's native Latent Upscale, reducing the need for one custom node
- The workflow itself supports up to 6 images, 2 videos, and 3 audio tracks, with each path settable as reference, guidance, or both; can continue from an input video, converge to the end of a video, or fill in the middle between two videos
- Built-in LLM prompt expansion from 1–4 steps: ref2va goes through expansion, reference analysis, creative blueprint, and compilation into H3 format in four steps; fl2va does one-step expansion, automatically determining the mode based on whether image 1 / image 2 are present
How to Use
- Import simply-advanced_minimax_h3_v1.6.json; must install ComfyUI-Easy-Use, ComfyUI-KJNodes, and the author's comfyui_essential-er
- Enable Force Video when adding sound to an existing video; select the mode for continuation/convergence in Seamless Extension; the author did not provide parameters such as sampling steps in the description
Risks and Limitations
- The author explicitly states that comfyui-frontend must be lower than v1.50.5; if the frontend version is incorrect, dropdowns in subgraphs will break
- Only 1 visible example images, no video examples; there are no examples of Force Video's effect
[A] Ghost In The Shell (2017) Style Lora - H3 · v1.0
LoRA · New Model · Author Lainier · Published 11-12 00:34 · Downloads 97
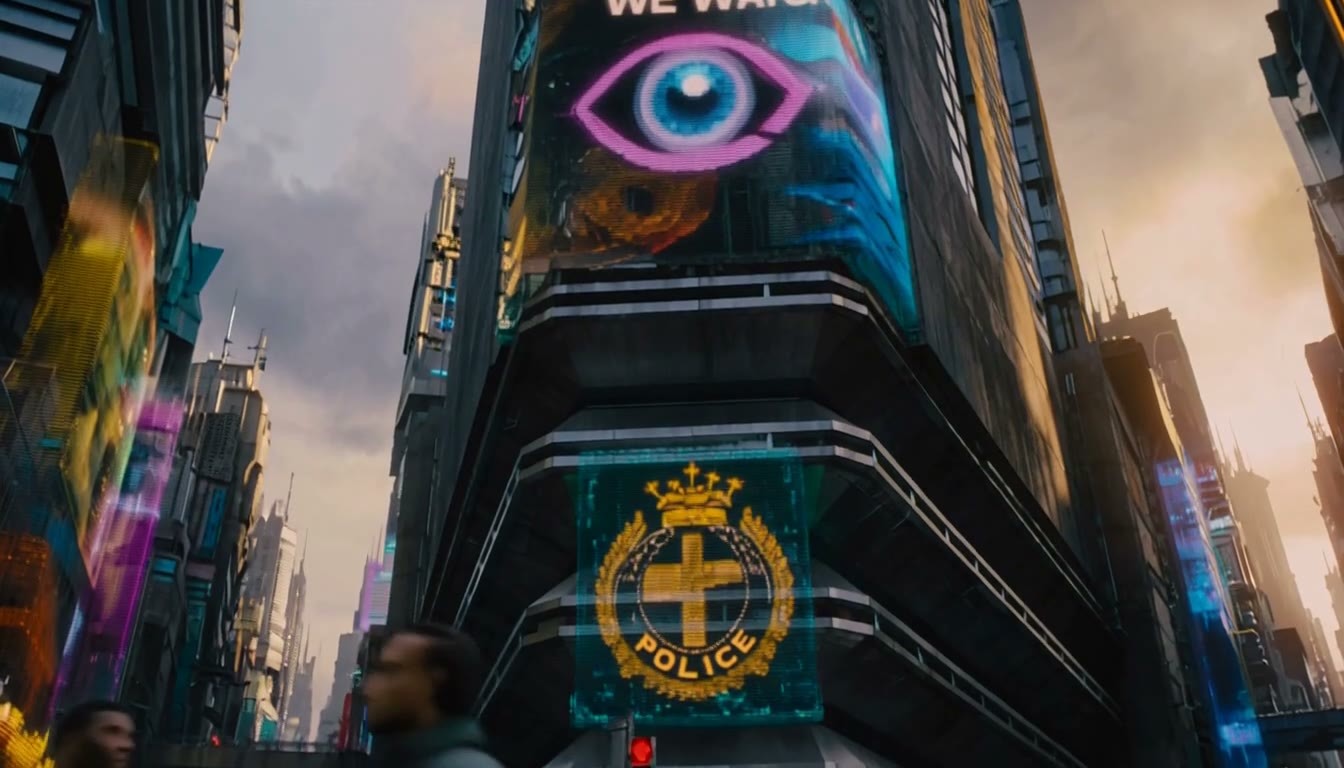
H3 style LoRA recreating the visual style of the 2017 live-action Ghost in the Shell film, targeted at fl2va text-to-video.
Image
Reasons for Recommendation
- New model; serves text-to-video with a cyberpunk cinematic feel: trained on 16:9 visuals, the author confirms it works for fl2va, but ref2va was not tested (the author plans to train a separate ref2va version)
- Trigger words and strength are provided; examples were generated on the fp8 base model, without acceleration LoRAs, using Spectrum nodes
- 97 downloads in 9 hours since release, indicating only attention level; 1 visible example videos
How to Use
- Write gits2017 in the prompt, strength 0.9; outputting in 16:9 landscape format is closer to the training data
Risks and Limitations
- The author claims this is their first style LoRA and the effect is average
- 5 examples are hidden, with only 1 visible; there are no examples of performance when paired with turbo/acceleration LoRAs
Trigger Words: gits2017
Worth Watching (5)
[B] Aigis / Aegis Voice - Persona 3 - Audio Only [Minimax H3] · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-12 06:30 · Downloads 22
H3 audio LoRA for Aegis's Japanese voice from Persona 3 Reload, changing only the speaking voice, not the visuals.
Image
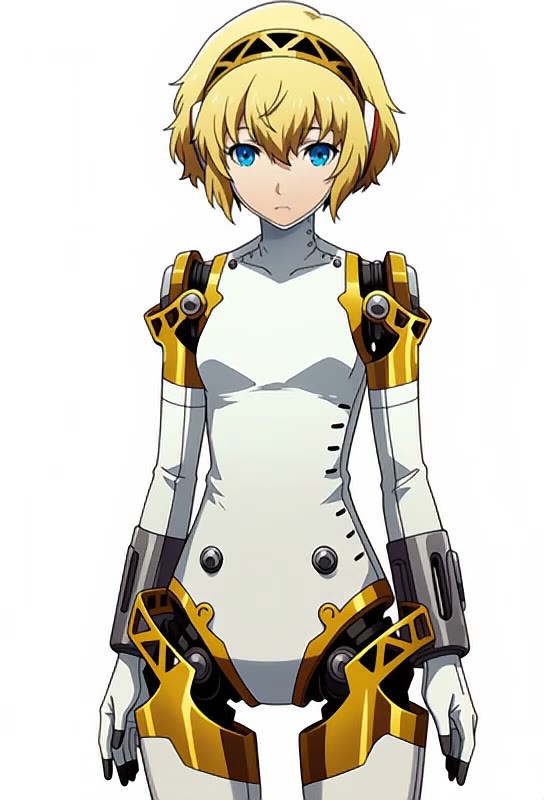
Reasons for Recommendation
- New model; serves character dubbing in H3 videos: trained on Aegis's Japanese voice lines from the game, the author claims the data covers emotions such as shy, nervous, confident, relaxed, happy, excited, and affectionate
- The dataset uses English descriptions and Japanese transcriptions; the author claims it can speak English lines too, but they will differ from the official English dub; 5 visible example videos, the most among this set of voice LoRAs
How to Use
- Write the prompt in the training format: Aigis says "<line>"; the author did not provide strength, and no trigger words are registered
Risks and Limitations
- Trained on commercial game character dubbing, involving voice actors' voice rights; the license does not list commercial use of outputs
[B] Kotone Shiomi / FeMC Voice - Persona 3 - Audio Only [Minimax H3] · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-12 06:45 · Downloads 18
H3 audio LoRA for Kotone Shiomi's Japanese voice, the female protagonist of Persona, changing only the speaking voice.
Image
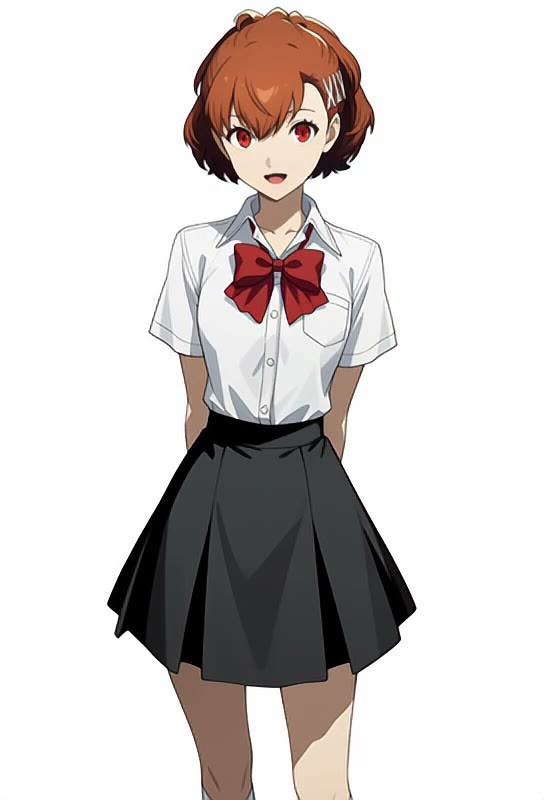
Reasons for Recommendation
- New model; serves character dubbing in H3 videos: trained on Kotone Shiomi's Japanese voice lines from the crossover event in Persona 5 Phantom X, the author claims it covers emotions such as shy, nervous, confident, happy, and excited
- Same approach as the author's Aegis and Elizabeth voice LoRAs: English descriptions + Japanese transcriptions, can also speak English lines; 4 visible example videos
How to Use
- Write the prompt in the training format: Kotone says "<line>"; the author did not provide strength, and no trigger words are registered
Risks and Limitations
- Trained on commercial game character dubbing, involving voice actors' voice rights; the license does not list commercial use of outputs
- Only 1 likes since release
[B] Elizabeth Voice - Persona 3 - Audio Only [Minimax H3] · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-12 06:00 · Downloads 26
An H3 audio LoRA for Elizabeth's Japanese voice from Persona 3 Reload, changing only the speaking voice.
Image
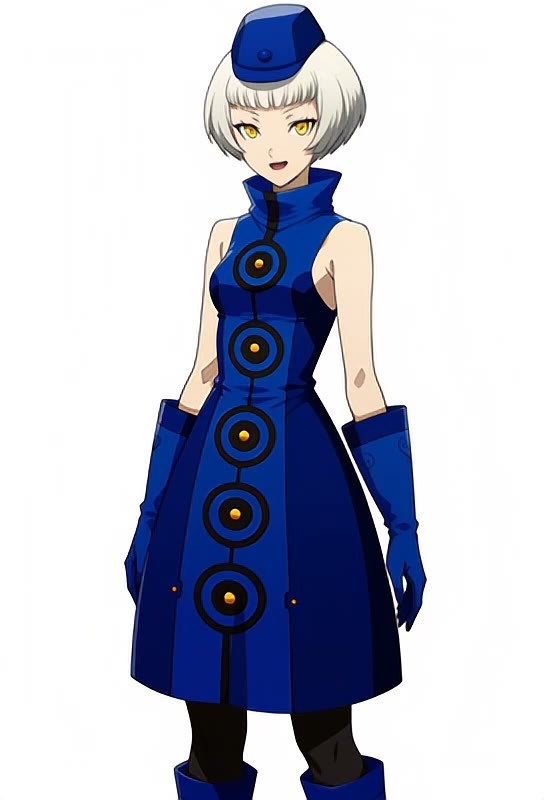
Reasons to Recommend
- New model; serves character dubbing in H3 videos: trained on Elizabeth's Japanese voice lines from the game, with the author claiming coverage of multiple emotions; training scripts lean towards her solemn, archaic manner of speaking
- Dataset includes English descriptions + Japanese transcriptions, with the author stating it can also speak English lines; example videos are visible in the 3 section
How to Use
- Write prompts in the training format: Elizabeth says "<line>"; strength is not specified by the author, and no trigger words are registered
Risks and Limitations
- Trained on voice acting for a commercial game character, involving voice actor rights; the license does not list commercial use of generated images
【B】Margaret Voice - Persona 4 - Audio Only [Minimax H3] · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-12 05:45 · Downloads 31
An H3 audio LoRA for Margaret's Japanese voice from Persona 4 / P4 Golden, changing only the speaking voice.
Image
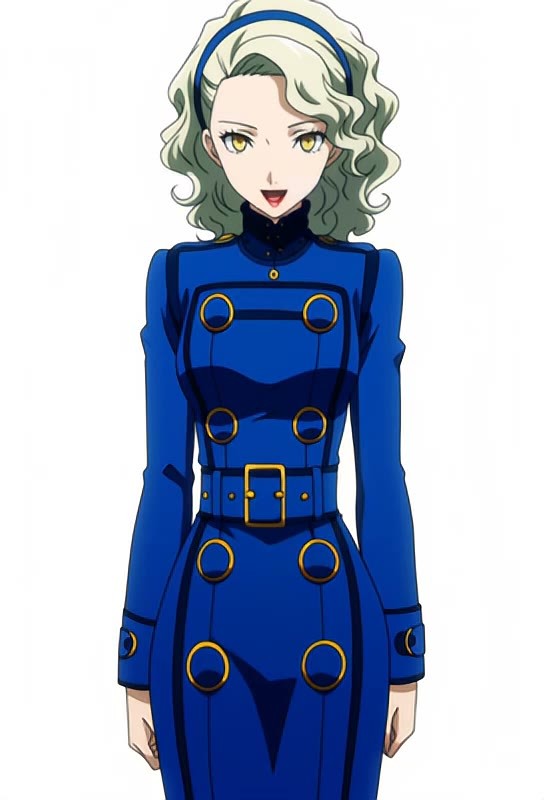
Reasons to Recommend
- New model; serves character dubbing in H3 videos: trained on Margaret's Japanese voice lines from the anime and game; unlike other entries in this series, the author did not specify which emotions are covered
- Dataset includes English descriptions + Japanese transcriptions, allowing it to speak English lines; example videos are visible in the 2 section
How to Use
- Write prompts in the training format: Margaret says "<line>"; strength is not specified by the author, and no trigger words are registered
Risks and Limitations
- Trained on voice acting for commercial anime / game characters, involving voice actor rights; the license does not list commercial use of generated images
- 1 examples are hidden
【B】Prophetero Scene Planner GLOBAL — H3 Public Beta · Version: 0.2.0-beta.1
Workflow · New Model · Author Prophetero · Published 11-12 04:17 · Downloads 25
An H3 scene planning page (public beta) for ComfyUI: arrange keyframe images, timestamps, prompts, and LoRAs, then export a new workflow to run.
Image
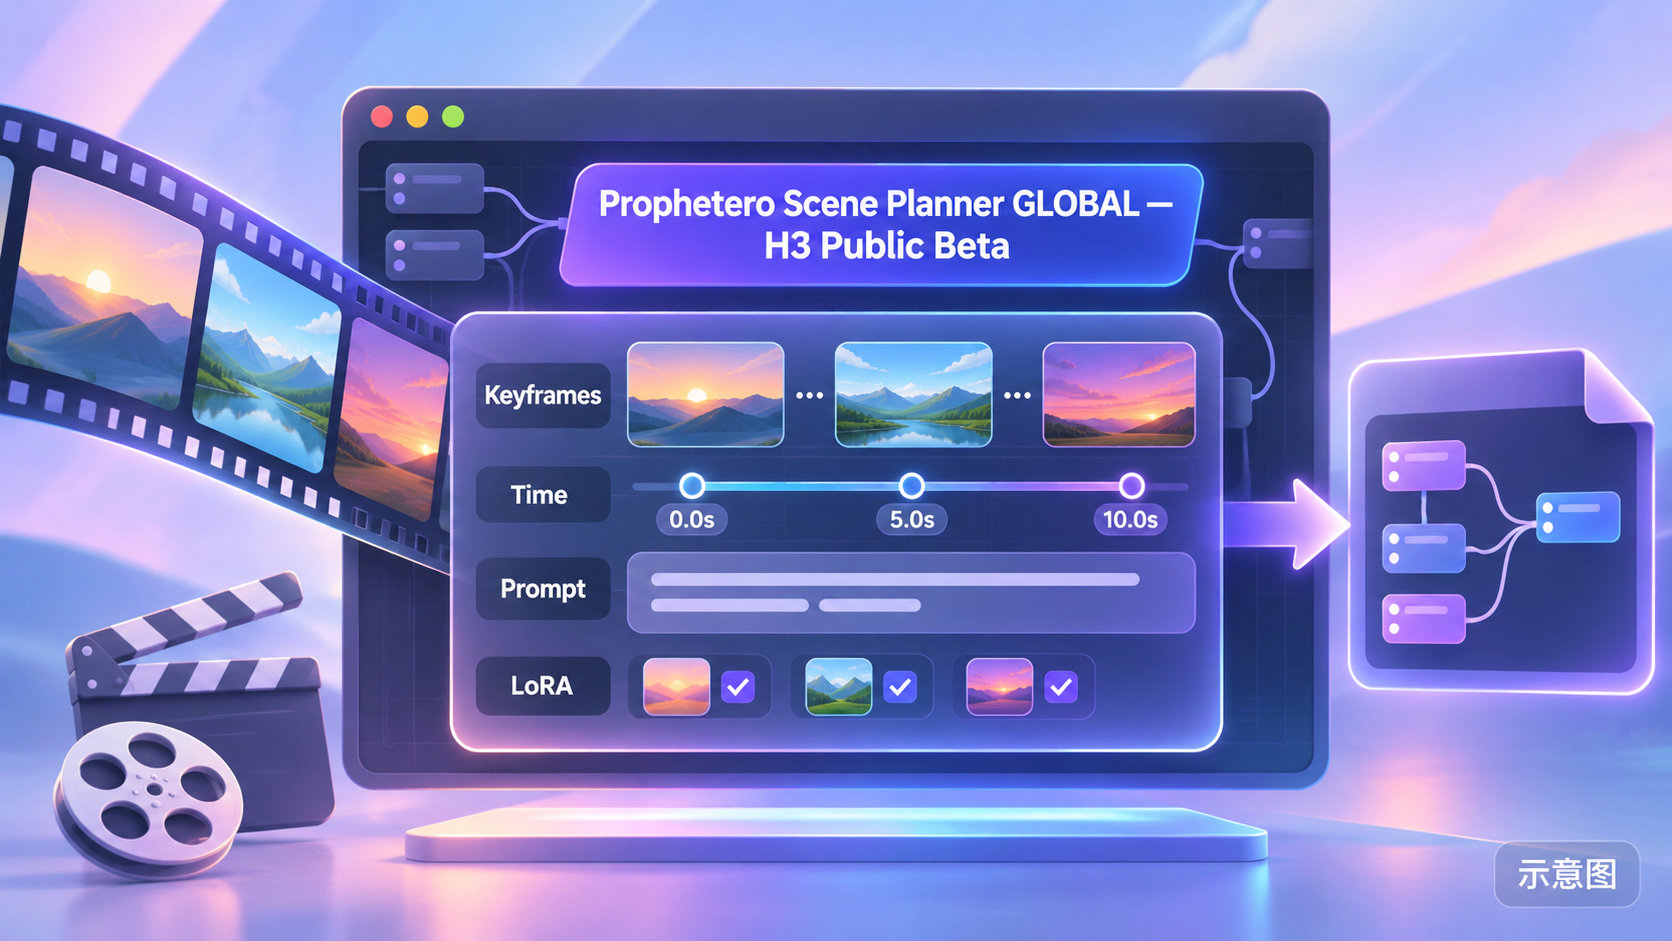
Reasons to Recommend
- New model (plugin + workflow companion tool, not weights; does not generate video itself): supports only the DaSiWa and Eros sets of H3 Simple / Pro workflows; reads the current image and plans within a single large page
- Supports up to 6 first-frame / intermediate-frame / last-frame images, with sorting, timing, and cropped previews; resolution presets include 1088 × 608; simultaneously displays your desired duration in seconds and the actual frame count and duration exported by H3; allows writing scene events and audio instructions (ambient sound, SFX, music, or silence) for specific time segments
- Allows searching, adding/removing LoRAs, and adjusting strength within the page; compares the original workflow with the planned version before export; optional local Ollama translation for prompts; interface available in 8 languages
How to Use
- Unzip the ZIP file, stop the ComfyUI backend first, run INSTALL.cmd selecting the directory containing main.py, then fully restart SwarmUI / ComfyUI; open via the H3 node or right-click menu on the canvas, and follow QUICKSTART_EN.md to create a short scene first
- Models, encoders, VAEs, and dependency nodes must be downloaded separately; see DEPENDENCIES.md in the package
Risk and Limitations
- Public beta; installer is a Windows .cmd file; unrecognized loaders or workflow structures are rejected outright
- No visible examples (1 hidden); the author states that keyframes and event timings are only guidance, with no guarantee that actions and sounds will appear on time, nor does it include dubbing, lip-syncing, or automatic transitions
- The license does not allow resale or paid bundling
- The card image is an AI-generated diagram, not the actual output of the model; the author has no publicly available standard-level examples
Included Only (4)
- Isobelle NordhavenLove · MiniMaxH3 — LoRA: Character LoRA for the original fictional female character Isobelle NordhavenLove, ported to H3 video from versions like MOSS Image on the same page.
- Annabelle Von Vergin · MiniMaxH3 — LoRA: Character LoRA for the original fictional female character Annabelle Von Vergin, ported to H3 video from multiple image base model versions on the same page.
- Edith Belwyn · MiniMaxH3 — LoRA: Character LoRA for the original fictional female character Edith Belwyn, ported to H3 video from multiple image base model versions on the same page.
- Lena Mossclaw · v1.0 H3 — LoRA: Character LoRA for the original catgirl character Lena Mossclaw, ported to H3 from versions like LTXV 2.3 and ZImageTurbo on the same page.
Data: Civitai public API (base model MiniMax H3), inclusion window 11-11 21:03 → 11-12 09:33 (Beijing Time). Recommendations are editorially reviewed; download counts reflect attention only.