Zhenzhen's AI Radar · MOSS Image · 2026-10-31 Morning Report
This issue features 59 new versions: Strongly Recommended 2 · Recommended 9 · Worth Watching 18 · Included Only 30
Editor's Note This issue reviews 66 new MOSS versions, with 2 rated S and 9 rated A. Top pick: North American Diesel Freight Trains LoRA v1.1: accurately renders locomotives by model, railway company liveries, and car numbers; includes complete settings for strength, steps, CFG, and prompt writing, with the author also listing limitations. Another S-rated entry is a medium format film style LoRA with trigger words and sample image parameters. A-rated entries include the MOSS-Image-SFT_clear base model (denoising and saturation boost; BF16 version; the three quantized versions are just format changes, rated B), a high-contrast lighting LoRA that flattens light, a bidirectional anime/realism slider, a general detail slider, and a figure texture LoRA. Downgrades: Kan Liu art style (imitating a living artist) downgraded from S to A; Lucid Trauma and realistic furry LoRAs downgraded from S to B because their MOSS version parameters were copied entirely from other base models; numerous standard character/person LoRAs, entries with only one line of description, or entries with all examples hidden are rated C.
Strongly Recommended (2)
[S] North American Diesel Freight Trains | MOSS-Image LoRA · v1.1
LoRA · Version Update · Author colinu · Published 10-31 06:33 · Downloads 13
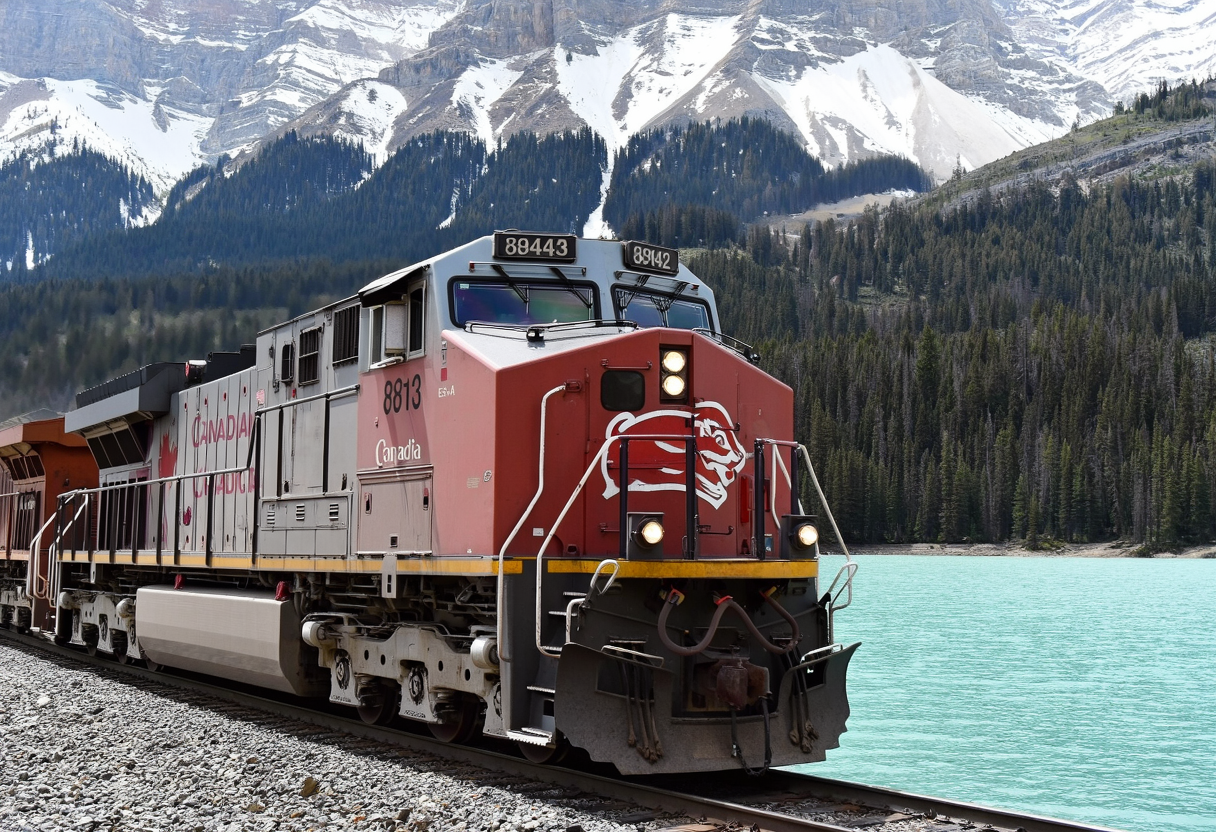
v1.1 of the North American Diesel Era Freight Train LoRA: enables MOSS to accurately render locomotive bodies by model, liveries of various railway companies, and various freight car types, producing realistic photographic compositions typical of railway enthusiasts; the author states v1.1 is sharper and more accurate in rendering locomotive models.
Maintained S: New capabilities are clear, examples are sufficient, parameters and prompt writing are complete, and the author proactively lists limitations; the subject matter is narrow, but within the scope of North American diesel freight, it is actionable.
Images
Reasons for Recommendation
- Version Update: Update note states v1.1 is sharper and more accurate in locomotive models; the full model card additionally notes significant improvement in bulkhead flatcars for v1.1, while v1.0 appears soft at strength 1.0
- Clear New Capabilities: The author lists 33 locomotive models (EMD, GE, ALCO/MLW), 13 car types, and liveries for railway companies such as Union Pacific, BNSF, and Santa Fe, capable of rendering car numbers and reporting marks; suitable for text-to-image generation involving railway themes, transportation scenes, and nostalgic railway photography
- Complete Parameters: Strength 1.0 (reduce to 0.7–0.8 if the image appears soft), 50 steps, CFG 3; the full card also provides sampler, Shift, resolution, and negative prompts, comparing the effects of Base vs. SFT
- 8 visible examples, no sensitive-level examples; free, license allows image generation, rental, on-site rental, and merging, with no attribution required; this version has approximately 3 hours since release with 13 downloads, while the entire model has accumulated 71 downloads (indicating popularity only)
How to Use
- Load na_diesel_freight_moss_v1.1.safetensors in a MOSS Base (used for training, author states it is closest to real railway photos, slightly softer) or SFT (author states it is sharper, with more accurate text and logos, but looks more like CG) workflow; no trigger word
- Strength 1.0, 50 steps, CFG 3; the full card recommends sampler euler, scheduler sgm_uniform, ModelSamplingSD3 Shift set to 5, banner resolution of approximately 1MP, and negative prompts for Base: sensitive content, worst quality, bad anatomy, watermark, jpeg artifact
- Write prompts like a railway enthusiast writing photo captions: manufacturer and model (e.g., EMD SD40-2, GE ES44AC), railway company and color scheme, car number or reporting marks, camera angle and scene; do not add quality words like masterpiece
Risks and Limitations
- Author's stated limitations: Railway logos and long strings of text sometimes garble; obscure or visually similar models may be confused (e.g., SW1500 rendered as GP type); coil cars remain unstable on Base
- Covers only North American diesel era freight; steam locomotives, passenger trains, and European/Asian vehicles are out of scope
- File is FP32, approximately 572 MB, larger than common LoRAs
- Railway company names and logos are trademarks of respective companies; commercial image generation requires caution
[S] waxa Medium Format Film Style · v1 Moss Base
LoRA · New Model · Author superkaero · Published 10-30 21:48 · Downloads 73
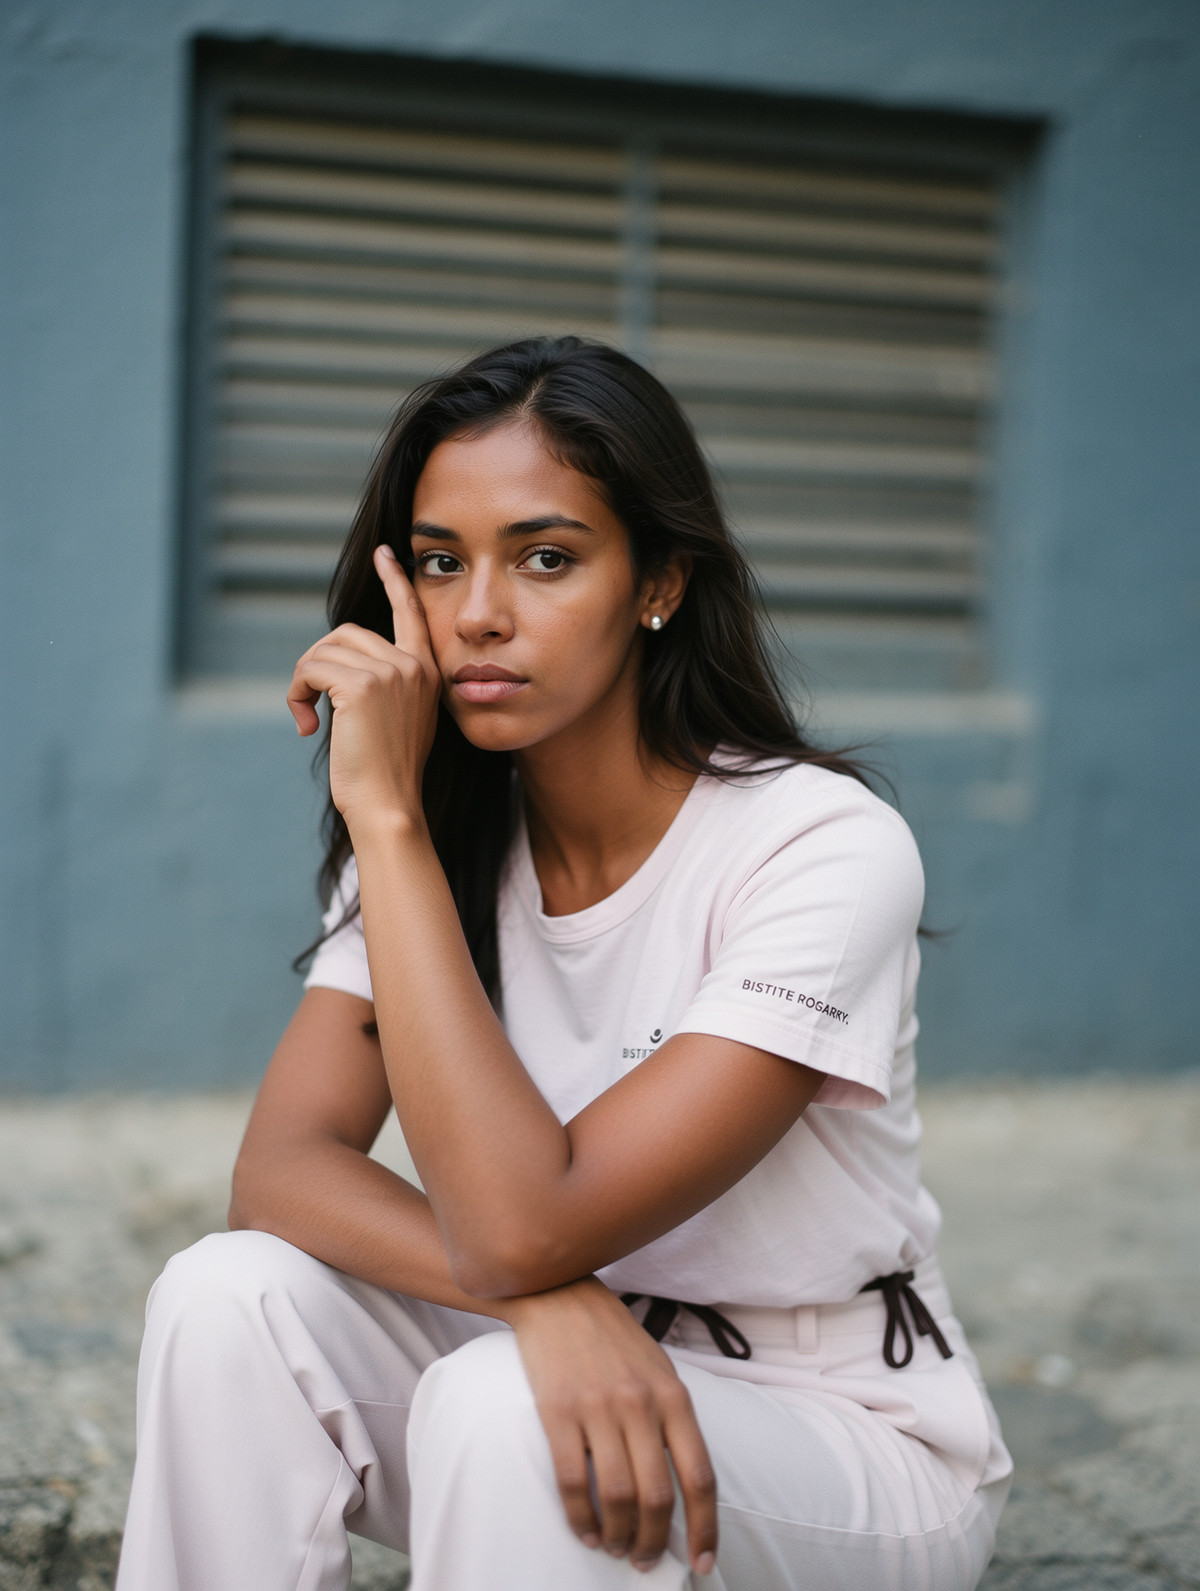
Medium format film photography style LoRA: The author states it reproduces the wide dynamic range, soft tonal transitions, and shallow depth of field blur of medium format film, pushing MOSS's realistic outputs toward the texture of film portraits / film landscapes.
Maintained S: Purpose is clear in one sentence, trigger words and sampling parameters are complete, examples are abundant, and the license is the most permissive; the only gap is the lack of strength and acceleration scheme details.
Images
Reasons for Recommendation
- New Model: A photography style LoRA trained on MOSS Base; the author states the training set consists of 98 curated medium format photography works; suitable for realistic text-to-image users seeking film texture without post-processing color grading
- Actionable: Trigger word "medium format film"; the author specifies all sample images were generated using euler_ancestral / simple / CFG 1 / 8 steps; the model card content is consistent across Chinese, English, and Japanese
- 13 visible examples; free, most permissive license: allows image generation, rental, sale, and sale of merges, with no attribution required
- Approximately 11 hours since release with 73 downloads and 6 likes (indicating popularity only)
How to Use
- Load waxa_MediumFormatFilm_Mosebase_v1.safetensors in a MOSS workflow, include the trigger word "medium format film" in the prompt, then describe the image content
- Follow sample image parameters: sampler euler_ancestral, scheduler simple, CFG 1, 8 steps; the author did not specify LoRA strength, start testing from 1
Risks and Limitations
- CFG 1 / 8 steps generally imply the use of an acceleration LoRA or distilled model, but the author did not specify whether sample images used direct Base output or added DMD acceleration; verify this yourself when reproducing
- The author did not specify LoRA strength; the source of training images (whether self-photographed by the author) is not stated
- 4 sensitive-level examples are hidden
Trigger Word: medium format film
Recommended (9)
[A] Kan Liu (666kArts) - Artist Style · MOSS-Image
LoRA · Ported · Author Azriaelis · Published 10-31 01:13 · Downloads 43
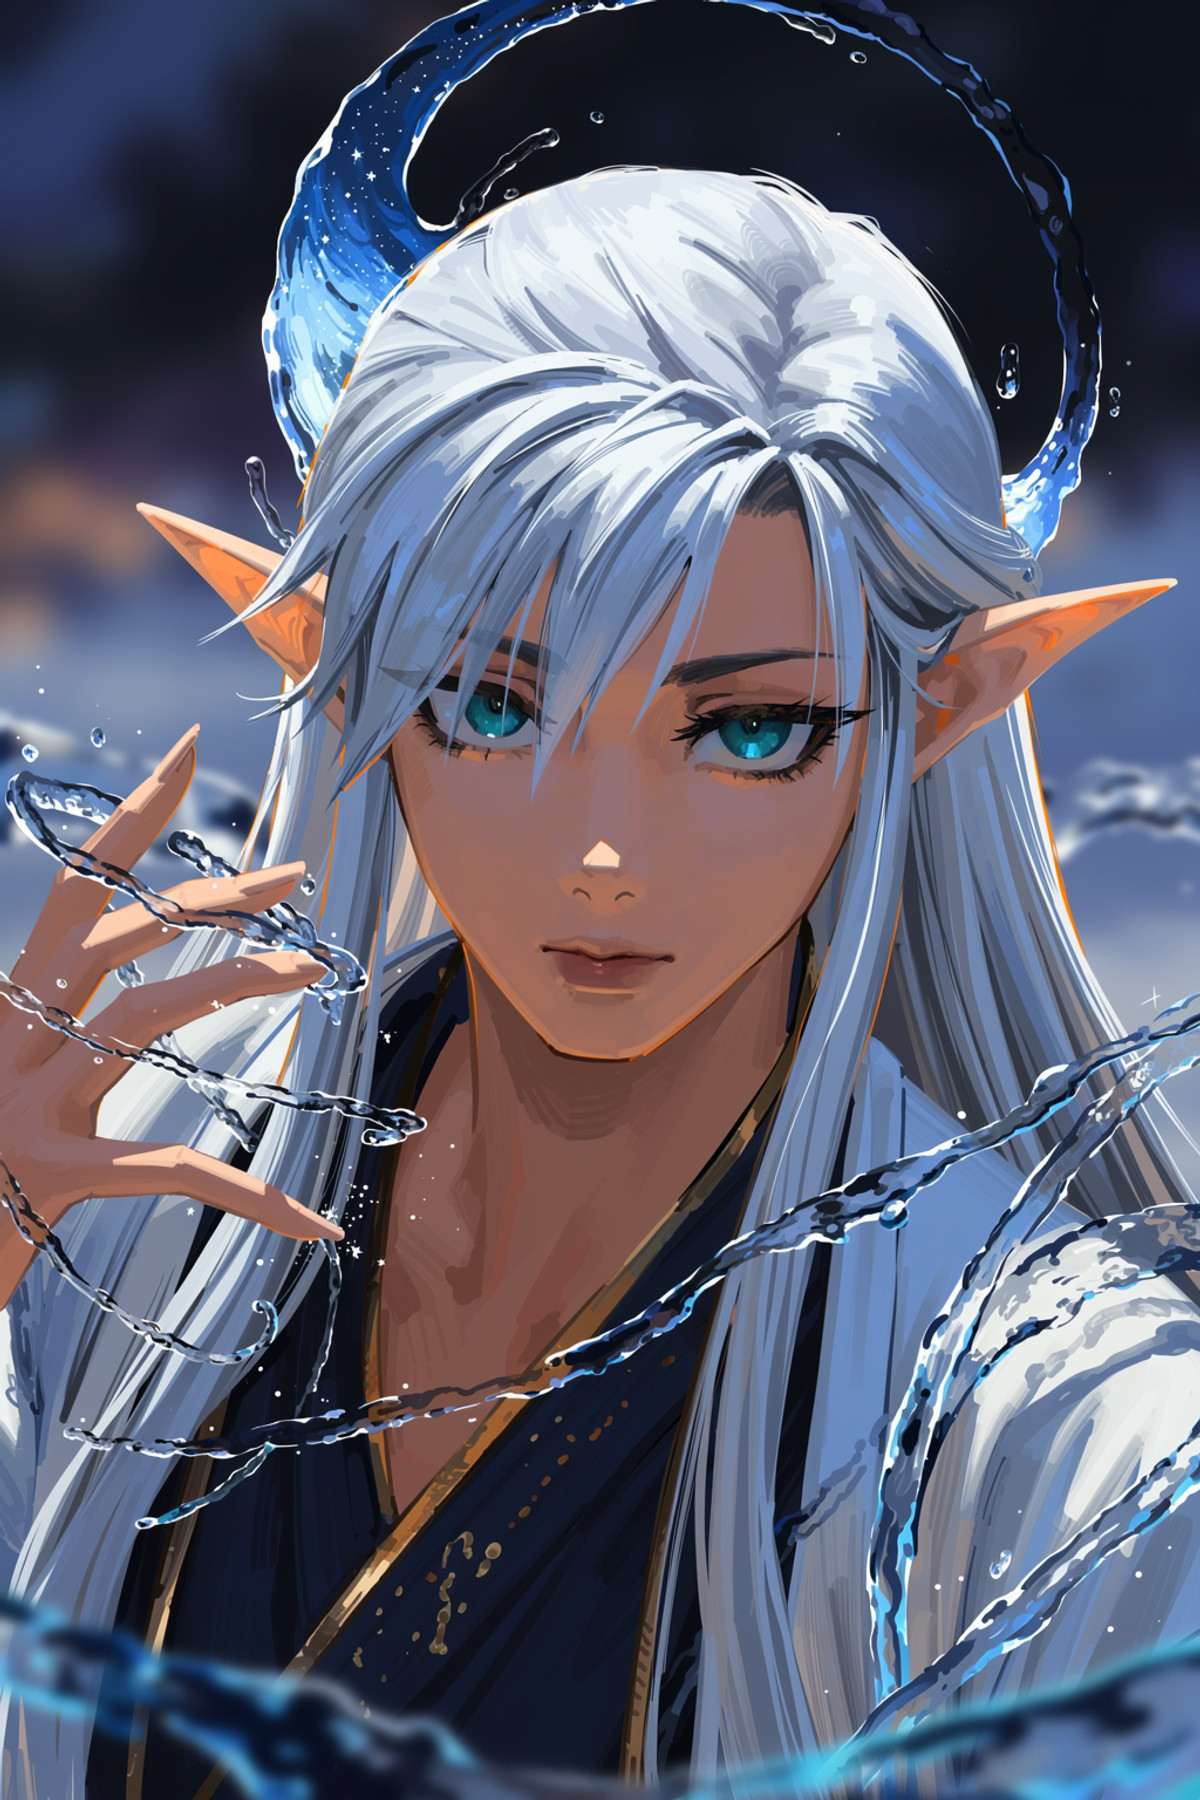
MOSS version of the art style LoRA for artist Kan Liu (666kArts): A painterly illustration style with brushstrokes and sketch-like qualities; the author states the style becomes significantly stronger when the trigger word is added.
Downgraded from S to A: MOSS parameters, trigger words, and examples are complete, but it is essentially a port of an artist style imitation, not a new capability, and there are artist authorization issues.
Images
Reasons for Recommendation
- Ported: Previous versions existed for Anima and Krea2Turbo; the MOSS version has an empty version note, but the model card contains a separate set of MOSS parameters
- Serves users wanting watercolor / brushstroke-style illustrations in MOSS text-to-image (tags include painterly, brushwork, sketch)
- MOSS Parameters: Use Base with 8 step turbo LoRA, euler + simple, LoRA strength 0.8-1, 8-16 steps, CFG 1-3
- 15 visible examples; free; approximately 8 hours since this version's release with 43 downloads, while the entire model has accumulated 801 downloads (indicating popularity only)
How to Use
- Load KANLIU-MOSS-V1 (1).safetensors in a MOSS Base workflow and connect a 8 step turbo/DMD acceleration LoRA; include the trigger word "@kan_liu_(666k)" in the prompt
- Sampler euler, scheduler simple, LoRA strength 0.8-1, 8-16 steps, CFG 1-3; the other two parameter sets on the card are for Anima and Krea2Turbo, do not mix them
Risks and Limitations
- Imitates the personal art style of a living artist; the author does not state whether authorization was obtained, so commercial use and public release require self-assessment
- License allows only image generation and on-site rental, not merging
- The MOSS version has no independent description, only a set of parameters in the model card; relies on an additional acceleration LoRA
- 5 sensitive-level examples are hidden
Trigger Word: @kan_liu_(666k)
[A] MOSS-Image-SFT_clear · BF16
Base Model / Checkpoint · New Model · Author easygoing0114 · Published 10-31 05:43 · Downloads 29
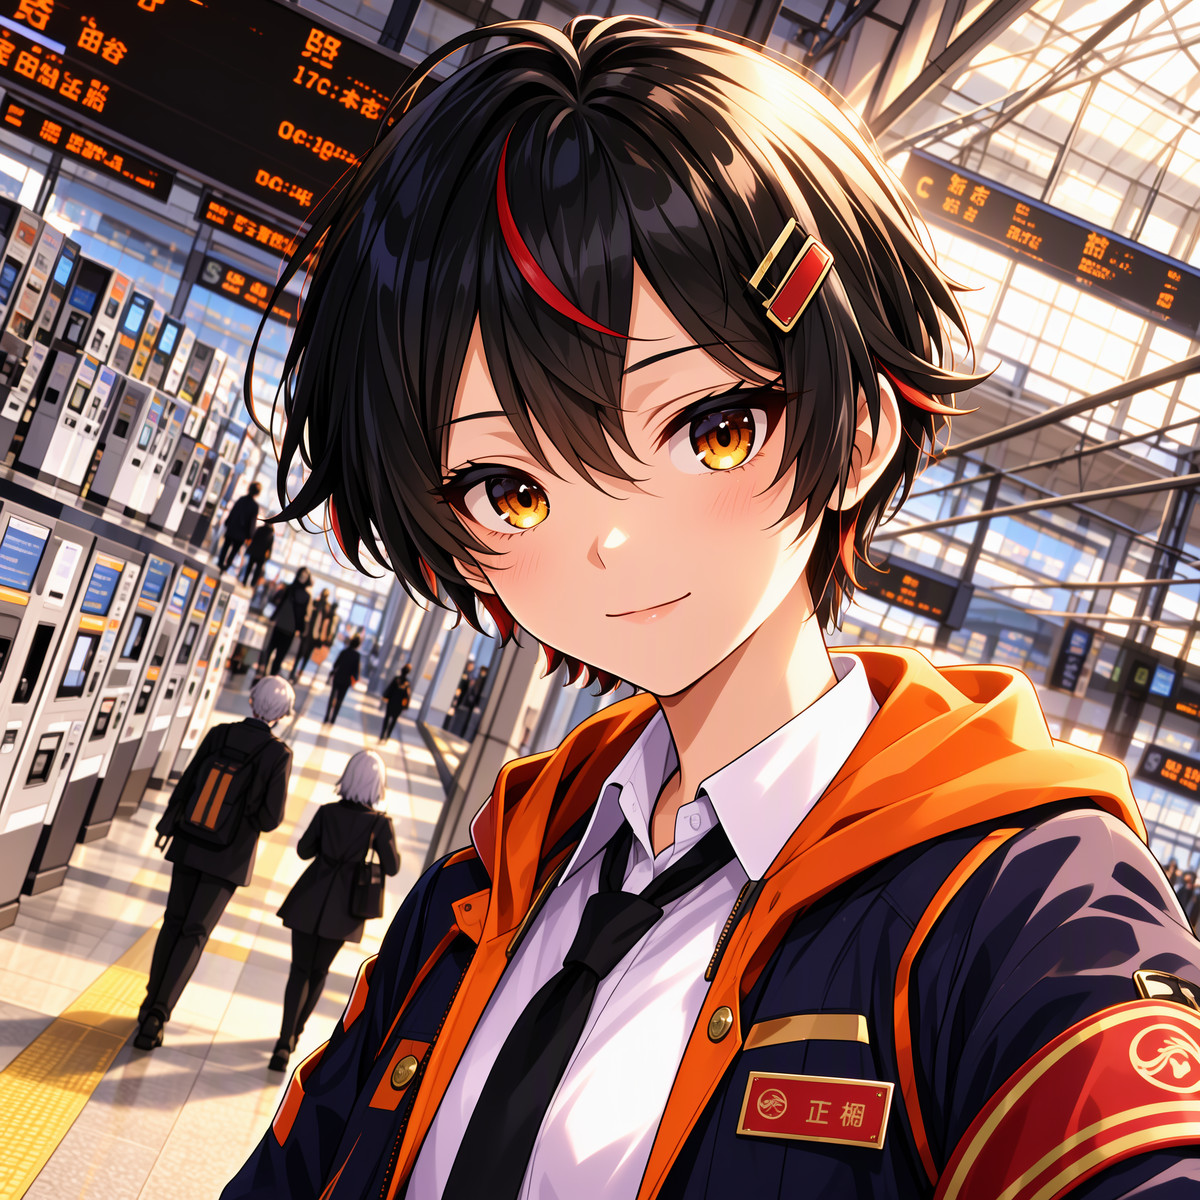
A denoised base model fine-tuned from the official MOSS-Image-SFT: The author states it has less image noise, clearer details, and higher saturation and contrast, particularly catering to anime illustrations; this entry is the full BF16 weights.
Downgraded from S to A: Parameters are complete, license is most permissive, and comparison images are provided, but it is a general image quality fine-tune rather than a new capability, and training details are not disclosed. Look at this entry first among the four files.
Images
Reasons for Recommendation
- New Model: A checkpoint that directly replaces the MOSS SFT base model; serves users who find the original SFT images gray and noisy, wanting cleaner and more vibrant anime illustrations or general text-to-image; the author placed side-by-side comparison images with the original SFT on the card
- Parameters fully documented: CFG 3-4, sampler euler, scheduler normal, 20-40 steps (approximately 30 steps); ComfyUI workflow PNG is on the author's Hugging Face
- The same model also released Int8ConvRot_HQ, MXFP8, and FP8_svd_scaled quantized files; the author wrote a separate comparison article for each format (off-site), allowing selection based on GPU and VRAM
- 4 visible examples; Apache-2.0 license, on-site license is also fully open (image generation, rental, sale, sale of merges, no attribution required); approximately 3 hours since this version's release with 29 downloads (indicating popularity only)
How to Use
- Download mossImageSFTClear_bf16.safetensors and place it in diffusion_models, replacing the MOSS SFT base model; the file contains only the diffusion model, text encoder and VAE remain from the original MOSS
- CFG 3-4, euler + normal, approximately 30 steps (adjust between 20-40); no trigger word; workflow can be downloaded as PNG from the author's Hugging Face and dragged into ComfyUI
Risks and Limitations
- The author does not state what data was used for fine-tuning or how much training was done, only providing a set of comparison images with the original
- The BF16 file is approximately 9.9 GB; if VRAM is insufficient, switch to the quantized versions of the same model
- The author did not write a version note; the NVFP4 version mentioned on the card has not been released yet
- 2 sensitive-level examples are hidden
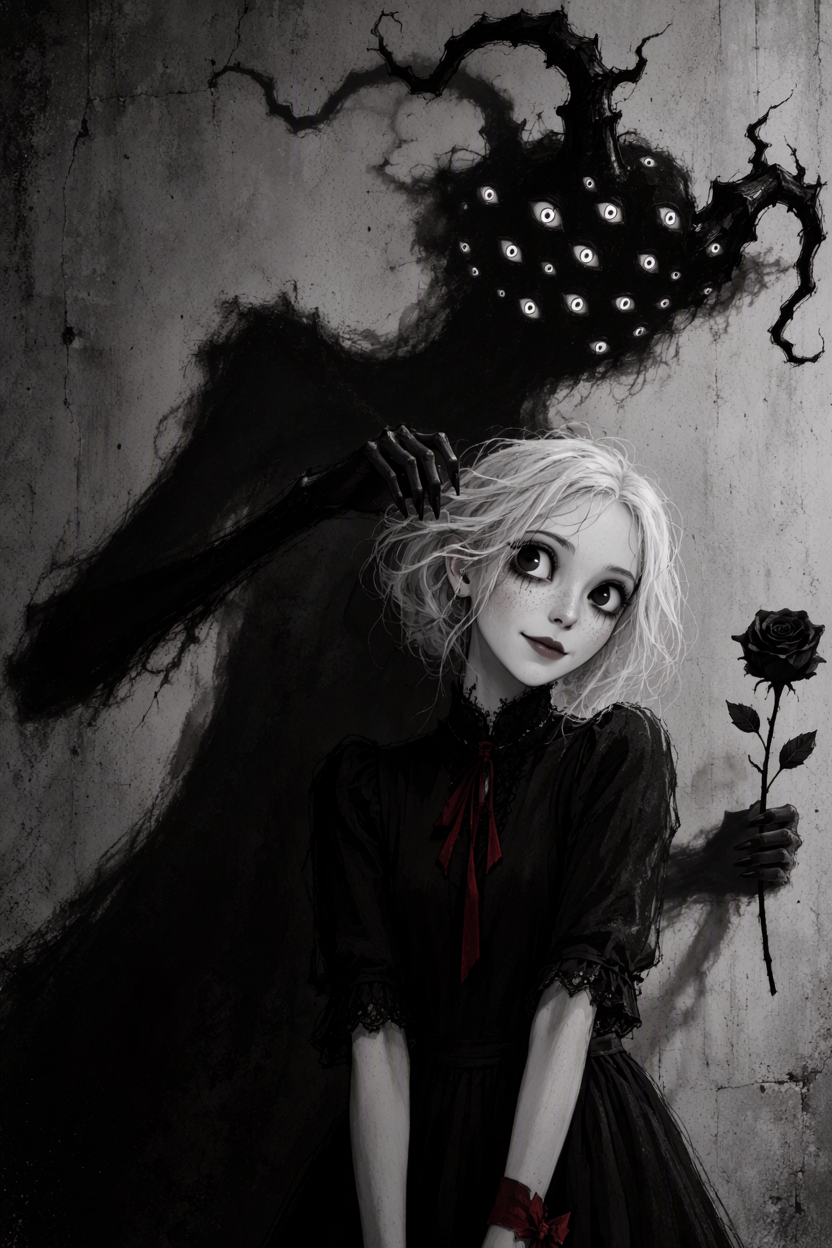
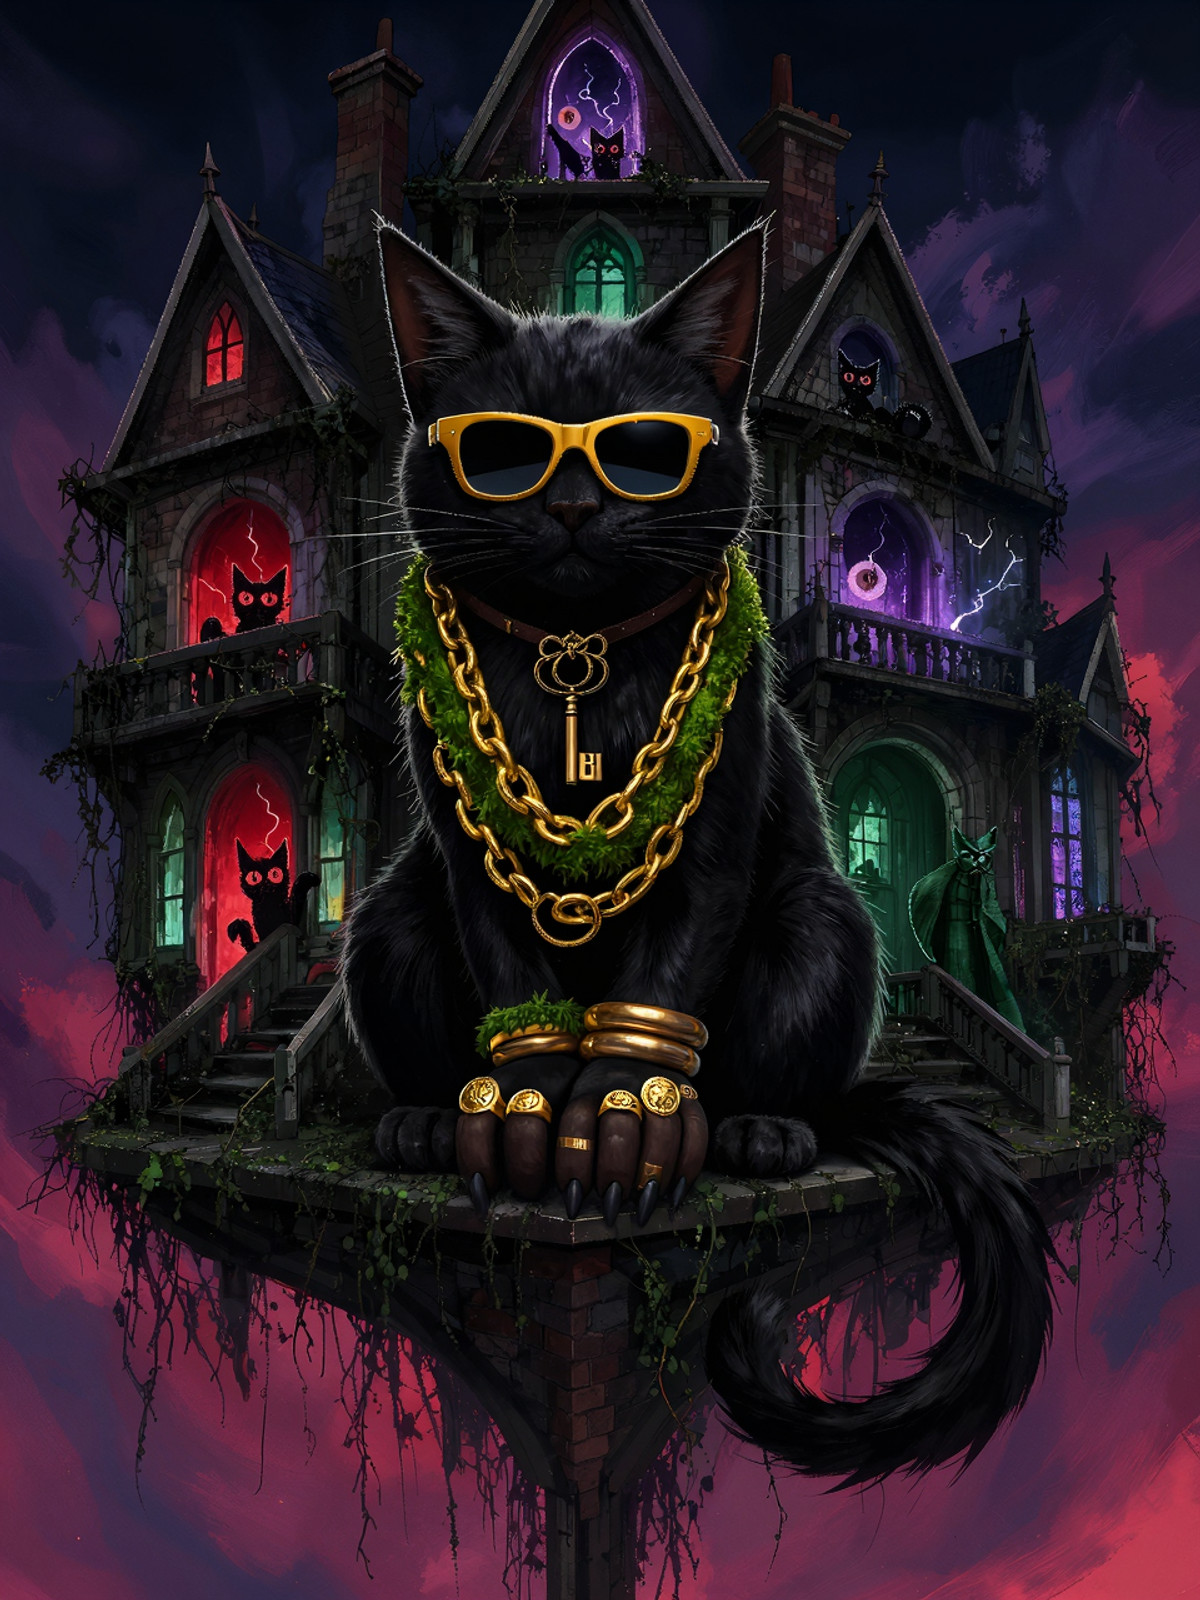
[A] [Black and White Mistique · v1.0 Moss] (https://civitai.com/models/3027236?modelVersionId=3439391)
LoRA · Port · Author Daalis · Published 10-30 22:15 · Downloads 49
The MOSS version of the "Black and White Mistique" art style LoRA: Based on high-contrast black and white, ink textures, and sparse accent colors, this is an illustration style leaning towards gothic surrealism, dark fantasy, and quirky humor; the author states it can also be used for full-color images.
Downgraded from S to A: Trigger words, strength tiers, and style descriptions are clear, but step counts and CFG are missing. The difference between the MOSS and Krea versions is described in only one sentence, and there are few examples.
Images
![Example 832x1248] (https://rh-images-switch.xiaoyaoyou.com/input/openapi/90c6531954803440041b2e4004e531ef9e1d17ca836326de17f7f84a5870ebde.png)
Reasons for Recommendation
- Port: Previously available as a Krea 2 Turbo version; the MOSS version description is just one sentence. The author states that MOSS overlays its own base style, but the training absorbed it well—meaning the MOSS and Krea versions will yield different results.
- Suitable for text-to-image generation for Halloween, horror, dark fantasy, grotesque creatures, and illustrations with contrasting humor; the author suggests trying monochrome with one vibrant accent color first, then trying full-color fantasy scenes.
- Trigger words and strength tiers are clearly defined: BWDaal; 0.5–0.8 for light effect, 1.0 is the author's recommended value, 1.2–1.5 lets the style dominate.
- 4 visible examples; free, license allows image generation, on-site rental, and merging, attribution optional; published about 11 hours ago with 49 downloads and 8 likes, cumulative downloads for the entire model are 122 (indicating popularity only).
How to Use
- Load BW Mistique Moss.safetensors in the MOSS workflow, include "BWDaal" in the prompt, start strength at 1.0, and adjust between 0.5–1.5.
- The author did not provide step counts, CFG, sampler, or whether to use Base or SFT.
Risks and Limitations
- The MOSS version has no dedicated parameters; the model card body contains generic instructions for various base models.
- The author states that MOSS brings its own stylistic tendencies, but does not explain specifically how they differ.
- Only 4 visible examples; 1 sensitive-level examples are hidden.
Trigger Word: BWDaal
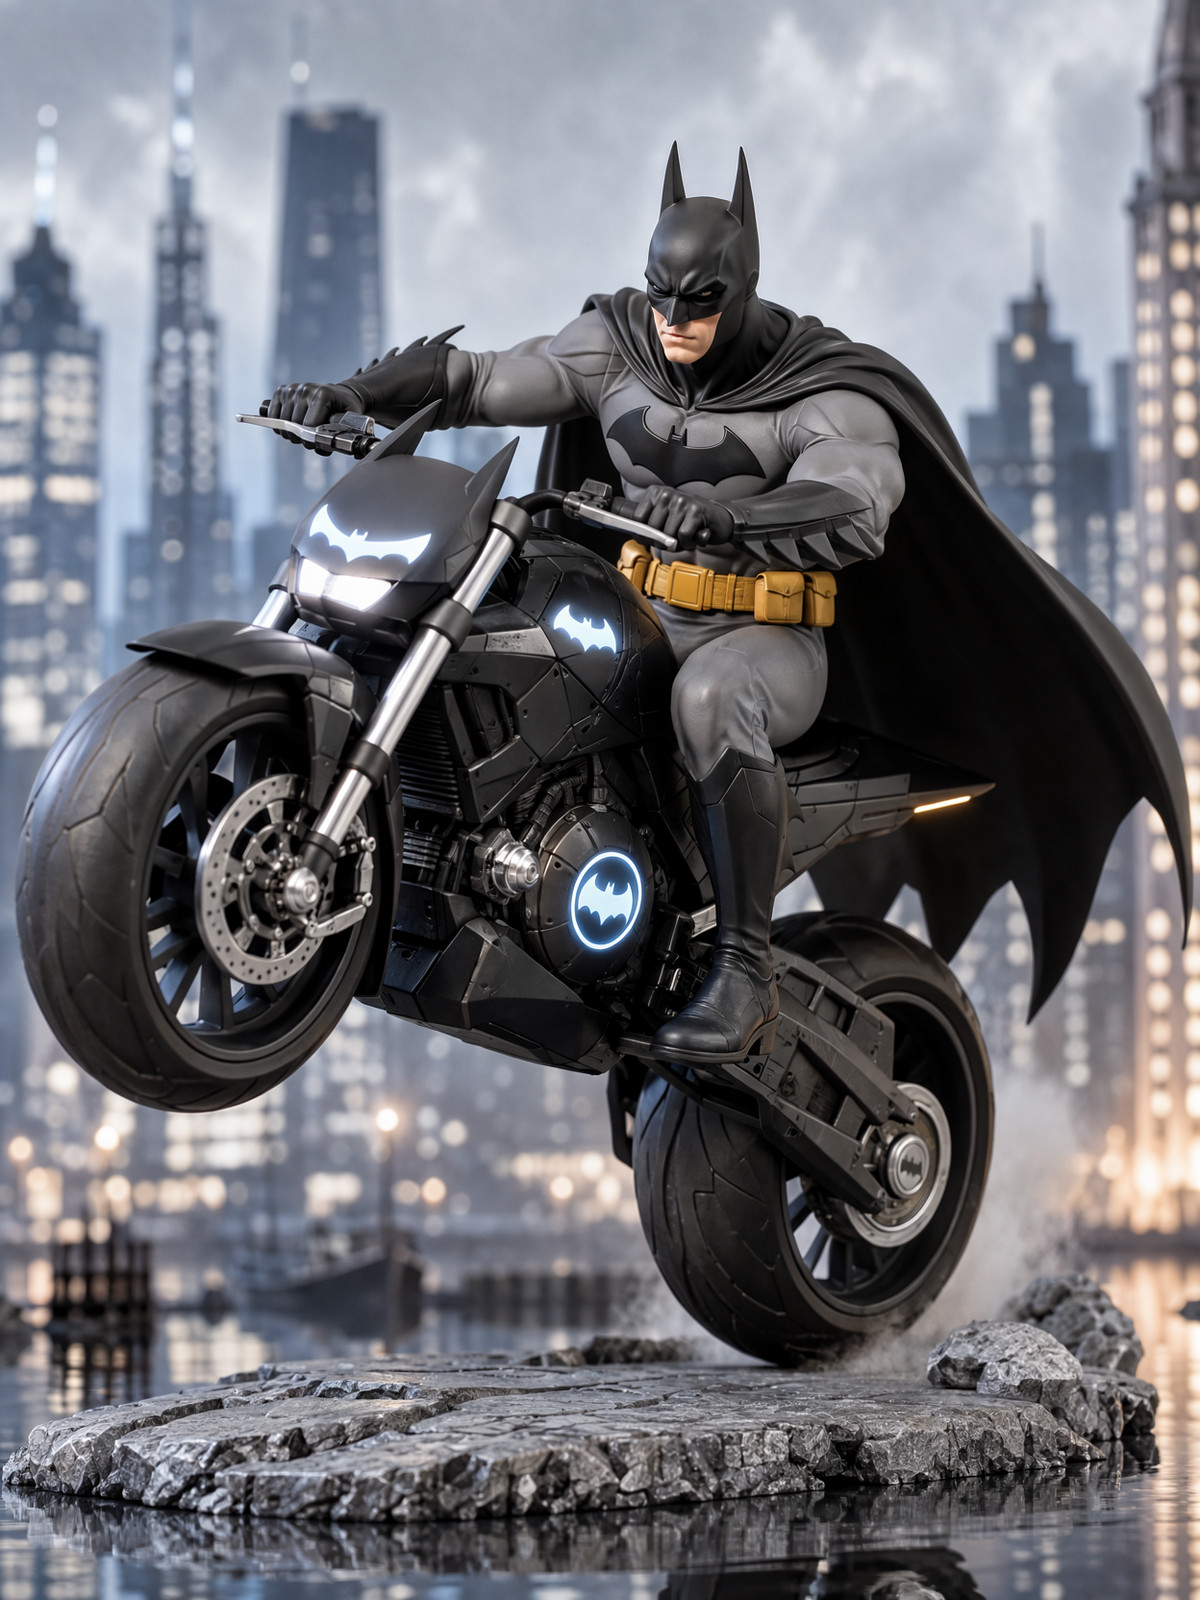
[A] [Figurine Style - Moss Image/ZIT · Figz_Style-MossV1] (https://civitai.com/models/2197855?modelVersionId=3440104)
LoRA · Port · Author ShadyNyaa · Published 10-31 06:00 · Downloads 51
The MOSS version of an art style LoRA that renders characters or figures with the texture of high-quality collectible figurines; the author states the training images are real photos of fantasy, sci-fi, and anime figurines.
Maintained at A: Purpose is clear, parameters are complete, and the license is permissive; however, there are only 1 public examples, and the majority are sensitive-level examples, so it does not reach S.
Images
![Example 1248x1664] (https://rh-images-switch.xiaoyaoyou.com/input/openapi/f2b5a9eea03cdbb2a6a12835064ca8e3ec84589d82aa65b8ef60ff69bb536bd9.jpg)
Reasons for Recommendation
- Port: Previously available as a Z Image Turbo version; the author explains that the MOSS version uses the same dataset, re-tagged and simplified, and is activated via the trigger word @figz style (the ZIT version had no trigger word during training).
- Serves text-to-image needs for figurizing existing characters or people, creating collectible display images, and merchandise concept art.
- MOSS parameters are complete: The author uses 40 steps, CFG 3.0, sampler res_2m + scheduler beta, strength 1.0; the 0.9 on the card is the strength for the ZIT version.
- Free, with the most permissive license: Allows image generation, rental, sales, and sales of merged models, attribution optional; this version was published about 3 hours ago with 51 downloads and 9 likes, cumulative downloads for the entire model are 692 (indicating popularity only).
How to Use
- Load figz_style-Moss.safetensors in the MOSS workflow, write "@figz style" in the prompt, strength 1.0.
- 40 steps, CFG 3.0, res_2m / beta; if you want the character to stand on a base, you must specify the base in the prompt.
Risks and Limitations
- Only 1 visible examples; 17 sensitive-level examples are hidden, making it nearly impossible to judge the effect from public examples.
- The base prompt advice and the note that "higher strength looks more plastic, lower looks more realistic" were written by the author for the ZIT version; it is not stated if this applies to the MOSS version.
- Training images are real manufacturer figurine photos; users must be mindful of copyright when generating copyrighted character designs.
Trigger Word: @figz style
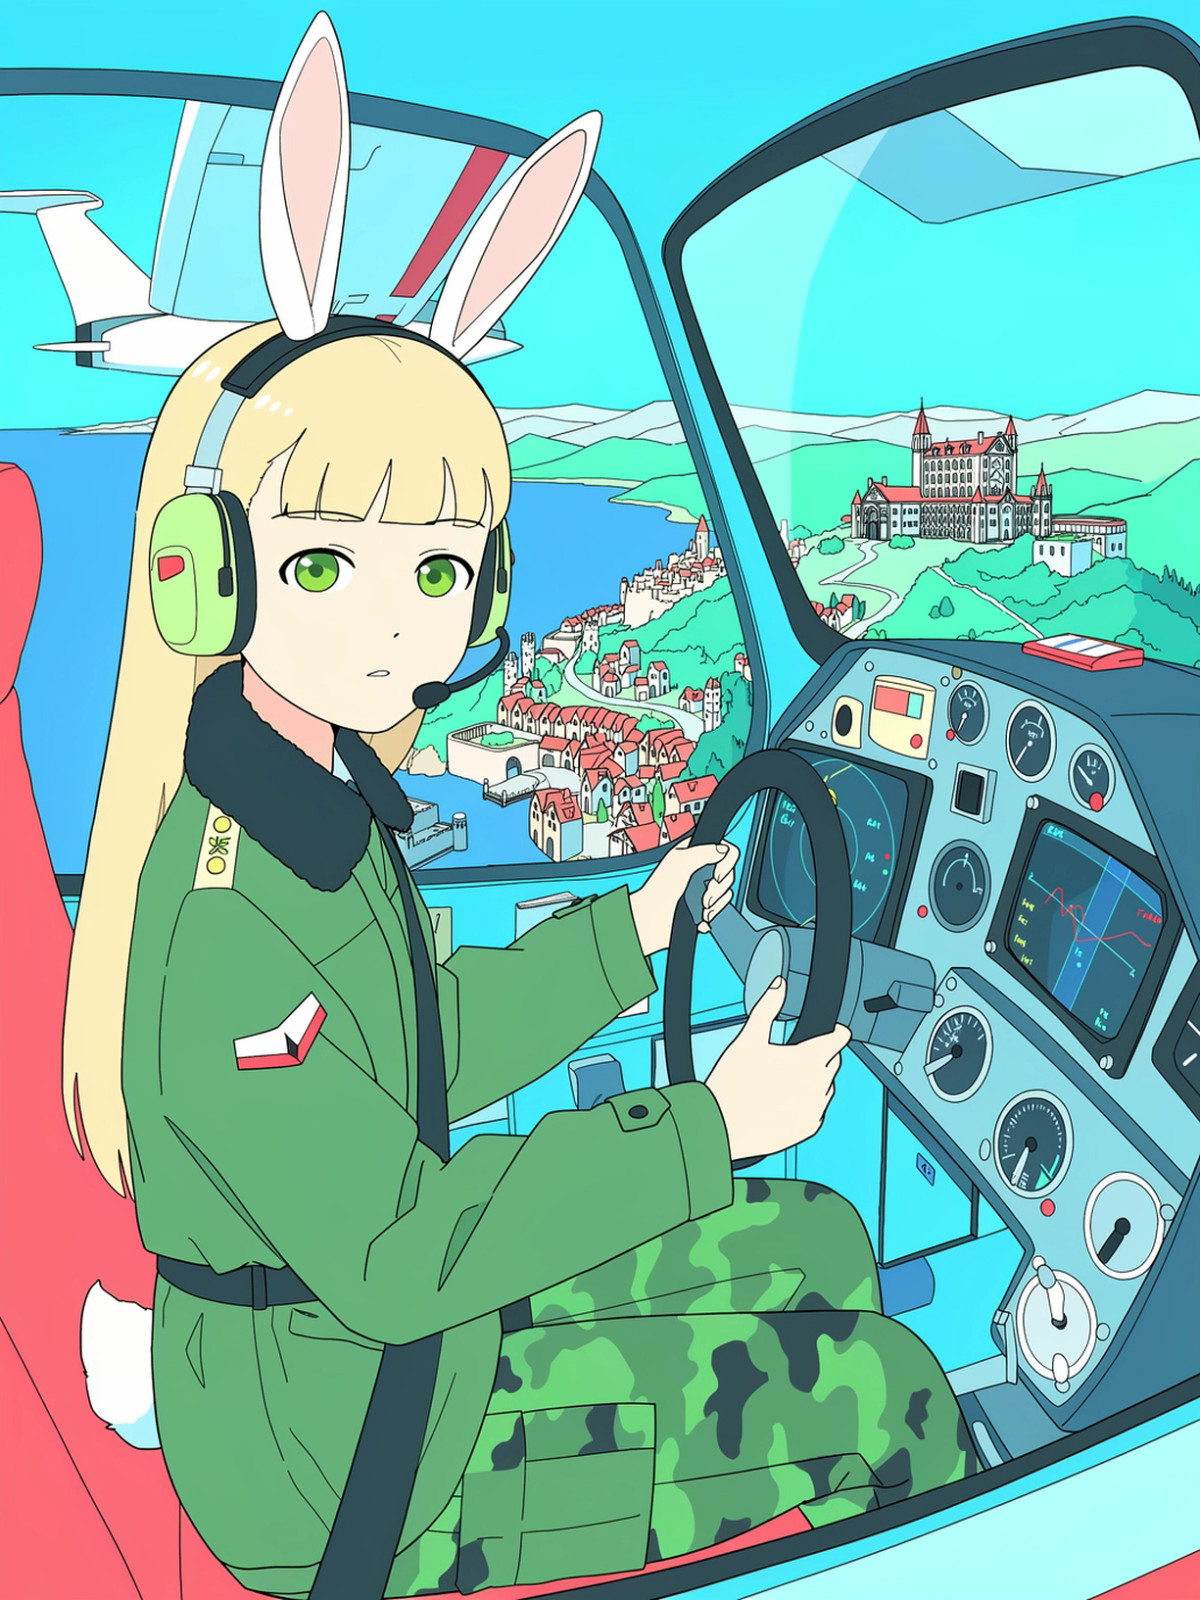
[A] [Style: Akabane 1999 · MOSS-base v1.0] (https://civitai.com/models/3028054?modelVersionId=3439288)
LoRA · New Model · Author NerissG · Published 10-30 21:20 · Downloads 66
An illustration style LoRA for artist Akabane 1999: Anime line art illustrations in the ligne claire style; the author states strength can be pushed to 1.25 to enhance the effect.
Maintained at A: Purpose and trigger word are clear, examples are sufficient, and the license is permissive, but generation parameters are missing, and it mimics a specific artist's style.
Images
![Example 1225x1633] (https://rh-images-switch.xiaoyaoyou.com/input/openapi/38548b371972cf0ff809ed45f2cd2545ce8f3c90a0d00828ca104d313d7566ad.jpg)
Reasons for Recommendation
- New Model: An art style LoRA trained on MOSS Base; serves text-to-image users who want clean lines and flat-color anime illustrations.
- Trigger word is fixed as "Illustration by @akabane 1999", strength can be increased to 1.25.
- 8 visible examples; free, permissive license: Allows image generation, rental, sales, and sales of merged models, but requires attribution; small file size (36 MB).
- Published about 12 hours ago with 66 download and 9 likes (indicating popularity only).
How to Use
- Load akabane_MOSS-Base_v1.safetensors in the MOSS workflow, start the prompt with "Illustration by @akabane 1999".
- Default strength is 1; for a stronger style, increase to 1.25; the author did not provide step counts, CFG, or sampler.
Risks and Limitations
- The description is only two sentences; step counts, CFG, and whether an acceleration LoRA is needed are not provided.
- Mimics a specific artist's style; the author does not state if authorization was obtained.
- 1 sensitive-level examples are hidden.
Trigger Word: Illustration by @akabane 1999
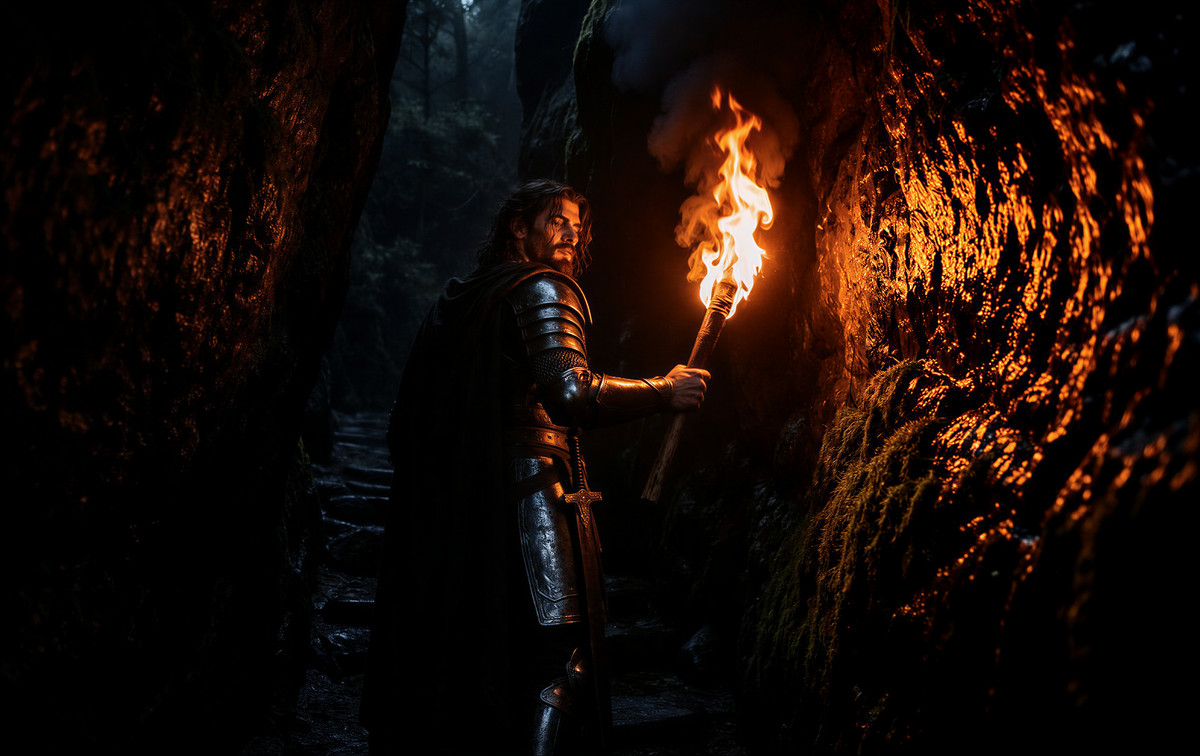
[A] [Creperum · MOSS Image v1.0] (https://civitai.com/models/3028241?modelVersionId=3439527)
LoRA · New Model · Author GreenRazor · Published 10-30 23:30 · Downloads 47
A lighting LoRA with strong contrast: Inspired by chiaroscuro and film noir lighting, it suppresses flat lighting and AI's automatic "face fixing" to create deep shadows, pure black negative space, and volumetric light beams, while preserving the three-dimensional structure of the scene (as stated by the author).
Maintained at A (from auto A): The keyword list is actionable, strength has a starting point, and the purpose is clear; however, examples are few and sampling parameters are missing, so it does not reach S.
Images
![Example 3160x1990] (https://rh-images-switch.xiaoyaoyou.com/input/openapi/f6528e559444ed0e006fad477649e4f9a6d707c8a74c0735bbc9f7e29d26afce.jpg)
Reasons for Recommendation
- New Model: A lighting LoRA specifically designed to counter MOSS's default flat lighting tendency, serving text-to-image generation for dark-toned portraits, dungeon/bunker dark room scenes, and black-and-white film noir styles.
- The author provides a keyword list categorized by effect: half-face split lighting, shadows engulfing eye sockets, rim-lit silhouettes, corner vignetting, arched corridor perspective, parallel light beams, window pane shadows, wet stone highlights, as well as color schemes for black and white, desaturated cool gray, and warm/cool contrast.
- Strength provides a range and starting point: 0.8-1.0, starting from 0.9; it also lists which "flat lighting" terms to avoid in negative prompts.
- 3 visible examples, all with prompts; free, fully open license; published about 10 hours ago with 47 downloads (indicating popularity only).
How to Use
- Load Creperum_MossImage.safetensors in the MOSS workflow, start strength at 0.9 (adjust between 0.8-1.0); no trigger word, driven by the author's listed effect keywords.
- Example: For dark-toned portraits, write "harsh split lighting effect cutting the face vertically" or "deep heavy shadows completely obscuring the eye sockets"; for black and white, add "monochrome, black and white".
- Do not include terms like ambient light, flat lighting, soft lighting, flash, or studio lighting in the negative prompt, as the author states they will cancel out the LoRA; the author did not provide step counts or CFG.
Risks and Limitations
- Only 3 visible examples, making it difficult to judge effectiveness across different subjects.
- No recommendations for step counts, CFG, or base model (Base / SFT, whether to pair with DMD).
- Desaturation and darkening are its purpose, so it is not suitable for images requiring bright commercial lighting.
[A] [MOSS Detailer · v051] (https://civitai.com/models/3028777?modelVersionId=3440252)
LoRA · New Model · Author Volnovik · Published 10-31 06:36 · Downloads 85
A single detail slider LoRA: The author states it only increases image detail without changing the art style, used to add texture and detail to MOSS outputs.
Maintained at A: Purpose is clear, highly versatile, license is permissive, and it gained traction fastest; however, it only provides a one-sentence strength hint and lacks comparative explanations, so it is not S.
Images
![Example 960x1216] (https://rh-images-switch.xiaoyaoyou.com/input/openapi/dc82d1de8f35ddd82c94981fecf4222b9f168e70be37639b86cc787fb16faf2b.jpg)
Reasons for Recommendation
- New Model: A text slider trained using Fizgig, self-described by the author as "crude but usable"; serves all genres of MOSS text-to-image, for adding detail without changing style.
- No trigger word required; the author only hints that a weight of 1.0 might be too strong.
- 6 visible examples; free, most permissive license: Allows image generation, rental, sales, and sales of merged models, attribution optional; small file size (36 MB).
- Published about 2.4 hours ago with 85 downloads and 10 likes, the fastest gaining traction in this group (indicating popularity only).
How to Use
- Load MOSS_detailer_v051.safetensors in the MOSS workflow, no trigger word required; start adjusting strength below 1.0, as the author says 1.0 might be excessive.
- The author did not provide step counts, CFG, or whether negative values are usable (common for sliders to reduce detail in reverse).
Risks and Limitations
- The description is only three sentences, with no strength range or comparative image explanations; the author did not label whether examples show on/off comparisons.
- The author did not state whether it was trained and tested on Base or SFT.
- 11 sensitive-level examples are hidden.
[A] [Realistic Anime | MOSS Image · v1.0] (https://civitai.com/models/3028475?modelVersionId=3439824)
LoRA · New Model · Author Akai_azusa · Published 10-31 02:04 · Downloads 68
A bidirectional adjustment art style LoRA: Positive strength pushes the image towards anime illustration, negative strength pushes towards realistic and photorealistic textures; the author explains it is not a background enhancement model, only affecting the overall anime/realistic tendency.
Maintained at A: Function and strength scale are clearly written, allowing for comparisons at -1 / 0 / 1 / 2; missing step counts and CFG, few examples, and stricter license, so it does not reach S.
Images
![Example 768x1280] (https://rh-images-switch.xiaoyaoyou.com/input/openapi/4e79b569f1ebffe1661ad343dc7a235b297f743b5c5f50573494138a6e08b0af.jpg)
Reasons for Recommendation
- New Model: A MOSS-specific style slider, serving the need to fine-tune between anime illustration feel and photorealistic feel with the same prompt, without changing the base model or stacking multiple style LoRAs.
- The author provides a complete strength scale: 0.5 for light anime, 1.0 as recommended starting point, 1.5 for more obvious effect, 2.0 near the upper limit; -0.5 starts leaning realistic, -1.0 for stronger photorealism, near the lower limit; below -1.0 or above 2.0 easily causes ghosting, color blocks, or structural collapse.
- 3 visible examples; free; published about 7 hours ago with 68 downloads and 6 likes (indicating popularity only).
How to Use
- Load moss_realistic_anime_v1.safetensors in the MOSS workflow, no trigger word; start strength at 1.0, adjust up or down in increments of 0.25, change to negative values (-0.5 to -1.0) for a more realistic look.
- The author did not provide step counts, CFG, sampler, or whether to use Base or SFT; the author reminds that optimal strength varies by base model.
Risks and Limitations
- The model card lists a series of comparison cases by strength, but only 3 are publicly visible; 1 sensitive-level examples are hidden.
- The card also lists cases for strength -1.5, which contradicts the statement that "-1.0 is near the lower limit".
- The license only allows on-site rental, not commercial image generation or merging.
- The author did not disclose the source of training materials.
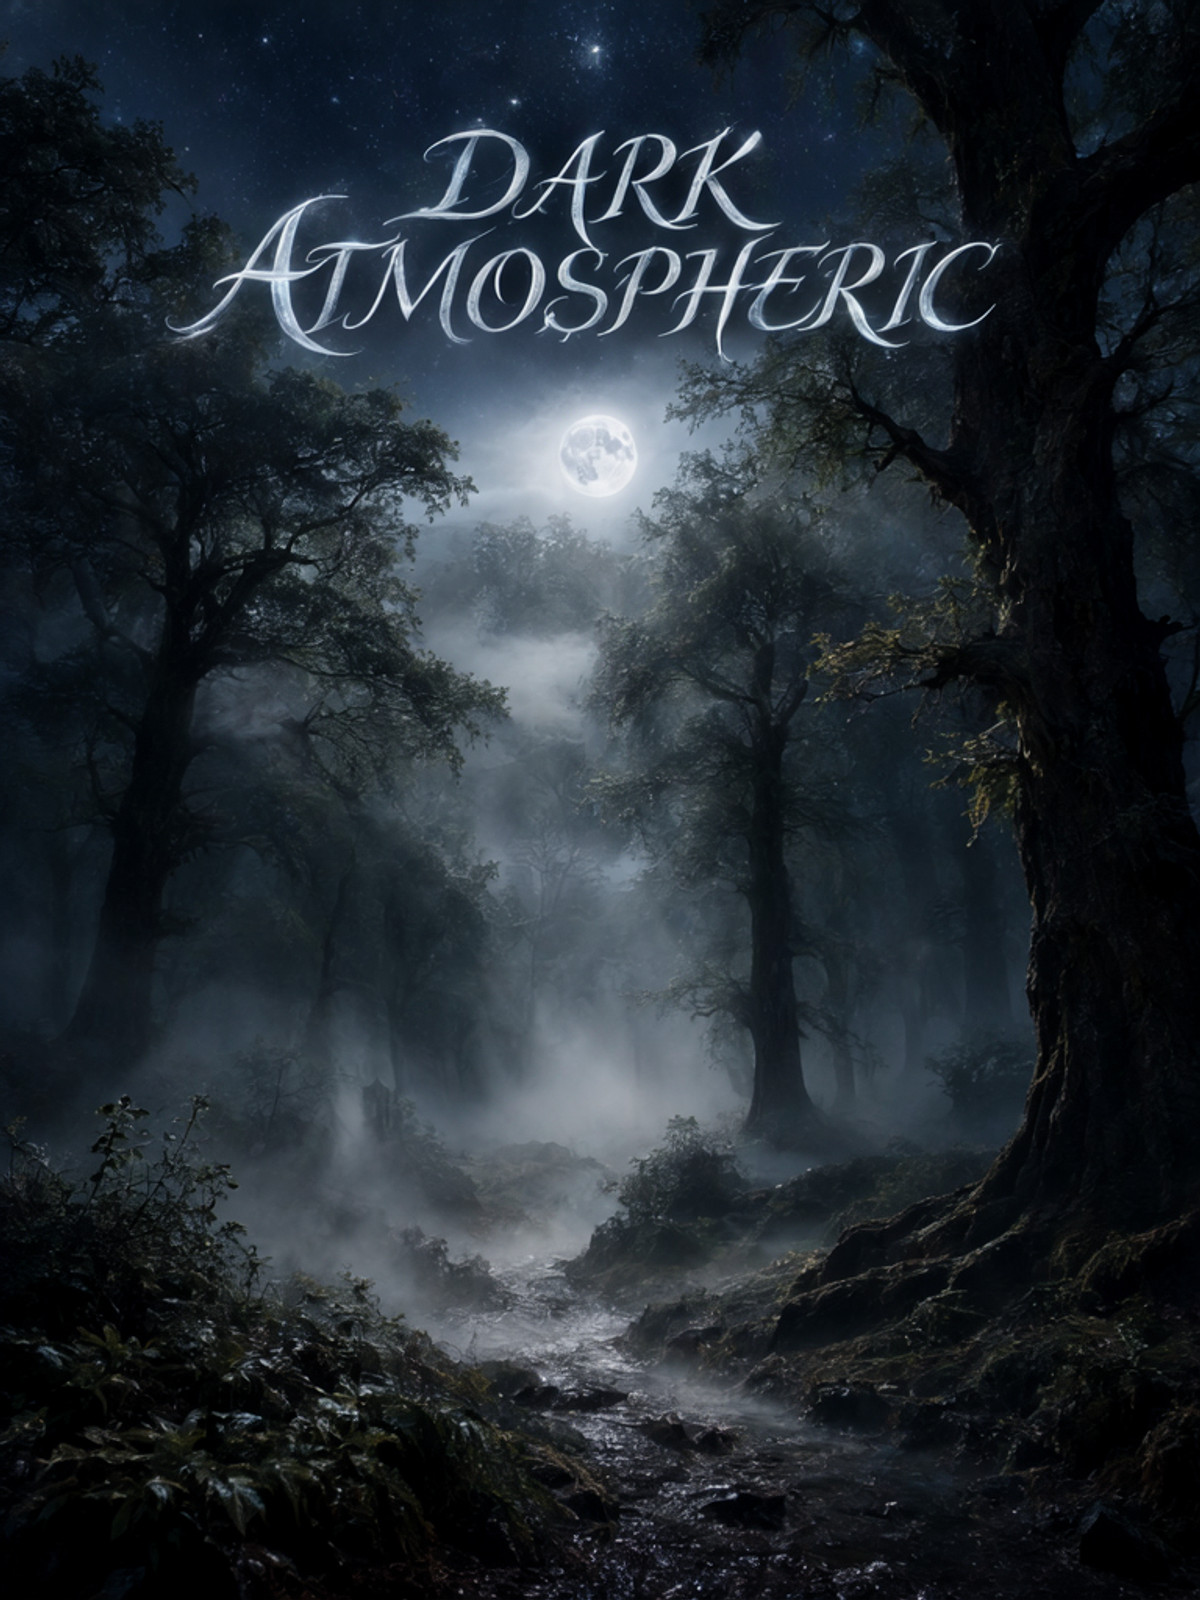
【A】Dark Atmospheric Style - CE · V01a - MossImage Base/SFT
LoRA · Port · Author CreativeEdge · Published 10-31 01:52 · Downloads 74
The MOSS version of the "Dark Atmospheric" LoRA: adds shadows and mist to images, with a slight soft-light diffusion effect.
Maintaining A: Clear purpose, strong reputation within the series, MOSS version includes Base/SFT compatibility notes and examples, but parameters and trigger words are completely missing.
Images
Reasons for Recommendation
- Port: Previous versions exist for Flux.1 D, Qwen, Z Image, Flux.2 Klein, Krea 2, etc.; the MOSS version is trained on Base, and the author states it works with both Base and SFT, with all showcase images generated using SFT
- Serves text-to-image needs for dark, misty, low-key lighting atmospheres (dark fantasy, suspense scenes, etc.)
- 7 visible examples; free, attribution not required
- This version was released about 7 hours ago with 74 downloads; the entire series has accumulated 7914 downloads and 580 likes (indicating attention only)
How to Use
- Load DarkAtmospheric01a_CE_MossImg_AIT4k.safetensors in a MOSS SFT (or Base) workflow
- The MOSS version author has not registered trigger words; other base model versions use DarkAtmosCE_style, and it is unclear if the MOSS version follows this; strength, steps, and CFG are not provided by the author
Risks and Limitations
- Description is only two sentences, with no MOSS parameters
- No registered trigger words
- License only allows image output and on-site rental, does not allow merging
- 2 sensitive-level examples are hidden
Worth Watching (18)
【B】Eleptor's Realistic Furry Anthro LoRA (Ill/Moss/Anima/Krea) · Moss
LoRA · Port · Author Eleptor · Published 10-30 23:10 · Downloads 43
The MOSS version of a realistic-style furry anthro species LoRA: the author claims to have retrained from scratch using 2,178 images and 73 species, making fur, scales, leather textures, and lighting more realistic while preserving the distinctive features of each species.
Images
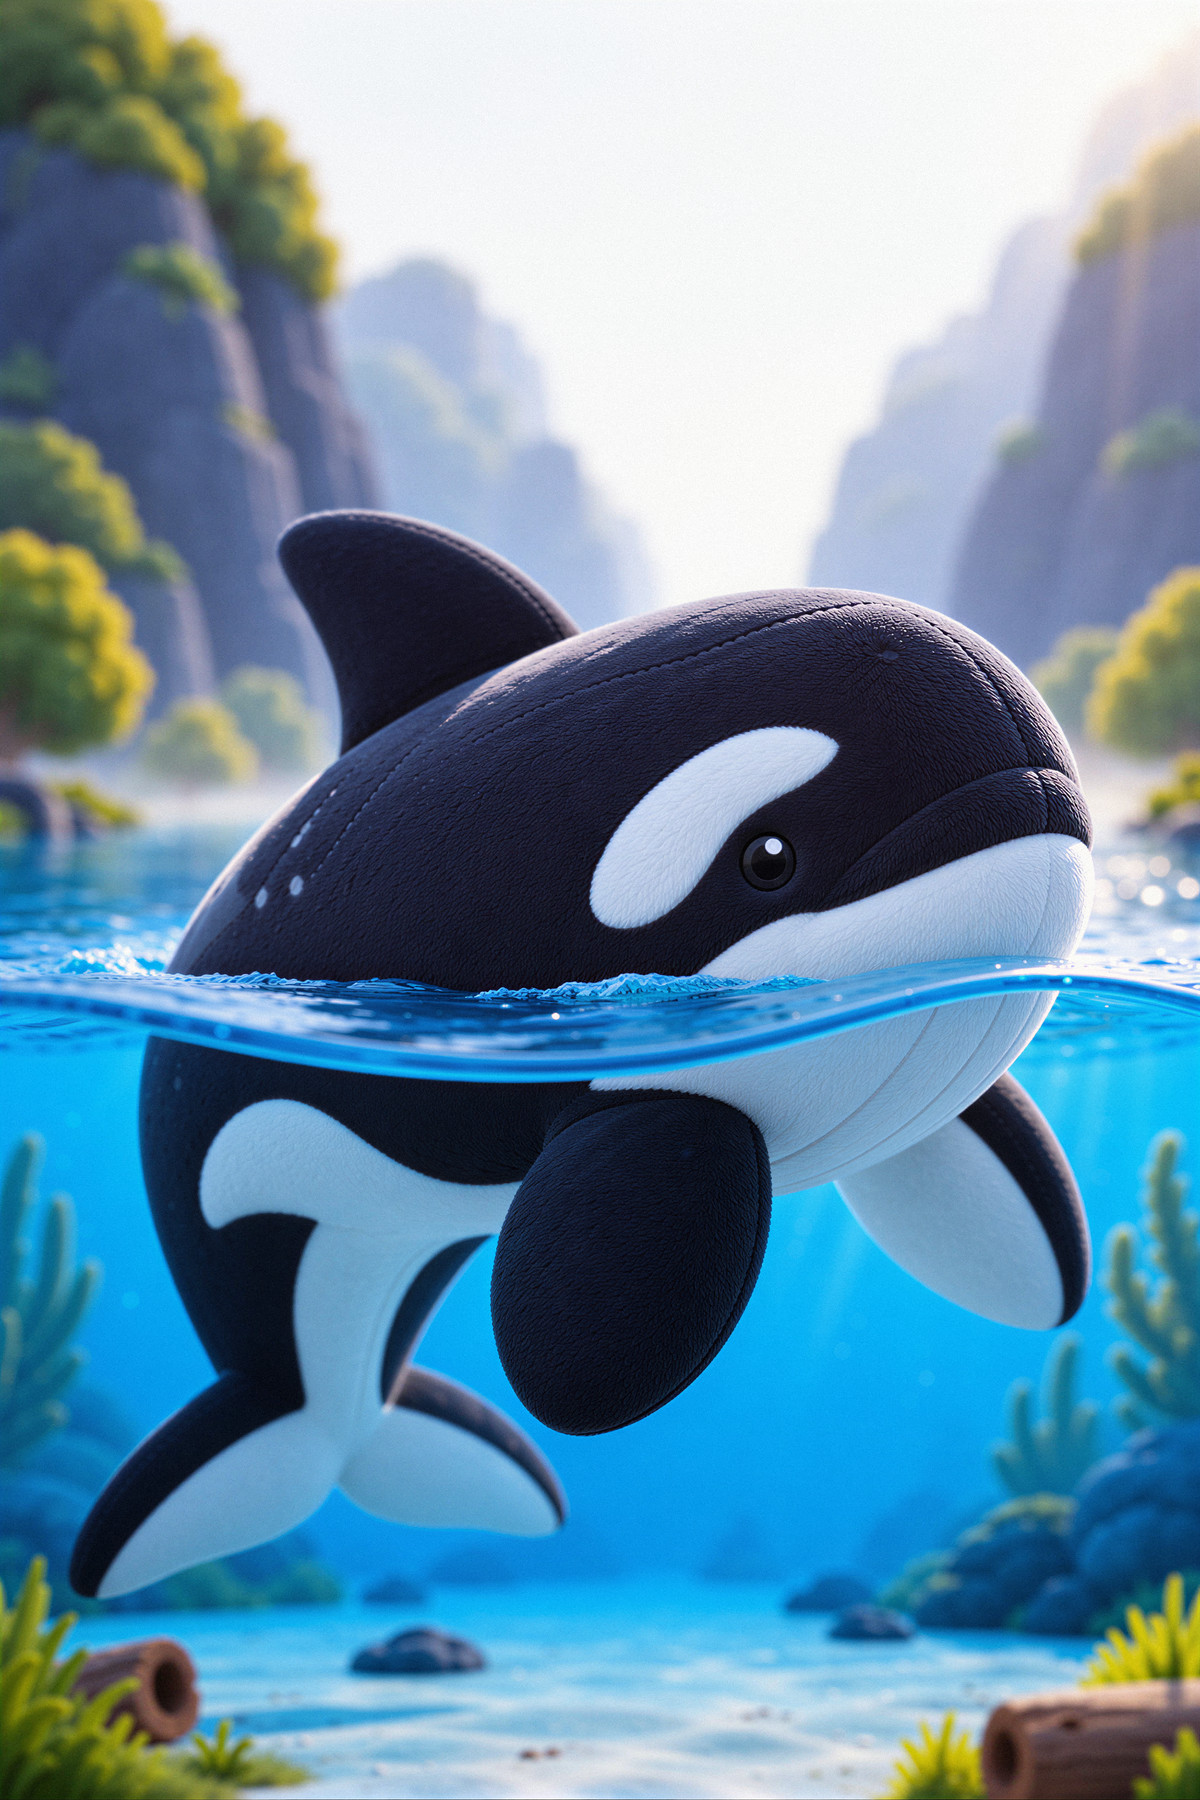
【B】Plush style · v2 - M0SS
LoRA · Port · Author Fatbuns · Published 10-31 06:40 · Downloads 22
The MOSS version of a style LoRA that renders main subjects with a plush toy texture; the author states they trained a specific plush style they created using MOSS, and frankly admits the MOSS version's quality is inferior to the Krea 2 version trained on the same dataset.
Images
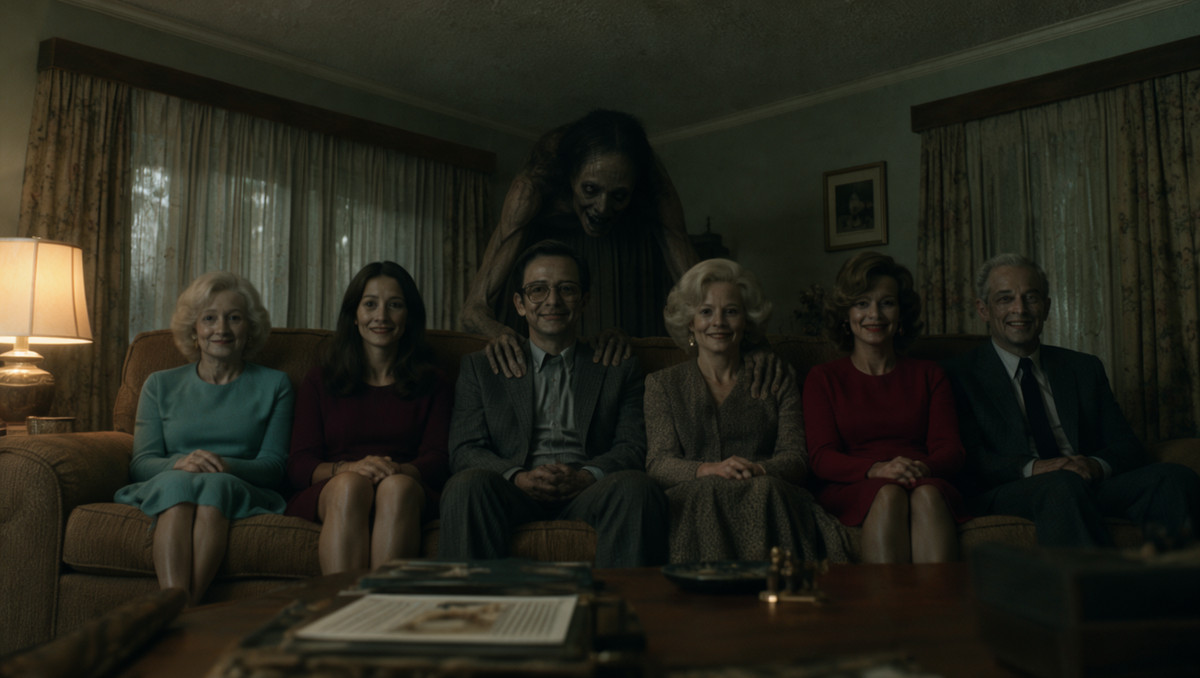
【B】Obsidian Nightmare · Lucid Trauma MOSS-Image
LoRA · Port · Author Granddyser · Published 10-30 23:13 · Downloads 65
The MOSS version (named Lucid Trauma) of the horror-style LoRA "Obsidian Nightmare": the author claims to have rebuilt the dataset, focusing on psychological horror rather than gore, using composition, posture, lighting, and semi-hidden figures to create an unsettling feeling of "being watched."
Images
【B】Moss image Edit: workflow with upscale · v1.0
Workflow · New Model · Author def813 · Published 10-31 06:44 · Downloads 23
A ComfyUI workflow for MOSS image editing (Edit), which automatically appends an upscale step using Z Image Turbo (ZIT) after editing; contains no new weights.
Images
【B】Muchin style | [MOSS | Anima | Illustrious] · moss-1.0
LoRA · Port · Author NoiseWriggler · Published 10-31 00:43 · Downloads 57
The MOSS version of a LoRA for the art style of doujinshi artist Muchin, trained on MOSS Base and tested on SFT; the author emphasizes that this style requires illustration, 2D, or anime-style descriptions, and realistic descriptions will not work.
Images
【B】MOSS-Image-SFT_clear · Int8ConvRot_HQ
Base Model / Checkpoint · Version Update · Author easygoing0114 · Published 10-31 06:28 · Downloads 17
The Int8 ConvRot (HQ) quantized file for the MOSS-Image-SFT_clear denoising fine-tuning base model; the content is the same model as the BF16 version, just smaller in size.
Images
【B】Batman MOSS - Photorealism · v3.0
Base Model / Checkpoint · New Model · Author brucewayne123 · Published 10-31 05:18 · Downloads 91
A photorealistic MOSS merged base model: the author merged a 8-step turbo LoRA into the model by gradient, claiming it preserves the effects of CFG and negative prompts, generates images in 6 to 10 steps, and restores skin textures and details that the original version tends to smooth out.
Images
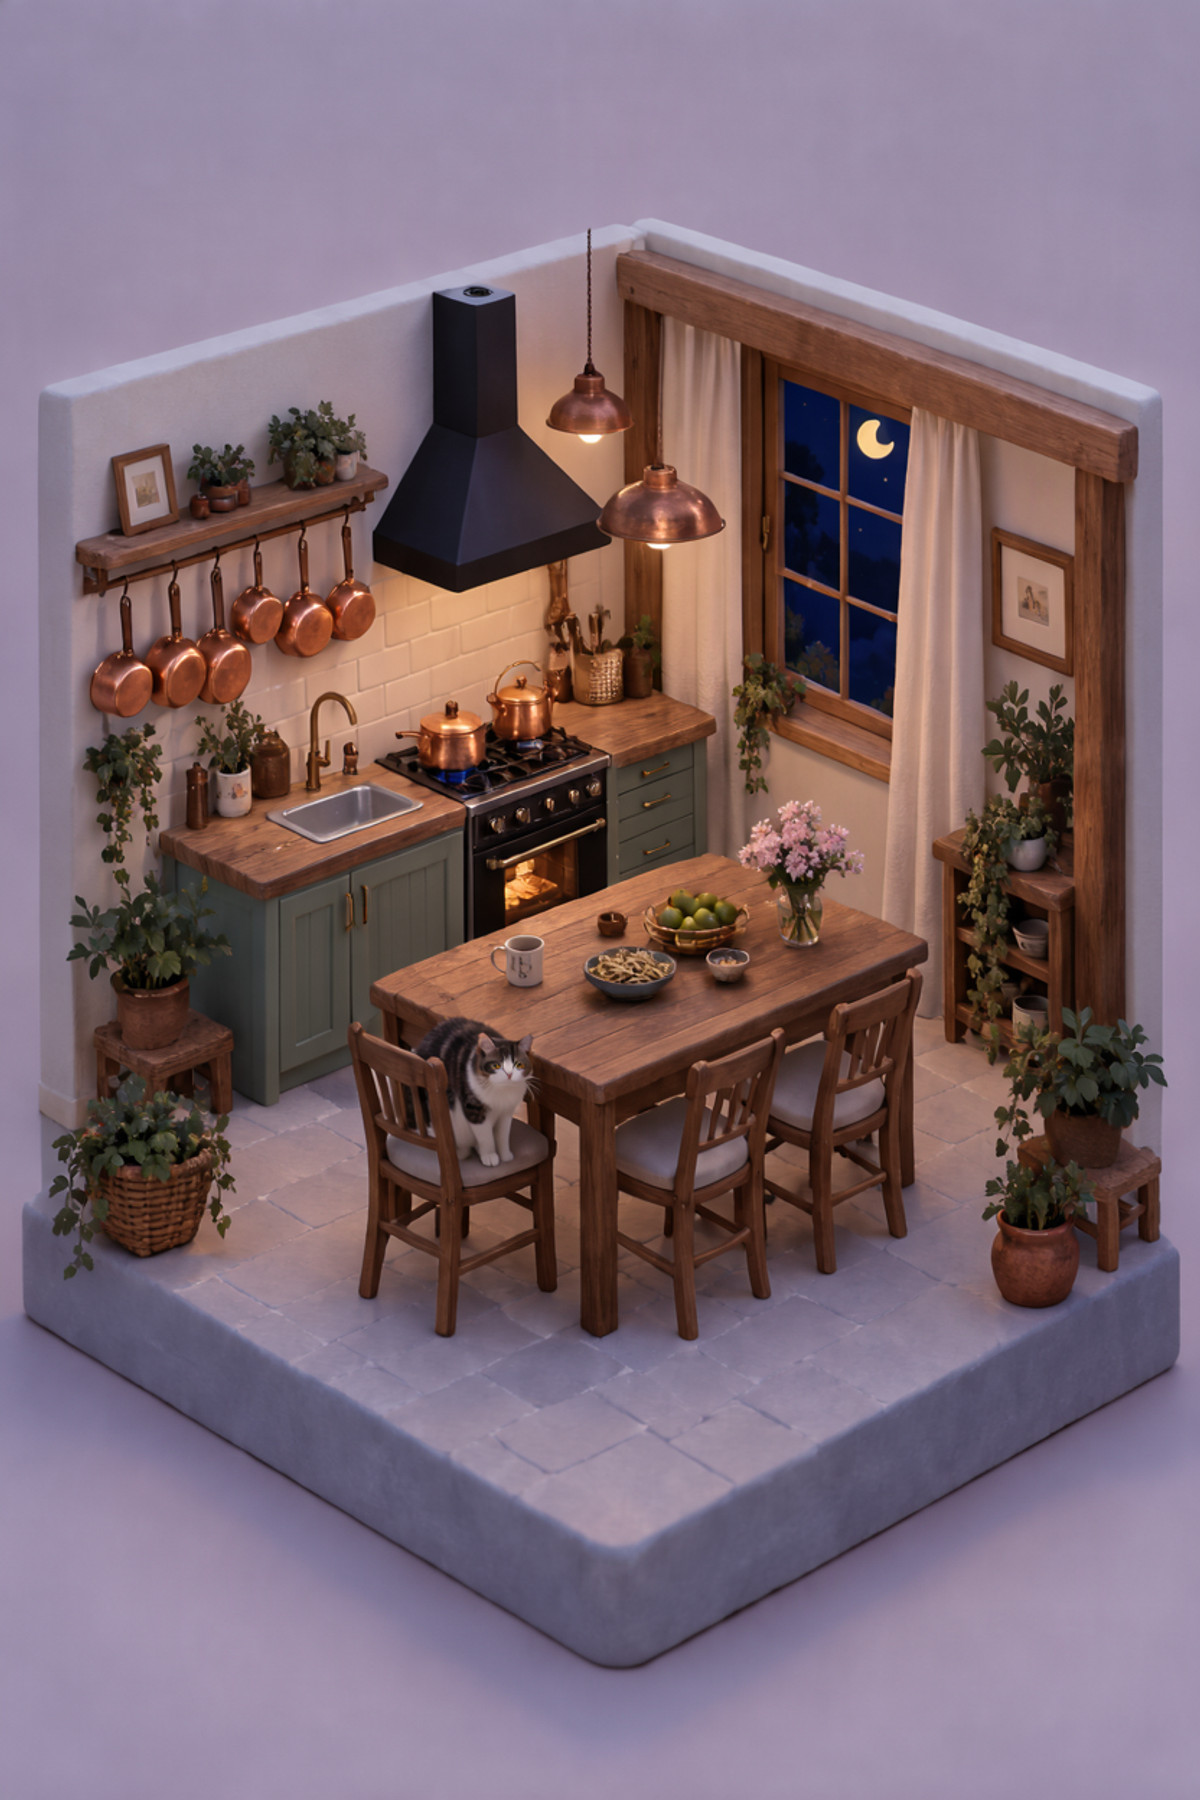
【B】Isometric Diorama Style [MOSS] · Isometric Diorama
LoRA · New Model · Author RalFinger · Published 10-31 04:43 · Downloads 50
An isometric diorama style LoRA, rendering scenes as small, three-dimensional model-like blocks viewed from above; the model card has no text description, so the purpose can only be inferred from the name, tags, and examples.
Images
【B】PieMOSS · v0.2
Base Model / Checkpoint · Version Update · Author Imbrium · Published 10-30 22:25 · Downloads 8 · Paid
PieMOSS v0.2: A MOSS realistic fine-tuning base model aimed at "removing the AI plastic look," with this version adding more datasets and training epochs.
Images
【B】MLP Feral Pony / Ponify [Krea 2] · MOSS
LoRA · Port · Author OrdinaryTwig · Published 10-31 05:47 · Downloads 28
The MOSS version of a concept LoRA that "ponifies" characters or directly draws them as four-legged ponies in the style of My Little Pony; the author claims the MOSS version has been re-tagged, offering better support for realistic styles and various concepts.
Images
【B】Double Exposure Style [MOSS] · Double Exposure
LoRA · New Model · Author RalFinger · Published 10-31 05:10 · Downloads 36
A double exposure style LoRA, used to create photography/poster effects with two layers of overlapping images; the model card has no text description, so the purpose can only be inferred from the name, tags, and examples.
Images
【B】Stained Glass Style [MOSS] · Stained Glass
LoRA · New Model · Author RalFinger · Published 10-31 04:15 · Downloads 35
A stained glass (church window) style LoRA: renders images to look like stained glass mosaics.
Images
【B】Laoshi wo hao e [Artist] [Anima] · moss 0.5
LoCon · Port · Author choch · Published 10-31 06:59 · Downloads 12
The MOSS draft version of a LoCon for the art style of artist laoshi wo hao e: the author switched to training on 512x512 because training at 1MP did not converge, resulting in this experimental weight version.
Images
【B】ComfyUI-MOSS-QwenVL-Layout · v1.1.2
Workflow · Version Update · Author leroy989 · Published 10-30 21:33 · Downloads 59
A ComfyUI node that converts reference images into MOSS layout prompts: uses Qwen3-VL / Qwen3.5-VL to identify specified objects and text in the image, generating the layout JSON required by MOSS (descriptions, text content, converted bounding boxes); v1.1.2 adds a prompt expansion node.
Images
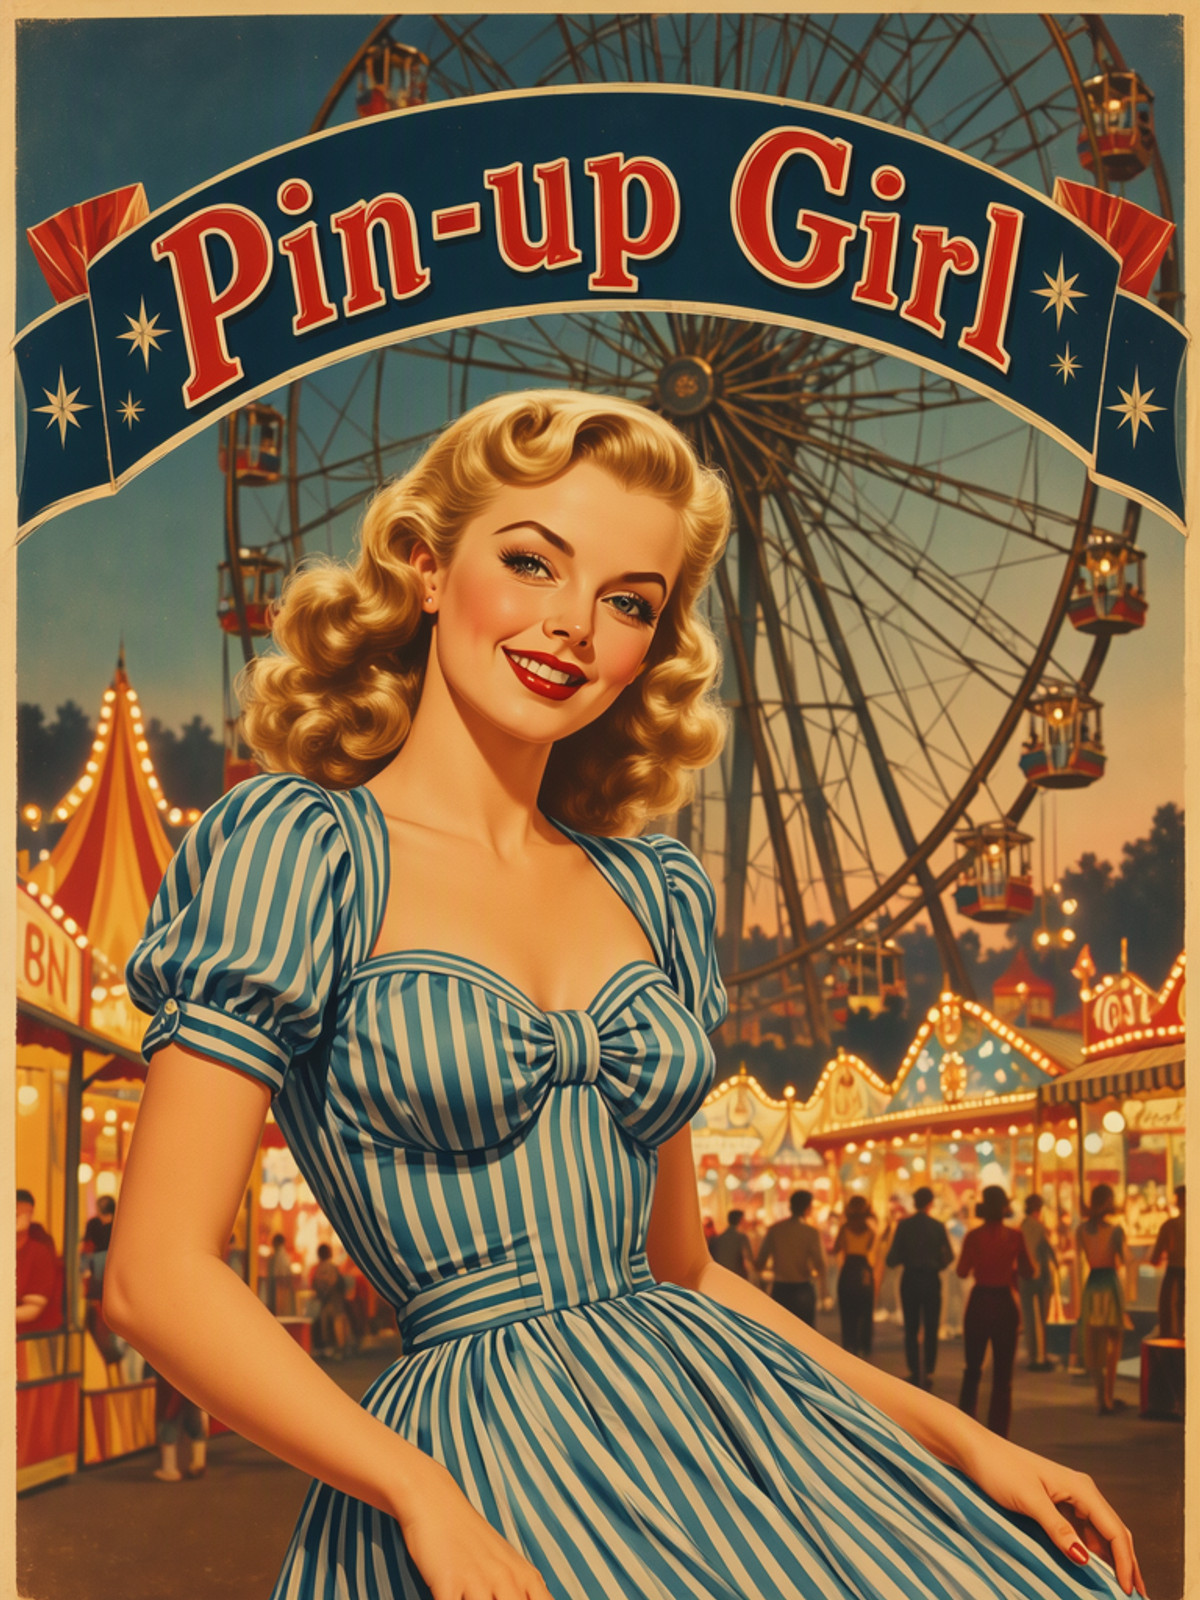
【B】Pin-up Girl - CE · V01e - MossImage Base/SFT
LoRA · Port · Author CreativeEdge · Published 10-31 07:31 · Downloads 23
The MOSS version of a 1940s American pin-up girl style LoRA, with soft tones; the author suggests trying different media, such as colored pencils, airbrush, oil painting, or no specified medium.
Images
【B】MOSS-Image TestSampler and Merger for ComfyUI · v1.0
Other · New Model · Author aueki4g467 · Published 10-30 23:42 · Downloads 15
A MOSS ComfyUI toolkit for model makers: includes layered merging nodes (weighted_sum / add_difference / train_difference), a converter to transform INT8 and other quantized models back to BF16 with the same structure as the base model, and a test sampler that can export the sampler's internal state.
Images
【B】MOSS-Image-SFT_clear · FP8_svd_scaled
Base Model / Checkpoint · Version Update · Author easygoing0114 · Published 10-31 07:42 · Downloads 2
FP8 svd scaled quantized file for the MOSS-Image-SFT_clear denoising fine-tuned base model, which is the same model as the BF16 version.
Image
【B】MOSS-Image-SFT_clear · MXFP8
Base Model / Checkpoint · Version Update · Author easygoing0114 · Published 10-31 07:00 · Downloads 2
MXFP8 quantized file for the MOSS-Image-SFT_clear denoising fine-tuned base model, which is the same model as the BF16 version.
Image
Included Only (30)
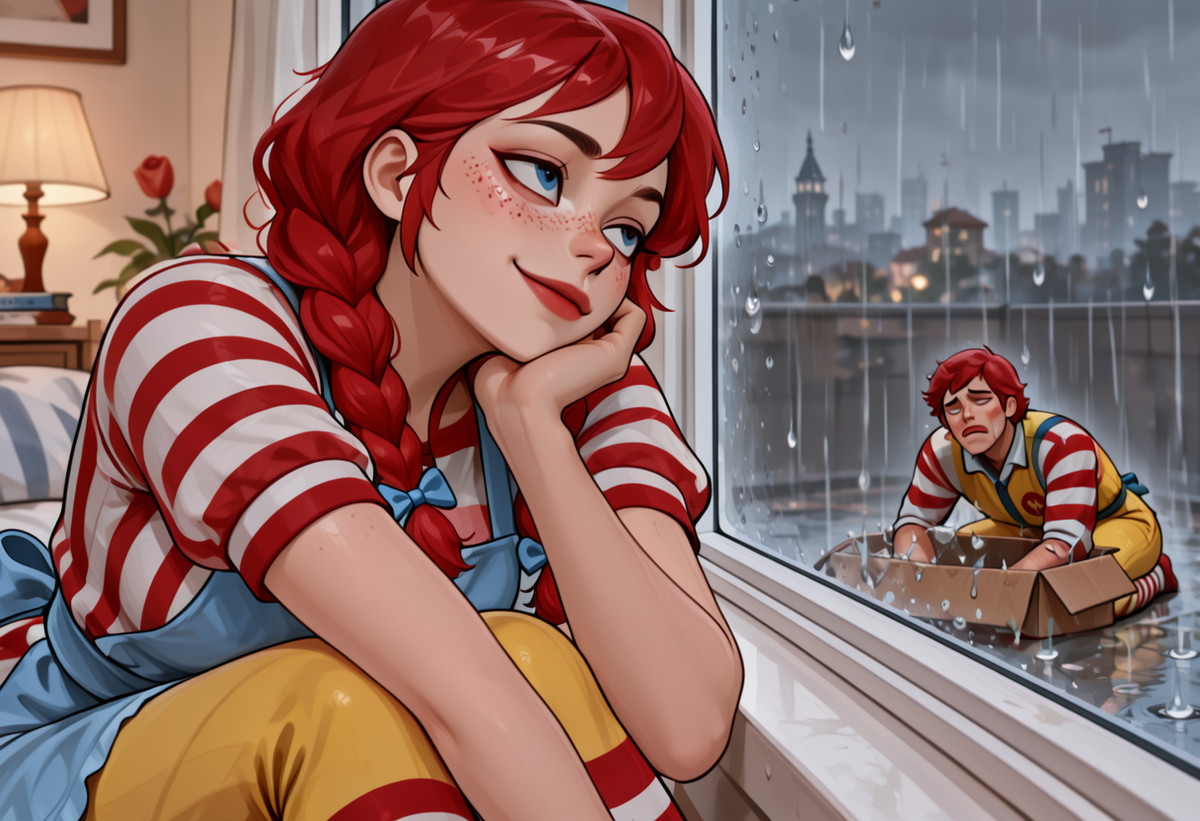
- Wendy (Wendy's) | Where's the beef? [ANI & MOSS & IL] · MOSS — LoRA: A MOSS character LoRA for Wendy, the mascot of the American fast-food brand Wendy's (red pigtails, freckles, blue-and-white striped dress with an apron), derived from the "Where's the beef?" meme.
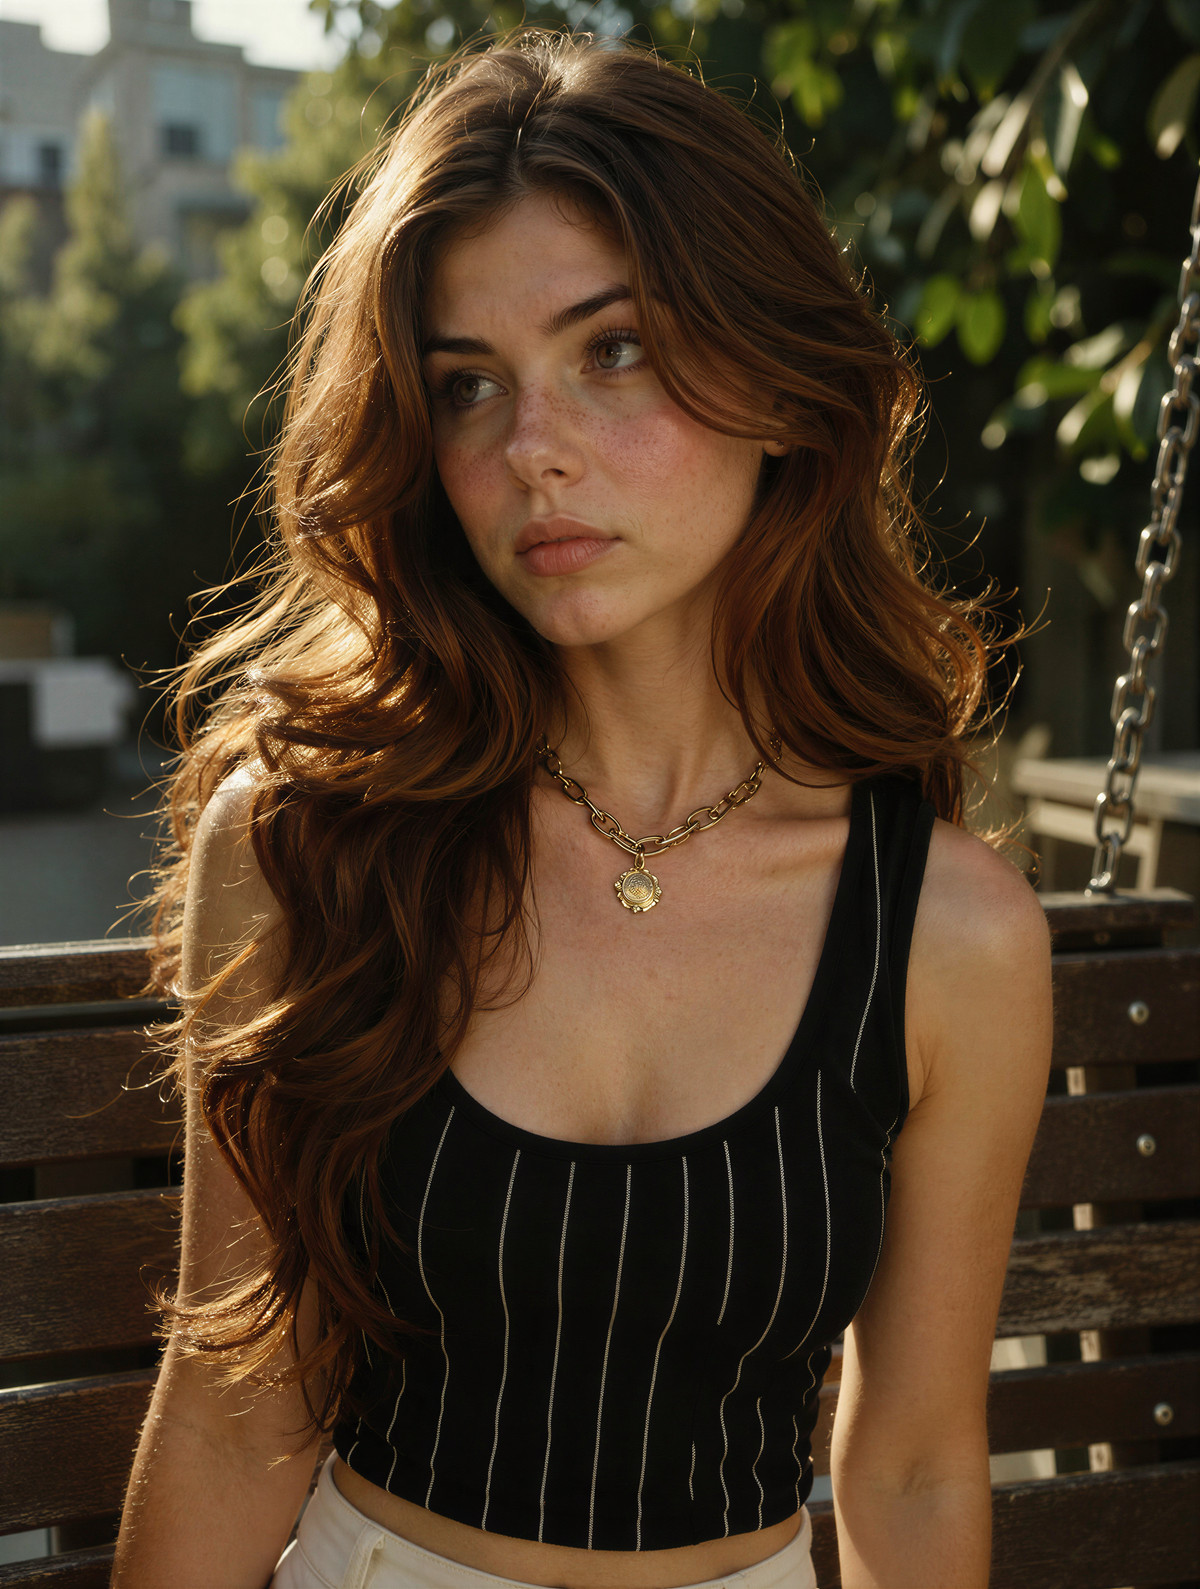
- Diamond, a fake person · Moss — LoRA: A MOSS character LoRA for the fictional persona "Diamond": The author trained an AI-generated fake human image to create a female figure in her early 30s with light brown hair, used to maintain facial consistency.
- Miyako(Moss/Krea2) · Moss-Image — LoRA: A MOSS version of the character LoRA for "Miyako," an original fictional character created by the author. The author's character setting describes her as "a slightly slow-paced girl-next-door type older sister."
- Dasulchan Style · MOSS-Image v1.0 — LoRA: A MOSS version of the art style LoRA by artist Dasulchan; the model card only states "A straightforward art style LoRA based on Dasulchan's works," without describing specific stylistic features.
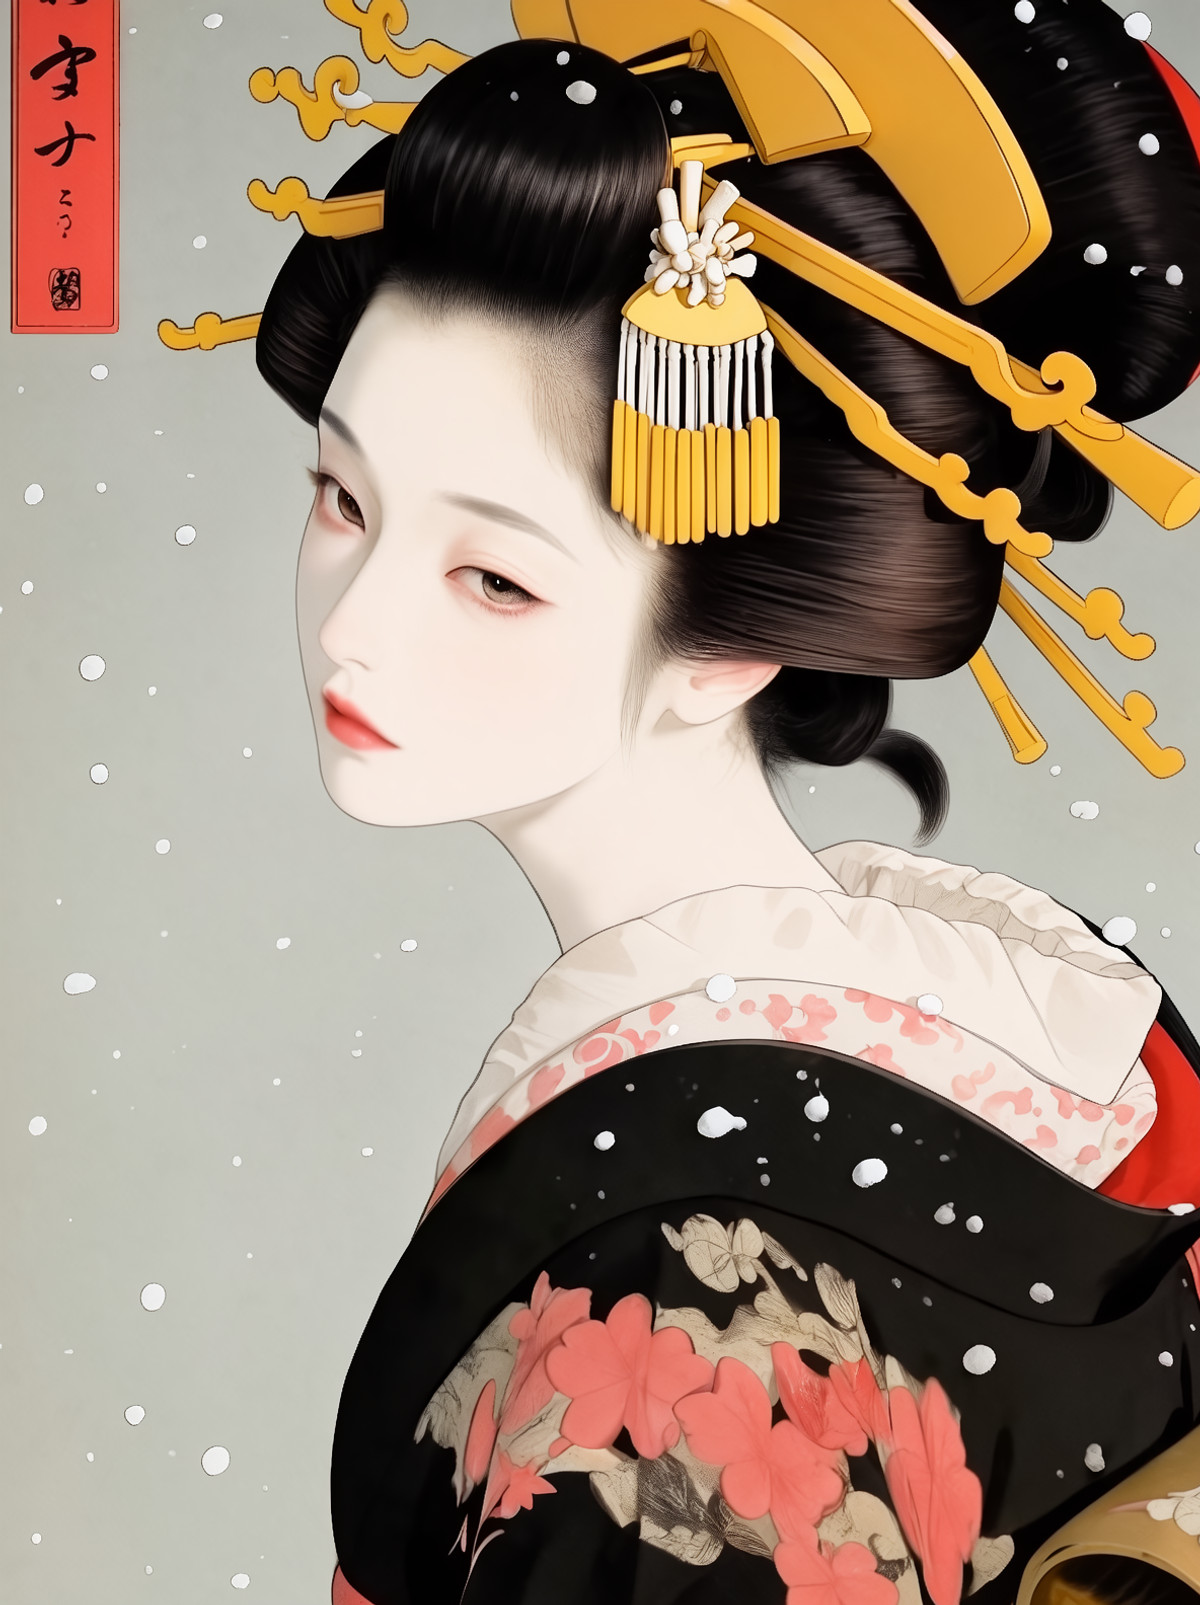
- Nippon · MOSS_v1.0 — LoRA: A MOSS version of a lightweight art style LoRA that blends anime with traditional Japanese painting (ukiyo-e, ink wash); the author notes the effect is subtle and does not drastically change the art style, though female characters' eyes will have distinctive features.
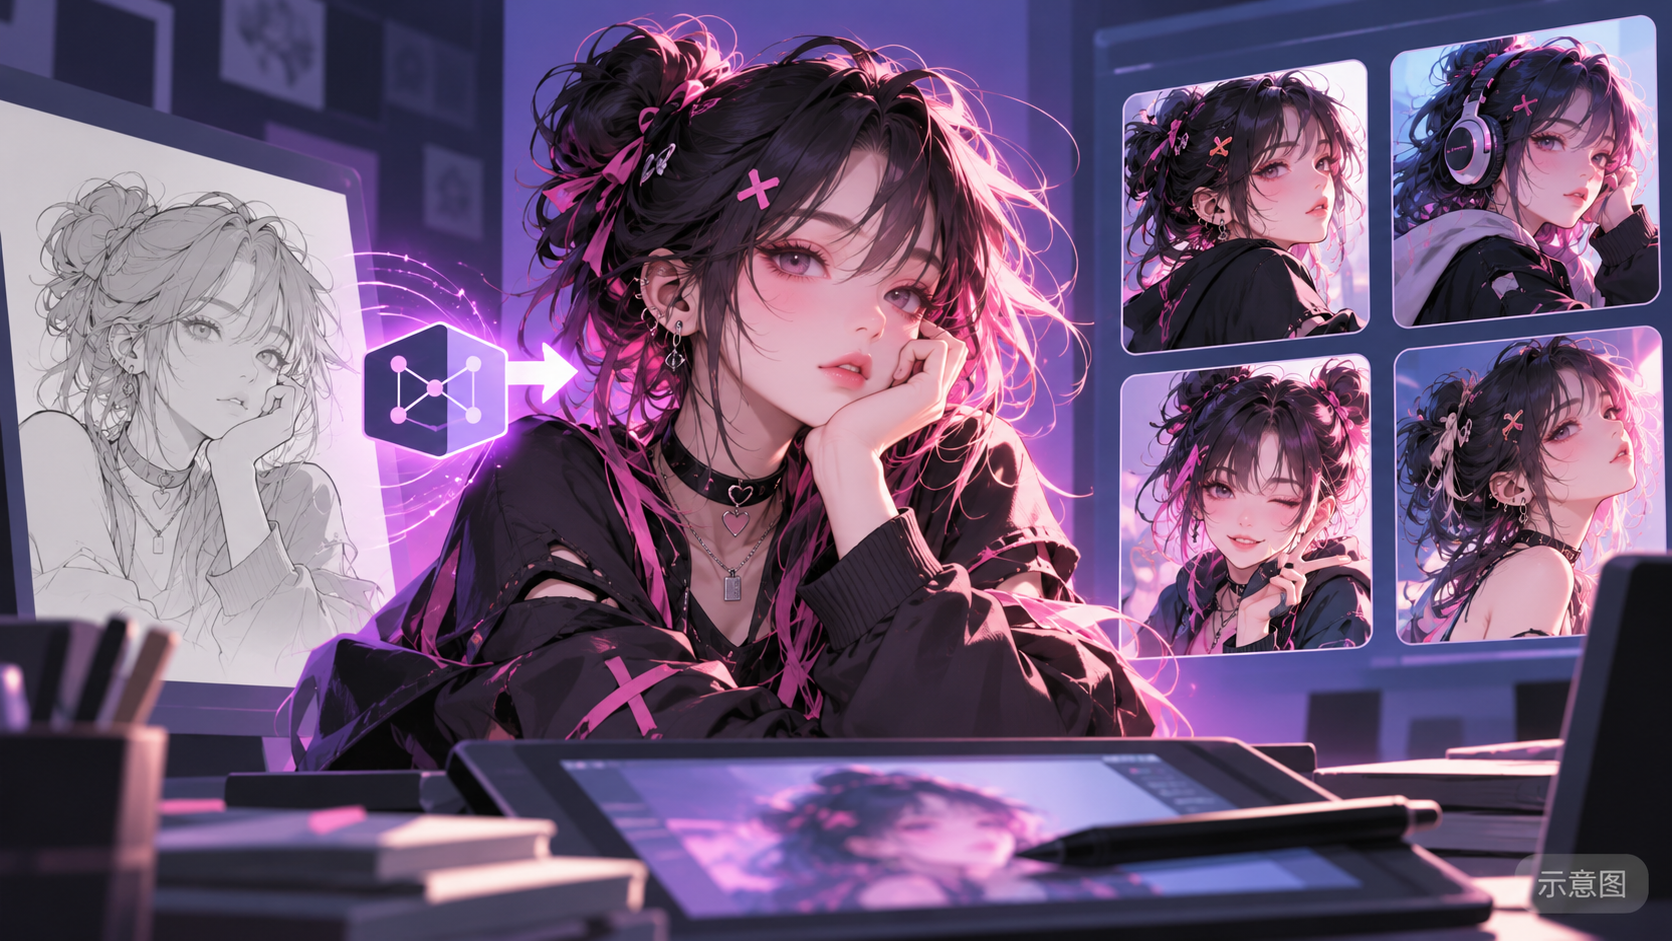
- Alt-Girl/E-Girl · Moss v0.5 — LoRA: A draft MOSS version of the Alt-Girl / E-Girl (alternative, emo fashion style young female look) LoRA: The author states they only trained for 2000 steps and will upload a more thoroughly trained version later.
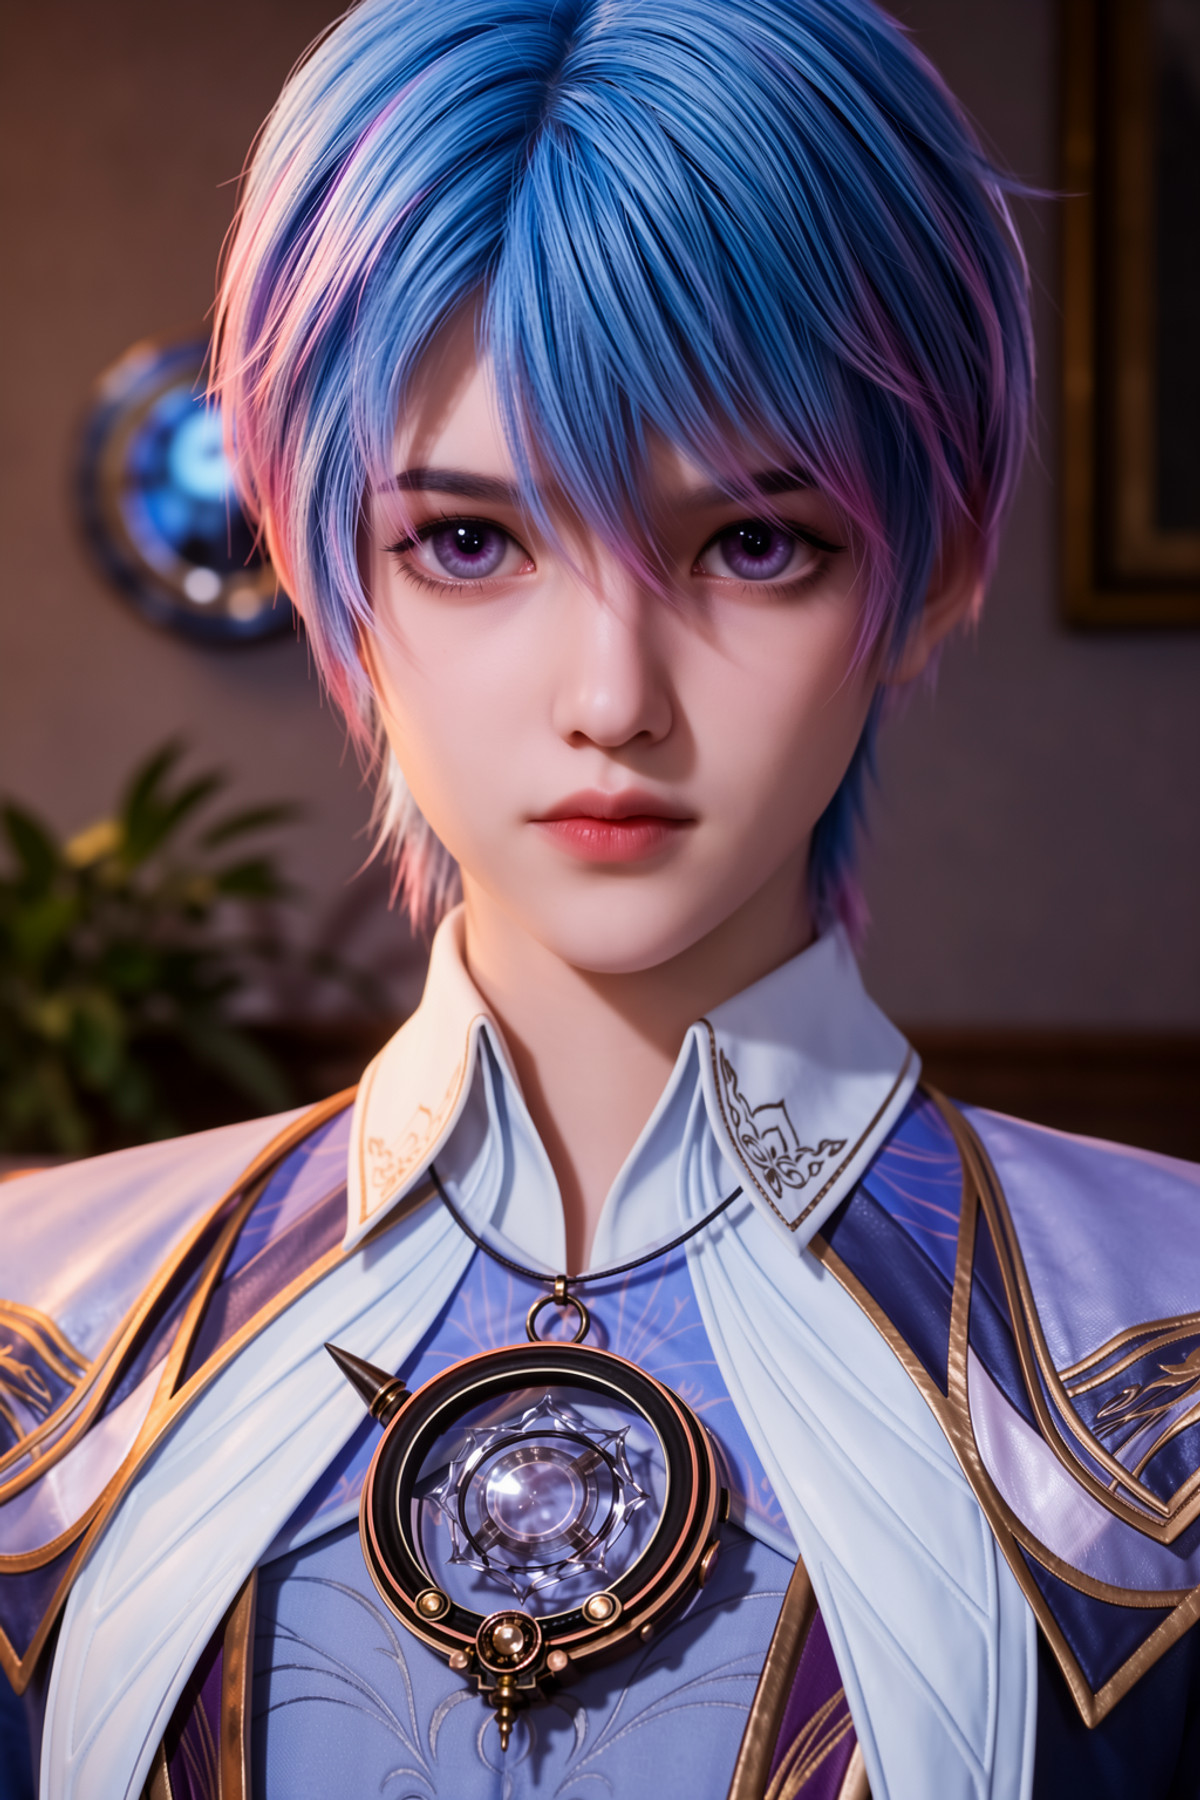
- Soul Land Wang Dong (Short-haired Tang Wutong) · v1.0 — LoRA: A MOSS character LoRA for Wang Dong from the Chinese animation "Soul Land" (the short-haired form of Tang Wutong, featuring short hair with a gradient from sky blue to pink, and a blue-white-gold gown).
- Oldies and brats Moss image · Brat48 — LoRA: Brat48 from the character LoRA collection "Oldies and brats": The author placed multiple female characters (both older and younger) on the same model page, with each version representing one character; this version is Brat48.
- Velnara Style · MOSS v1.0 — LoRA: A MOSS version of the "Velnara" art style LoRA; the model card only lists the trigger word and notes that the original images are Midjourney works by X user GlitterPixely.
- indian-girl-brown-eyes - moss - base · moss-base — LoRA: A realistic character LoRA (MOSS Base version) depicting an Indian female model in her twenties, with the trigger word indian-girl-brown-eyes; the model card contains stock-photo-style promotional copy without usage instructions.
- MMD-STYLE-MOSS · v1.0 — LoRA: An MMD style LoRA: Judging by the name, it mimics the rendering style of MikuMikuDance 3D models; the model card only states "A style lora."
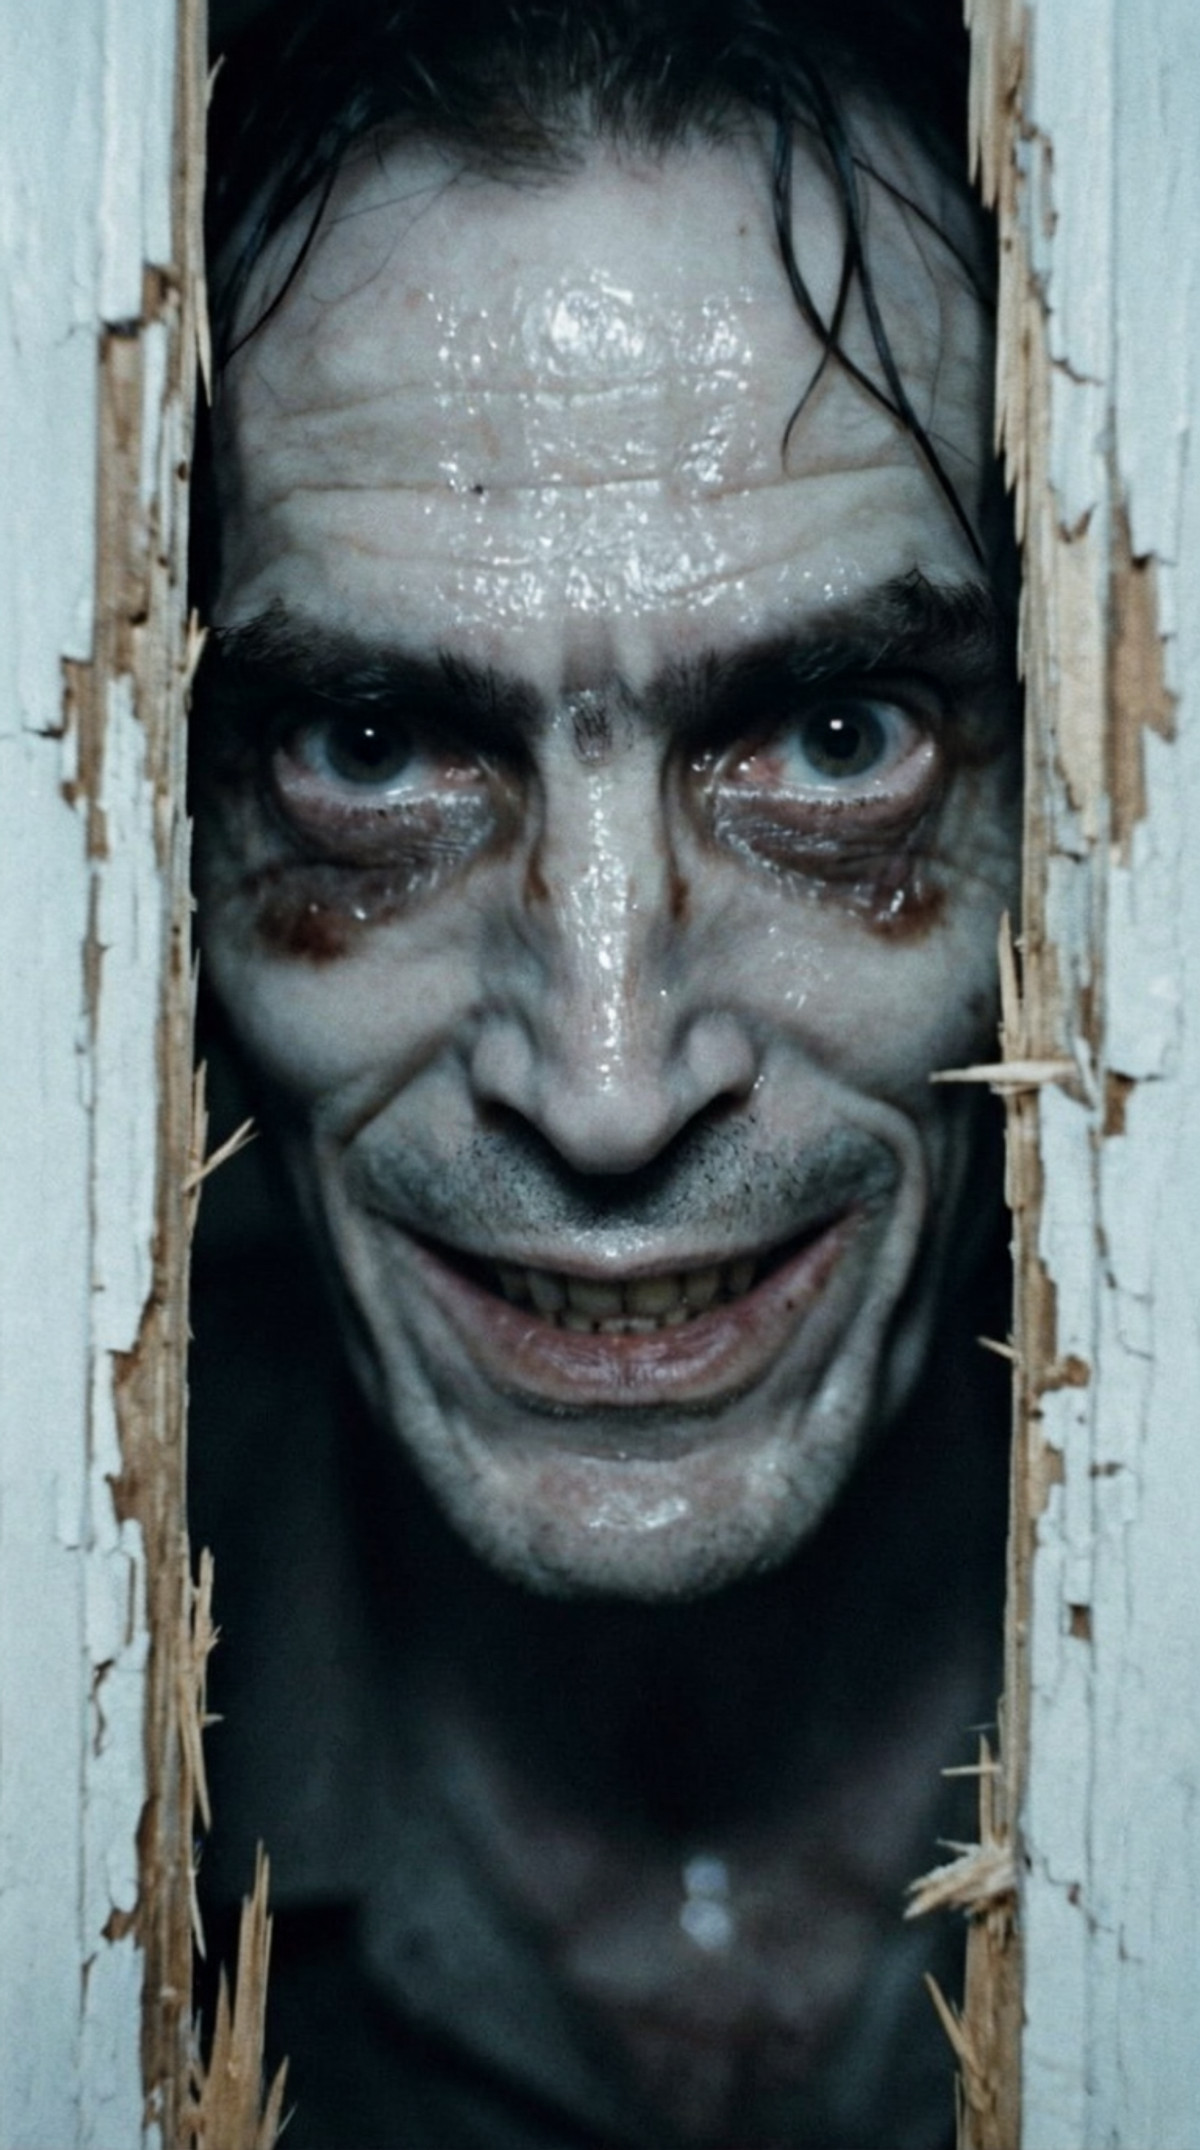
- The Shining LoRA (Krea 2, Moss Image) · v2.0 (Moss Image) — LoRA: A MOSS version of a concept LoRA imitating classic shots from the film "The Shining": It generates extreme close-up photos of a maniac's face peeking through a hole broken in a door; the author states the training set was generated using Gemini.
- Oldies and brats Moss image · Brat33 — LoRA: Brat33 from the character LoRA collection "Oldies and brats": Like other versions on the same page, each version corresponds to a female character; this version is Brat33.
- Prompt Helper [html] - Kromoss - Lens · v1.0 — Other: Not model weights, but an HTML prompt helper designed to work with the Kromoss base model (4 KB compressed archive), offering prompt options for three lens styles: DSLR Color, SLR Color, and SLR B&W.
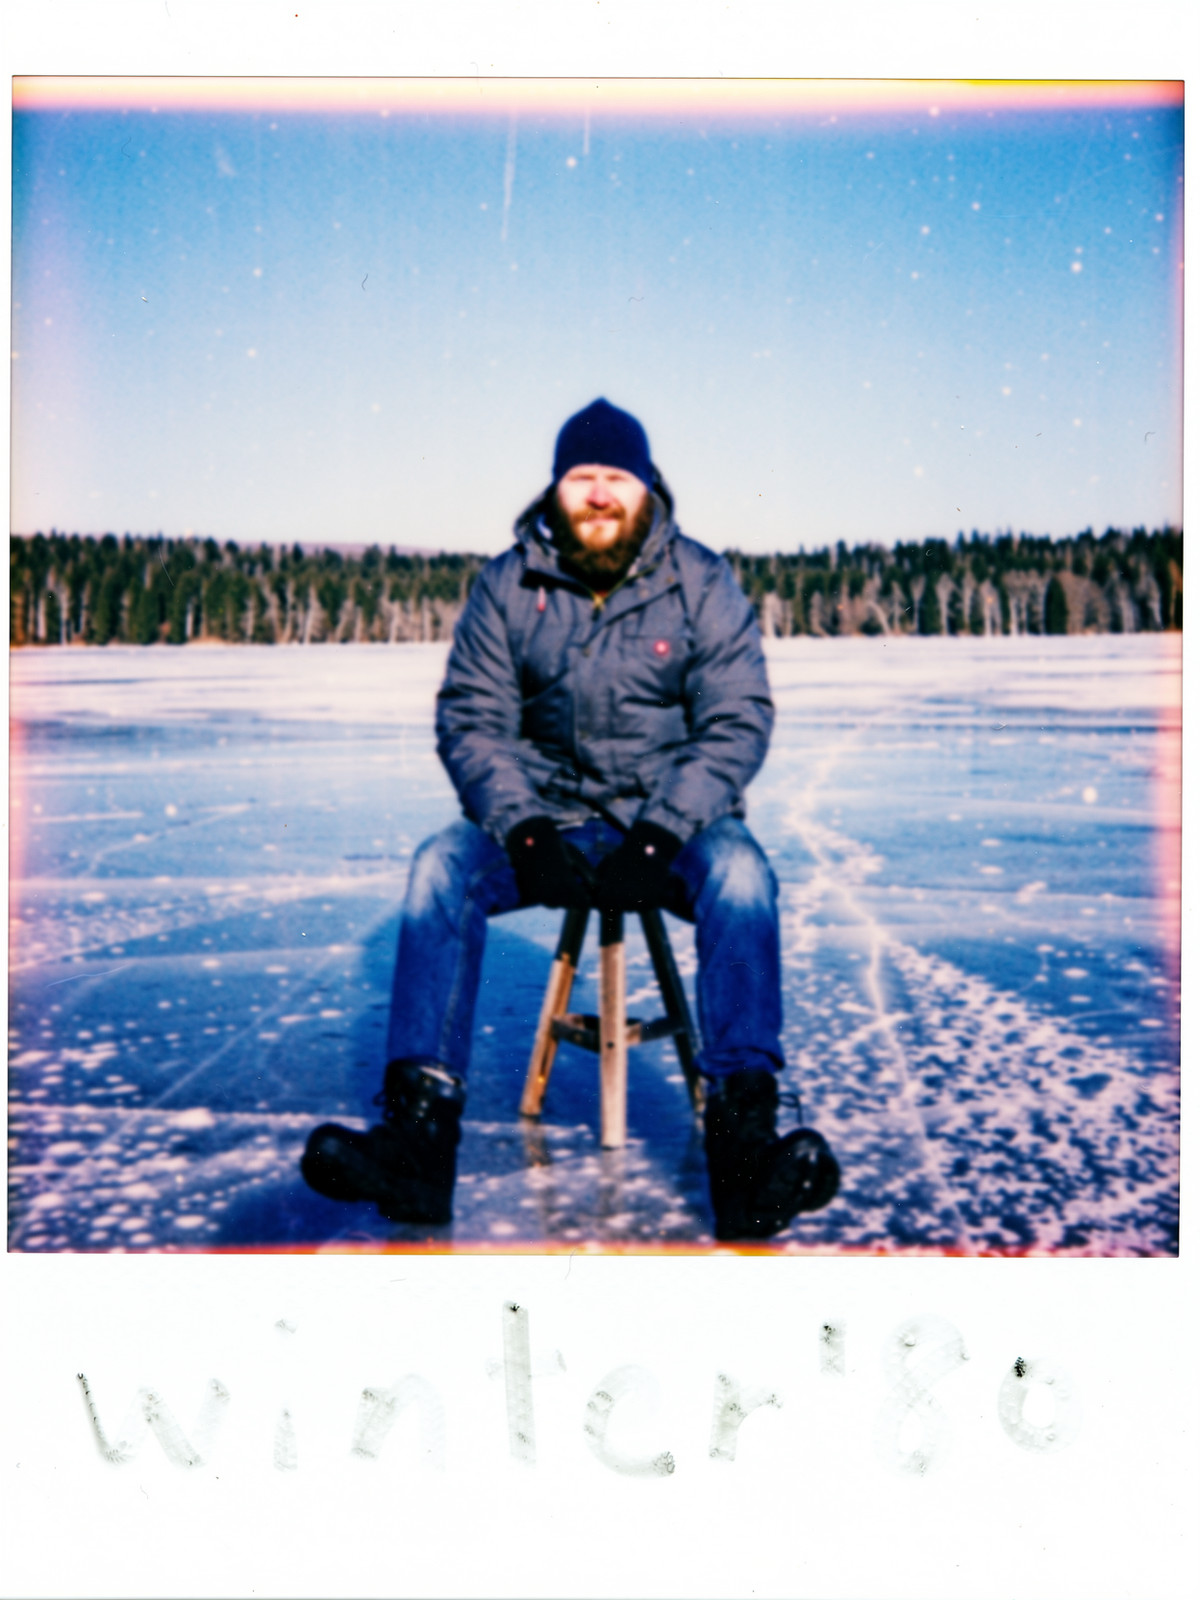
- Prompt Helper [html] - Kromoss - Instant · v1.0 — Other: An HTML prompt helper accompanying another MOSS model, Kromoss, listing 10 instant (Polaroid) style presets, such as LoFi, Sunbleed, Coldfade, night flash, black and white, etc.
- indian-girl-brown-eyes moss - sft · moss-sft — LoRA: The MOSS SFT version of the realistic character LoRA depicting the same Indian female model in her twenties, with the trigger word indian-girl-brown-eyes; the model card contains the same stock-photo-style promotional copy as the Base version.
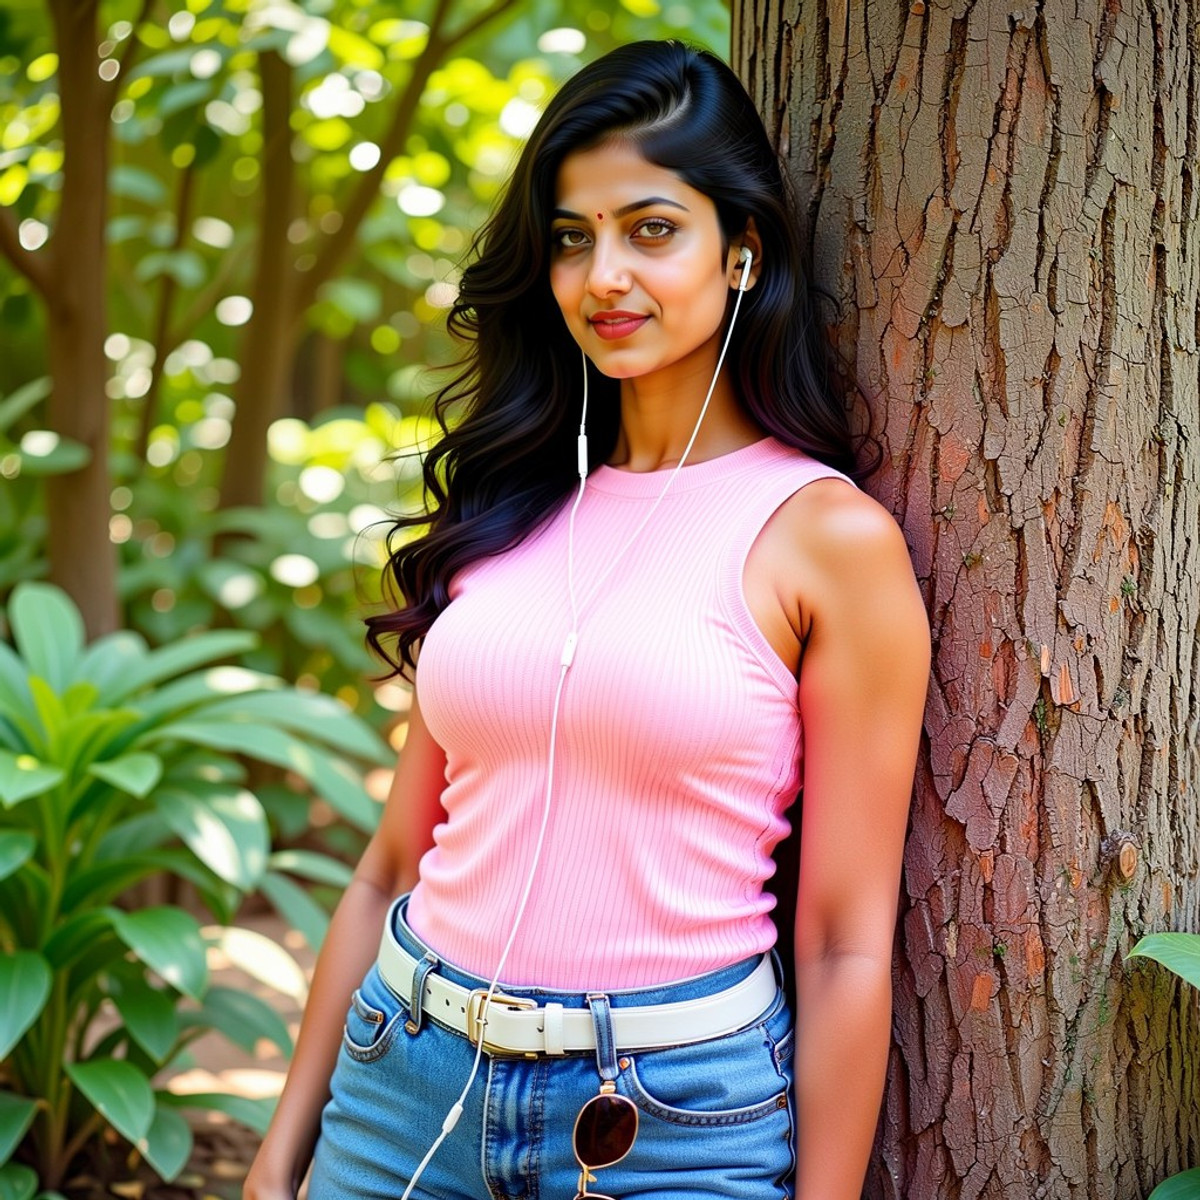
- nu-moss sytle-E detail 2D · v1.3 — LoRA: A "detail-oriented 2D art style" LoRA, which the author explicitly notes is unstable.
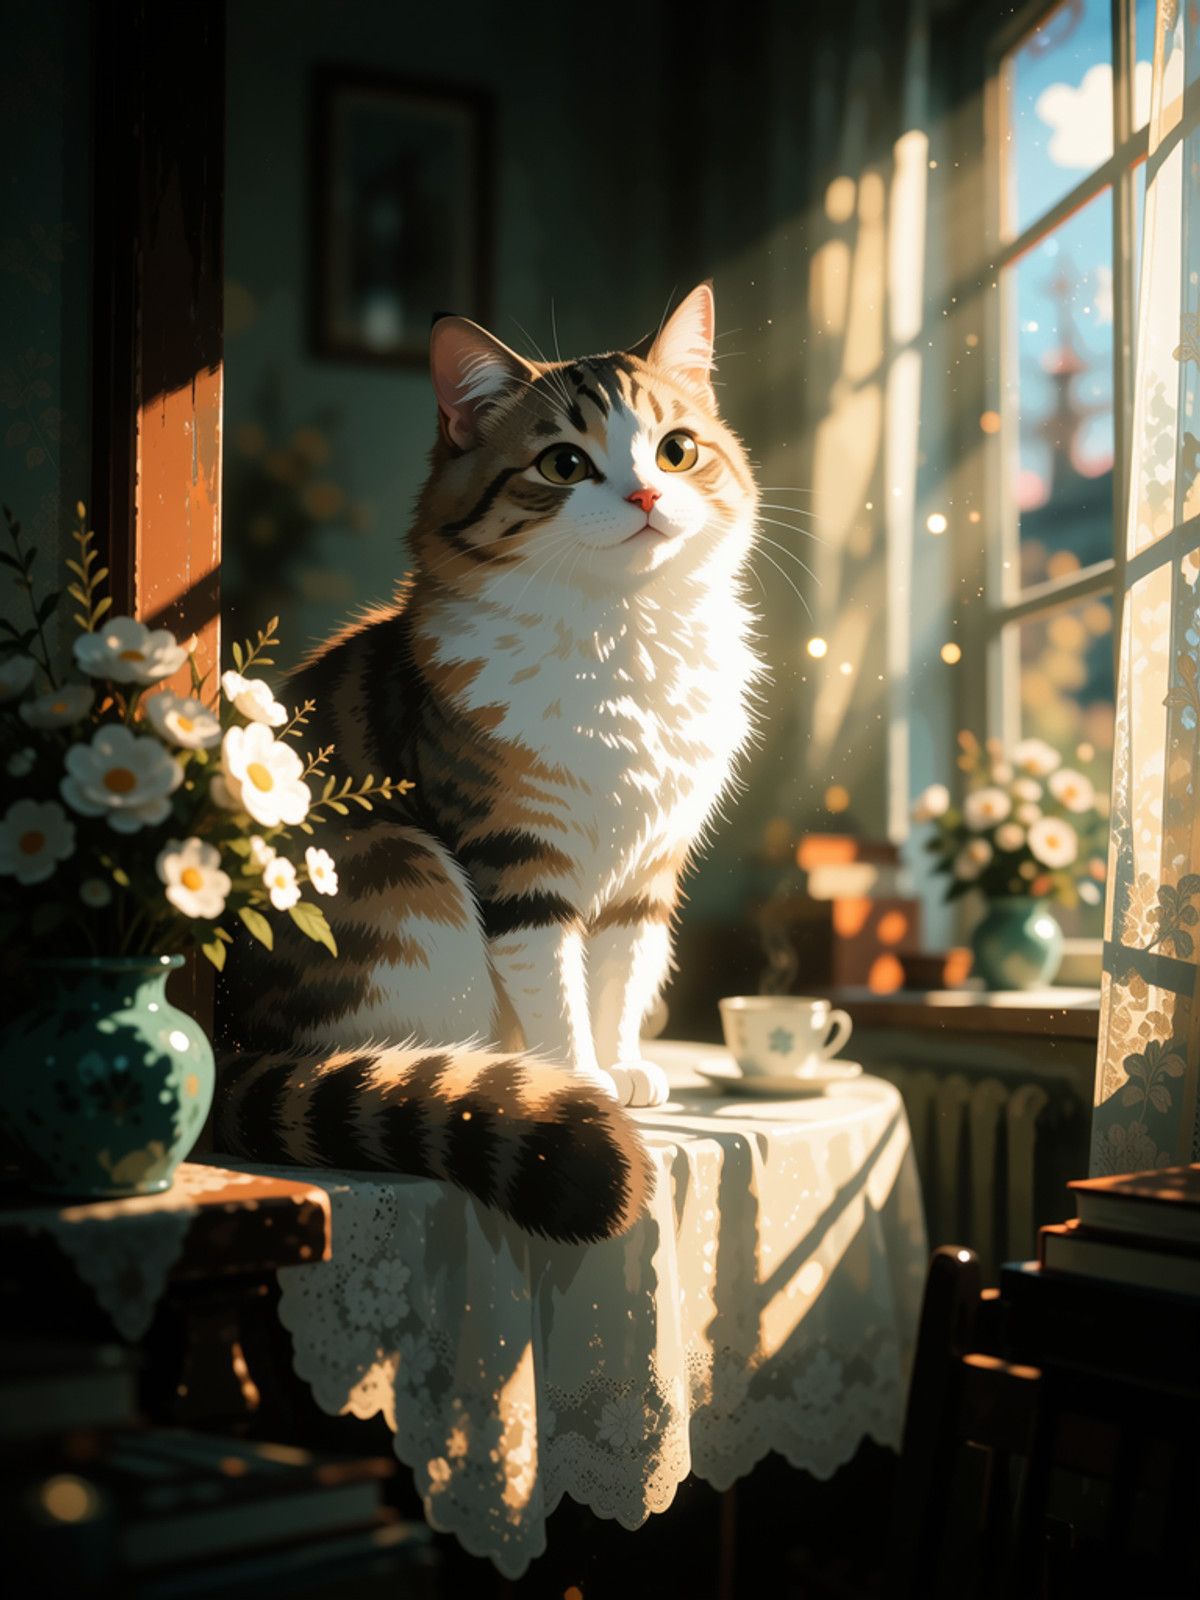
- Jemima NordhavenLove · MossImage — LoRA: A character LoRA for Jemima NordhavenLove, a fictional person created by the author (a harbor photographer who grew up on the coast of Bohuslän, Sweden, often wearing a dark coat with a soft scarf); the author states she is not a real person.
- AuthentiQ - Lian [Krea2/MOSS/ZiT/Anima] · MOSS_SFT_v1.0 — LoRA: The MOSS SFT version of "Lian," an Asian female character LoRA from the AuthentiQ series.
- Chavettes and Essex women for Moss · Chav1 — LoRA: A LoRA depicting young women in the British "chav" and Essex girl style (tags include heavy makeup, female); the description consists only of the title line, so specific effects can only be judged from the examples.
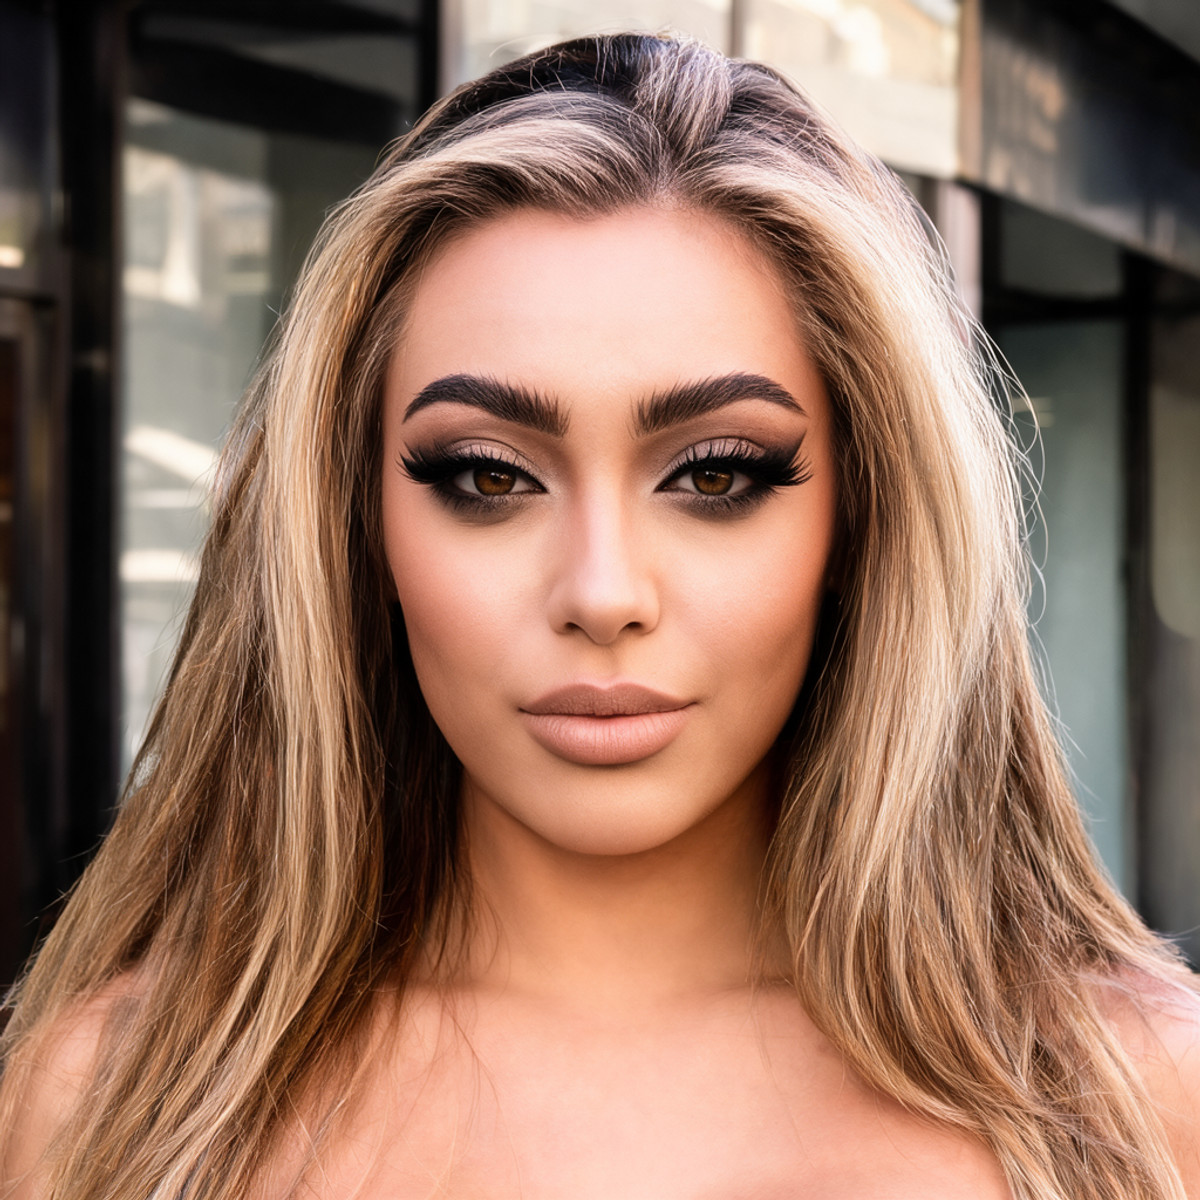
- xionstyle [Anima, Krea 2, MOSS] · v1.0 (MOSS) — LoRA: The MOSS version of the author's personal art style xionstyle: Trained on images created by the author stacking multiple LoRAs on Z-Image, solidifying that mixed style into a single LoRA; the card does not describe stylistic features.
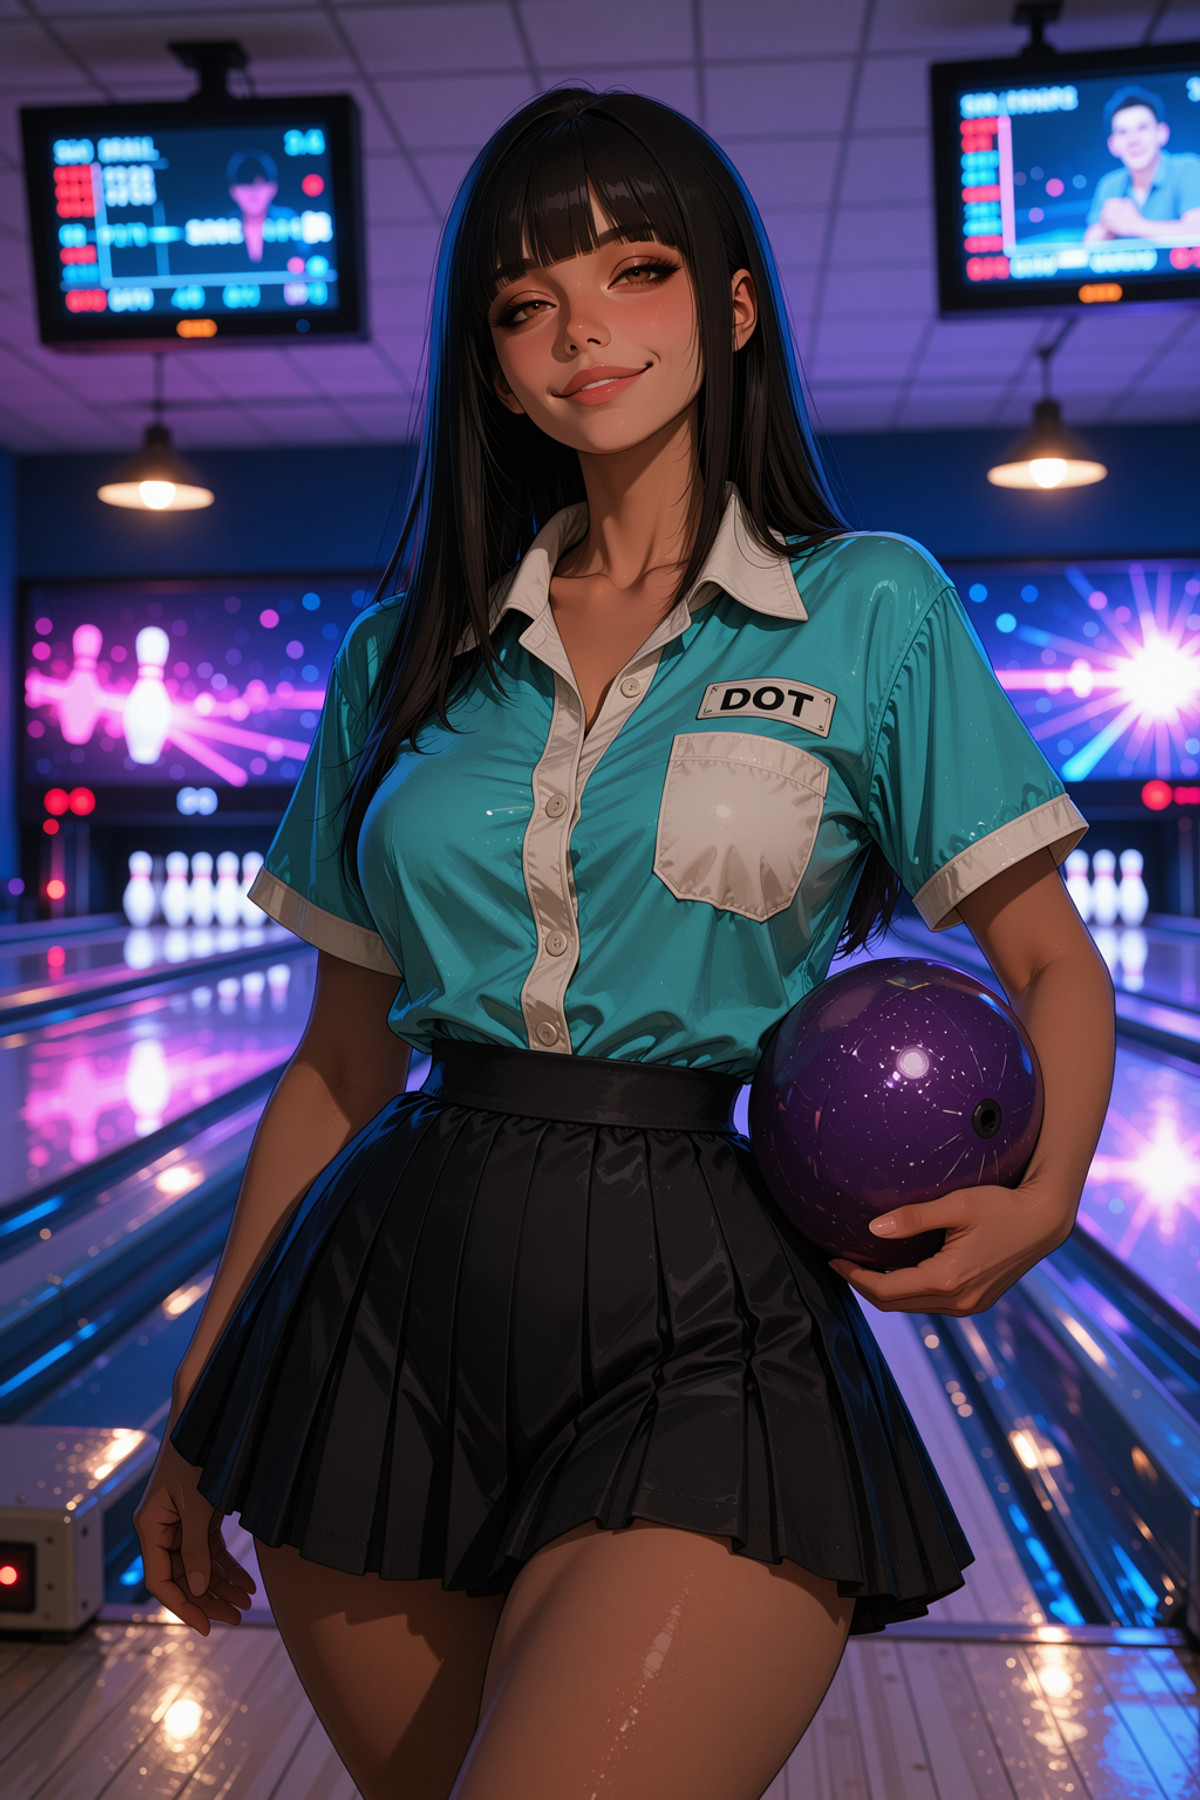
- ShadowVerse-Opulent Strategist シャドウバース-千金武装の大参謀 影之诗-武装千金的大参谋 Black Form · v1.0 — LoRA: A MOSS character LoRA for the "Opulent Strategist" card character from "Shadowverse," in its black form.
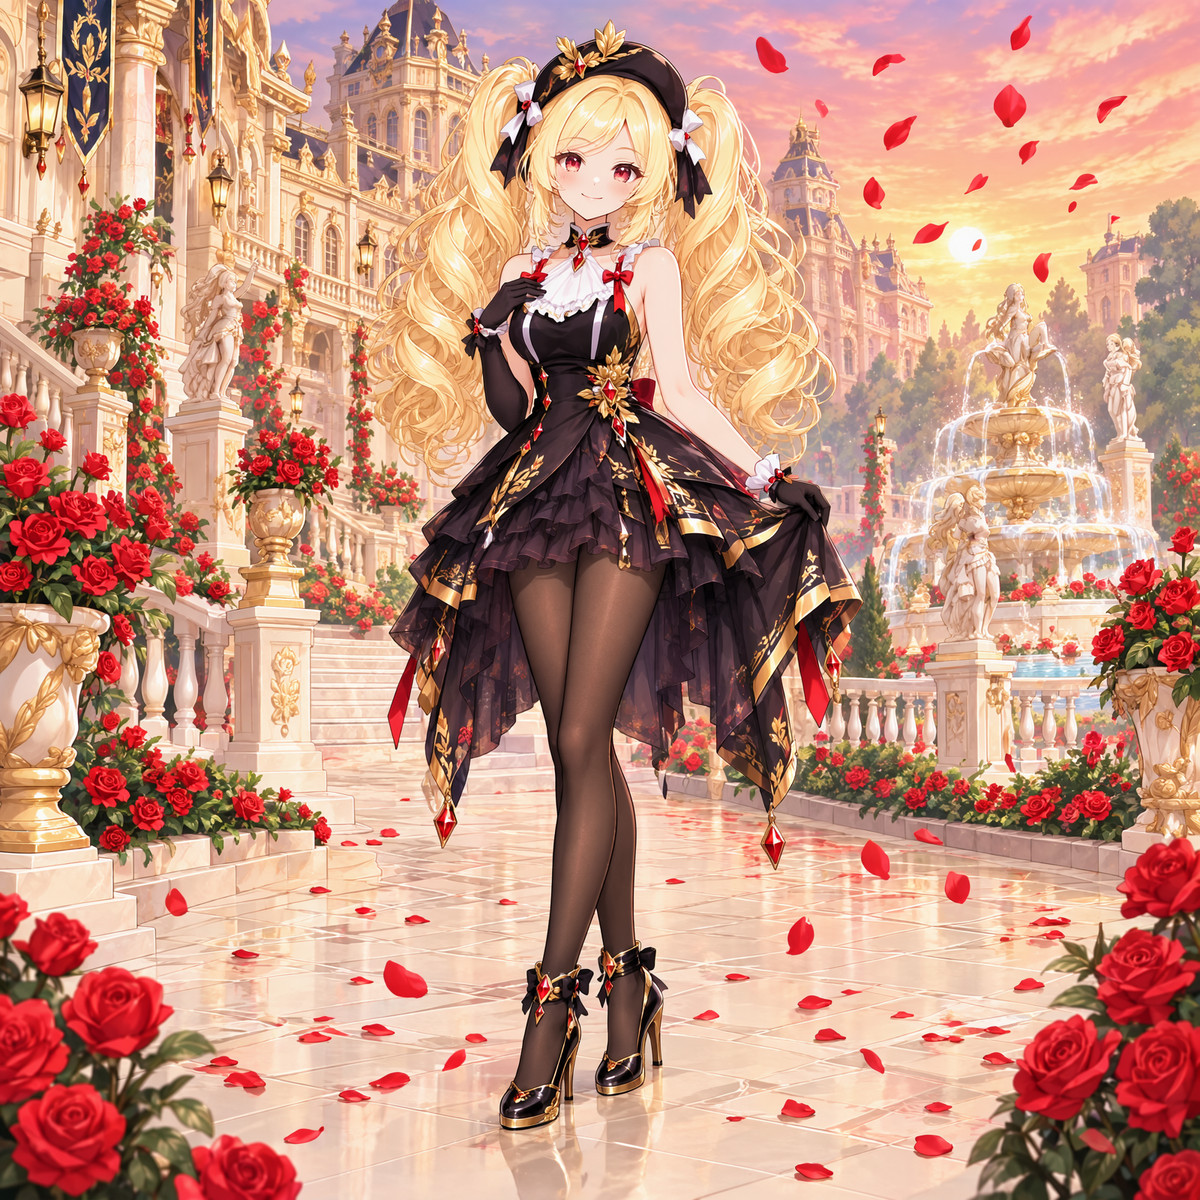
- World of Warcraft Cinematic Style · MOSS — LoRA: A MOSS version (trained on MOSS Base) of a fantasy art style LoRA imitating the CG cinematic quality of "World of Warcraft"; the model card only states "Use Euler/Normal."
- Overwatch Cinematic Style · MOSS — LoRA: A MOSS version (filename indicates MOSS Base) of a LoRA imitating the official CG animation art style of "Overwatch"; the model card contains only one sentence.
- Rocner Style · MOSS — LoRA: The MOSS Base version of an art style LoRA by artist Rocner, featuring a Western cartoon style.
- Chavettes and Essex women for Moss · Chav2 — LoRA: The 2nd version (Chav2) of the LoRA depicting young women in the British "chav" and Essex girl style; the description consists only of the title line, and differences from Chav1 are not explained.
- Chavettes and Essex women for Moss · Chav3 — LoRA: The 3st version (Chav3) of the LoRA depicting young women in the British "chav" and Essex girl style; the description consists only of the title line, and differences from the previous two versions are not explained.
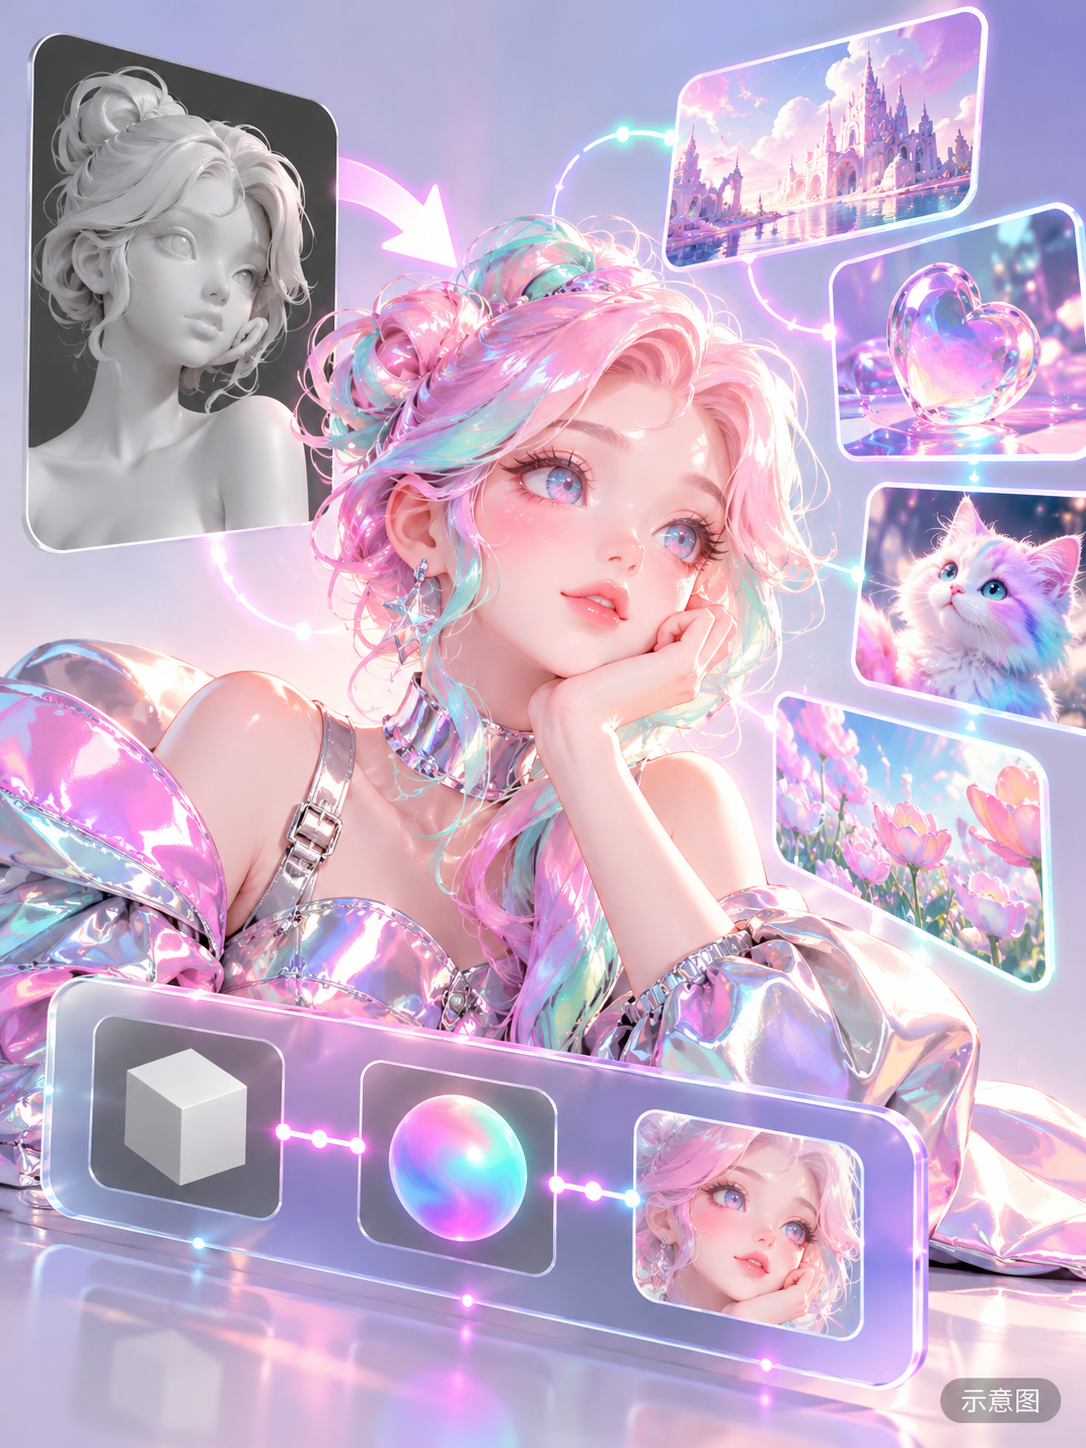
- Bubblegum Gloss Moss Turbo · 1.0 — Base Model / Checkpoint: A MOSS fused base model in the "Bubblegum Gloss" candy-colored glossy illustration style: The author describes it as having airbrushed skin, bright makeup, and pink/mint/lavender hair colors, paired with strong highlights on satin, patent leather, and metal, along with neon rim lighting, sitting between fashion rendering and illustration.
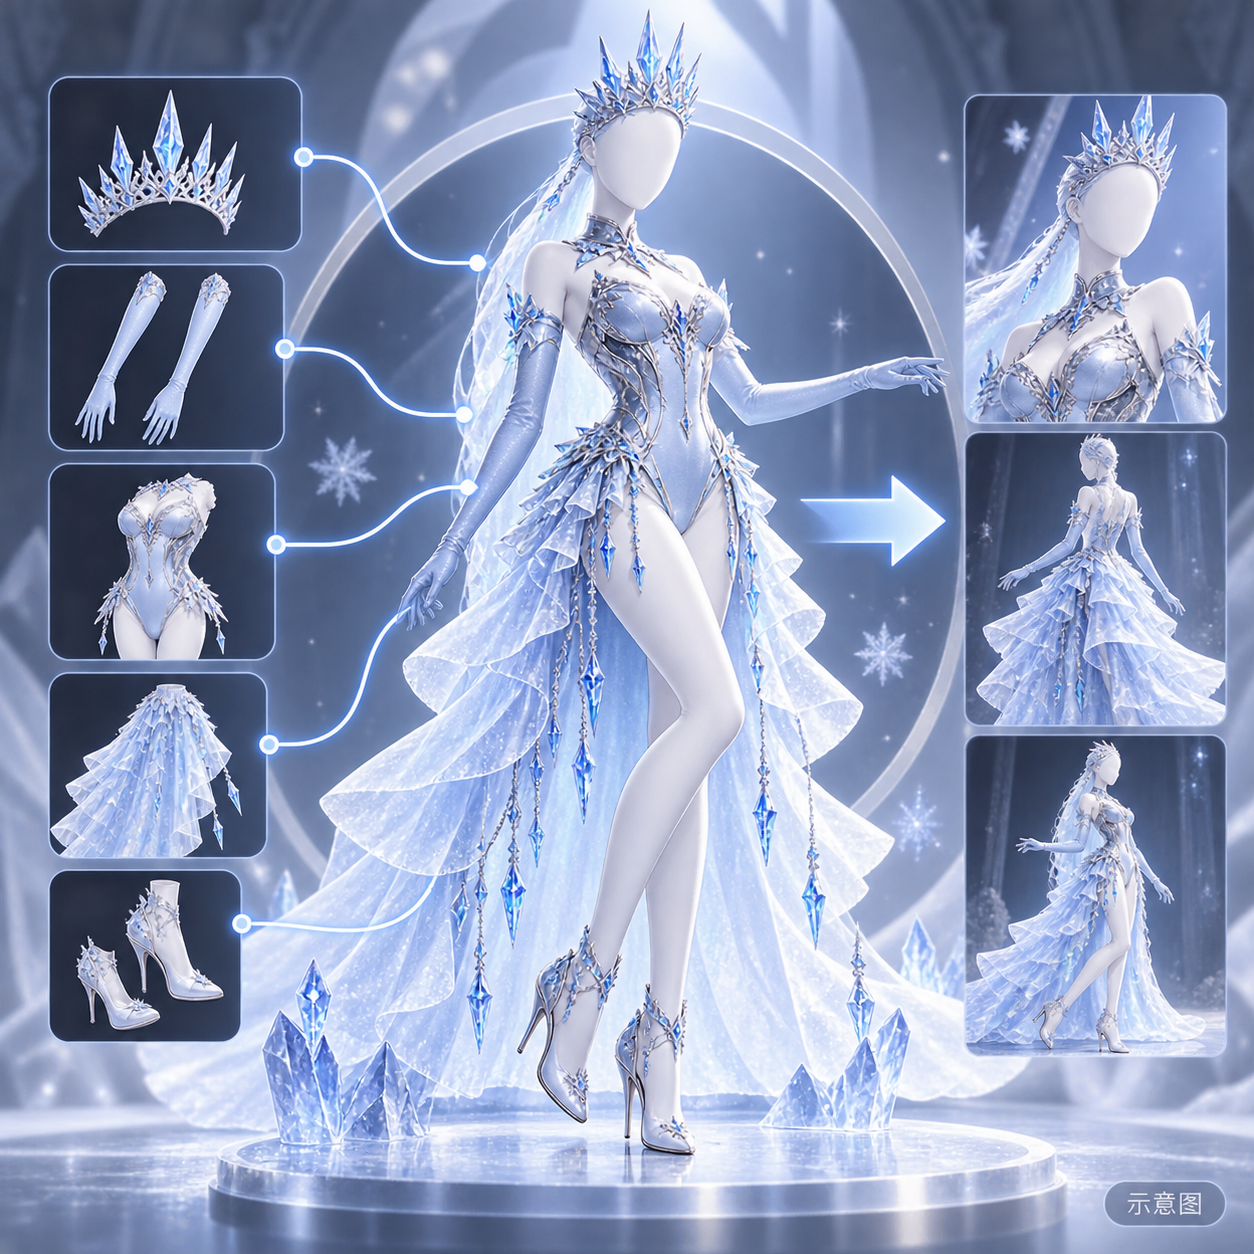
- Final Fantasy Shiva Cosplay (MOSS) · v1.0 — LoRA: A cosplay costume LoRA for the summon "Shiva" from "Final Fantasy": Featuring an ice crown, long gloves, high heels, a bodysuit with showgirl-style skirts and icicle decorations.
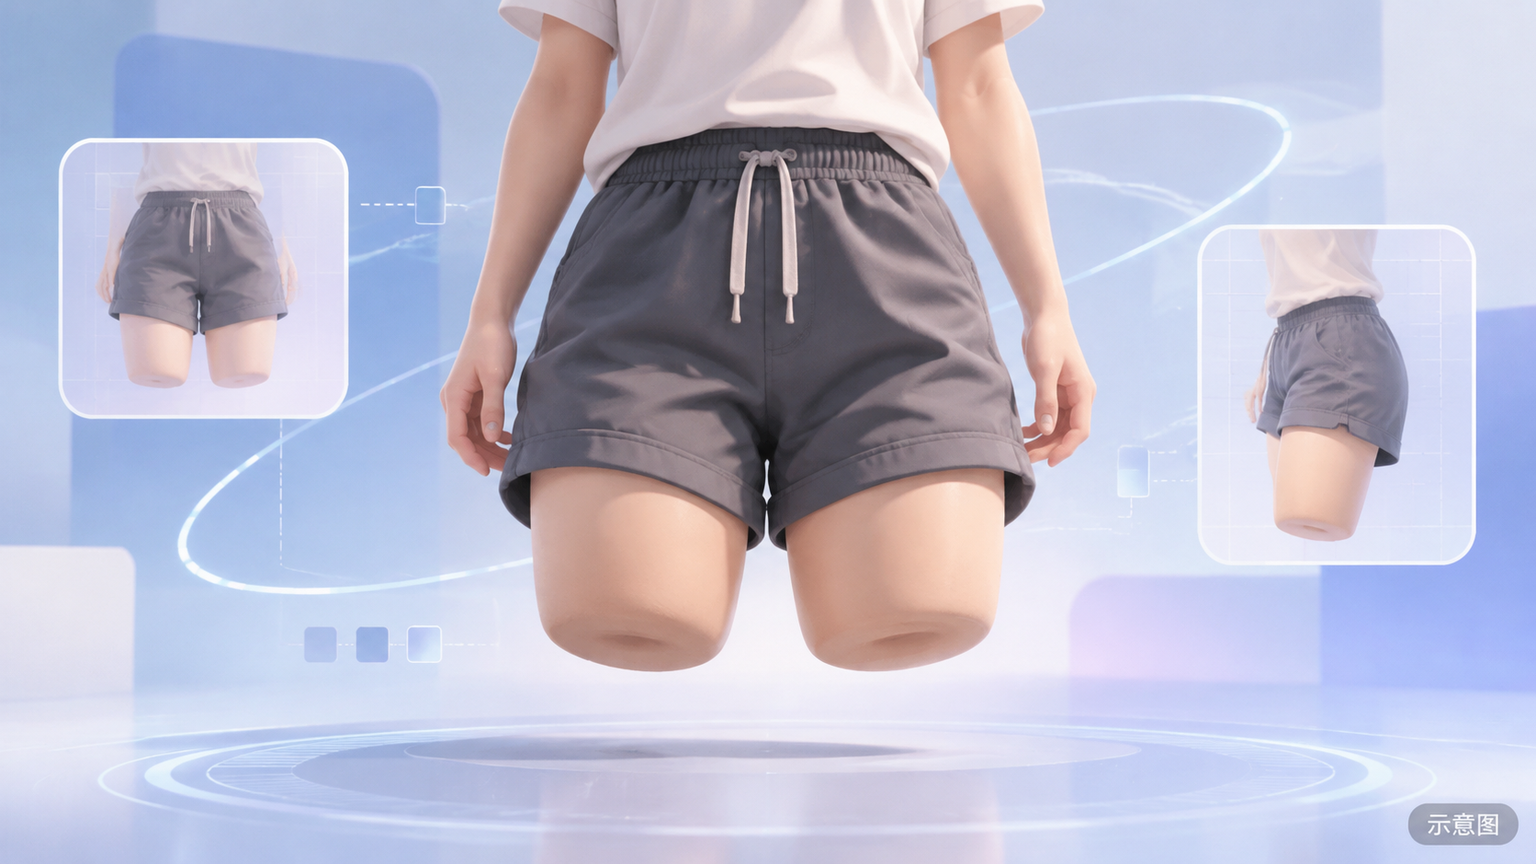
- Double above knee stubbies · Moss Image — LoRA: A MOSS version of a human anatomy concept LoRA featuring bilateral above-knee amputations (stumps).
Data: Civitai Public API (Base Model MOSS Image), collection window 10-30 20:31 → 10-31 09:01 (Beijing Time). Recommendation reasons have been reviewed by editors; download counts only reflect attention levels.