Zhenzhen's AI Radar · MOSS Image · 2026-11-03 Evening Report
This issue features 34 new versions: Strongly Recommended 1 · Recommended 11 · Worth Watching 9 · Listed Only 13
Editor's Note This issue reviews 35 new MOSS versions. Top pick: FFF_MOSS-Alba integrated checkpoint, which directly integrates the author's anime character style into MOSS-Image SFT. It is ready to use upon loading, requiring no LoRA or trigger words. Backgrounds and text retain MOSS's original rendering, with sampling parameters and negative prompts fully specified. Tier A includes the Cat Tower v2 anime checkpoint, the FFF_MOSS-Alba-style LoRA in the same style, dark fantasy and thick ink line graphic novel styles, Lomo fisheye film, olive-gray cinematic color grading, doll style, realistic female portraits, Lada cars, and a text-to-image workflow for 8 GB VRAM. The auto-S rated realistic lifestyle photo v2 and Kisa character port are downgraded to B; scene-based LoRAs are downgraded to B due to few visible examples; fictional characters trained on AI-generated images and standard anime character LoRAs are rated C.
Strongly Recommended (1)
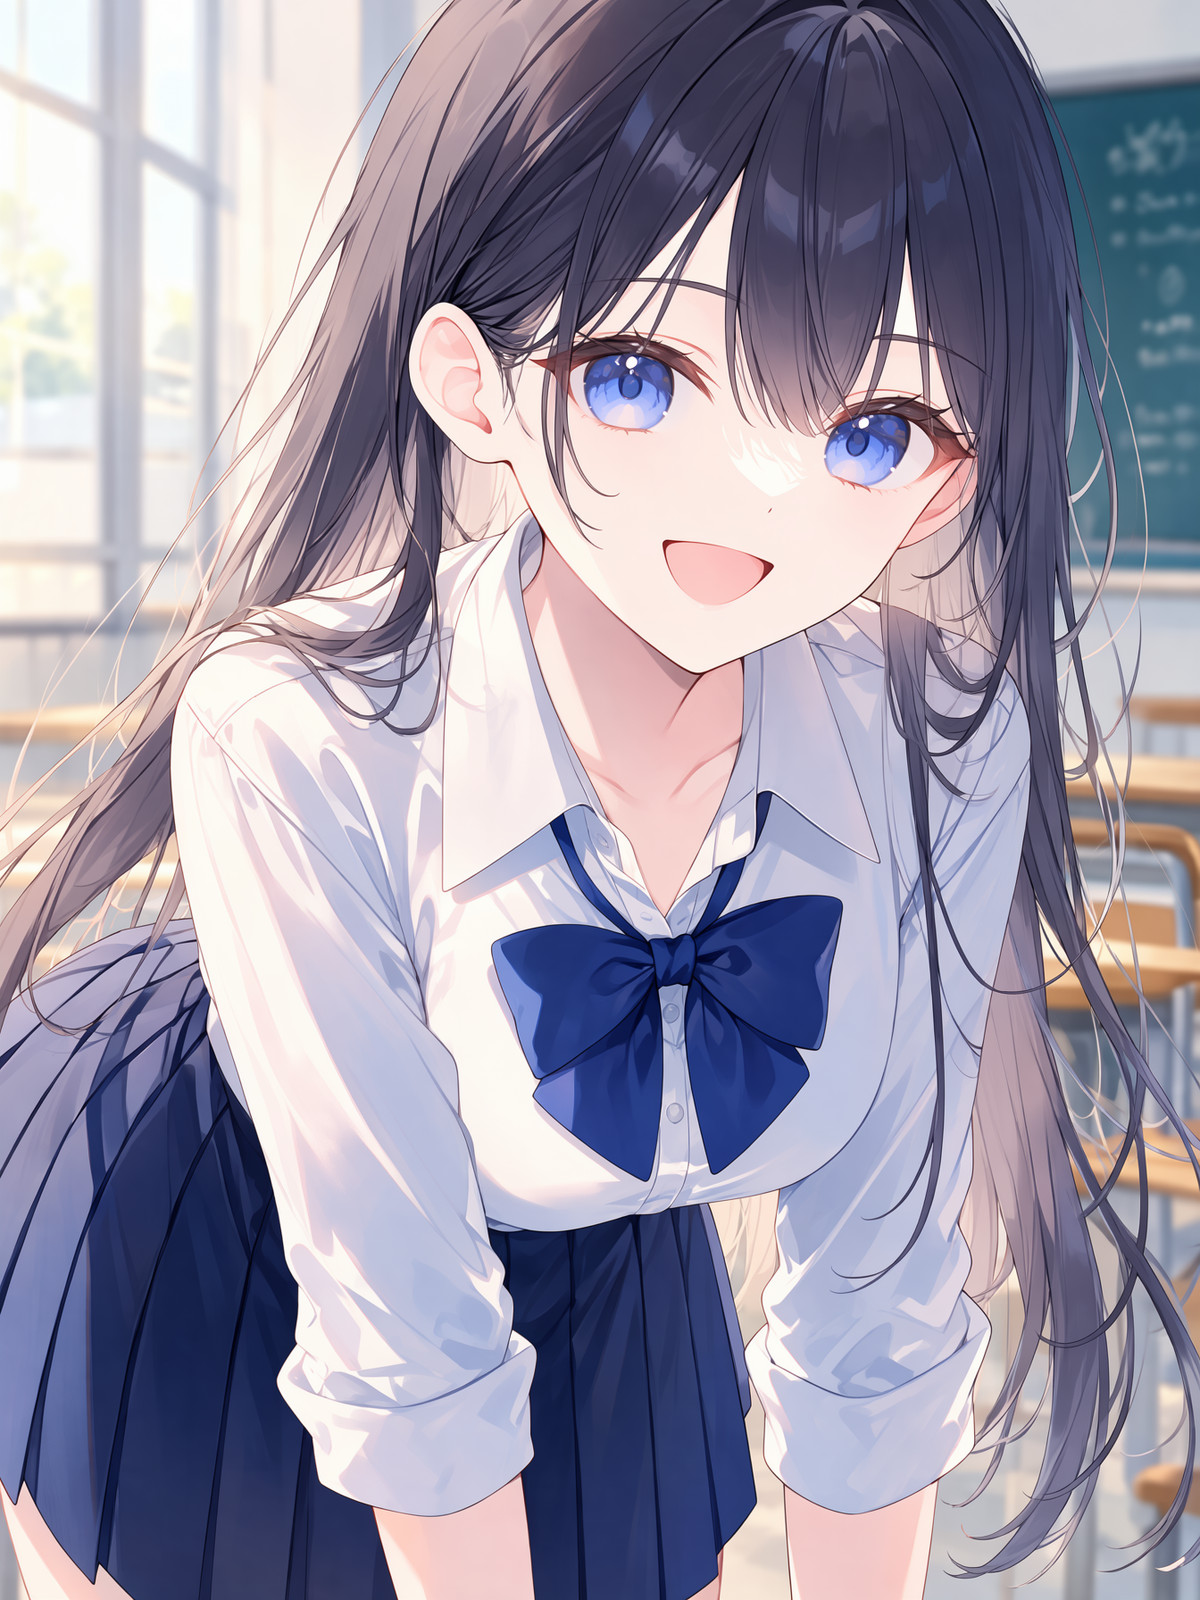
[S] FFF_MOSS-Alba · v1.0
Checkpoint · New Model · Author: flyfront · Published 11-03 14:18 · Downloads 57
An integrated checkpoint that directly merges the author's FFF_ANIMA-Alba anime style into MOSS-Image SFT: no LoRA required, no trigger words needed, characters are generated in this style, while backgrounds and text retain MOSS's original rendering.
Upgraded from A to S: The automatic score was capped due to "missing usage facts," but the actual model card parameters are complete. This is the only integrated checkpoint in this group, ready to use upon loading, suitable for those who do not want to stack style LoRAs.
Images
Reasons for Recommendation
- New model: The author states they performed full fine-tuning on MOSS-Image Base using 1,377 images generated by FFF_ANIMA-Alba, calculating loss only on the character parts, then overlaying the weight changes onto MOSS-Image SFT. Thus, only the character style is changed, leaving scenes and text untouched.
- Serves illustration and poster generation needs where users want a unified anime character style while retaining MOSS's background details and text rendering within quotes; both danbooru tags and English sentences are supported.
- Complete usage instructions: Sampler, steps, scheduler, CFG, resolution, and negative prompt additions are all specified. A LoRA version of the same style (FFF_MOSS-Alba-style) is also available for other MOSS Base checkpoints.
- Free, with 5 visible examples and no hidden examples; approximately 7 hours after release, it has 57 downloads (indicating attention level only).
How to Use
- Load as a replacement for MOSS-Image SFT: Text encoder Qwen3.5-9B, VAE uses FLUX.2 small-decoder; the author recommends the int8 file (approx. 5 GB), stating the image quality is nearly identical to bf16 (9.5 GB) but with about half the processing time.
- Euler, 25-30 steps, MOSS or Simple scheduler (shift 5), CFG 3; resolution approx. 2.4M pixels, any aspect ratio (1344x1792, 1792x1344, 1536x1536), reducing to approx. 1M pixels is also acceptable.
- No trigger words; add "best quality, highres" to every prompt; use the standard MOSS-Image negative prompts, plus "blush, embarrassed" (SFT tends to default to blushing), "overexposure" (to prevent overexposure in daytime scenes), and "warm lighting" (to prevent overall orange tint).
Risks and Limitations
- Training images are generated by the author's own Anima model, effectively distilling an existing style into MOSS; the author states that prompts for other styles like realistic photos and watercolors still elicit responses, but weaker than SFT.
- 1boy often generates as a girl; the author suggests using a descriptive sentence for male characters instead.
- Full negative prompts and detailed settings are on the Hugging Face page; the Civitai card only contains a summary.
- The author specifies an Apache 2.0 license, but the Civitai license section only checks image output and rental, not sales; verify with the author's original text before commercial use; this entry was not tested.
Recommended (11)
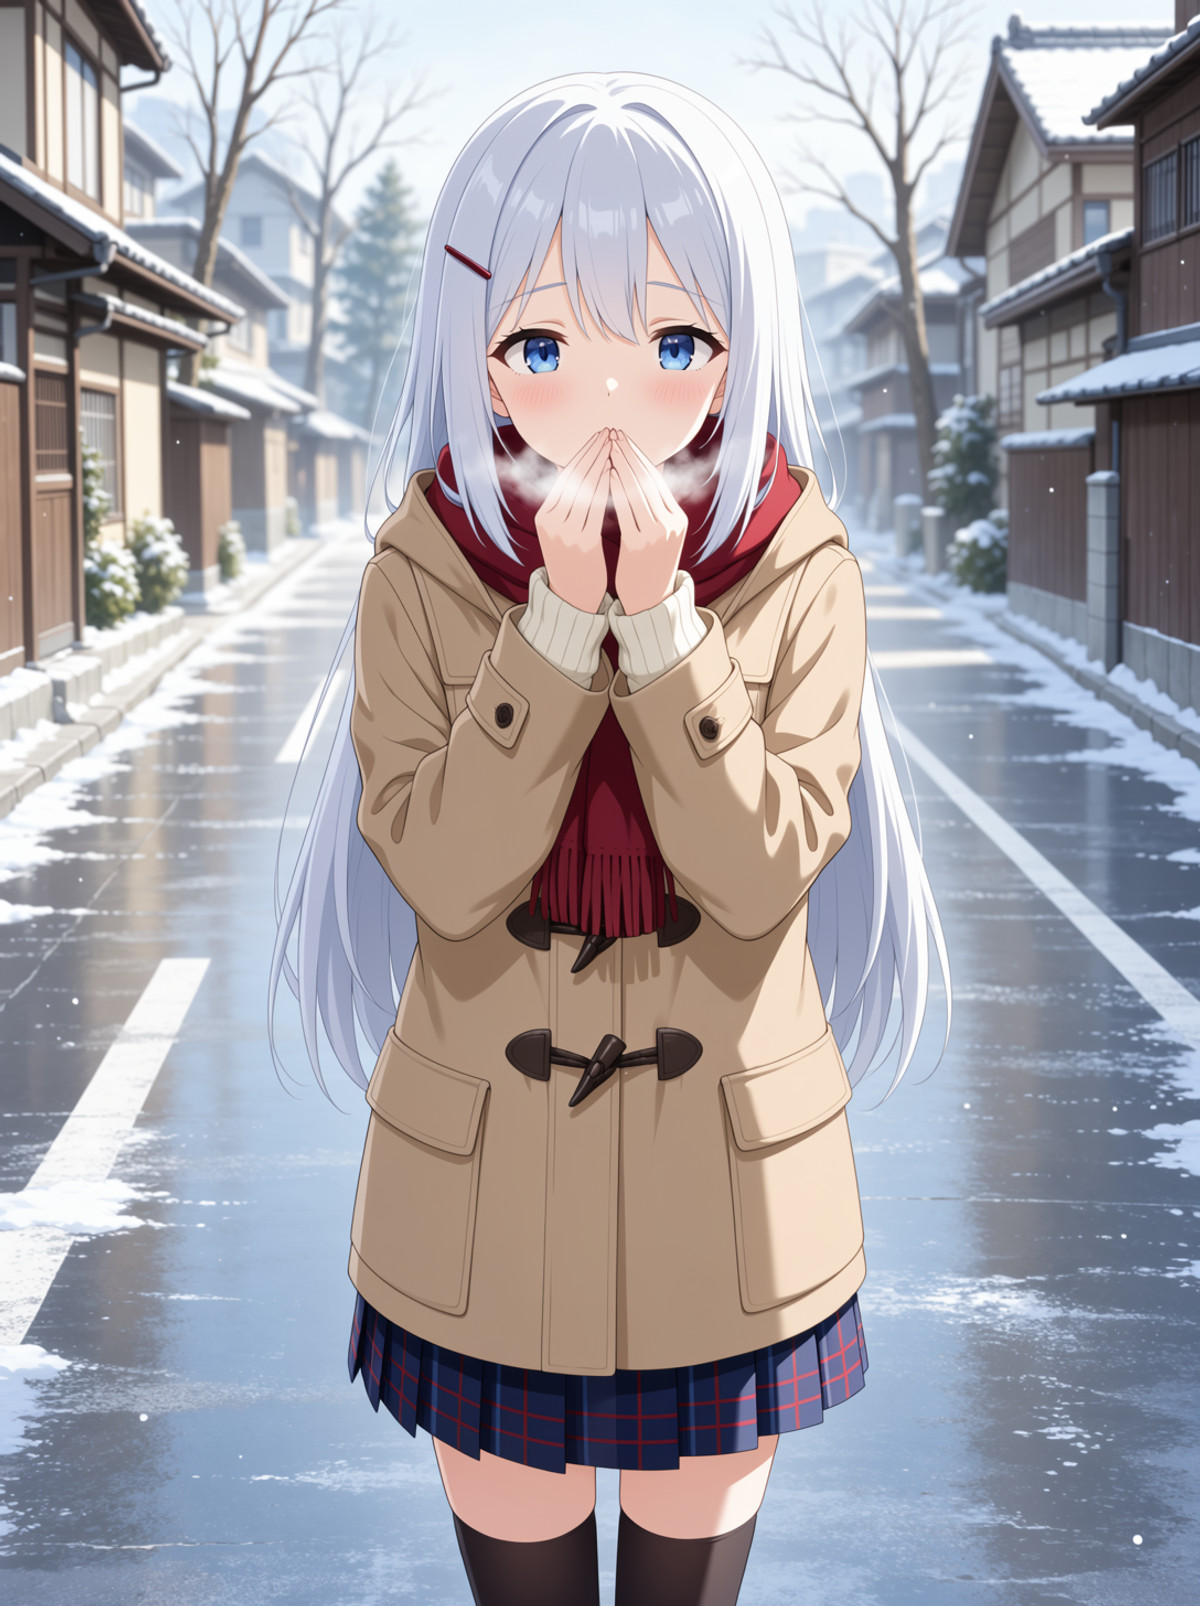
[A] MOSS Cat Tower · v2.0
Checkpoint · Version Update · Author: nuko_masshigura · Published 11-03 14:10 · Downloads 233
v2 of Cat Tower, an anime-oriented MOSS Image fine-tuned checkpoint. The author states the default style has been adjusted, and it requires skip-layer guidance for output.
Top pick in this group. Full model, parameters can be copied directly, most examples; the only shortcoming is the overly brief update notes. Existing users are advised to compare with v1 before upgrading.
Images
Reasons for Recommendation
- Version update: Update notes are only two sentences—default style adjusted, training settings same as v1; no specific direction of adjustment is mentioned.
- Serves anime illustrations in text-to-image generation: The author states this is a full model fine-tuned on MOSS-Image to enhance the default anime style. It is ready to use by swapping the checkpoint, without needing to stack style LoRAs.
- The author provides very complete recommended settings (resolution, steps, CFG, sampler, scheduler, skip-layer guidance layer numbers and start/end ratios, negative prompts), noting that without skip-layer settings, the style is unstable and anatomy is often incorrect.
- Free, with 19 visible examples; this version has 233 downloads, cumulative downloads for the entire model are 2167 (indicating attention level only).
How to Use
- Select mossCatTower_v20_bf16 or int8 version as the checkpoint; also requires Qwen3.5 9B text encoder (choose one of bf16 / int8_convrot / w4a8_gptq) and flux2-vae (or flux2-vae_small).
- Requires ComfyUI v0.42.1 or higher, or Forge Neo 2.31 or higher.
- Resolution 1-2MP, Steps 50, CFG 3, euler + simple.
- Skip-layer guidance: In ComfyUI, use the SkipLayerGuidanceDiTSimple node, skip 22,24,26 layers, Start 0.35, End 0.7; in Forge Neo, set in Settings → Stable Diffusion and restart.
- Write prompts according to the official MOSS-Image-Base guide; negative prompts: worst quality, bad anatomy, watermark, jpeg artifact; no trigger words.
Risks and Limitations
- Update notes are too brief to discern the direction of style changes in v2 relative to v1; users must compare using the same prompt themselves.
- Strongly dependent on skip-layer guidance; the author states that without it, the style is unstable and anatomy is prone to errors; output at 50 steps is slow.
- Full model bf16 version is approx. 9.5 GB, int8 version is approx. 5 GB; 1 sensitive-level examples are hidden; this entry was not tested.
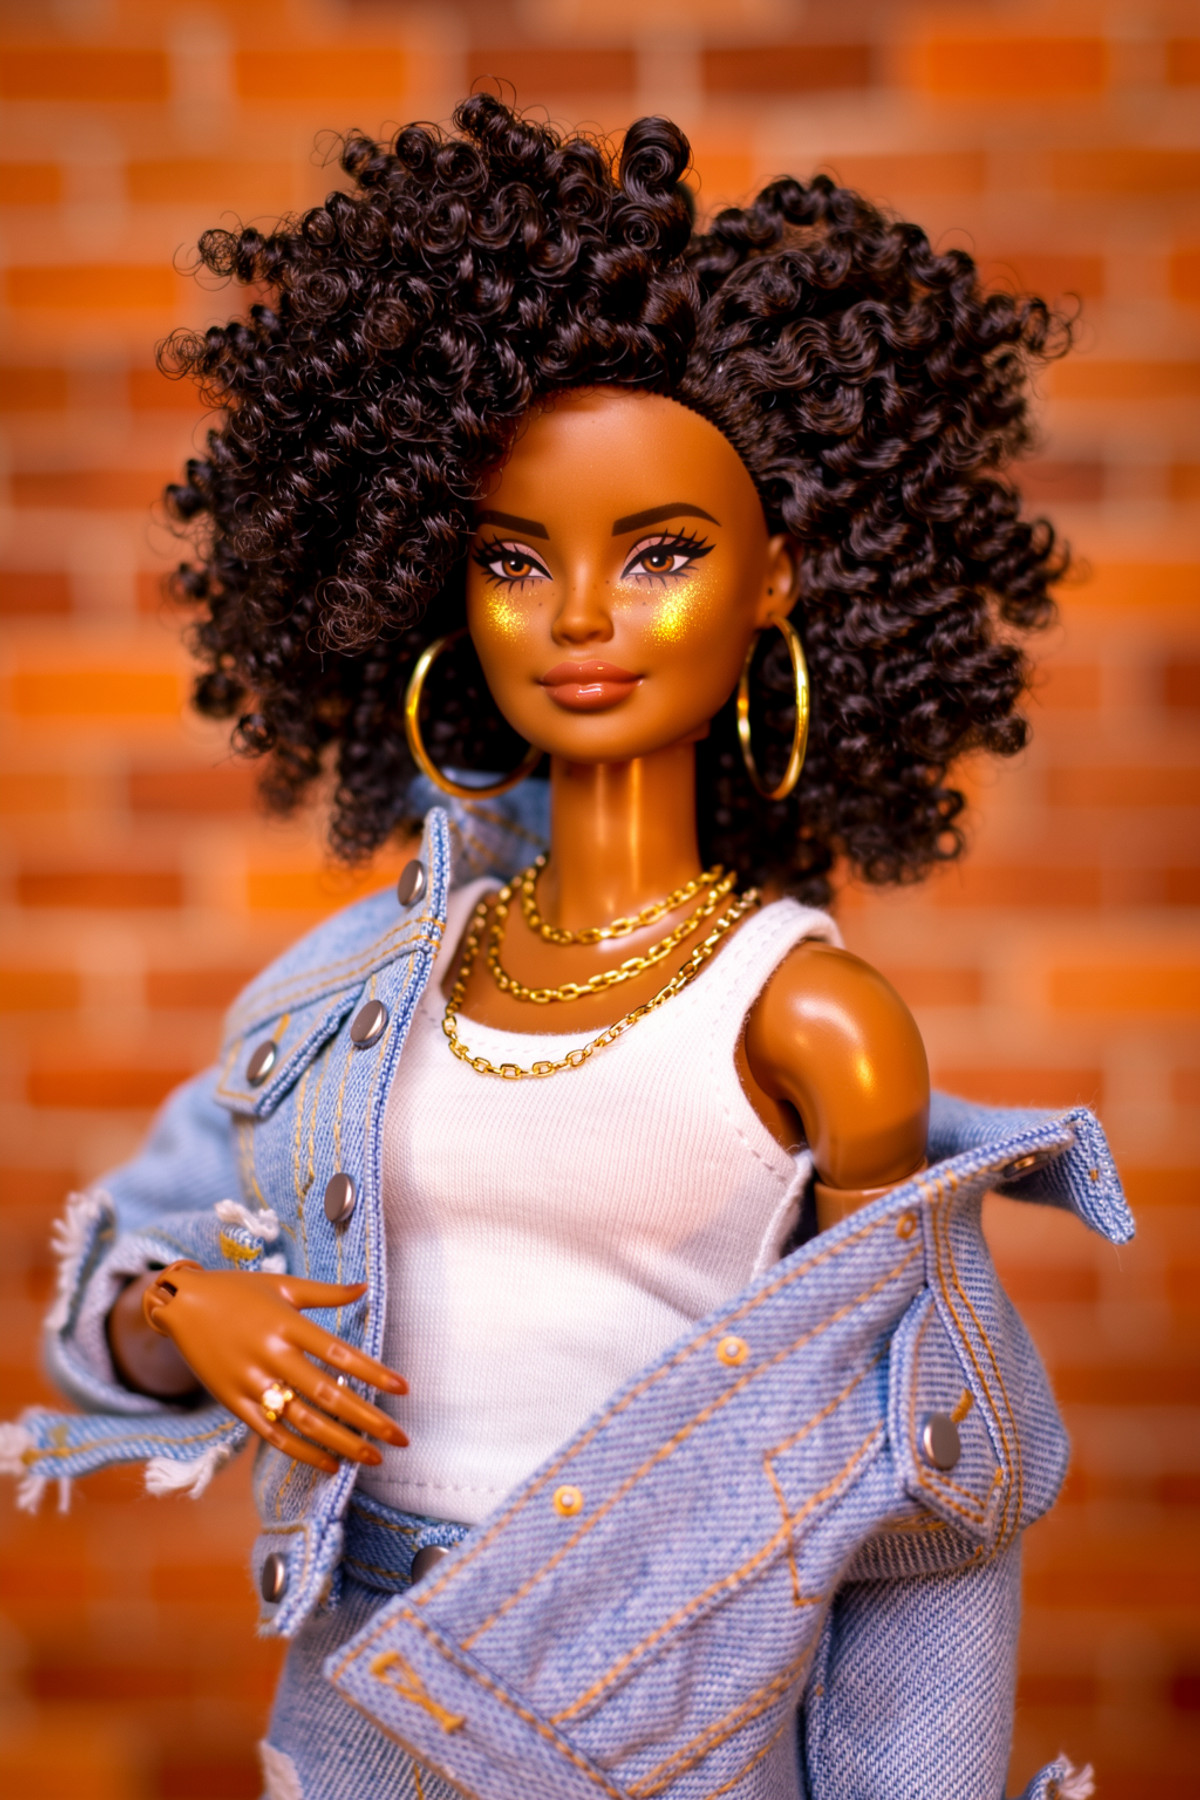
[A] AG: Raum - Barbie Doll Style · MOSS-Image
LoRA · Port · Author: Azriaelis · Published 11-03 11:00 · Downloads 43
The MOSS version of the Barbie doll style LoRA from the "Ars Goetia" series: renders characters as fashion dolls with doll joints. The author states the style is significantly enhanced when the trigger word is added.
Downgraded from S to A: This entry has the most complete parameters and can be copied directly, but training data sources are mixed, the author admits quality is inconsistent, and visible examples are fewer than hidden examples.
Images
Reasons for Recommendation
- Port: Previous versions existed for Anima and Krea 2 (Turbo); the difference in the MOSS version lies in usage—the author provides a separate set of MOSS parameters, requiring the use of a 8-step Turbo LoRA on MOSS Base. Strength and CFG are higher than the Anima version, with fewer steps.
- Serves portraits and character images with a doll/fashion doll texture; tags include "doll joints"; the author states the style is much stronger with the trigger word.
- Actionable: Trigger word, sampler, scheduler, strength, steps, and CFG are all provided; free; includes 6 example images.
- This version has 43 downloads, cumulative downloads for the entire model are 471 (indicating attention level only).
How to Use
- Load RAUM-MOSS-V1 (1).safetensors, include "@R44UMX7" and "doll" in the prompt.
- Author's MOSS parameters: MOSS Base + 8-step Turbo LoRA, euler + simple, strength 0.8–1, steps 8–16, CFG 1–3.
- The author did not specify which Turbo LoRA to use.
Risks and Limitations
- The author states training images are a mix of sources including Midjourney, NijiJourney, and Tumblr, and admits the series quality is inconsistent and is a small experiment.
- 7 sensitive-level examples are hidden, more than the visible examples.
- License does not allow merging/derivatives; "Barbie" is a Mattel trademark, be cautious before commercial use; this entry was not tested.
Trigger Words: @R44UMX7, doll
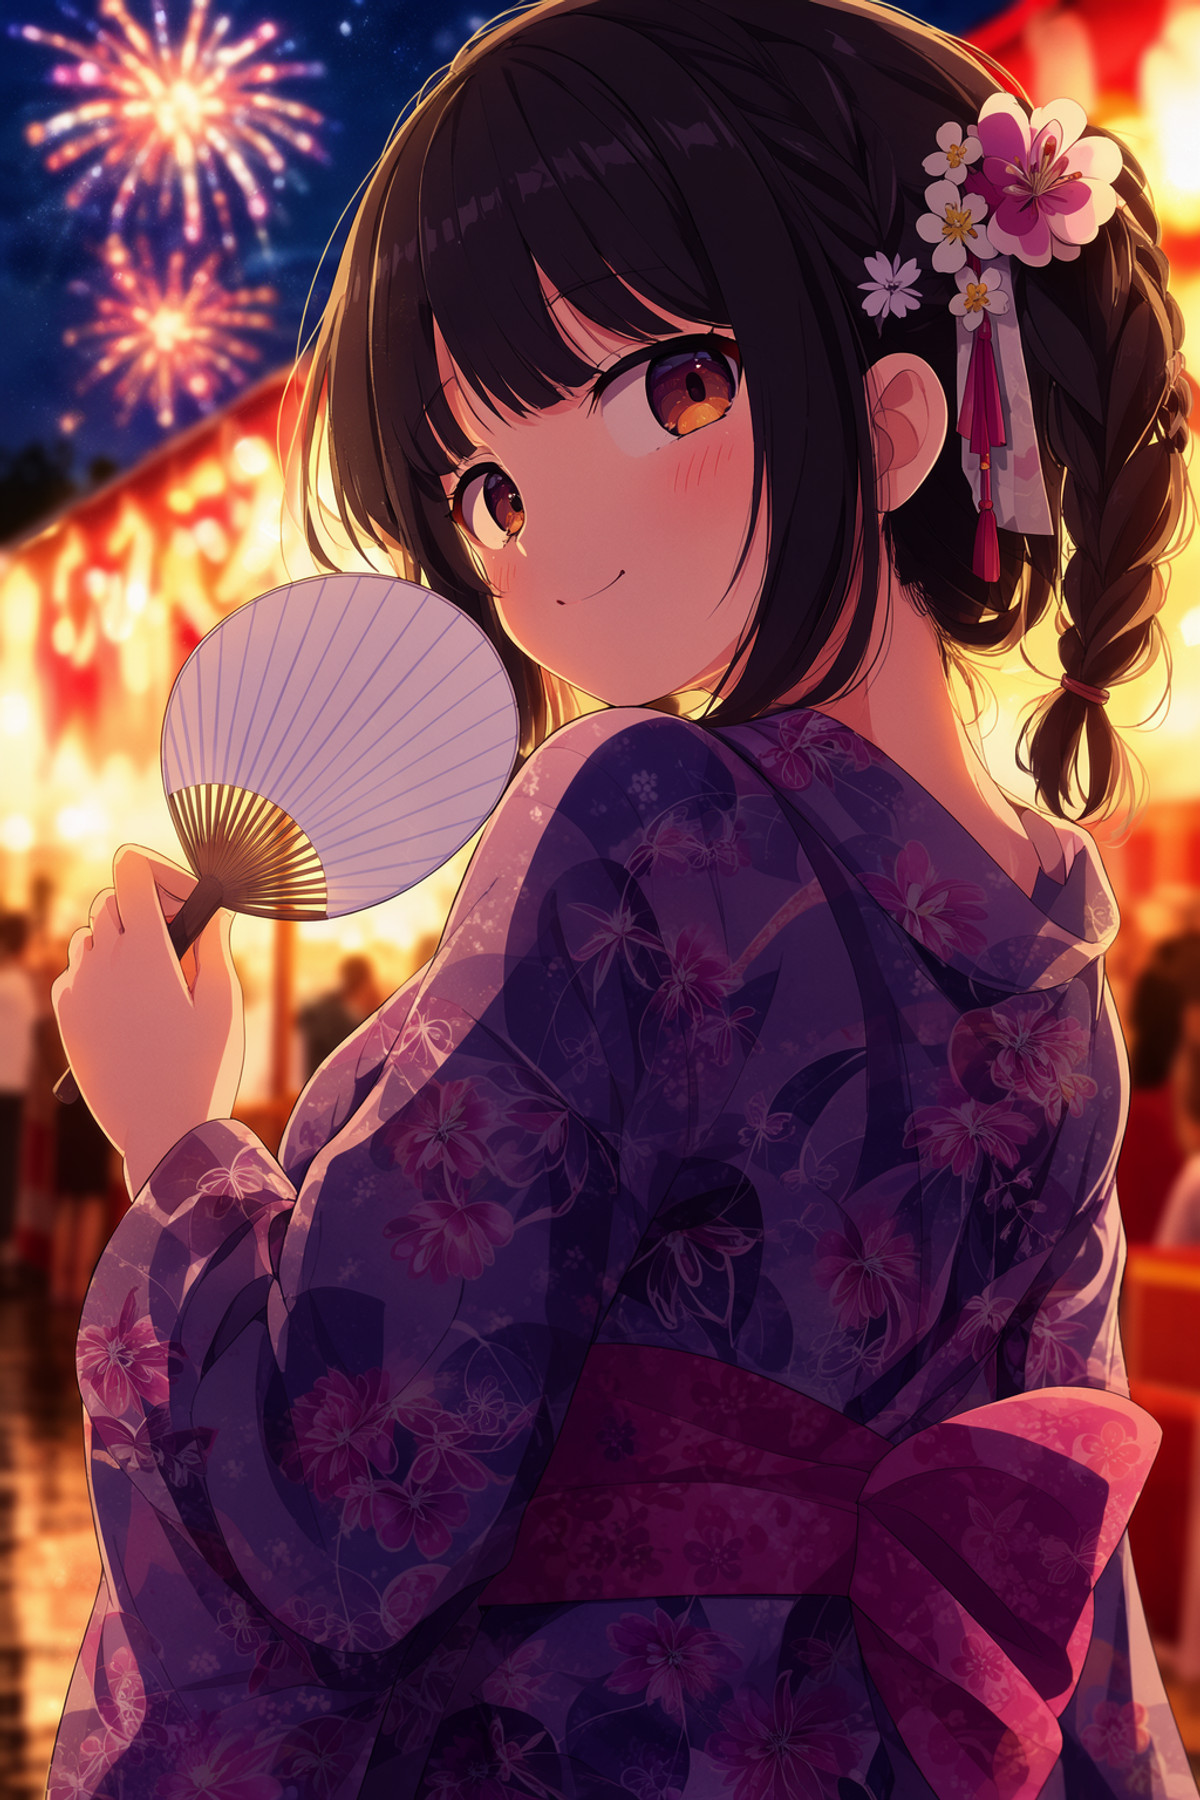
[A] Art Style: shiro9 (Shiro9jira) · v1.0
LoRA · New Model · Author: Suzuka_naoko · Published 11-03 18:29 · Downloads 40
A LoRA imitating the bright, high-light anime style of artist shiro9 (Shiro9jira): bright and transparent color palette, soft light spots and backlighting, round faces and open-mouth smiles; one version includes weights for three training step counts.
Downgraded from S to A: Usage and parameters are the most detailed in this group, and training insights are rare; downgraded one tier because it imitates a specific artist, requiring users to manage commercial and attribution issues themselves.
Images
Reasons for Recommendation
- New model: The author states training was performed on MOSS-Image Base using 120 curated images, with annotations mixing Chinese/English tags and Chinese/English natural sentences, so English tags, Chinese tags, English sentences, and Chinese sentences are all supported.
- Serves cute-themed anime illustrations (author cites examples like beast-ear girls, frilly clothing); provides two complete parameter sets (non-accelerated and DMD-accelerated), along with one example prompt each in Chinese and English.
- Three files correspond to three tiers: s6000 is brightest and most saturated, s7000 is most balanced and prompt-adherent (author recommended), s8000 has the strongest style but is darker and cooler; the model card also includes tier-by-tier comparisons and training insights stating "learning each image 100–120 times is optimal, 130–140 times is the upper limit," which is valuable for those training their own MOSS style LoRAs.
- Free; 40 downloads within 3 hours of release (indicating attention level only).
How to Use
- When downloading, choose shiro9_v1_s7000.safetensors (189 MB, the author's recommended version); the default main file on the page is s6000, which is not the recommended version
- Write "shiro9" at the very beginning of the prompt; for Chinese sentences, start with "shiro9 art style."; strength 1.0, adjustable between 0.8 and 1.2
- Without acceleration: 40-50 steps, CFG 3, euler / simple, shift 5; when stacking a DMD acceleration LoRA for 8 steps: 12 steps, CFG 1, euler / simple; if the art style is diluted, strength can be increased to 1.2
- Resolution approx. 1MP, e.g., 1024×1536, 832×1216; for stronger light effects, add lens flare, light particles, bloom
Risks and Limitations
- Mimicking a specific artist's style: The author states it is unofficial, prohibits impersonating the artist and commercial use, but the Civitai license section allows selling; these two are contradictory, so interpret according to the author's statement
- The trigger word is not registered in the version field, only written in the description
- Only 3 visible examples (the author states the first one is a comparison chart across versions), 1 sensitive-level examples are hidden; this entry has not been run
[A] Luminous Reverie · v1.0
LoRA · New Model · Author oreolove · Published 11-03 12:40 · Downloads 109
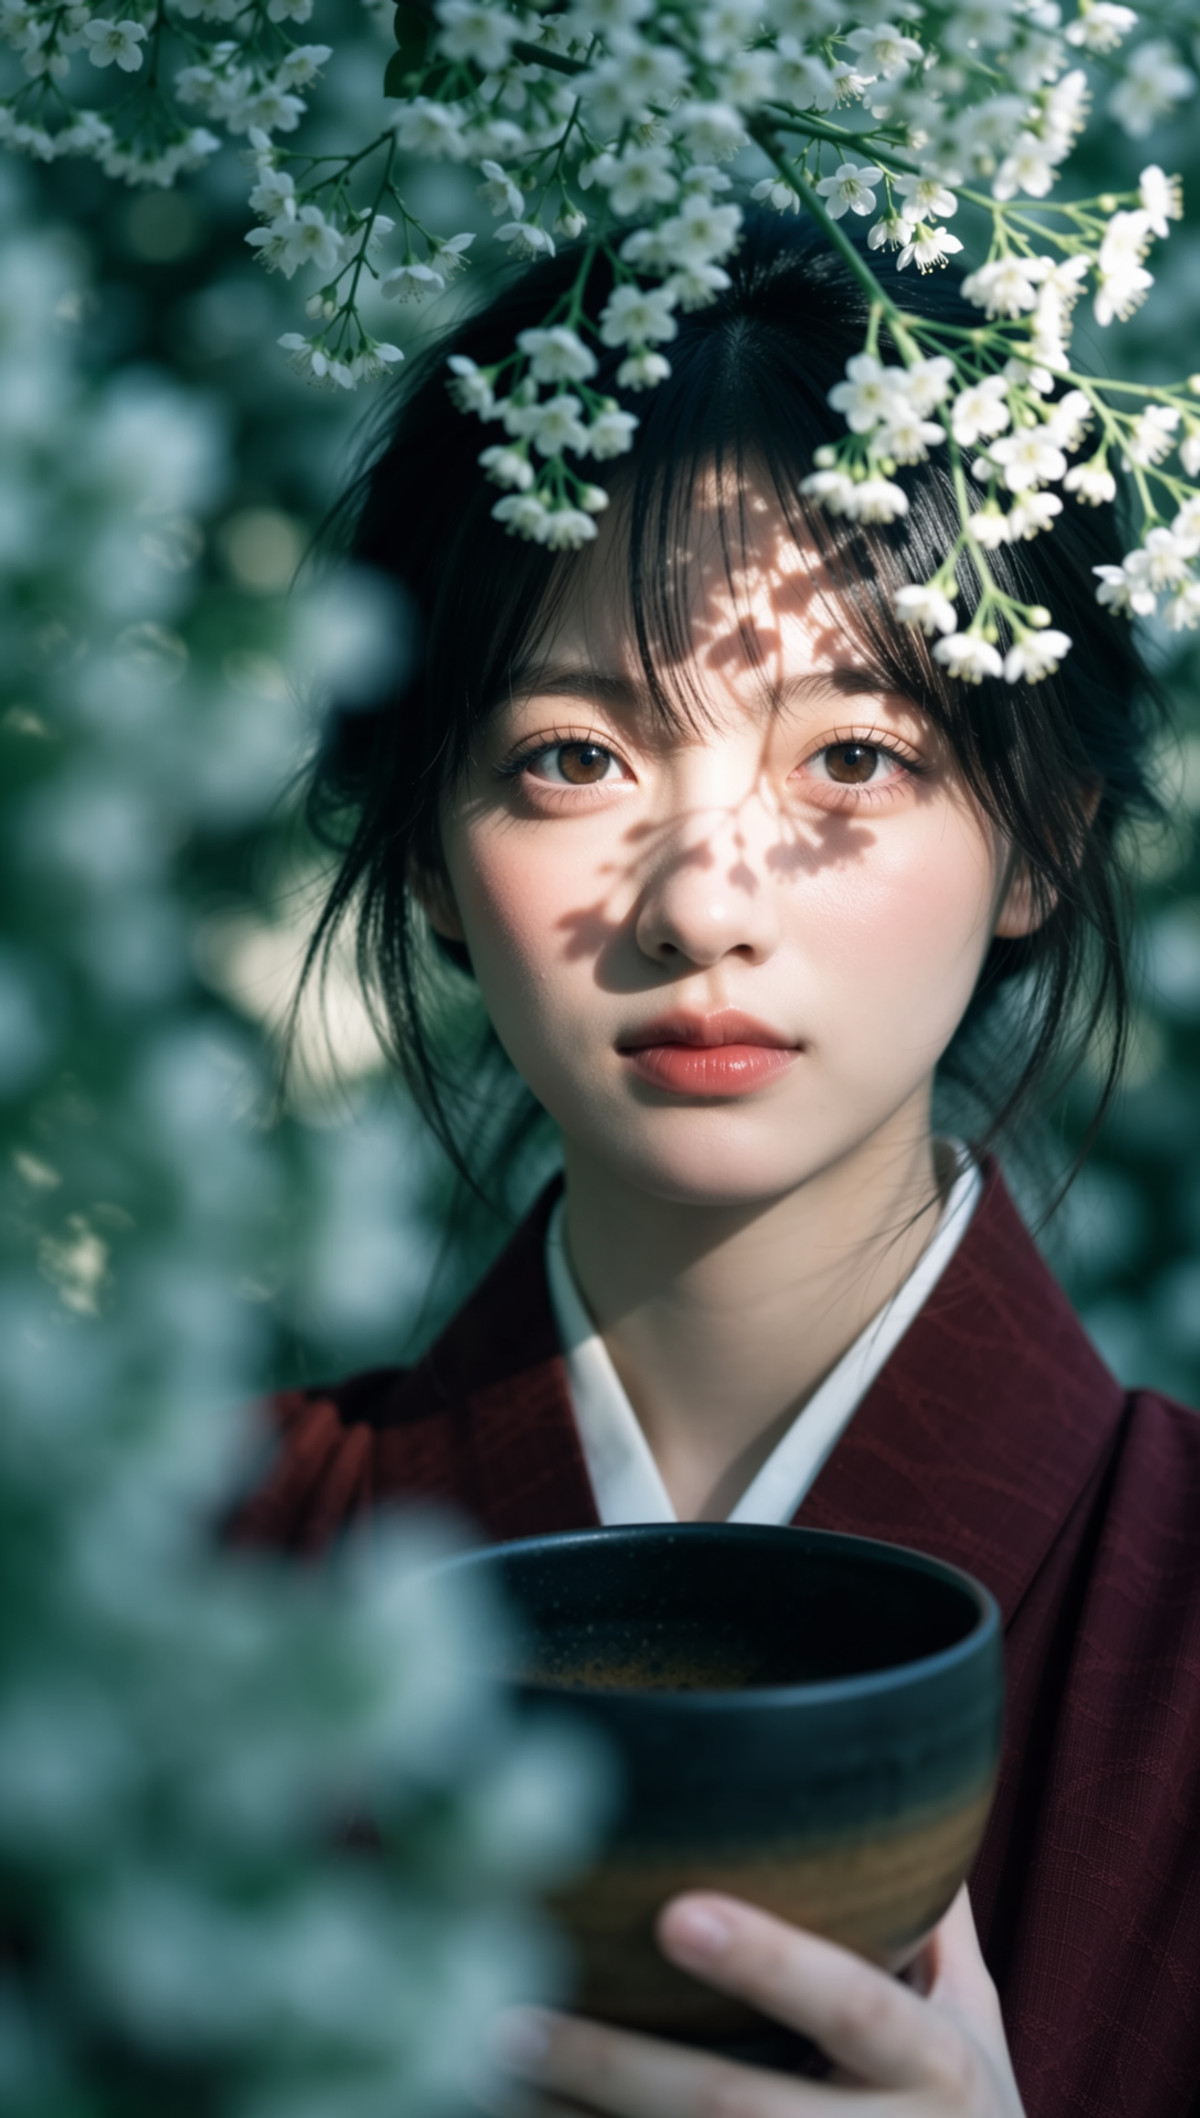
A realistic female portrait style LoRA: Based on natural photography, leaning towards soft lighting and shadows, facial texture, and hair details, targeting window light portraits, everyday portraits, street night scenes, travel, and ancient-style portraits.
Maintained at A (automatically downgraded from S): Usage is clear, strength and steps are provided, but CFG / sampler are missing, and examples rely on an undisclosed merged base model.
Images
Reasons for Recommendation
- New model: The author states the focus is on facial texture, hair details, and the natural relationship between characters and environmental light; the style positioning is delicate and soft, balancing a sense of daily life
- Serves text-to-image realistic portraits: The author explicitly mentions scenarios such as indoor window light, everyday street photography, night scenes, travel photos, and ancient-style portraits
- Provides strength and generation conditions for example images (merged model + four-step LoRA, 8 steps, strength 0.8); free, license allows outputting images, renting, selling, and selling merges
- Published 8 hours ago with 109 downloads, making it the highest download count in this group (only indicates attention level)
How to Use
- Load Luminous Reverie.safetensors, strength 0.8, adjustable according to workflow; no trigger word, use natural language to describe characters, lighting, and scenes
- Author's example images: 50% / 50% merged model + four-step acceleration LoRA, 8 step sampling
- CFG, sampler not provided by the author
Risks and Limitations
- Example images use a 50/50 merged model; the author did not specify which two base models were merged, so outputting directly with the original MOSS may differ from the examples
- Only 3 visible examples, 2 sensitive-level examples are hidden
- Realistic portrait LoRA, training image sources are not stated; caution is needed when involving real person portraits; this entry has not been run
[A] Dark Fantasy Style - MOSS-Image · v1
LoRA · New Model · Author JamesKim97 · Published 11-03 18:00 · Downloads 29
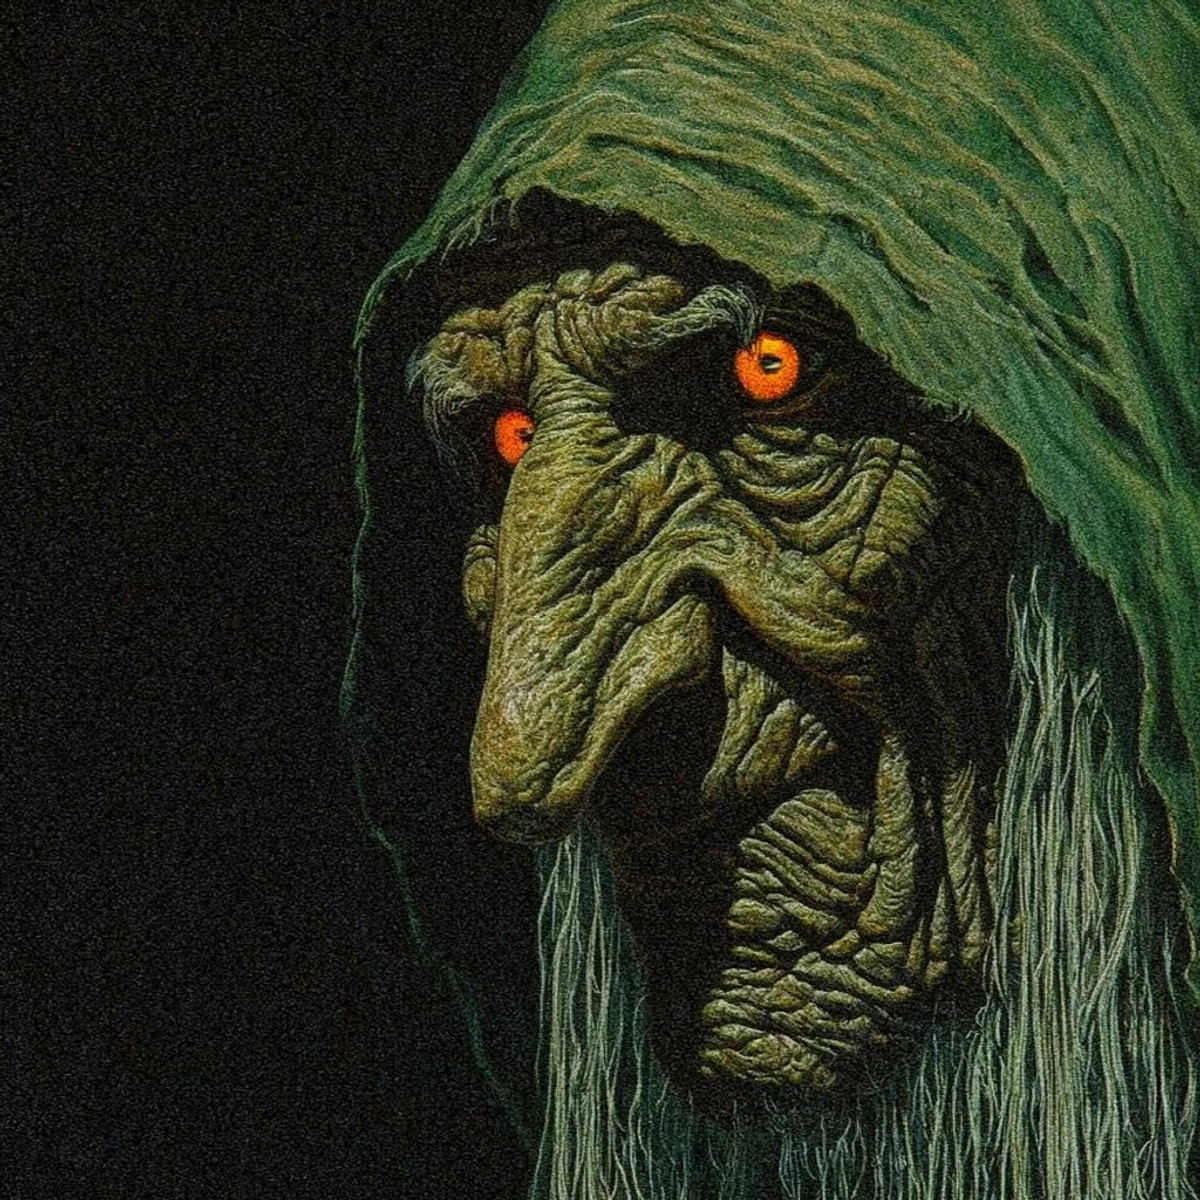
Dark fantasy art style LoRA: Uses the trigger word darkfantasystyle to pull the image towards a gloomy dark fantasy illustration style.
Images
Reasons for Recommendation
- New model: The author states training images come from dark fantasy images generated by Midjourney v5, used to add a layer of dark fantasy style to MOSS text-to-image
- Serves fantasy characters, monsters, scene concept art, and cover illustrations; the author states it can be attached to any MOSS base model
- Has a registered trigger word; the author recommends pairing with a specified MOSS text-to-image workflow (4 steps Turbo + SeedVR2 upscaling, link in description)
- Free, permissive license, author explicitly says feel free to use; 3 example images
How to Use
- Load darkFantasyStyleMOSS_v1.safetensors, write the trigger word "darkfantasystyle" in the prompt
- The author recommends using workflow https://civitai.com/models/3008600/moss-image-text-to-image-or-4-step-turbo-seedvr2-2x in ComfyUI
- Strength, steps, CFG, sampler not provided by the author
Risks and Limitations
- Training images are generated by Midjourney, so the style is "MJ-style dark fantasy," which may carry MJ's inherent aesthetics
- Only 3 examples, description is very short; strength and cross-base model performance need to be tested yourself; this entry has not been run
Trigger Word: darkfantasystyle
[A] Lada Granta FL [MOSS / Krea 2] · v0.1 MOSS
LoRA · Ported · Author bazya022020810 · Published 11-03 16:00 · Downloads 15
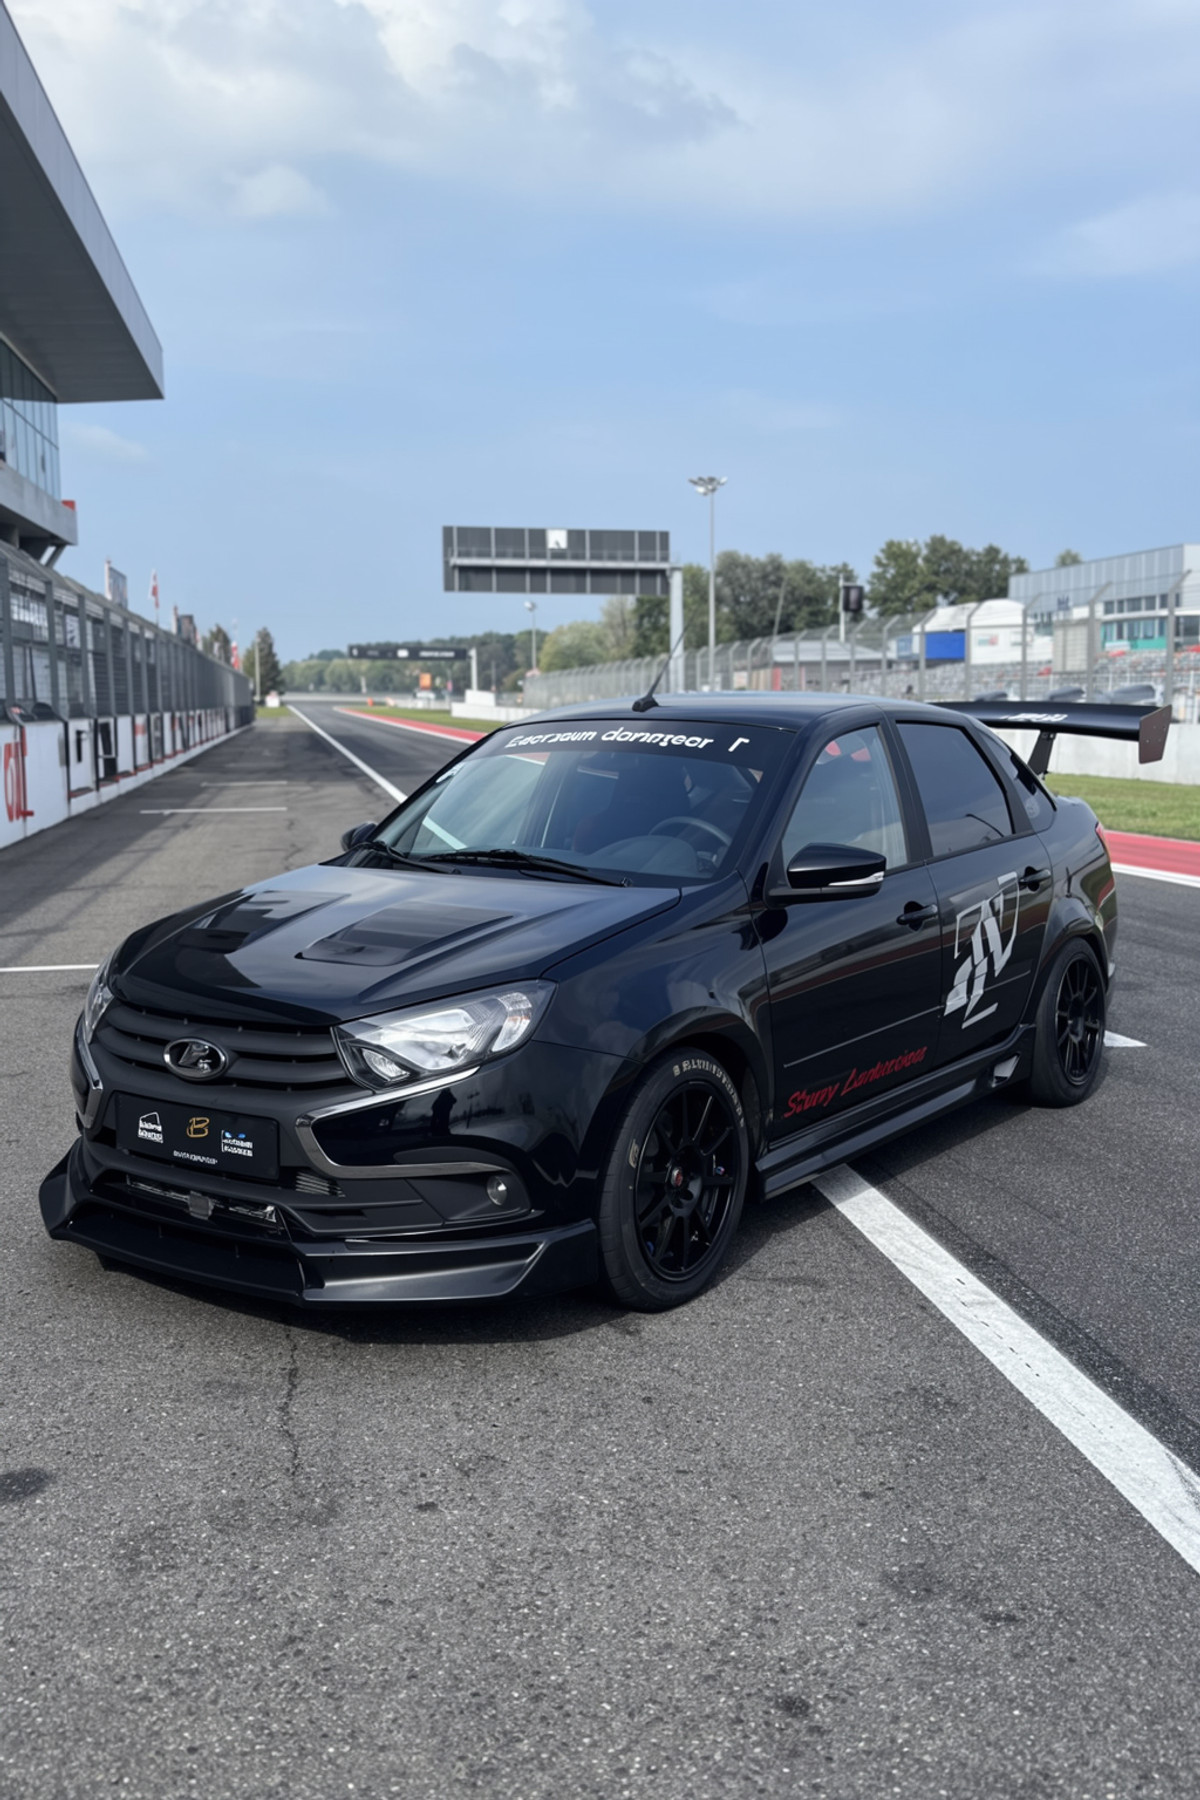
MOSS version of the vehicle LoRA for the Lada Granta FL facelift sedan: Generates this Russian family car; the author states body color, camera angle, and weather can be changed.
Maintained at A: Vehicle / still life LoRAs are rare on MOSS; usage and example prompts are clearly written, but the application scope is narrow.
Images
Reasons for Recommendation
- Ported: The same author first released the Krea 2 Turbo version; the MOSS version description only says "VERSION FOR MOSS Image," without stating the differences between the two versions
- The author states the car model is instantly recognizable, retaining the front X-shaped trim, taillights, and body proportions; color, camera angle, and weather can be changed; serves realistic vehicle scenes like street photography, highways, rain, and gas stations
- Provides weights and two copy-pasteable example prompts (white car daytime front 3/4, black car rainy night street); includes 6 example images; free
How to Use
- Load GRANTFV1m.safetensors, strength 1.0; start the prompt with "granta_fl sedan,"
- The author suggests specifying body color (white color, glossy black paint) and camera angle (front three-quarter view, side profile); the author states it works even without writing the trigger word
- Steps, CFG, sampler not provided by the author
Risks and Limitations
- The author states it is an early beta; interior details may not be accurate
- License does not check commercial use of outputs, does not allow derivatives, and requires attribution; Lada is a car manufacturer trademark
- 1 sensitive-level examples are hidden; this entry has not been run
[A] FFF_MOSS-Alba-style · v2.0
LoRA · Version Update · Author flyfront · Published 11-03 14:58 · Downloads 32
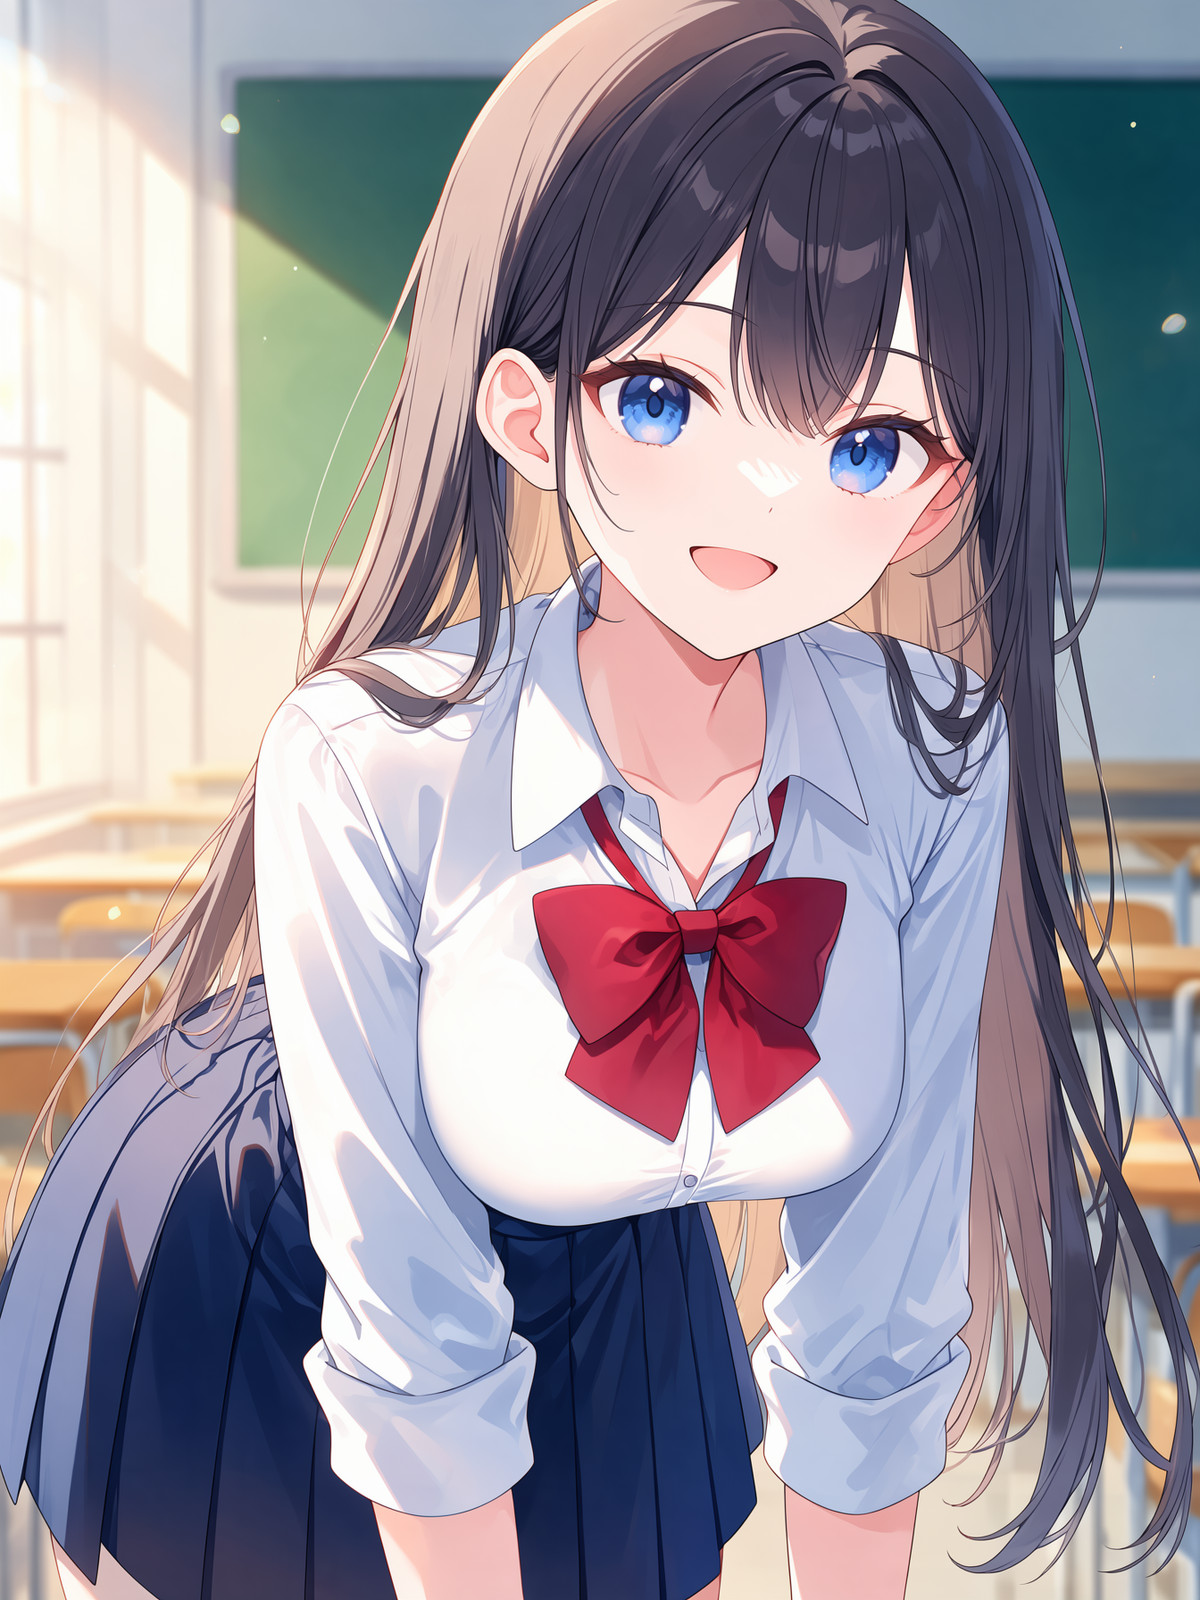
v2 of the FFF_MOSS-Alba art style LoRA: Turns the anime character art style of the author's same-named fine-tuned base model into a LoRA, to be used on other MOSS-Image Base series base models.
Same art style as the newly released full model FFF_MOSS-Alba in two forms: choose the full model if you want to change the base model; choose this LoRA if you want to keep your existing base model.
Images
Reasons for Recommendation
- Version update: v1 was a character LoRA mimicking the FFF_ANIMA-Alba art style; v2 is changed to replicate the art style of the author's newly released FFF_MOSS-Alba full model, for those who don't want to change their base model
- The author states only characters were trained, with backgrounds excluded via masks, so backgrounds retain MOSS-Image's own descriptions
- Parameters are very complete: strength, sampler, steps, scheduler and shift, pixel count, CFG corresponding to two coloring effects, negative prompt additions, can pair with 8/4/2 step distillation LoRA
- Apache License 2.0, same weights as MOSS-Image; free
How to Use
- Recommended MOSS-Image SFT (Base also works) + this LoRA, keep weight at 1.0
- Can add "@fyfnt" at the beginning of the prompt (author states optional; adding it makes eyes larger and closer to the original art style); no quality words or background words needed
- Euler, 25-30 steps, MOSS or Simple scheduler (shift 5); approx. 2.4M pixels any ratio, e.g., 1344x1792, 1536x1536
- CFG 3 produces soft shadows, CFG 5-6 leans towards cel shading; add blush, embarrassed, overexposure to the negative prompt based on common MOSS negatives
- When using distillation LoRA with CFG 1, use NegPiP to write negative weights in the positive prompt
Risks and Limitations
- The model card Quick start still lists v1 filenames, and training data descriptions are also for v1; v2 has only one sentence of update notes, training details not written
- v2 does not have a registered trigger word (@fyfnt was registered in v1); whether it works similarly needs to be confirmed yourself
- Only 2 examples; the author states fingers may be simplified, recommends pairing with hand repair; full negative prompt is on the Hugging Face page; this entry has not been run
[A] MOSS Image — Simple Text2Image (8GB VRAM) · v1.0
Workflow · New Model · Author tinytensor · Published 11-03 19:41 · Downloads 10
A MOSS Image text-to-image ComfyUI workflow with only nine nodes, requiring no custom nodes; the author states it can run on laptops with 8 GB VRAM.
Images
Reasons for Recommendation
- New workflow (not new weights): Serves users with low VRAM who want to get MOSS running first; no LoRA, ControlNet, or third-party nodes needed
- Only three files required: MOSS base int8, Qwen3.5 9B int8 text encoder, flux2-vae; the author wrote which folder each goes in
- The author provided all key parameters, three recommended sizes, Danbooru tag-style prompt templates, and solutions for three common pitfalls (long hems being shortened, hoods being removed, tiny figure erasing characters)
- The author provided time consumption on 8 GB 3070Ti, and the fix for when VAEDecode reports a comfy_kitchen / group_norm_stats3d error
How to Use
- Load mossImageSimple_v10.json in ComfyUI; place models in models/diffusion_models, text_encoders, vae
- Steps 50, CFG 3.0, euler / simple, Shift 5.0; sizes 1024x1408 portrait, 1408x1024 landscape, 1024x1024 square
- Use comma-separated Danbooru tags for prompts: masterpiece, best quality, very aesthetic, safe, 1girl, solo, followed by hairstyle/clothing, pose, camera, scene, lighting
- When VAEDecode errors, upgrade comfy-kitchen to above 0.2.40 in ComfyUI's built-in Python and restart
Risks and Limitations
- The workflow JSON is not a new model; its purpose is to lower the barrier to entry; according to author data, a 8 GB card takes about 150 seconds to generate one portrait image
- Only 1 examples, just published with 10 downloads; this entry has not been run
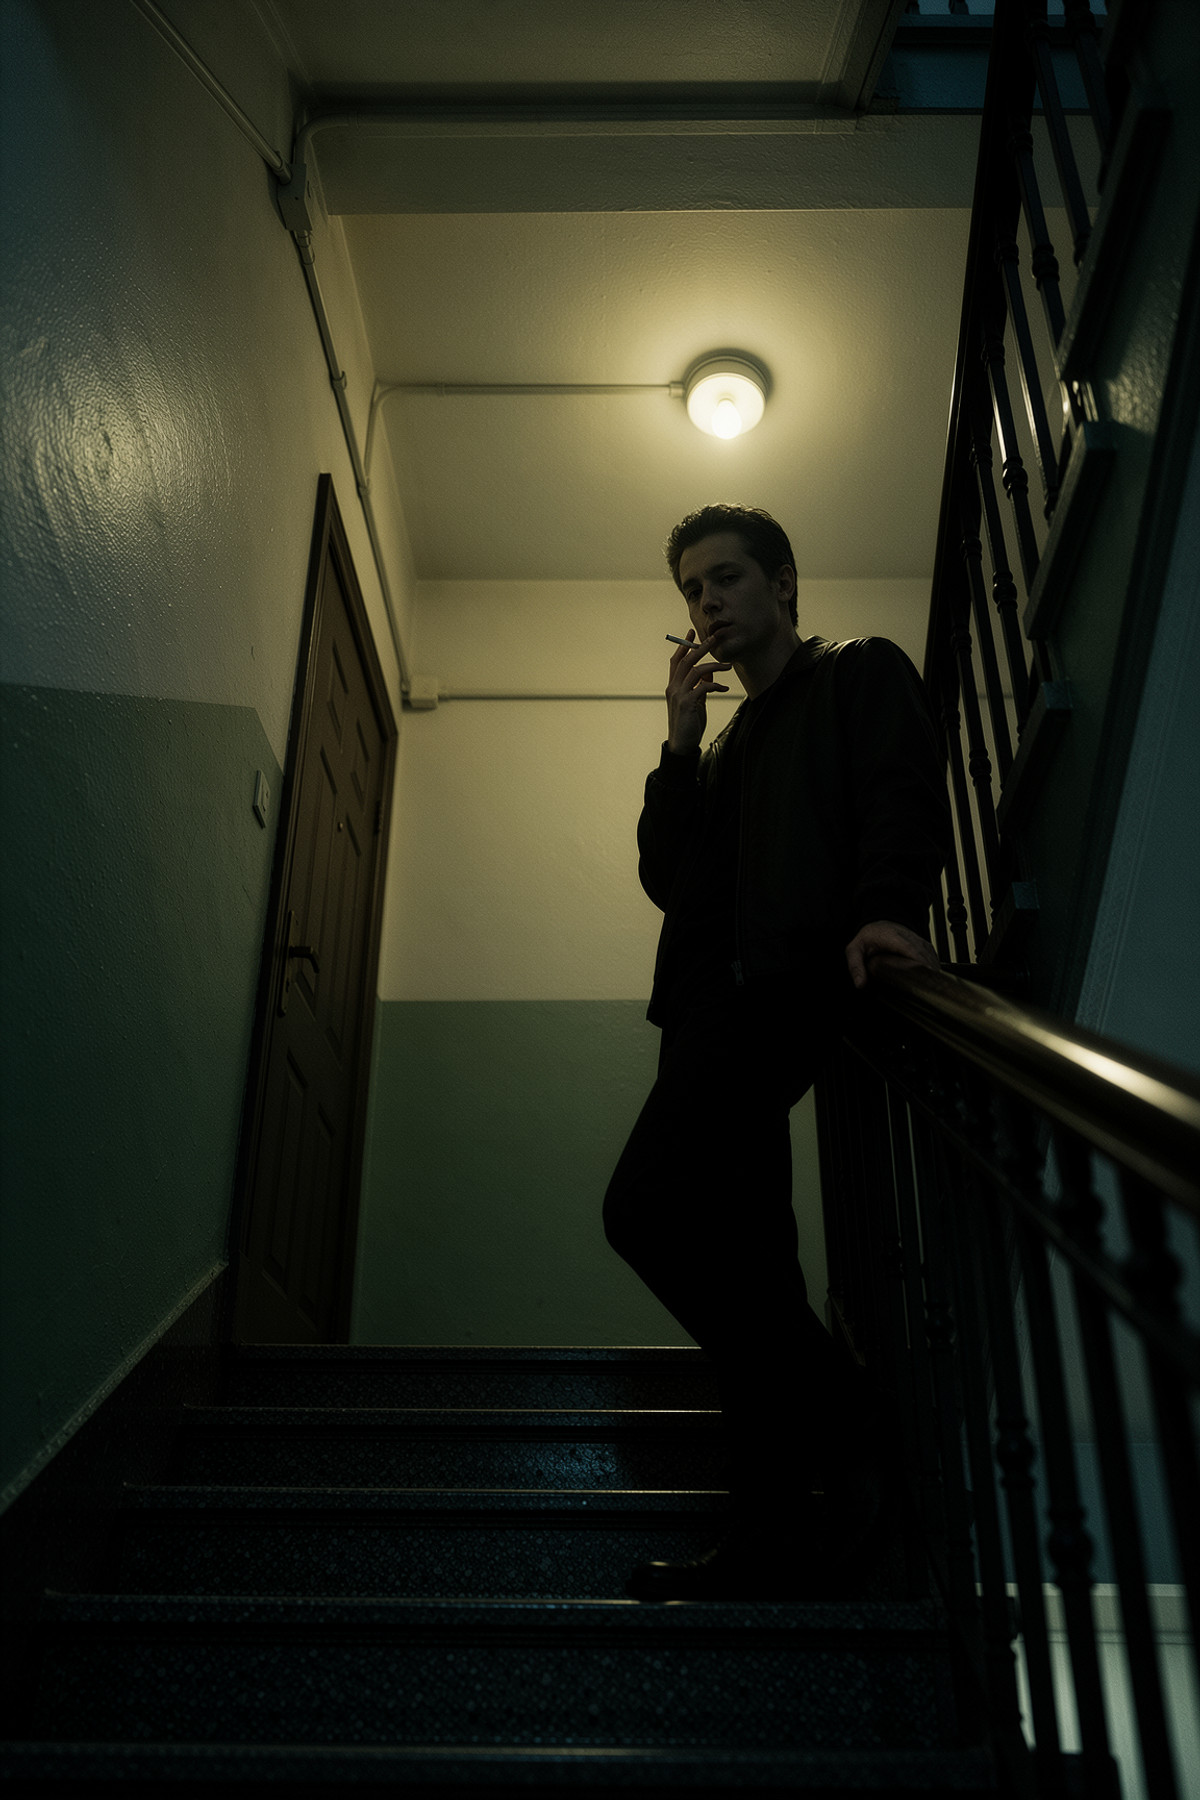
[A] "Joker Style" Olive Cinema Grade — Olive-Gray Tones, Sodium Lamps, Lonely City Nights | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-03 18:56 · Downloads 23
"Joker" style olive-gray cinematic color grading LoRA: Compresses the image into olive gray and dark green, with sodium lamp and fluorescent lighting, crushed blacks, grainy, creating lonely and dilapidated city night scenes.
Images
Reasons for Recommendation
- New model: Serves cinematic night scenes with a movie still aesthetic in text-to-image generation; the author states it works best when the subject is close to the camera and illuminated by only one actual light source.
- Specific prompt writing style: Start with the trigger word, set strength to 0.5, and specify a particular lamp (sodium lamp, wall sconce, fridge light) as the sole light source.
- The author advises avoiding sign text in the image, otherwise the trigger word might appear within the scene.
- Free, permissive license; 4 visible examples available.
How to Use
- Load olivecinemastyle.safetensors with strength 0.5, and start the prompt with "olivecinemastyle" (the trigger word is not registered in the model page metadata, but is mentioned in the description).
- Specify a concrete light source as the sole illumination in the prompt, such as sodium lamp, wall sconce, or fridge light.
- Steps, CFG, and sampler are not provided by the author.
Risks and Limitations
- The trigger word is not registered in the version information and must be copied from the description; if signs appear in the image, the trigger word might be rendered as text.
- 14 sensitive-level examples are hidden, far more than the 4 visible examples; this entry has not been tested.
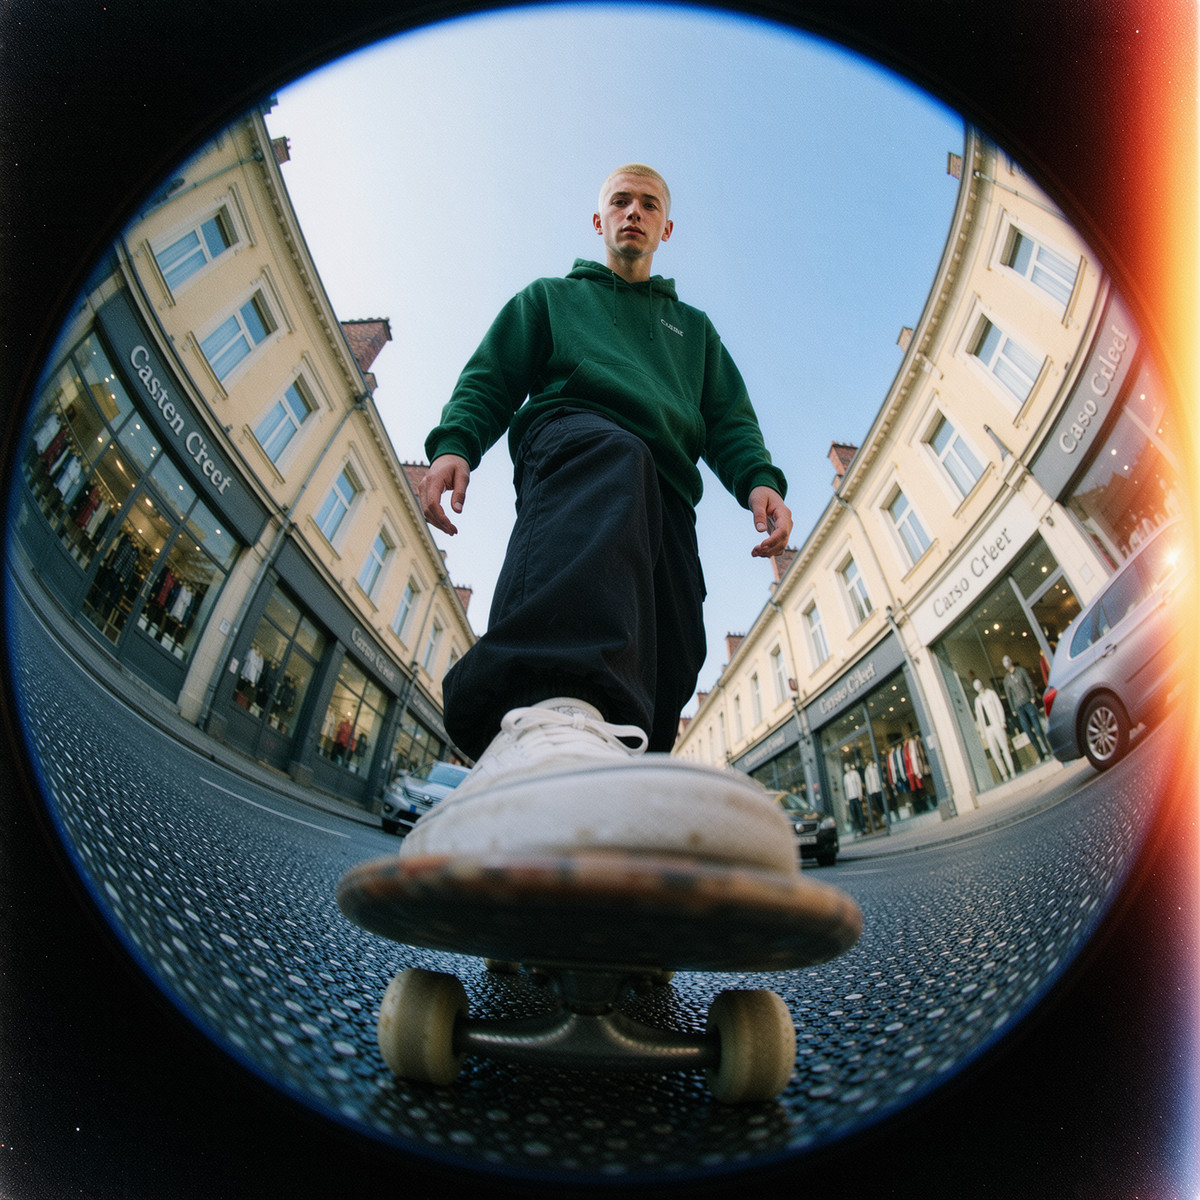
[A] Lomo Fisheye Film — Circular Black Border, Giant Foreground, Light Leaks | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-03 18:51 · Downloads 41
A LoRA for Lomo fisheye film camera effects: the image is framed within a thick black circular border, objects closest to the lens are exaggeratedly enlarged by the fisheye distortion while the background curves outward, accompanied by heavy grain, cross-processing color shifts, slight soft focus, orange-red light leaks on one side, and chromatic aberration at high-contrast edges.
Maintained as A: The effect description is specific and the writing style is clear; it is the most novel entry in this group. Parameters are missing, so strength needs to be determined manually.
Images
Reasons for Recommendation
- New capability: Not a subject or art style, but an imaging effect combining "lens distortion + film artifacts"; the author claims it can be applied to any subject.
- Serves portraits, street scenes, and object images requiring exaggerated foreground perspective and a retro film feel; the key to prompting is to first describe the object closest to the lens that should be enlarged—the author's original words are "the stretching effect is the point."
- Free, license allows selling and merging; published about 2 hours ago with 41 downloads (indicating attention only).
How to Use
- Load lomofisheye.safetensors (142 MB · FP16), start the prompt with "lomofisheye,", then describe the object closest to the lens that should be enlarged, followed by the subject and scene.
- Example images are 1408x1408 square; strength, steps, CFG, and sampler are not provided by the author.
Risks and Limitations
- The trigger word is only written in the description and not registered in the version fields.
- 15 sensitive-level examples are hidden, far more than the 4 visible examples.
- No parameters are provided, and the description consists of only two paragraphs; this entry has not been tested.
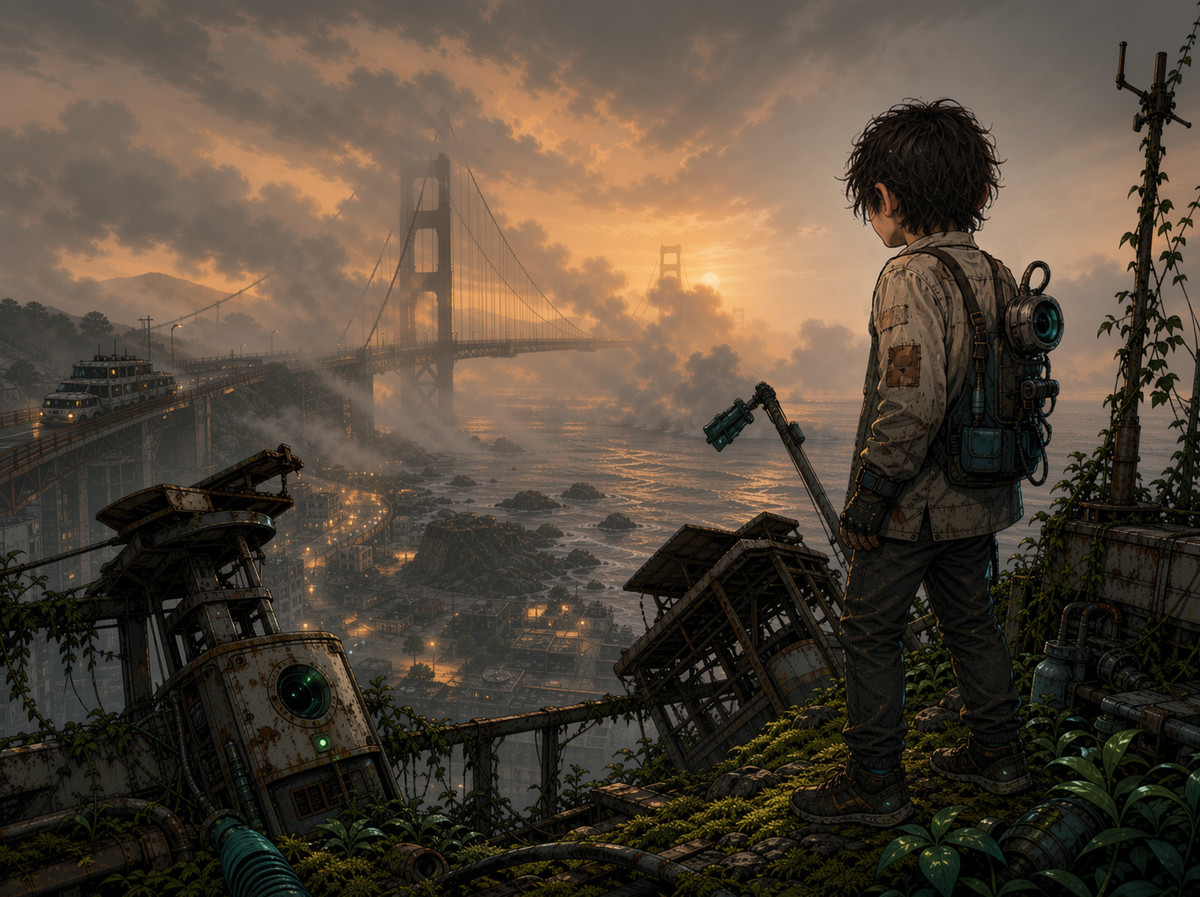
[A] Suideo's Graphic Novel Style for Moss · v1.0
LoRA · New Model · Author redhotcherrypop · Published 11-03 10:40 · Downloads 56
A LoRA for a modern graphic novel art style with rough ink sketch lines, requiring no trigger word.
Automatically upgraded from B to A: The style direction is clear, examples are provided, and trigger word options and strength limits are given; only sampling parameters are missing.
Images
Reasons for Recommendation
- New model: Serves comic storyboards, graphic novel illustrations, and character images with an ink line aesthetic.
- The author states no trigger word is needed, but adding "kafkaeffect4" or "graphic novel artstyle" can strengthen the style.
- The author claims strength can be adjusted freely, but it breaks down above 1.6, and degrades earlier when more models are stacked.
- Free, permissive license; 4 visible examples available.
How to Use
- Load MOSS_kafkaeffect4_000004250.safetensors, no trigger word required; to strengthen the effect, write "kafkaeffect4" or "graphic novel artstyle".
- Keep strength below 1.6, and lower it further when stacking other LoRAs; steps, CFG, and sampler are not provided by the author.
Risks and Limitations
- The description consists of only three sentences, with no sampling parameters or applicable base models (Base / SFT) provided.
- The weight file is approximately 567 MB, larger than common style LoRAs; 3 sensitive-level examples are hidden; this entry has not been tested.
Worth Watching (9)
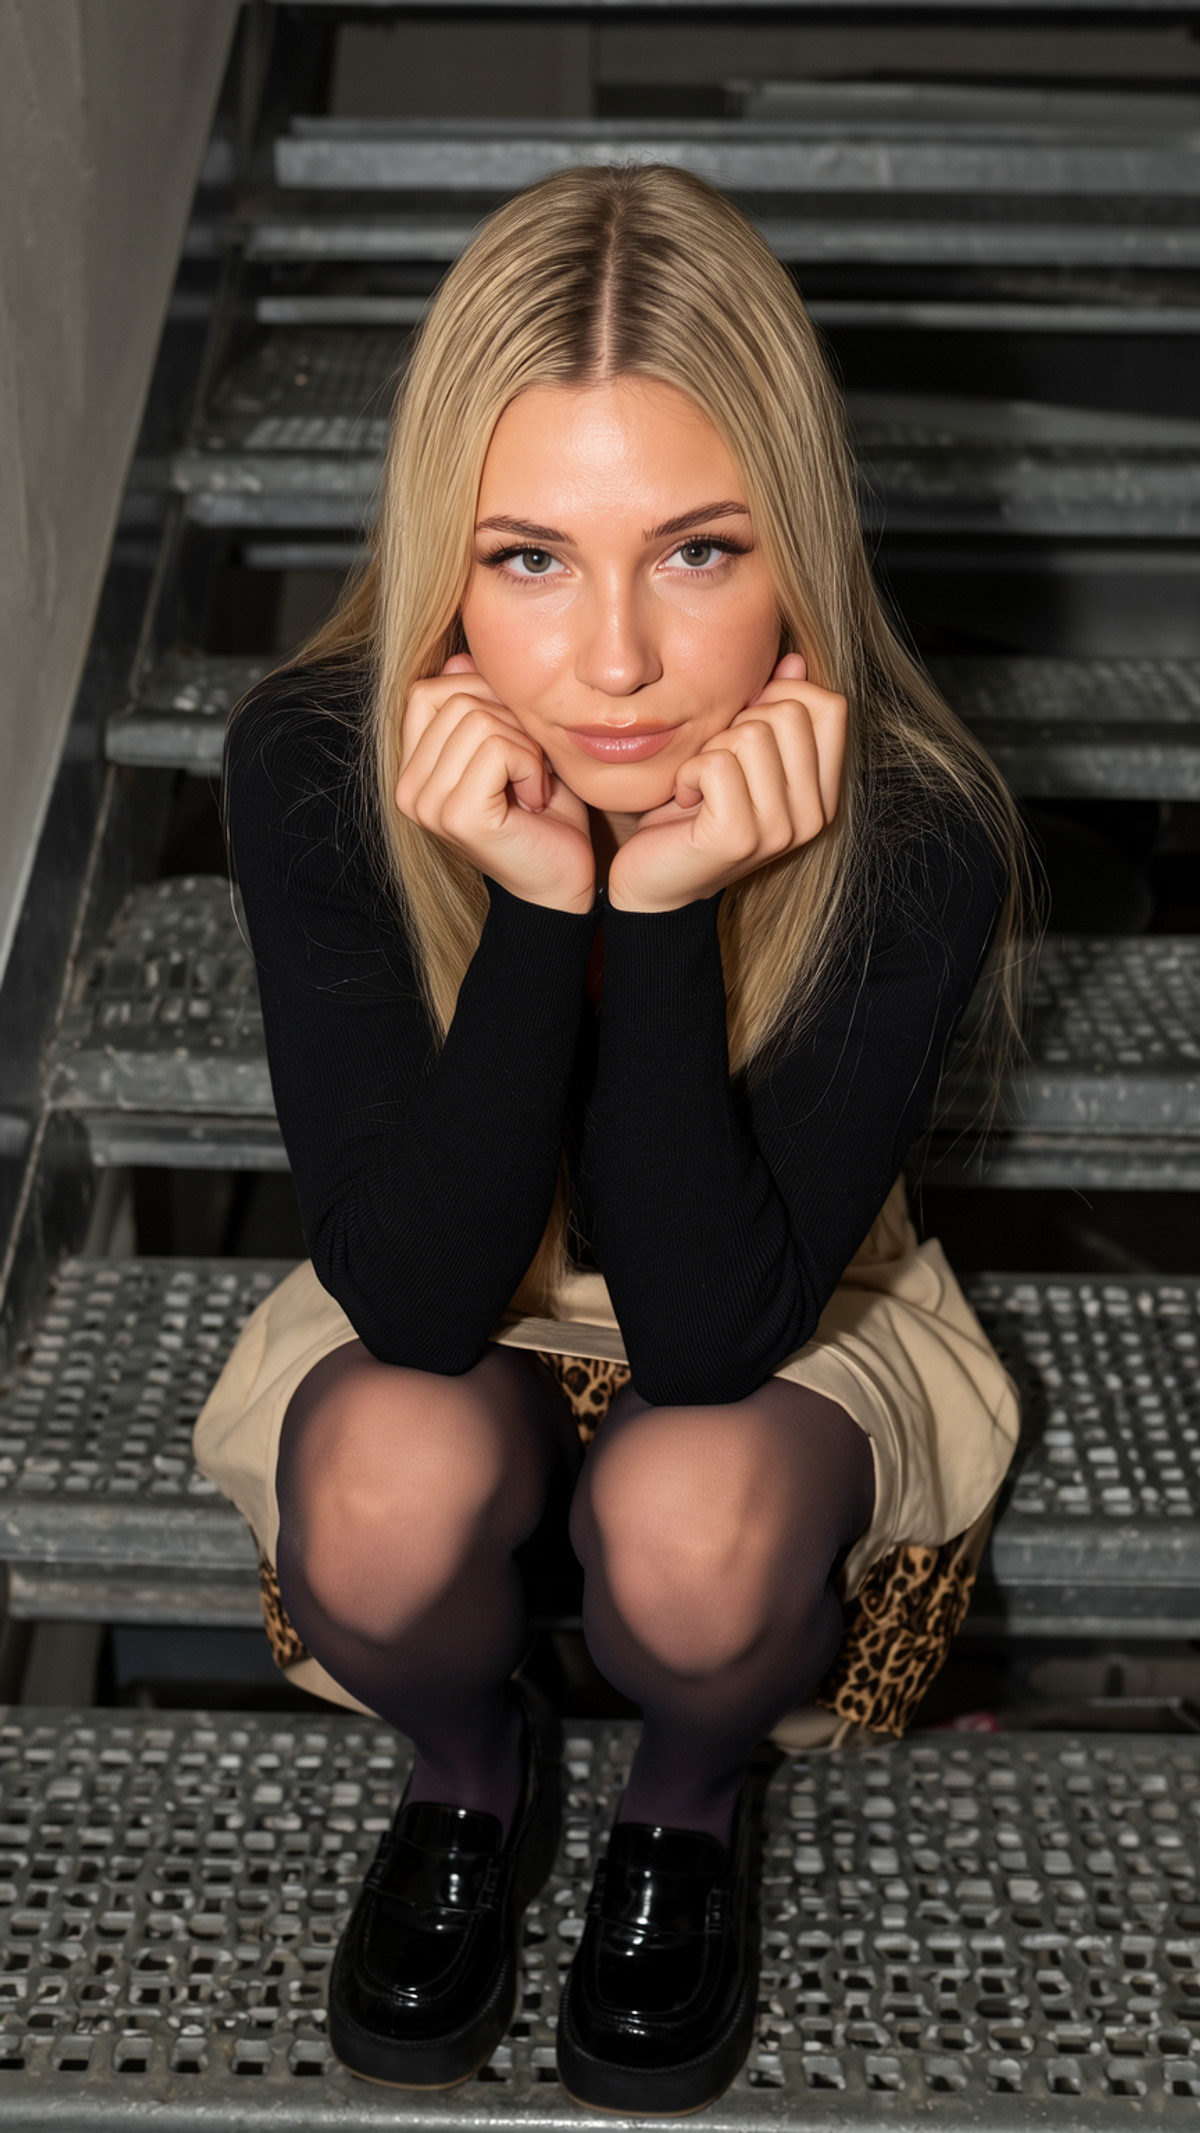
[B] moss image super realistic · v2.0
LoRA · Version Update · Author mytheron · Published 11-03 14:11 · Downloads 161
Version 2 of the MOSS Image photorealistic style LoRA, focusing on daily scenes, lifestyle photos, and selfie-style portraits.
Images
[B] MOSS-FET · v0.3
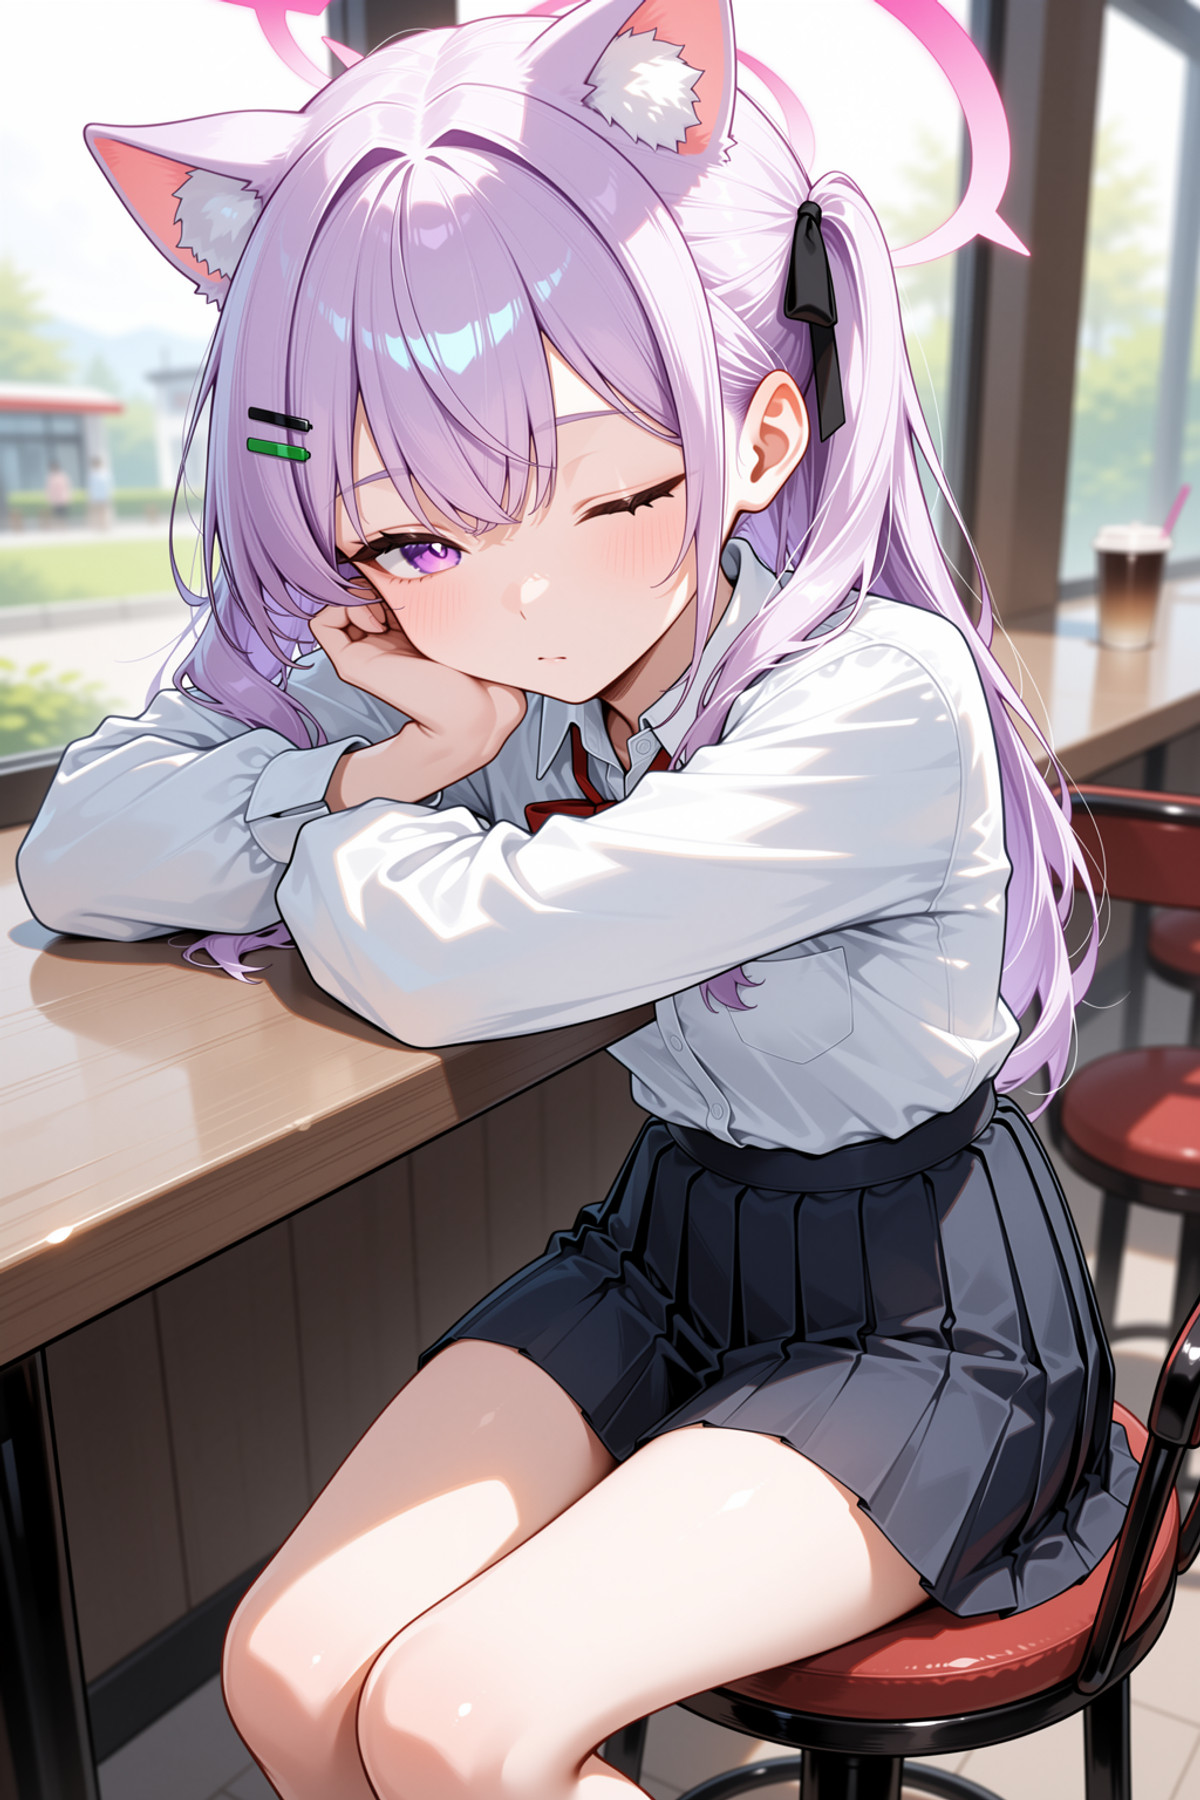
Base Model / Checkpoint · Version Update · Author aueki4g467 · Published 11-03 20:42 · Downloads 11
The third version of an experimental base model where the author performed full fine-tuning on MOSS using the Fizgig tool: v0.3 is a standard anime-style character base model.
Images
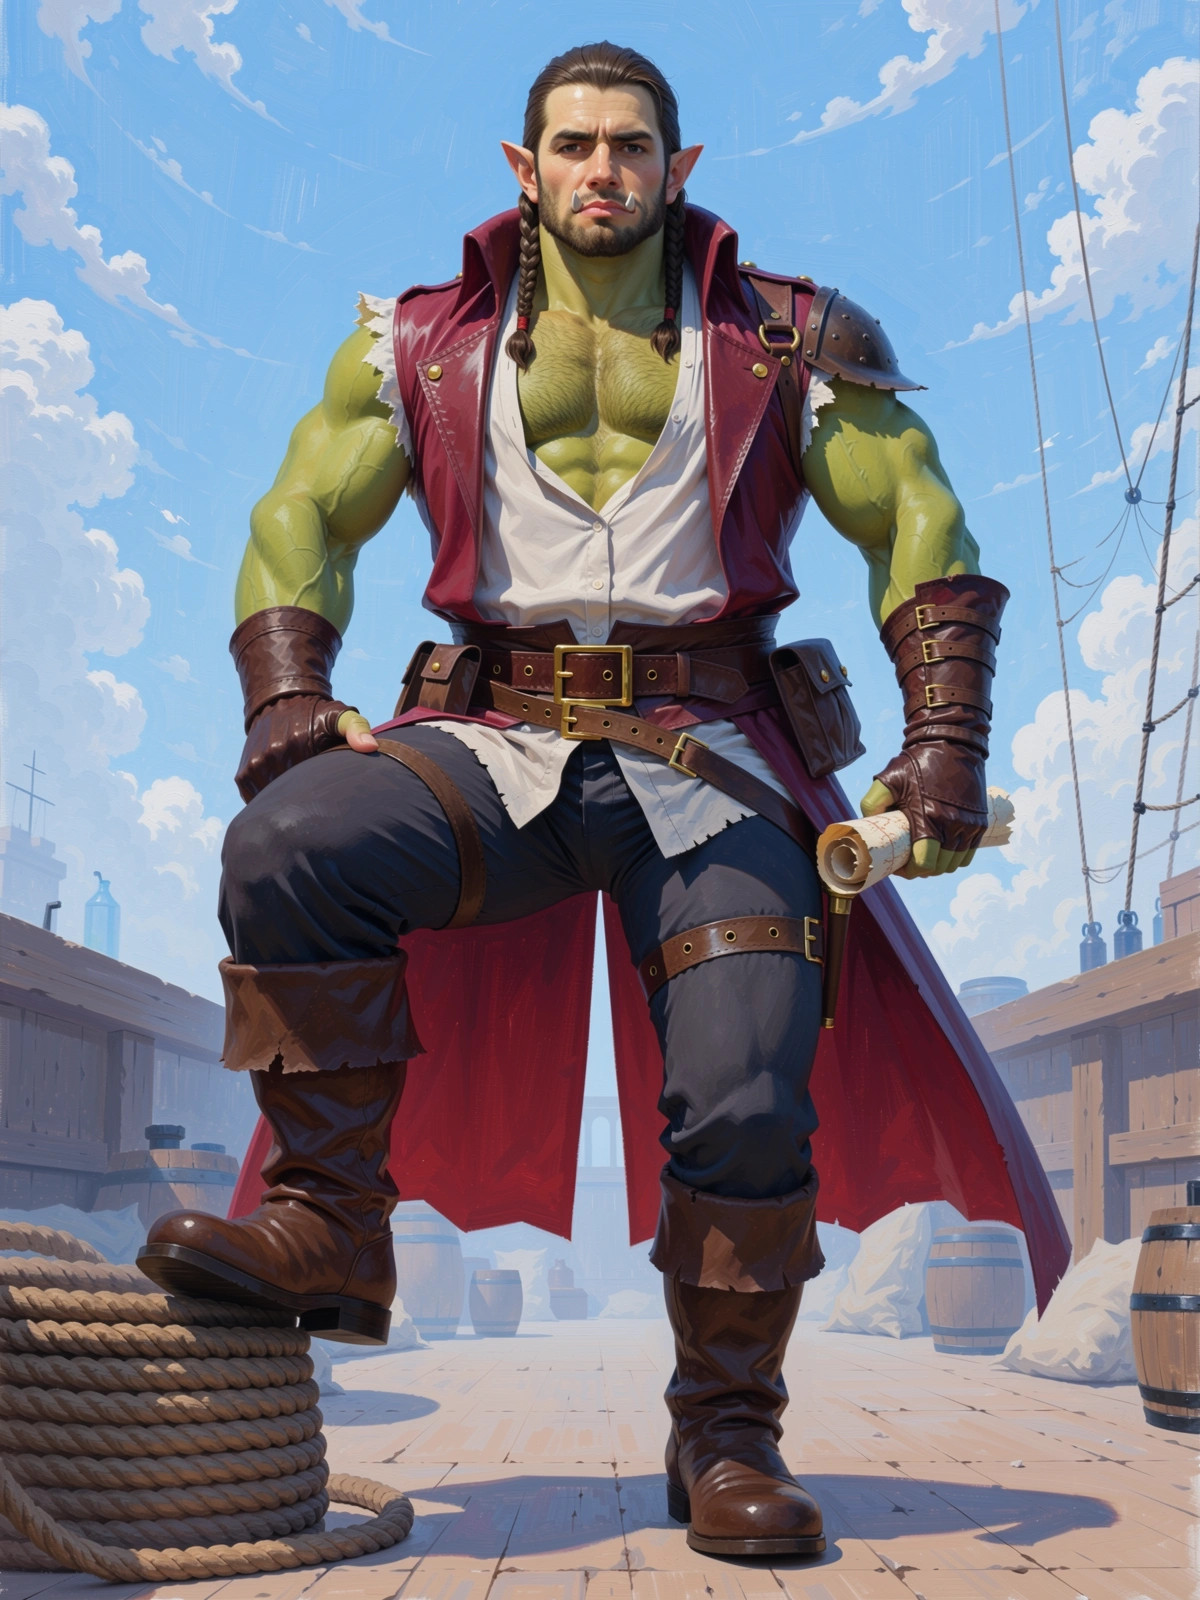
[B] MOSS HD Digital Painting · v1.0
LoRA · New Model · Author _Envy_ · Published 11-03 12:27 · Downloads 76
A LoRA for a sharp-detail digital painting style; the author claims the images will not have a "plastic" look.
Images
[B] Watercolor Painting · MOSS
LoRA · Ported · Author vizsumit · Published 11-03 10:21 · Downloads 41
The MOSS version of a traditional watercolor painting style LoRA, with the trigger word being "watercolor painting".
Images

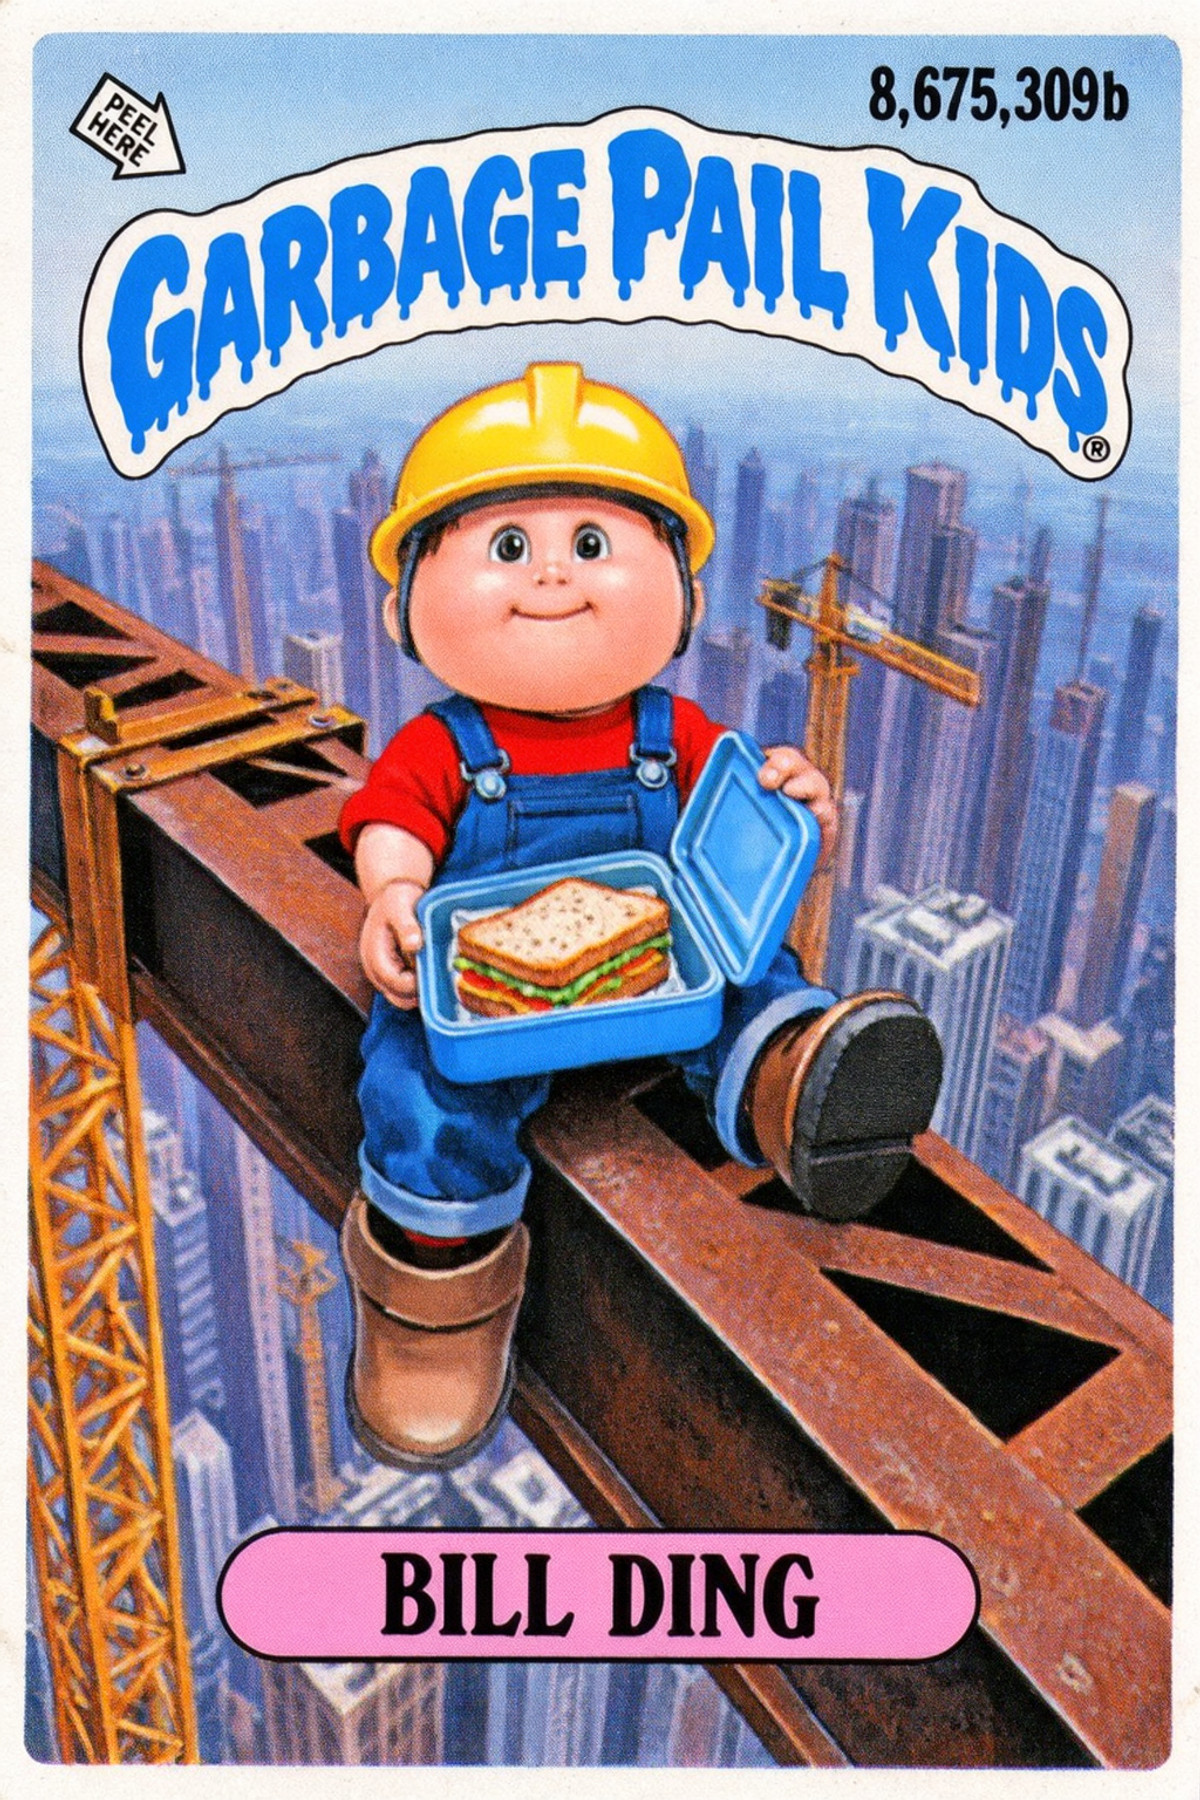
[B] GPK2Card · MOSS
LoRA · New Model · Author FiendishAI · Published 11-03 19:30 · Downloads 16
A LoRA mimicking the layout of parody sticker cards from the 80s (such as "Garbage Pail Kids"): generates collectible cards with quirky characters, card name text, and fixed layouts.
Images
[B] Moss/Anima-Style-Highlight Wet Rendering (nai5qijiu) · Moss-base-V2.0
DoRA · Version Update · Author hardworkingsaltedfish · Published 11-03 16:21 · Downloads 82
The MOSS Base V2 version of a DoRA for anime-style wet highlight skin rendering: features oily, reflective skin, sharp eyeliner and eyeshadow, and curvy character figures; training materials were sourced from nai5 outputs.
Images
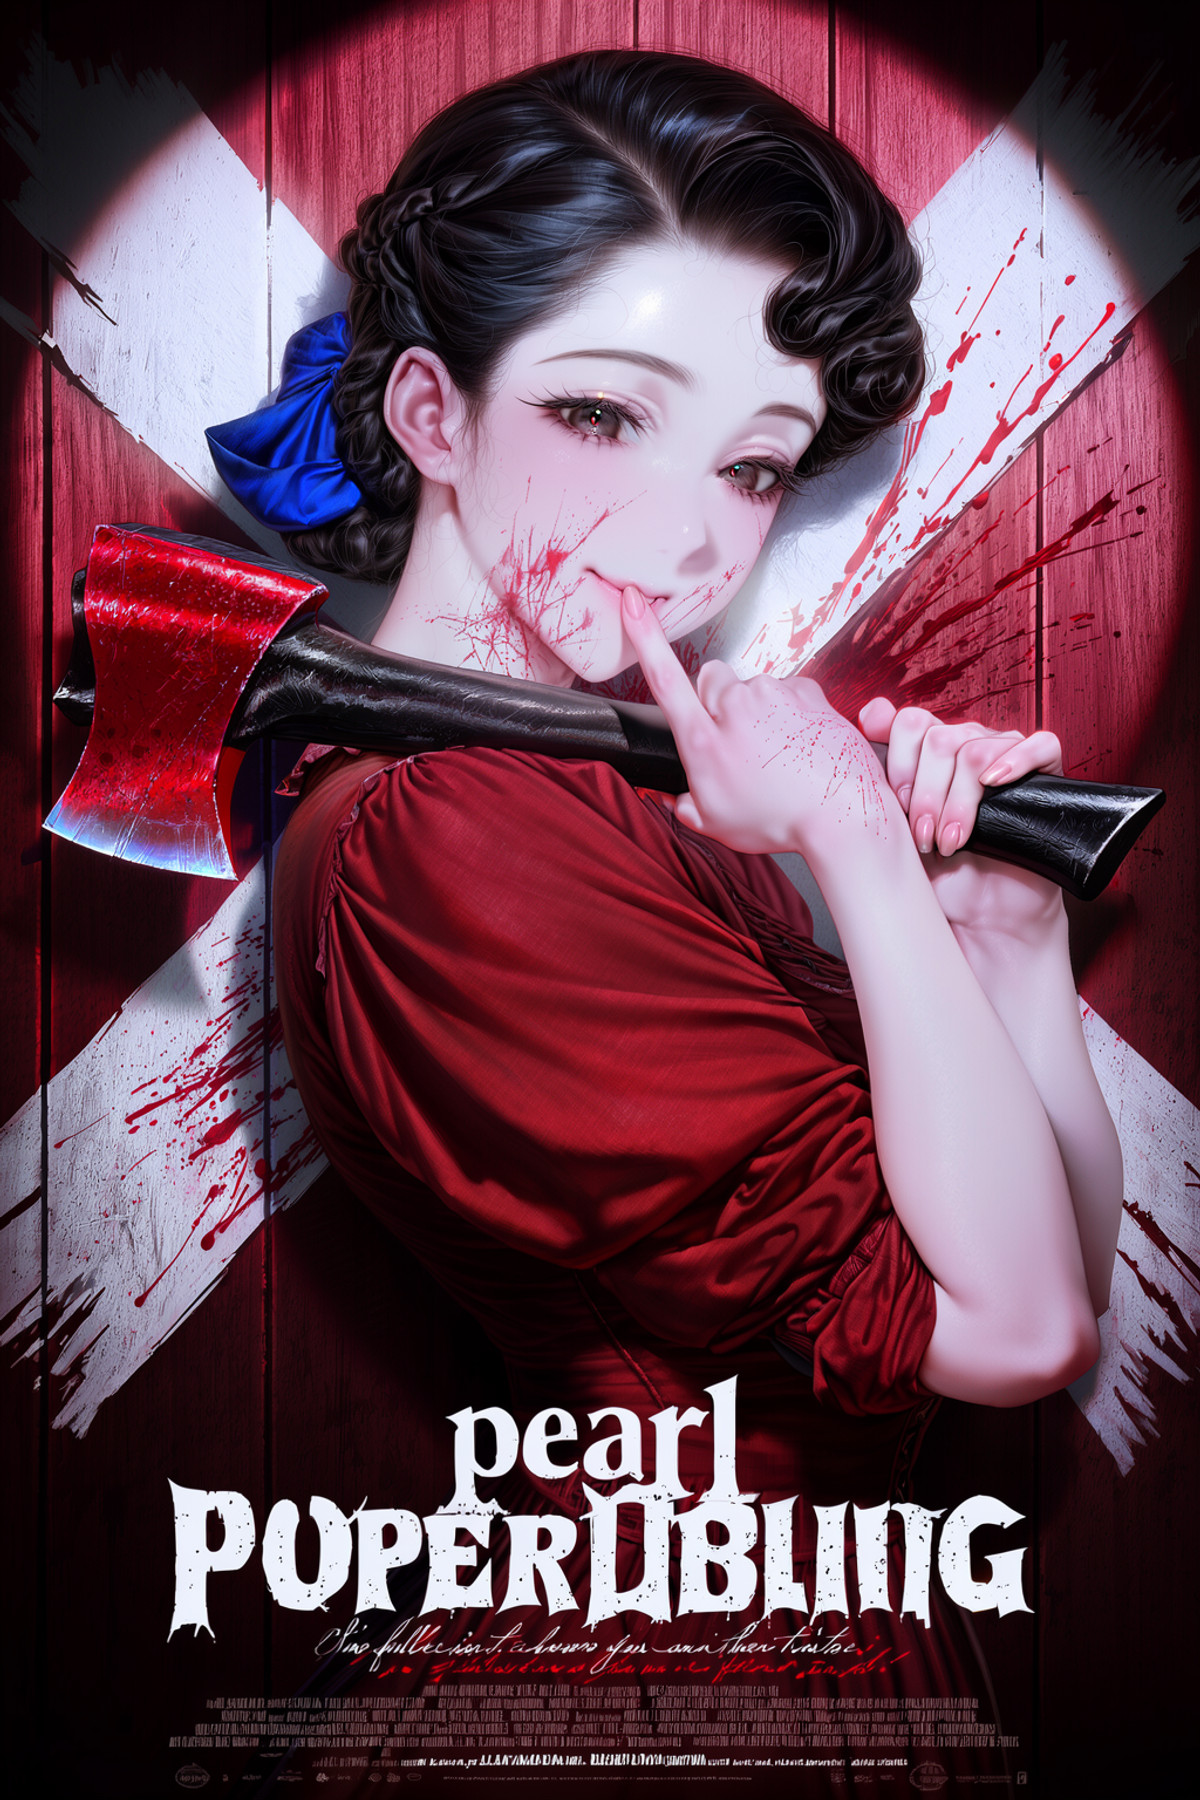
[B] Amish Barn — Straw Hats, Suspenders, Light Through the Boards, Hay and Buggies | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-03 19:04 · Downloads 31
A LoRA for Pennsylvania Amish farm scenes: old wooden barns, hay, buggies, and pastures, along with attire such as straw hats, suspenders, plain long dresses, and white prayer caps; the author claims beams of light shining through the gaps in the wooden boards produce the best effect.
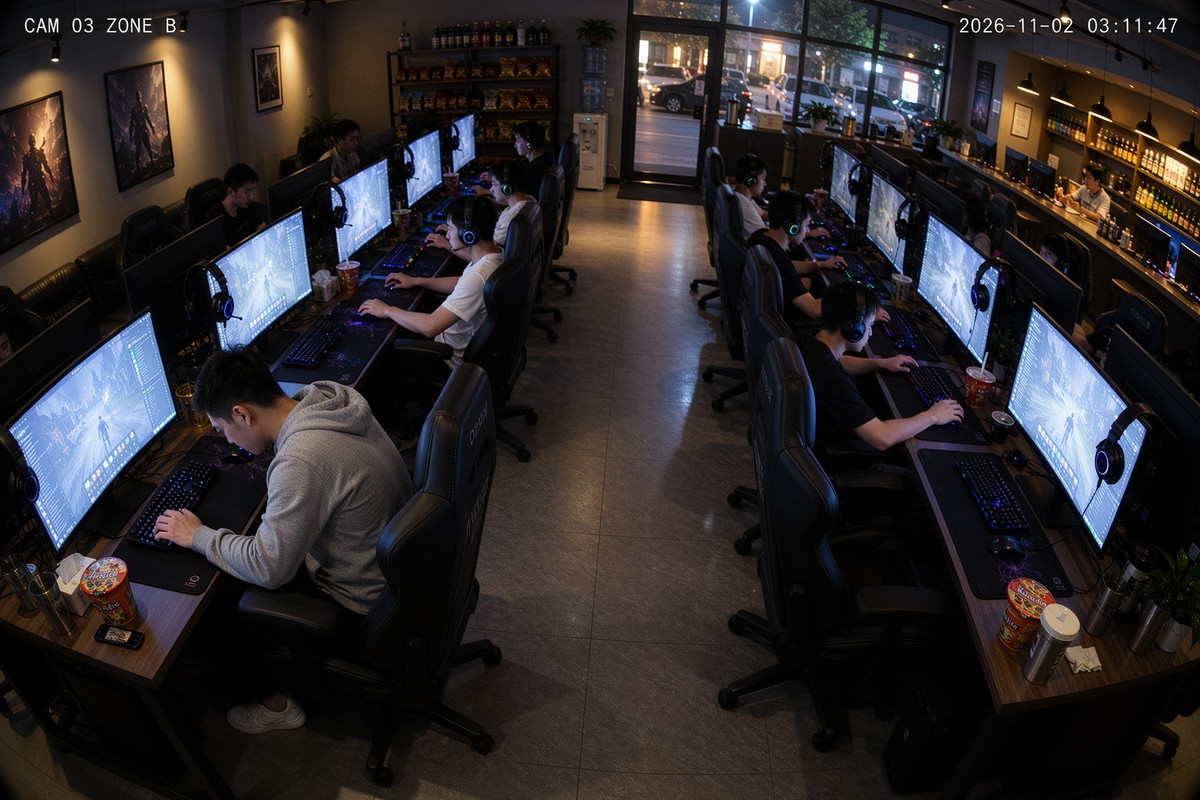
[B] Internet Café 网吧 — Rows of PCs, Gaming Chairs, Instant Noodles, Screen Glow | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-03 19:02 · Downloads 26
A LoRA for internet café scenes: rows of lit monitors and headphones, black gaming chairs, narrow partitions, instant noodles and drinks on desks, snack racks and reception counters, with cold screen light illuminating faces.
Images
[B] MOSS + Qwen2.1-PE Image Prompt Optimization Workflows (T2I + I2I/WD14) · v0.1
Workflow · New Model · Author EKLL · Published 11-03 15:22 · Downloads 23
Two ComfyUI prompt optimization workflows: rewriting rough text into detailed MOSS prompts, or reverse-engineering tags from reference images and then rewriting them.
Images
Included Only (13)
- xLingSoo · MOSS Image — LoRA: Fictional character LoRA: A young Taiwanese woman with straight black hair; the author states that all training images were AI-generated and no real photos were used.
- Kigurumi Onesie: Eddy Fox [Krea2/MOSS] · MOSS_SFT_v1.0 — LoRA: Part of the AuthentiQ onesie series: Dressing the character in a kigurumi onesie styled after Eddy the Fox from Pororo the Little Penguin, MOSS SFT version.
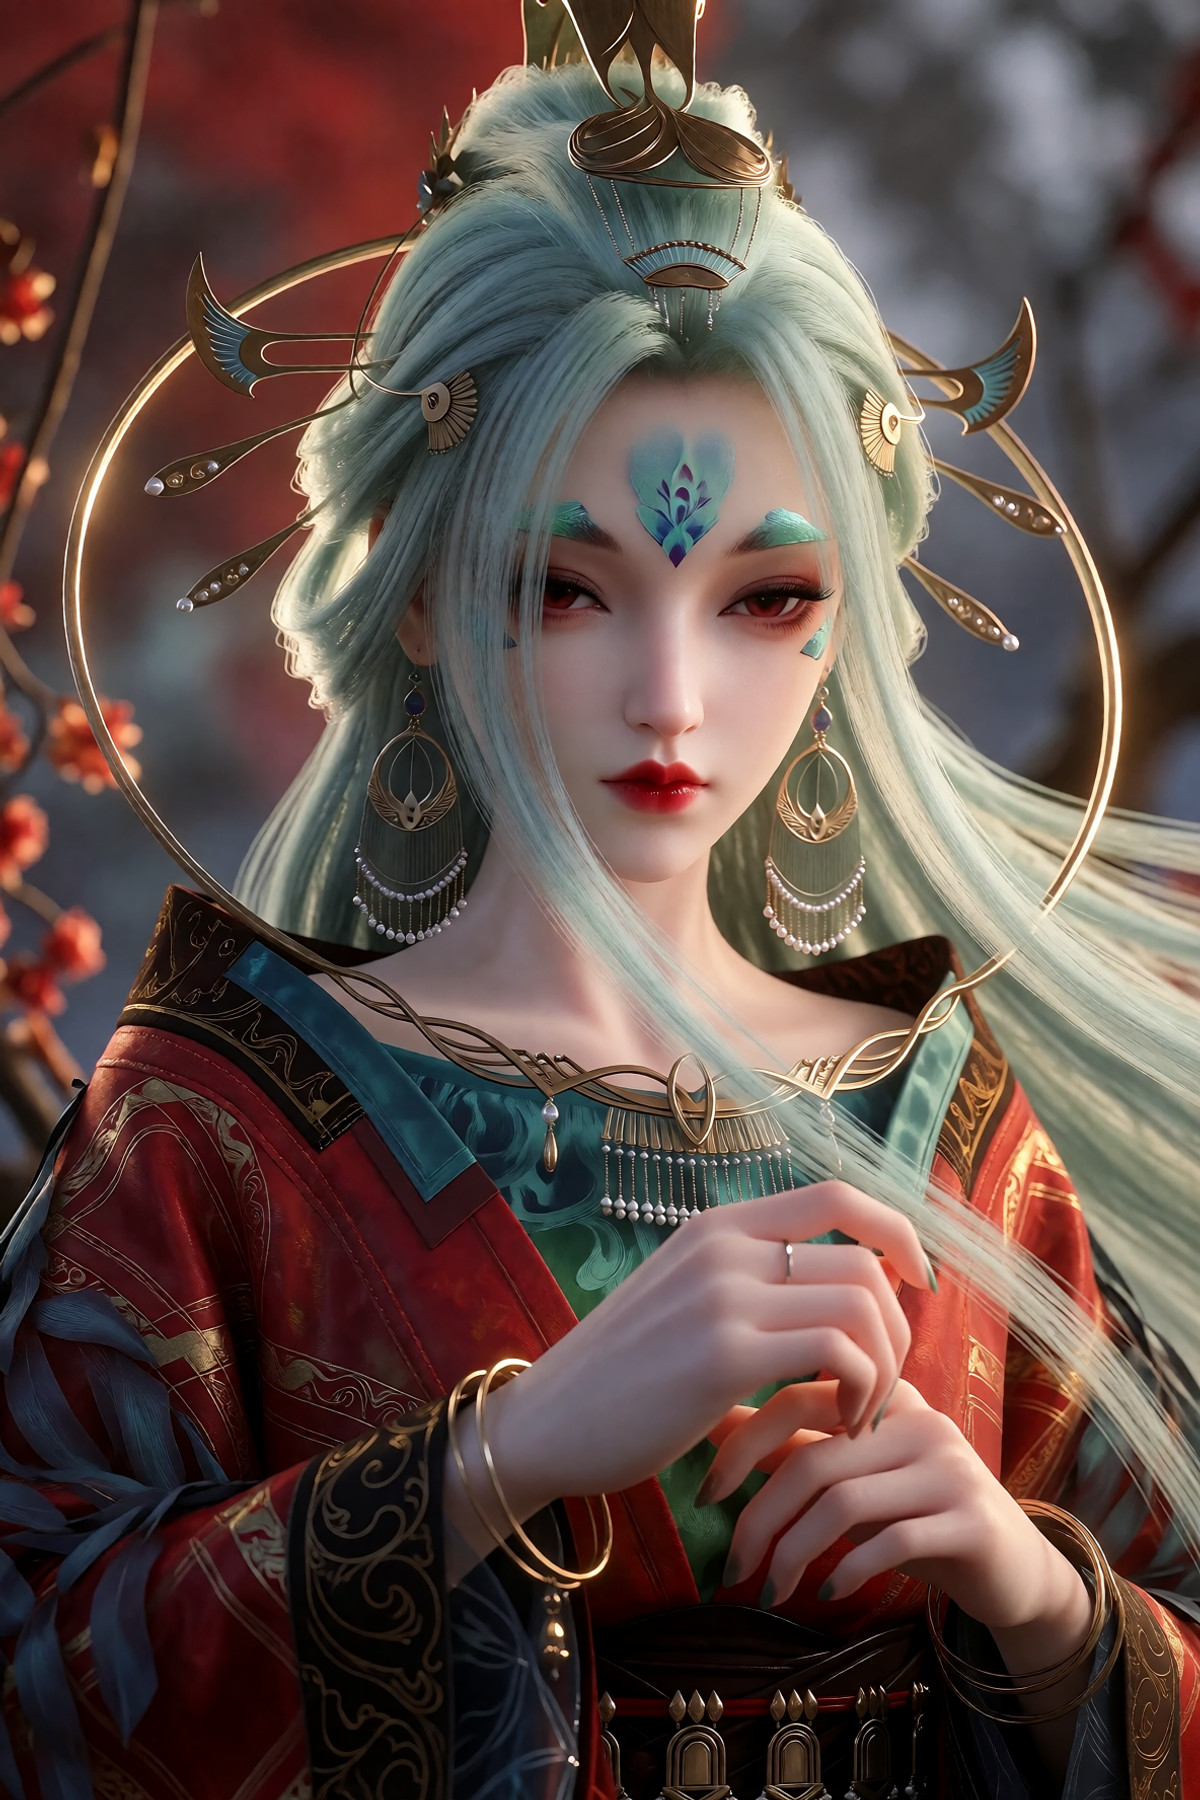
- MOSS-008Fengmian · 008yul Fengmian-moss — LoRA: MOSS version of the "Fengmian" character LoRA featuring a Chinese-style fairy: long light green hair, a golden hair ornament on top of the head, a circular halo behind, a blue floral forehead mark, and red lips.
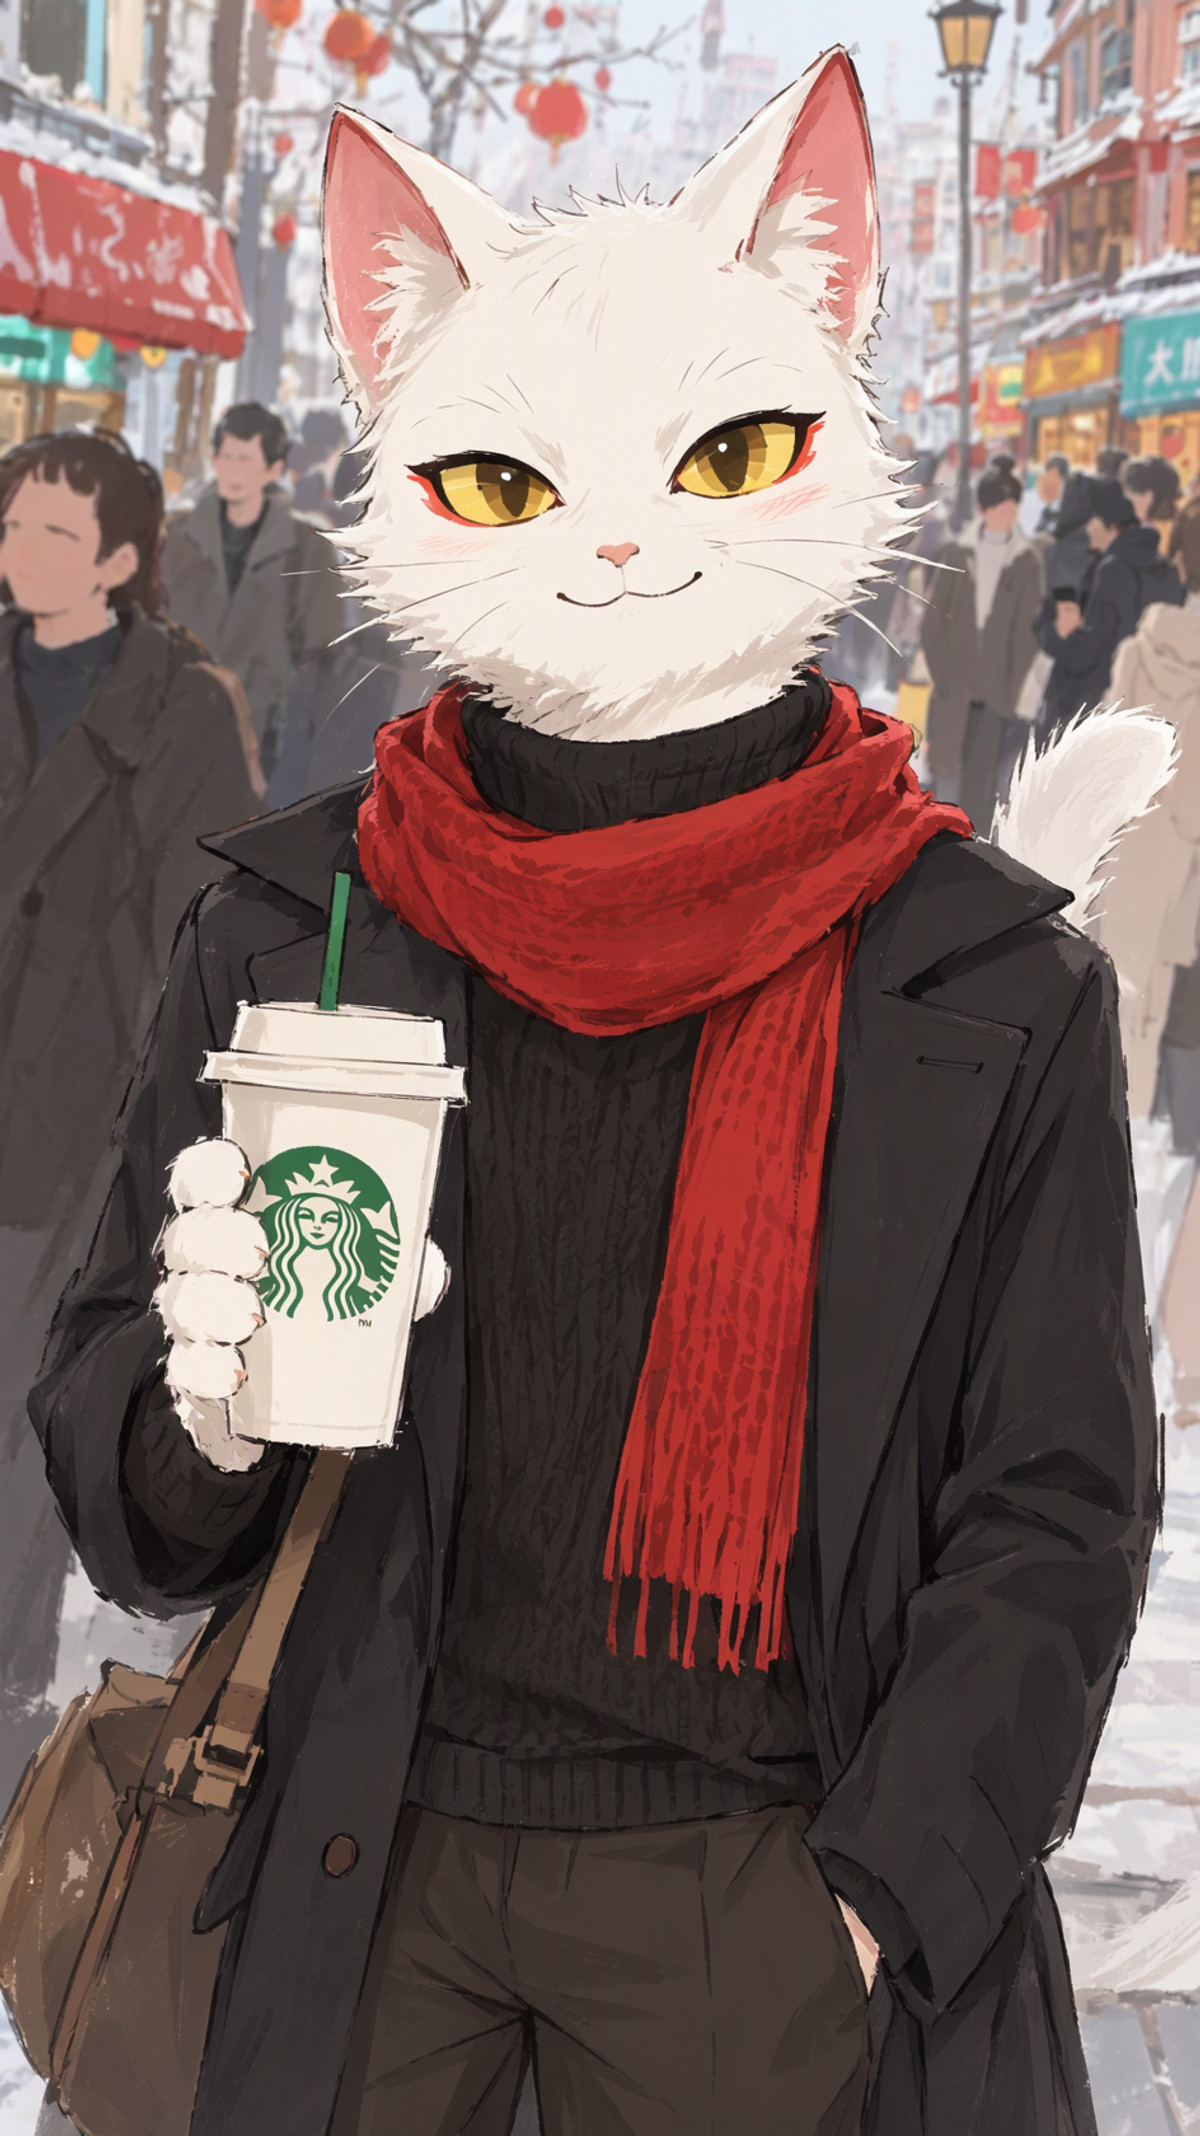
- White Cat Legend - Li Bing Libing-White Cat Legend · v2.0 — LoRA: Second version of the MOSS character LoRA for Li Bing, the white cat character from the Chinese animation White Cat Legend; use "guanfu" to generate the original official attire.
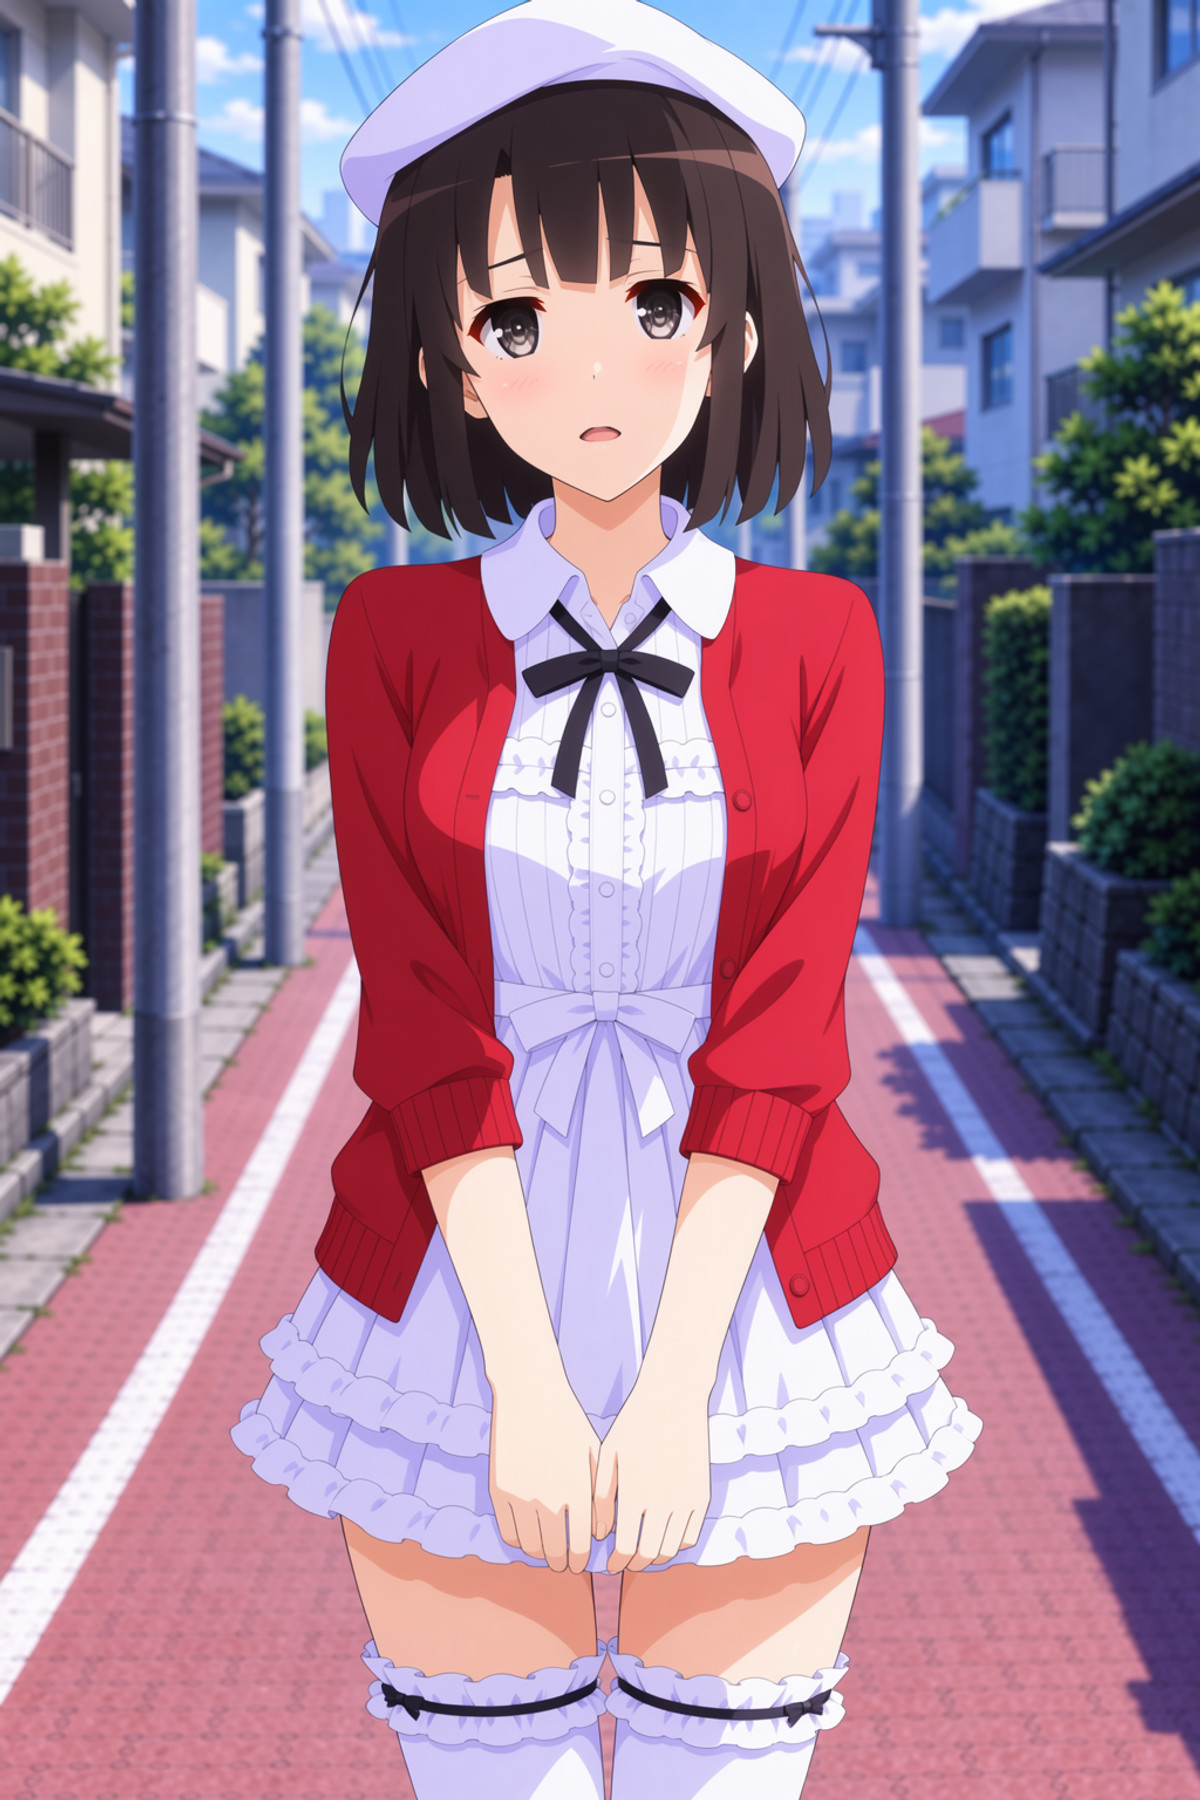
- Megumi Katou · v1.0 — LoRA: Character LoRA for Megumi Katou from Saekano: How to Raise a Boring Girlfriend: Two outfits, casual wear with a white beret, red cardigan, and white skirt, as well as a sailor-style school uniform.
- 2d game style · v1 — LoRA: A cartoon art style LoRA with thick black outlines; the author states it is aimed at art production for 2D game styles.
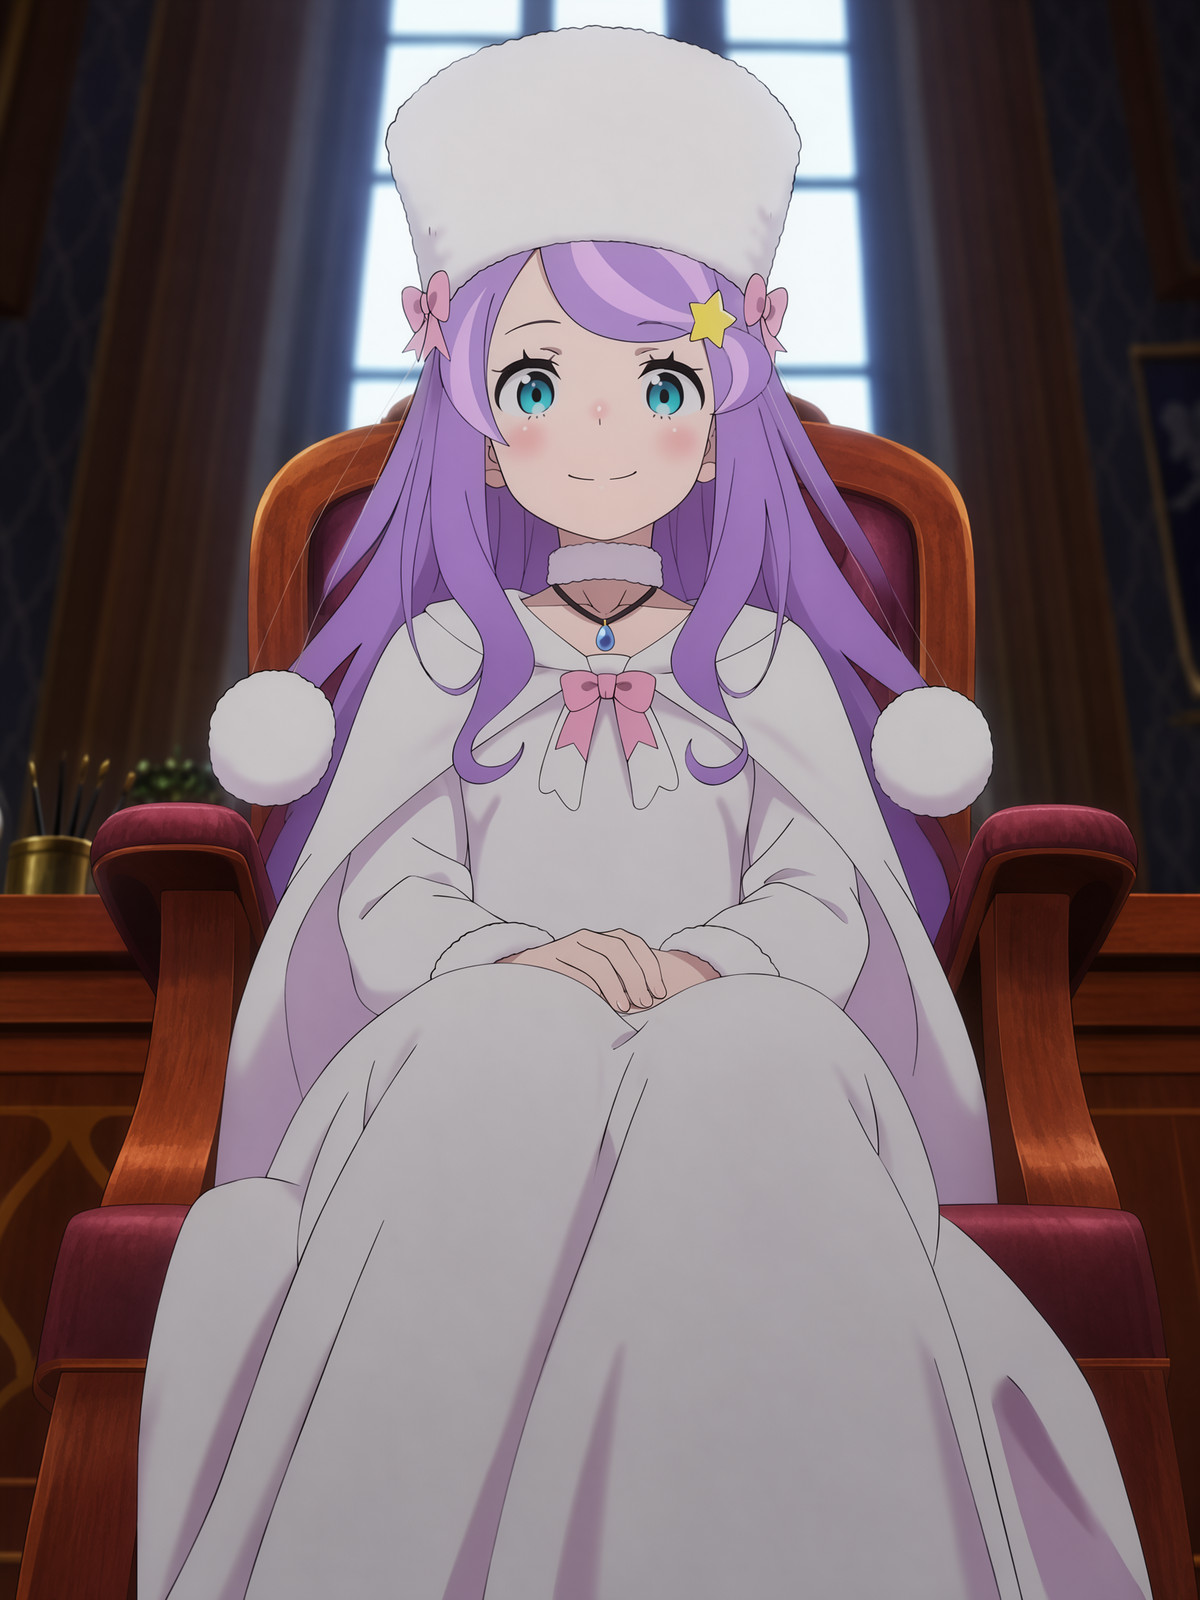
- Anastasia Hoshin - Re:Zero (MOSS Base) · Anastasia — LoRA: Character LoRA for Anastasia Hoshin from Re:Zero - Starting Life in Another World (trained on MOSS Base): White tall fur hat, white shawl with a pink bow and two pom-poms, long white dress, plus a hatless variant.
- MOSS mento Style · v1.0 — LoRA: An art style LoRA named "mento"; the author only states it was trained based on MOSS Base with no trigger word, without specifying the style.
- Elizabeth WhiteMoon · MossImage — LoRA: MOSS version of the character LoRA for the fictional female character Elizabeth WhiteMoon; the author released a version for each of six base models on the same day.
- [Moss] Female Administrator Endministrator | Arknights: Endfield · v1.0 — LoRA: Character LoRA for the female Administrator (Female Endministrator) from Arknights: Endfield, trained on MOSS-Image SFT.
- Nazuna Hiwatashi (Brand New Animal, BNA) · v1.0 — LoRA: Character LoRA for Nazuna Hiwatashi, a fox beastman character from the anime BNA: Brand New Animal; the author states this is a test trained using only 22 images.
- Araneesama - Style - MOSS Image · MOSS Image — LoRA: A 2D illustration style LoRA imitating the art style of Danbooru artist araneesama, tagged as pinup illustration.

- HollyAnn Moss · v1.0 — LoRA: Fictional female character LoRA "Holly"; the author states it was trained using images generated with prompts and Grok Imagine.
Data: Civitai public API (base model MOSS Image), inclusion window 11-03 08:31 → 11-03 21:01 (Beijing Time). Recommendations have been reviewed by editors; download counts only reflect popularity.