Zhenzhen's AI Radar · MOSS Image · 2026-11-04 Evening Report
This issue features 32 new versions: Strongly Recommended 1 · Recommended 5 · Worth Watching 17 · Included Only 9
Editor's Note This issue reviews 32 new MOSS versions. Top pick: un-GPT Re-sample: Use the Edit node with this LoRA to resample anime images already generated by MOSS SFT, removing the glossy GPT-style texture. The author provides full instructions, parameters, two workflows, and before-and-after comparison data. Tier A includes the free quantized version of Moody Moss Mix V4.1, Neon Double Exposure Film Style, Soft Pastel Photography Style, Halphas Cinematic Background Lighting, and sy4 Clear Anime Style. Of the 9 auto-S entries, only 1 were kept; three V67 batch ports only described usage for other base models and were downgraded to B / C. The paid BF16 precision version and Illuminated Manuscript Style are rated B; the paid hip slider and character LoRAs with only trigger word descriptions are rated C.
Strongly Recommended (1)
[S] un-GPT Re-sample | MOSS Image · v1.0
LoRA · New Model · Author bag3l · Published 11-04 16:54 · Downloads 27
A LoRA for "secondary resampling" of MOSS Image SFT outputs: It redraws already generated anime images to remove the glossy, heavy-blush GPT-style texture, replacing it with flatter shading and clearer lines, while keeping the character and composition largely unchanged.
Top pick for this group: The purpose is clear in one sentence, workflows and parameters are fully provided, and quantitative before-and-after data along with failure cases are included. This is the exact opposite direction of the contemporary gpt-image-2 style LoRA.
Reasons for Recommendation
- New model: Not a standard style LoRA, but a second-pass processing step—first generate text-to-image normally with MOSS SFT, then feed the image into the MOSS-Image Edit node with fixed instructions and this LoRA to redraw it; the author explicitly states that attaching it only in text-to-image generation yields almost no change
- Addresses the "AI look" in anime illustrations: Solves the issue of MOSS SFT outputs leaning towards GPT-style gloss; can be chained after existing text-to-image workflows or used to process existing images independently
- More robust evidence than similar tools: The author tested 24 prompts using a classifier distinguishing gpt-image-2 from hand-drawn anime; the author reports that after resampling + LoRA, the median score dropped from 0.927 to 0.452, with 13 out of 24 images scoring below 0.5; using only the LoRA or only resampling resulted in almost no drop
- Complete parameters and workflows: Original instructions, negative prompt syntax, edit format, strength, steps, CFG, sampler, skip layer guidance, and dimensions are all documented; includes two ComfyUI workflows (one-click two-pass / resample only) with no custom nodes required; 9 example images
- Free with a permissive license; approximately 5 hours after release, it has 27 downloads (indicating attention level only)
How to Use
- Place the LoRA in models/loras/ and name it ungpt_v1.safetensors; use the MOSS SFT main model, text encoder, and VAE from Comfy-Org/MOSS-Image; requires a newer version of ComfyUI with the Text Encode MOSS-Image Edit node
- Workflows: moss_sft_t2i_then_ungpt.json (queues both passes from prompt to final image) or ungpt_resample_image.json (processes existing images); both have preset parameters
- Instruction: Redraw this image as hand-drawn anime art without the AI-generated look. Keep the character, pose, outfit and framing.; leave the negative prompt empty and attach the same image; edit format is ai-toolkit (kv_cache off)
- Strength 1.0; 50 steps, CFG 3, euler + sgm_uniform, denoise 1.0 (starts from empty noise, guided by the input image, not low-denoise img2img); Skip Layer Guidance DiT Simple, single_layers 22, double_layers left empty; approximately 1 MP, dimensions must be multiples of 16, output size matches input size
Risks and Limitations
- The author tested on an RTX PRO 6000; resampling takes about 46 seconds and uses approximately 28 GB of VRAM; smaller GPUs and quantized model files were not tested by the author
- Inconsistent results: The author reports that in 24 images, 4 showed almost no score change; minor changes occur in hair, face, and expressions, and text within the image must be checked manually; it leans towards a general hand-drawn style and does not replicate specific artists
- The author reports that when processing original gpt-image-2 images, pose retention is only about 83%, with color casts, composition, and faces more prone to drift; MOSS Base, multiple seeds, other strengths, and samplers were not tested
- Classifier scores are not AI detectors; the author also warns that the classifier has not seen MOSS images, so it should only be used as a reference; this entry was not run
Recommended (5)
[A] AG: Halphas - Cinematic Backgrounds / Light · MOSS-Image
LoRA · Port · Author Azriaelis · Published 11-04 11:00 · Downloads 53
The "Halphas" style LoRA from the Ars Goetia series; the name and tags point to cinematic backgrounds and lighting effects (starlight, cinematic lighting, anime-oriented), using trigger words to enhance the style.
Downgraded from Auto-S to A: MOSS parameters and examples are complete, but the purpose can only be inferred from the name and examples, and the required turbo LoRA is not specified. The parameter syntax is identical to Chenbo's from the previous issue.
Reasons for Recommendation
- Port: Previous versions existed for Anima and Krea2Turbo; this version provides specific parameters for MOSS-Image: Base model + 8 step turbo LoRA
- Serves anime-oriented images in text-to-image generation that require cinematic lighting and atmospheric backgrounds; the author does not describe specific visual features in text, so examples must be reviewed
- Trigger word @H4LPH4S9; the author states that including the trigger word significantly strengthens the style; 17 visible examples
- Free; this version has 53 downloads, with cumulative model downloads at 683 (indicating attention level only)
How to Use
- MOSS-Image Base + 8 step turbo LoRA, then load HALPHAS-MOSS-V1 (1).safetensors, and include "@H4LPH4S9" in the prompt
- euler + simple, LoRA strength 0.8-1, 8-16 steps, CFG 1-3
- The author did not specify which turbo LoRA to use
Risks and Limitations
- The author states that training images are a mix of sources including Midjourney, NijiJourney, and Tumblr, describing it as a "small casual experiment" with varying quality across the series; copyright sources of training materials are unclear
- The description is very short and does not specify exactly what this LoRA draws; the license does not allow publishing derivative models; 3 sensitive-level examples are hidden; this entry was not run
Trigger Word: @H4LPH4S9
[A] Moody Moss Mix (Free download 免费下载) · V4.1 25STEPS CFG3
Base Model / Checkpoint · Version Update · Author catlover1937 · Published 11-04 16:54 · Downloads 492
The V4.1 free quantized version (INT8 / FP8) of the realistic MOSS fusion base model Moody Moss Mix; the author claims to have fixed oily skin highlights, streamlined redundant weights, and retained the dark atmospheric lighting of V3.
Downgraded from Auto-S to A: The update direction is clearly written, and the free quantized version is ready to use, but there are few visible examples, the update notes in the version section are empty, and the license restricts commercial use of outputs.
Reasons for Recommendation
- Version update: The version notes section is empty; the V4.1 section of the model card lists three points—suppressing skin "oiliness" and overexposed highlights, removing redundant training concepts prepared for Krea 2 (the author claims prompts are more obedient), and retaining the dark contrast and dynamic lighting of V3
- Serves text-to-image generation for realistic portraits and cinematic dark scenes; the author states that starting from V3, a dual Turbo LoRA mix was adopted and tuned for 25 steps, with some original Base mixed back in to mitigate the SFT's bias towards Asian faces
- The same page provides free INT8 and FP8 files; the author claims there is little difference in quality between daily use and BF16; BF16 is a separate paid version
- Approximately 5 hours after this version's release, it has 492 downloads, with cumulative model downloads at 11560 (indicating attention level only)
How to Use
- Replace the base model with moodyMossMixFreeDownload_v4125STEPSCFG3_fp8.safetensors (or the INT8 file on the same page); no trigger word
- 25 steps; CFG is 3 as per the version name; sampler is Euler + Simple (recommended in the V3 section, not rewritten separately in the V4.1 section)
- The author emphasized in early versions that his dedicated 25 step workflow is required, with an additional 4K HD workflow; the author did not state if this is mandatory for V4.1
Risks and Limitations
- The author did not write update notes (the version notes section is empty); changes are only visible in the model card's self-description; the CFG in the V3 section is 3.5 (Chinese section 3.5–5.0), which is inconsistent with the version name CFG3
- Visible examples consist of only 1 video segments + 2 images; 17 sensitive-level examples are hidden, far exceeding the visible count
- Strict license: Only on-site rental is allowed; commercial use of outputs and publishing derivative/fusion models are prohibited; the author also forbids reposting; the author states the training set is biased towards Asian faces; this entry was not run
[A] Neon-Double Exposure Grainy Photography - Style Booster · Moss
LoRA · New Model · Author TheP3NGU1N · Published 11-04 11:54 · Downloads 58
Neon night scene double exposure film style LoRA: Overlays characters with city neon reflections, bokeh, and coarse grain to produce duotone, soft-focus, haloed night photography.
Downgraded from Auto-S to A: The style is clear and the prompt templates are useful, but the examples are upscaled, step counts are not provided, and the license restricts commercial use.
Reasons for Recommendation
- New model: The author claims training on 200 double exposure photos, mostly featuring neon / urban / long-exposure night themes, aiming to make this style appear consistently
- Serves night portraits and mood posters in text-to-image generation: Characters walking on wet streets, riding motorcycles, or in neon sign reflections can be described with short words or simple shapes
- Actionable: Trigger words, strength range and author's preferred values, CFG range, negative prompts, and two prompt templates with replaceable colors and subjects are provided; the author claims to have tested it on Dirty-Moss, Kromoss, and Moss SFT, and it can be stacked with other LoRAs
- Free; approximately 10 hours after release, it has 58 downloads and 13 likes (indicating attention level only)
How to Use
- Load NDEGP_Moss_v1_Final.safetensors, strength 0.7-1.0, author's preference approx. 0.75; trigger word NDEGP, author states it is usually not required
- Prompt template: Dark urban night, film grain, double exposure, reflection of neon sign of short word/simple shape, halation bloom bokeh, color1-color2 duotone, soft focus + your subject (replace color1 / color2 with specific colors)
- CFG 1-3.5, sampler / scheduler author states common ones are fine; negative prompt: daytime, drawing, painting, worst quality, bad anatomy, watermark, jpeg artifact
- Steps not specified by author
Risks and Limitations
- Author notes all example images were upscaled with SeedVR2, so native output details should be viewed with reduced expectations; 5 images are visible, another 5 sensitive-level examples are hidden
- Strict license: rental within the site only, generated images cannot be used commercially, derivatives not allowed; this entry was not run
Trigger Words: NDEGP, Dark urban night, film grain, double exposure, reflection of neon sign of short word/simple shape, halation bloom bokeh, color1-color2 duotone, soft focus, Dark urban night, heavy film grain, double exposure ghosting, reflection light streaks, halation bloom bokeh, color1-color2 duotone, soft focus cinematic
[A] Soft Pastel Photography | MOSS & Krea2 · MOSS v1.0 - BF16
LoRA · Port · Author Coffmeteor · Published 11-04 16:27 · Downloads 17
Soft pastel photography style LoRA: light colors, low contrast, lifted shadows, glowing soft-light portraits, best suited for Hanfu portraits and classical garden scenes.
Downgraded from S to A automatically: parameters and training details are transparent, but the subject matter is narrow and examples are few.
Reasons for Recommendation
- Port: Another independently trained Krea 2 version is available on the same page; the author emphasizes that the two files are not interchangeable. The MOSS version is trained on the original MOSS Image Base with frozen text encoding.
- Suitable for generating ancient-style / Hanfu portraits and romantic period scenes in text-to-image tasks; the author also provides a migration example for modern portraits.
- Complete parameters: Trigger phrase, strength, base model used in examples, acceleration LoRA, steps, CFG, sampler, and shift are all clearly specified. The 4 example images are unupscaled and have not undergone face correction.
- Training details are public: rank 32, 272 updates, 17 training images; free to use with a permissive license.
How to Use
- Load Soft Pastel Photography MOSS.safetensors and include "Soft pastel photography style" in the prompt; set strength to 1.0, or use 0.7 for a subtler effect.
- Example configuration: MOSS Image SFT BF16 + separately downloaded 16step-cfg1 acceleration LoRA (strength 1.0), 16 steps, CFG 1, Euler / simple, shift 5. Load this style LoRA first, then load the acceleration LoRA.
- This file contains only the style, not the acceleration weights.
Risks and Limitations
- The training set consists of only 17 images, focused on similar female Hanfu portraits. There are only 1 example images of modern portraits for each version.
- At high strength, it may alter hairstyles, headwear embroidery, faces, and composition. The author explicitly states that character identity is not preserved. Only 4 visible examples are provided; this entry has not been tested.
Trigger Words: Soft pastel photography style
[A] Art Style: sy4 · v1.0
LoRA · New Model · Author Suzuka_naoko · Published 11-04 09:32 · Downloads 73
Clear Sky LoRA with a transparent anime style: The author describes the style features as bright large eyes, fine soft hair, transparent skies and lighting, and clean color palettes.
This is the most complete entry in the group: It includes training configurations, two sets of sampling parameters, and prompt templates; what is missing is the number of examples.
Reasons for Recommendation
- New model: The author states it was trained on MOSS-Image Base using 79 WD14 annotated images (rank 32 / alpha 128, learning rate 1e-4, 8000 steps, approximately 100 epochs per image), tested on SFT int8
- Serves anime illustration text-to-image generation; the author states it is suitable for beast-ear girls, school uniforms, and daily scenes, with prompts written in tag format
- Parameters are complete and divided into two sets: One set without DMD and one with a 8-step DMD acceleration LoRA, each providing steps, CFG, sampler, and scheduler, along with strength, resolution, and two complete example prompts; the author states that the example image information includes prompts and seeds
- Free; approximately 73 downloads in about half a day since release (indicating attention level only)
How to Use
- Load sy4_e100.safetensors, strength 1.0 (adjustable between 0.8 and 1.2); write "@sy4" at the beginning of the prompt, using the tag format "@sy4, general, 1girl, solo, ..."; the author states it works even without writing it, but writing it is more stable
- Without DMD: 40-50 steps, CFG 3, euler / simple, shift 5 (the author states colors are more saturated)
- With 8-step DMD acceleration LoRA: 12 steps, CFG 1, euler / simple (the author states results are cleaner, brighter, and faster)
- Resolution is approximately 1MP, such as 1024×1536, 832×1216; to generate text, specify the content in the prompt
Risks and Limitations
- Only 2 visible examples (another 2 sensitive-level examples are hidden), so the style relies mainly on the author's description
- The trigger word is not registered on the site, only mentioned in the description; the name sy4 refers to a specific artist, and the author declares it is unofficial, asking users not to impersonate the artist or use it commercially, but the site license checkbox allows selling, creating an inconsistency; handle commercial use according to the author's declaration; this entry has not been tested
Worth Watching (17)
[B] Excellent MOSS-Image [EMI] Hi-Res T2I/I2I Upscale v1.0 by ArtGourieff · v1.0
Workflow · New Model · Author ArtGourieff · Published 11-04 15:57 · Downloads 29
ArtGourieff's MOSS-Image high-resolution upscaling ComfyUI workflow: Generates images in 8 steps, supports text-to-image and image-to-image, and upscales to 8MP.
[B] V67 IOR · V1 MOSS
LoRA · Port · Author angelomaiota · Published 11-04 17:08 · Downloads 26
"Index of Refraction" material LoRA: Add (IOR:value) to objects in the prompt, aiming to make glass, water droplets, ice, diamonds, and wet skin reflect and refract according to the corresponding index of refraction.
[B] Style > gpt-image-2 · MOSS v0.1
LoRA · Port · Author AgileNumbers · Published 11-04 17:08 · Downloads 58
An enhanced LoRA that pushes generated images toward the gpt-image-2 style: the author claims it adds detail, lighting, and texture, at the cost of potentially making the image appear slightly “blurry.”
【B】V67 Photo Painting · V1 MOSS
LoRA · Port · Author angelomaiota · Published 11-04 14:39 · Downloads 24
A “photo + oil painting” hybrid style LoRA: the images look like realistic photos but feature visible brushstrokes and canvas texture, with variants available for watercolor, charcoal, palette knife, impasto, pastel, etc.
【B】Minaba Hideo Style | MOSS Image · v1.0
LoRA · New Model · Author HissingCat · Published 11-04 11:52 · Downloads 104
A LoRA mimicking the art style of illustrator Minaba Hideo, with tags associated with Granblue Fantasy.
【B】Wanderer's Semi Realistic Artistic Style | Krea 2 + MOSS · MOSS Image
LoRA · Port · Author ImWanderer · Published 11-04 13:18 · Downloads 49
The MOSS version of a semi-realistic artistic style LoRA; the author previously created a Krea 2 version.
【B】[MOSS Image] Mix Armor Lora · v1.0 - SFT
LoRA · New Model · Author hinablue · Published 11-04 09:35 · Downloads 61
An armor clothing LoRA: the author states it was trained by mixing existing data with armor data, intended to improve the representation of various types of armor.
【B】xSolarpunk · MOSS Image
LoRA · New Model · Author randomimagepotato · Published 11-04 16:47 · Downloads 26
A Solarpunk style LoRA: optimistic future cities where technology and plants merge, featuring landscape perspectives and detailed lighting.
【B】Goblin Slayer · Goblin_Slayer_Moss_v1.0
LoRA · Port · Author AthosAI · Published 11-04 11:13 · Downloads 15
The MOSS version of a character LoRA for Goblin Slayer, the protagonist of Goblin Slayer; it can generate looks such as full armor with helmet, face visible without helmet, and helmet paired with casual clothing.
【B】UAZ-452 Bukhanka (Vintage Van) | Soviet Retro Off-Road LoRA · v1.0 MOSS
LoRA · Port · Author bazya022020810 · Published 11-04 20:43 · Downloads 10
The MOSS version of a LoRA for the Soviet UAZ-452 “Bukhanka” (Loaf) vintage off-road van; the author describes it as a trial version.
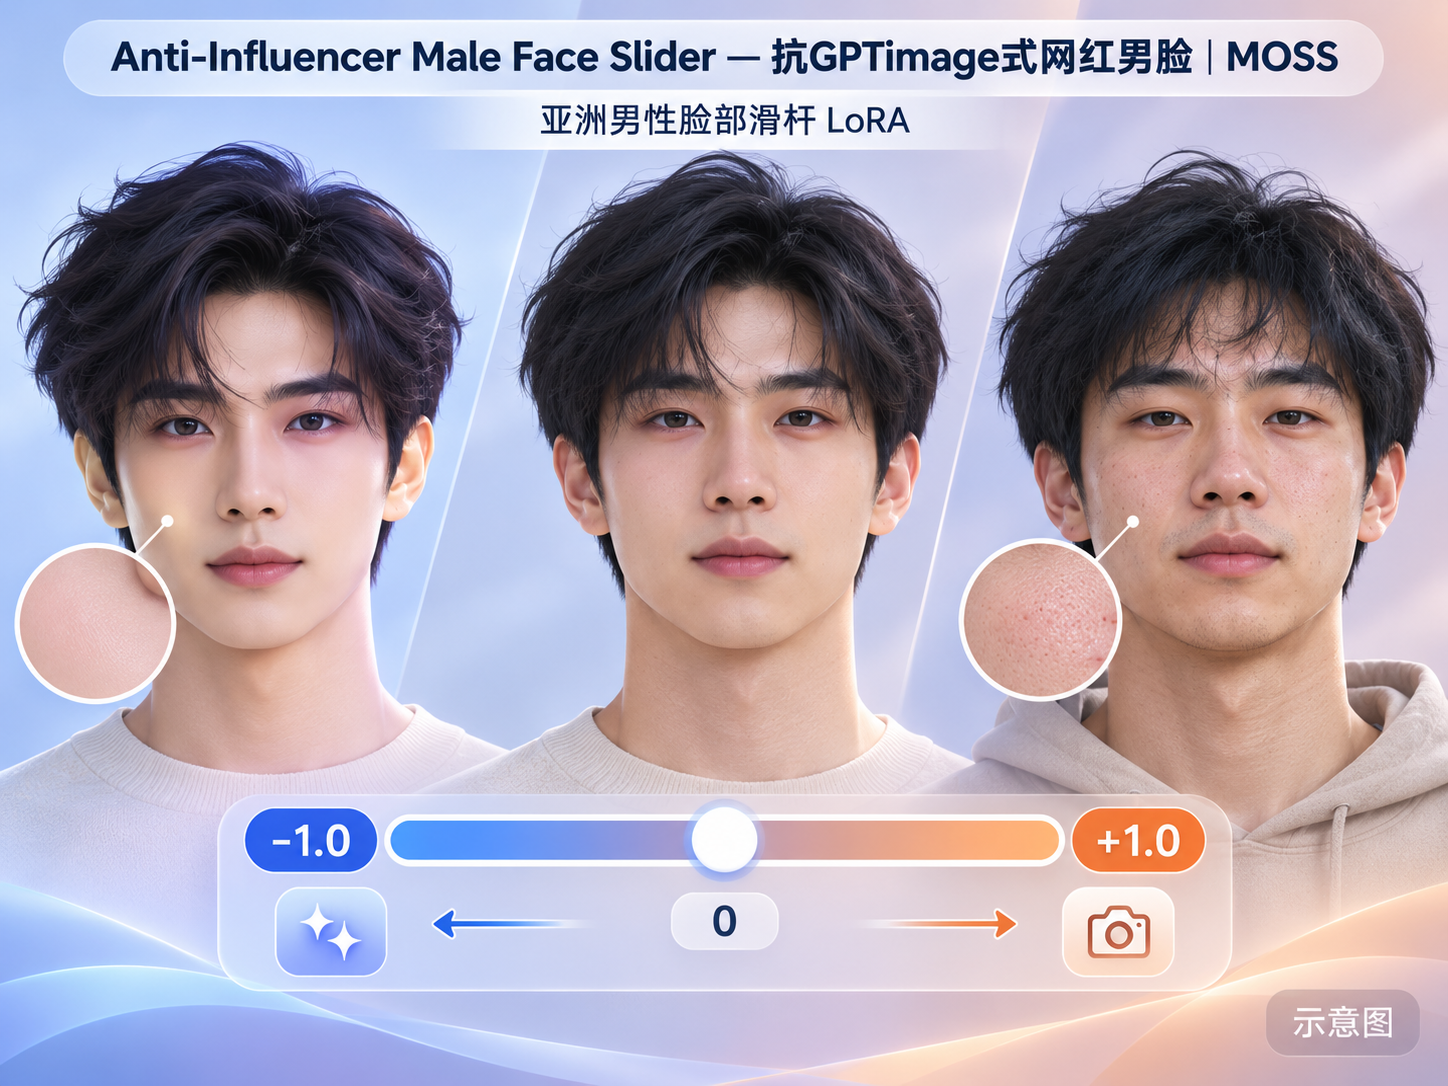
【B】Anti-Influencer Male Face Slider — Anti-GPTimage Influencer Male Face | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-04 17:58 · Downloads 34
An Asian male face slider LoRA: positive values shift refined “influencer faces” toward realistic appearances and skin textures that look like ordinary people, while negative values make them more polished and idol-like.
Illustration
【B】Moody Moss Mix (Free download 免费下载) · V4.1 25STEPS CFG3 BF16
Base Model / Checkpoint · Version Update · Author catlover1937 · Published 11-04 17:01 · Downloads 6 · Paid
The BF16 full-precision version of Moody Moss Mix V4.1, containing the same content as the contemporaneous free INT8 / FP8 versions, differing only in precision and requiring payment.
【B】Elevator Interior — Steel Walls, Handrail, Buttons, CCTV Timestamp | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-04 15:43 · Downloads 100
An elevator interior scene LoRA: places any scene inside a realistic passenger elevator—featuring brushed stainless steel walls with blurred reflections, horizontal handrails, a column of circular illuminated buttons, small floor displays, and square ceiling lights—with options for CCTV overhead or eye-level camera angles.
【B】Telephoto Candid — Shot From Far Away, Blurred Foreground, Compressed Space | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-04 16:05 · Downloads 85
Telephoto candid concept LoRA: Creates the effect of a shot taken from a distance with a telephoto lens—flattening the subject and background, layering the background behind the subject, and including a blurred obstruction in the foreground, while the subject remains unaware of being photographed.
【B】dyfstyle_c1-st6000 · v1.0
LoRA · New Model · Author starskill123 · Published 11-04 15:29 · Downloads 31
"Impressionist Anime" style LoRA: Adds impressionist brushstrokes while retaining the sharp lines of anime, producing semi-thick paint style anime illustrations.
【B】Giant Octopus Wrap — An Octopus Bigger Than the Boat, Tentacles Everywhere | MOSS · v1.0
LoRA · New Model · Author 858654128784 · Published 11-04 20:48 · Downloads 14
Giant Octopus concept LoRA: Generates an octopus larger than a boat, using thick tentacles to wrap around characters and lift them from decks, docks, or reefs. The author states the goal is to look like real photographs rather than cartoons or CG.
【B】Religious Illumination Fantasy · MOSS
LoRA · Ported · Author ArsMachina · Published 11-04 18:15 · Downloads 0 · Paid
MOSS version of a LoRA featuring medieval illuminated manuscript and religious iconography styles, rendering fantasy themes as illustrations with a "sacred art" decorative feel.
Included Only (9)
- V67 Lighting · V1 MOSS — LoRA: Cinematic lighting "component" LoRA: Placing a long string of lighting keywords (volumetric light, neon, golden hour, chiaroscuro, rim light, Tyndall effect, etc.) at the beginning of the prompt enhances the lighting atmosphere of the image.
- Original Characters | Original Character Compilation LoRA · Ma Junyang-MOSS — LoRA: MOSS version of the character "Ma Junyang" added to the Original Character Compilation LoRA. The model card contains no introduction for this character.
- Ciri (The Witcher 3) | Krea 2 + MOSS · MOSS — LoRA: MOSS version of the character LoRA for Ciri from The Witcher 3. The author previously created a Krea 2 version.
- YUL-Xiao Wu-moss · Moss-yul Xiao Wu-v1.0 — LoRA: MOSS version of the LoRA for the character "Xiao Wu" in Chinese animation style, tagged as Chinese animation, 3D, and Chinese style.
- Zaynab NordhavenLove · MossImage — LoRA: Character LoRA for Zaynab, a fictional character from the NordhavenLove family created by the author. The model card is a character backstory (a herbalist on the west coast of Sweden) with no usage instructions.
- Tamaki Kousaka · v1.0 — LoRA: Anime character LoRA for Tamaki Kousaka from ToHeart2. The trigger word includes a description of a red sailor uniform school outfit.
- VRC-style-MOSS · v1.0 — LoRA: A style LoRA named VRC-style. Judging by the name, it mimics the visual style of VRChat avatar screenshots. The model card only states "A style lora".
- L-shaped sideburns · v1.0 — LoRA: v1.0 of the "L-shaped sideburns" hairstyle detail LoRA. The author marks this version as the final version (EOF) following the previous v0.2 beta test.
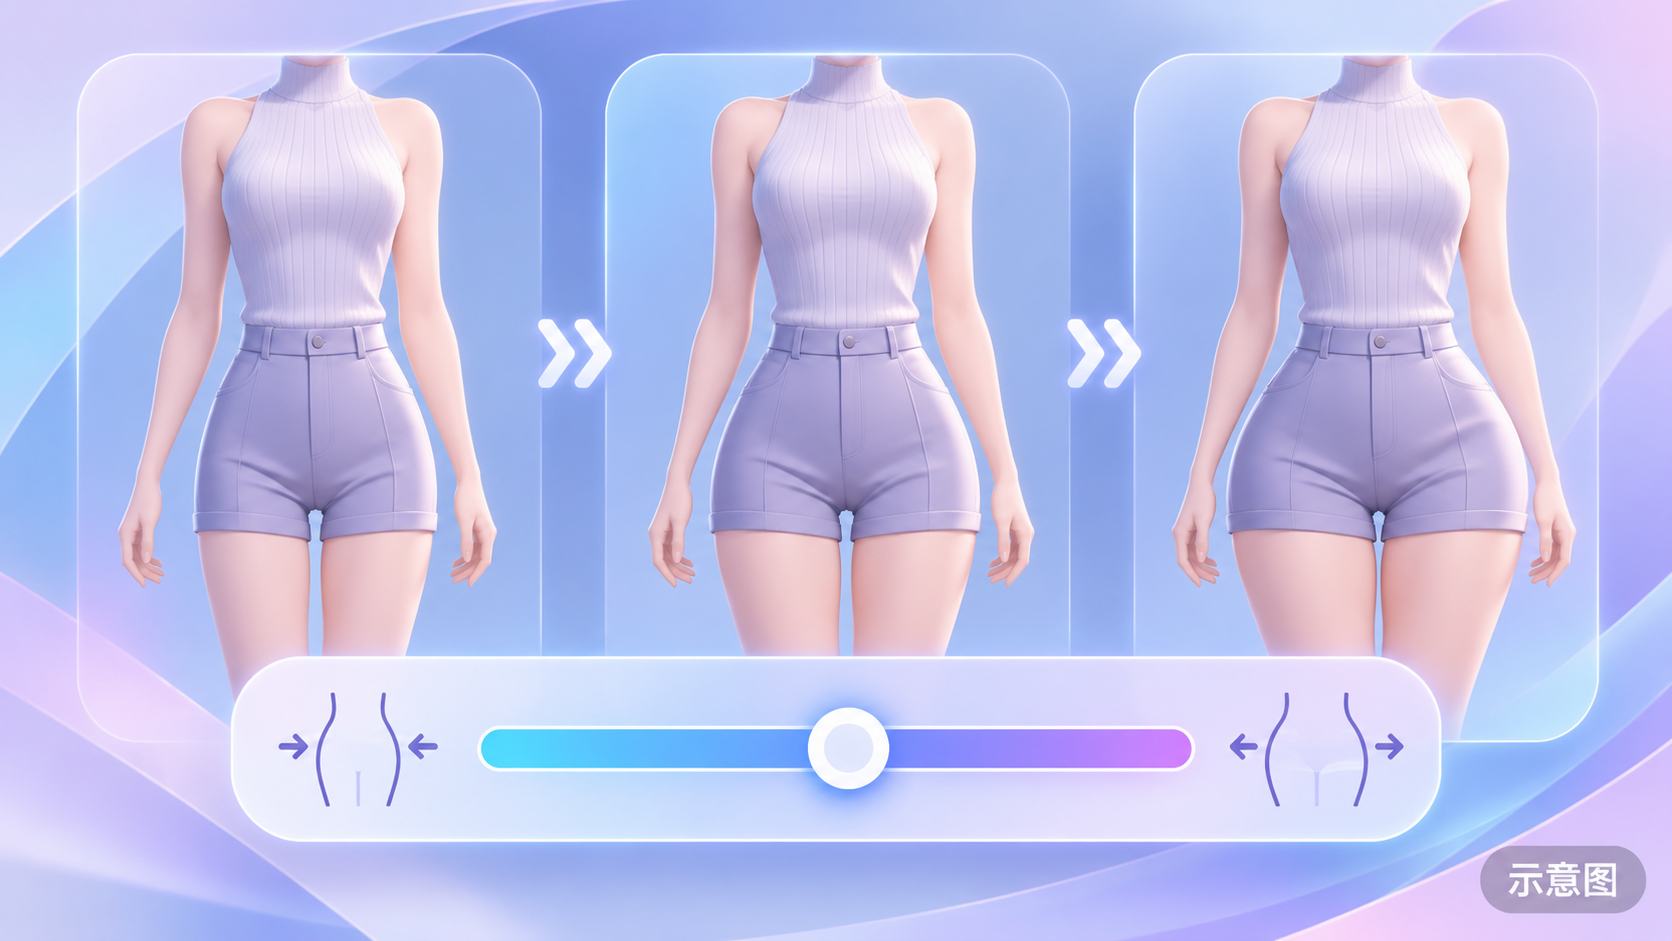
- Hips slider · Moss-image — LoRA: MOSS version of a slider LoRA for adjusting character hip width: Uses LoRA strength to continuously control hip body shape, requiring no trigger word.
Data: Civitai Public API (Base Model MOSS Image). Inclusion window 11-04 09:00 → 11-04 21:00 (Beijing Time), backfill period. Recommendation reasons have been reviewed by editors; download counts only reflect attention.