Zhenzhen's AI Radar · MOSS Image · 2026-11-06 Morning Report
This issue features 36 new versions: Strongly Recommended 1 · Recommended 11 · Worth Watching 16 · Listed Only 8
Editor's Note This issue reviews 38 new MOSS versions, rating 1 as S and 11 as A. The top pick is Retro Cel 90: a style LoRA replicating the cel animation look of 90s-era TV anime, with trigger words, prompt structure, strength, and full test parameters clearly documented. Other highlights include several style LoRAs (Vintage Drawing for old book illustrations, Ligne Claire, Anime Screencap style), the naturskinx skin detail slider, and the HaDeS MOSS Turbo 4-step / 8-step acceleration LoRA series. Auto-rated S entries like Sayoko, Clear Heels, and Mega Man PS1 style were downgraded to A or B, while standard character LoRAs such as Helena and Christie were downgraded to C.
Strongly Recommended (1)
[S] [MOSS Image] Retro Cel 90 - 1990s TV Anime Cel Style · v1
LoRA · New Model · Author lepetitprince716355 · Published 11-06 08:59 · Downloads 0
A style LoRA replicating the cel animation look of 1990s-era TV anime: flat two-tone shading, thin and uniform lines, hard-edged shadow blocks on faces, warm faded tones with fine film grain, and hand-drawn backgrounds; the author states it is an original style trained on self-generated images, not derived from any specific work, studio, or artist.
Upgraded from Auto A to S: Trigger words, prompt structure, strength, full test parameters, and known defects are all clearly documented, making this the most thoroughly explained style LoRA of the issue; training data sources are also disclosed.
Images
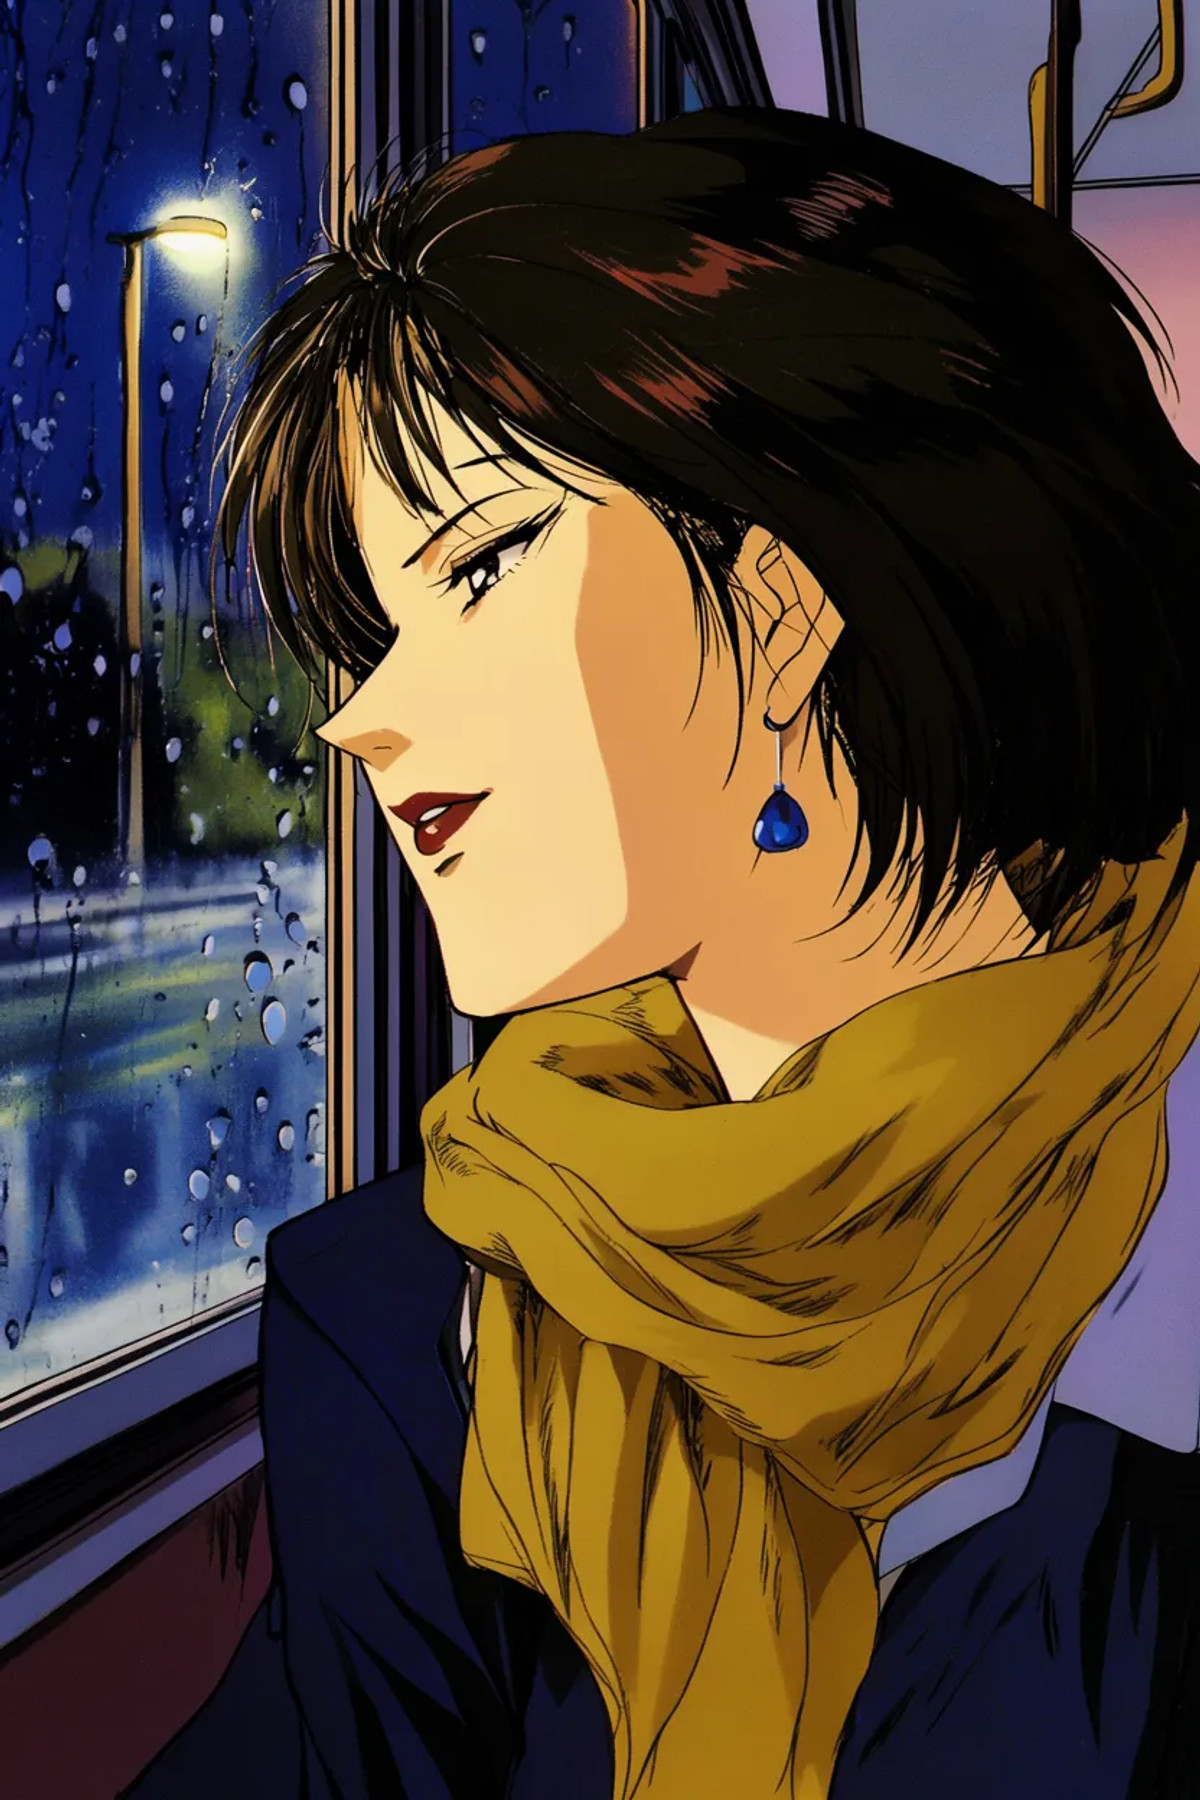
Reasons for Recommendation
- New Model: A style LoRA on MOSS specifically targeting the cel animation texture of 90s-era TV anime, serving text-to-image generation for retro anime-style character art and scene illustrations.
- Actionable: Trigger word is retrocel90; the author provides a prompt structure (start with the trigger word + a sentence specifying the medium, e.g., Anime-style digital illustration, then describe the scene in full sentences) and explains that without the medium specification, MOSS may output photorealistic images.
- Complete Parameters: Recommended strength is 0.8, not exceeding 0.8 for close-ups; the author's test environment is specified as MOSS-Image SFT, 25 steps, CFG 2.5, er_sde + simple, shift 5, 832x1248, loaded via LoraLoaderModelOnly.
- The description details the training method (ai-toolkit, 42 images, rank 32, 2000 steps) and known defects; there are 9 visible examples with no hidden ones; as it was just released, there is no download data yet.
How to Use
- Load moss_retrocel90_v1.safetensors via LoraLoaderModelOnly, strength 0.8 (0.8 or lower for close-ups).
- Start the prompt with retrocel90., followed by a sentence like Anime-style digital illustration., then describe the scene in natural language full sentences.
- Start with the author's test settings: MOSS-Image SFT, 25 steps, CFG 2.5, er_sde + simple, shift 5.
Risks and Limitations
- The author states that at strength 1.0, the style remains unchanged but faces are more prone to distortion, and hands and props become less stable.
- Colors in bright daylight scenes are more saturated than authentic 90s-era footage; the author suggests specifying a grayish base tone in the prompt.
- The author has only tested on SFT; performance with Base and Turbo acceleration LoRAs is not specified; this entry was not run, and example images were not viewed.
Trigger Word: retrocel90
Recommended (11)
[A] Sayoko - Artist Style · MOSS-Image
LoRA · Ported · Author Azriaelis · Published 11-06 00:00 · Downloads 51
A picture book illustration style LoRA with crayon and gouache textures: the author describes it as low-saturation fairy-tale tones, grainy pencil outlines, soft shadows, and a melancholic fairy-tale atmosphere; ported from the Krea 2 / Anima version to MOSS.
Downgraded from Auto S to A: MOSS parameters and trigger words are complete, but there is only a one-line style description, and it does not specify which acceleration LoRA to use.
Images
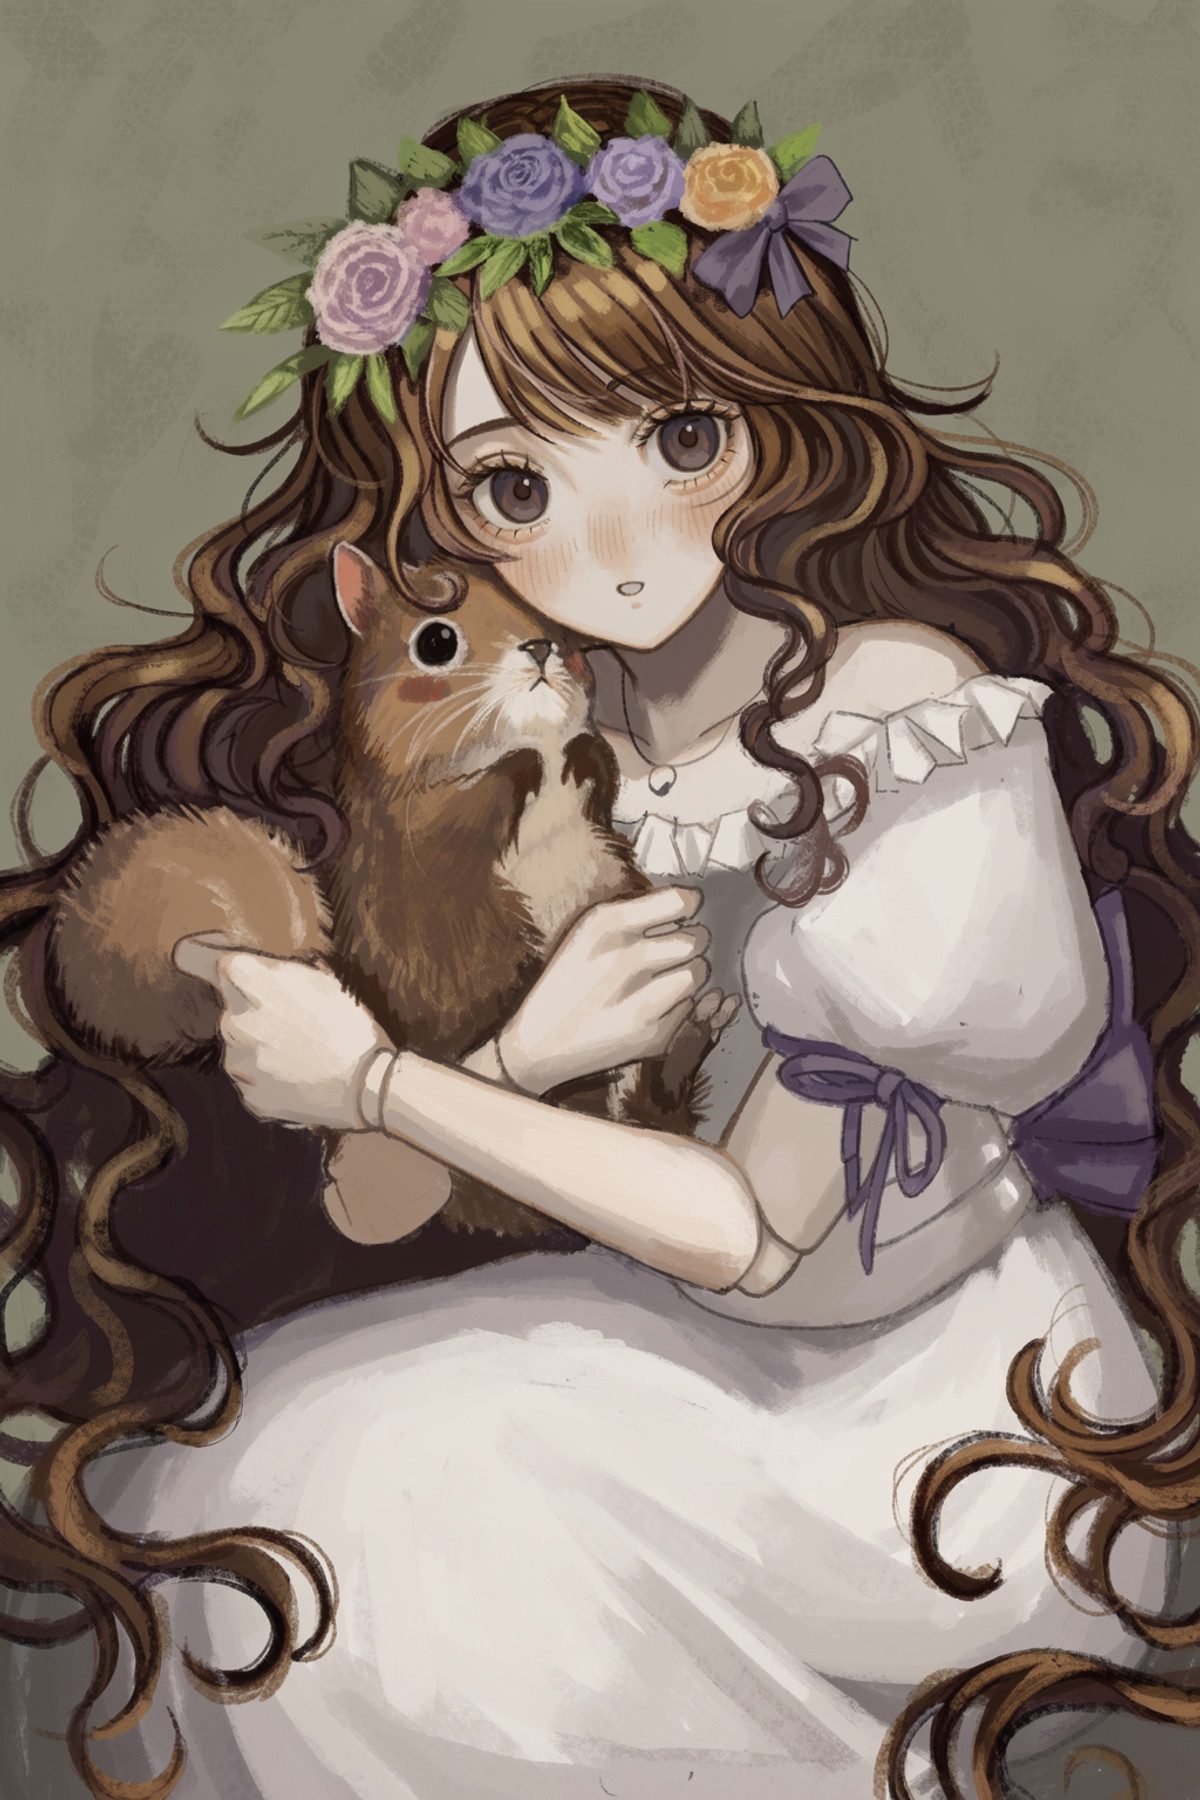
Reasons for Recommendation
- Ported: This style already has Anima and Krea2Turbo versions; the MOSS version provides a separate set of recommended settings; the version notes are empty, with no explanation of differences between the MOSS version and older versions.
- Serves text-to-image generation for picture book and fairy-tale illustration styles, with 19 visible examples.
- Actionable: Trigger words are @sayoko, vintage, crayon linework; the author states that including these trigger words significantly strengthens the style; MOSS settings are Base + 8-step Turbo LoRA, euler + simple, strength 0.8-1.2, 8-16 steps, CFG 1-3.
How to Use
- Use MOSS Base as the base model and attach a 8-step Turbo LoRA, then load SAYOKO-MOSS-V1 (1).safetensors at strength 0.8-1.2.
- Include @sayoko, vintage, crayon linework in the prompt; use euler + simple, 8-16 steps, CFG 1-3.
Risks and Limitations
- The author does not specify which 8-step Turbo LoRA to pair with; 'vintage' is a common word that may conflict with standard prompts when used as a trigger.
- The license does not permit publishing derivative/fusion models; 1 sensitive-level examples are hidden; this entry was not run, and example images were not viewed.
Trigger Words: @sayoko, vintage, crayon linework
[A] Megaman Legends Style PSX (MOSS Image) · v1.0
LoRA · New Model · Author zombiebashr830 · Published 11-06 07:39 · Downloads 29
A LoRA replicating the visual style of the PS1 game 'Mega Man Legends': the author describes blocky low-poly shapes, flat shading, cubic hair and clothing, hard pixel edges on textures, and the ability to generate generic PS1-style blocky anime characters.
Downgraded from Auto S to A: Usage and known limitations are clearly written, but inference parameters are missing, and there are only 5 examples.
Images
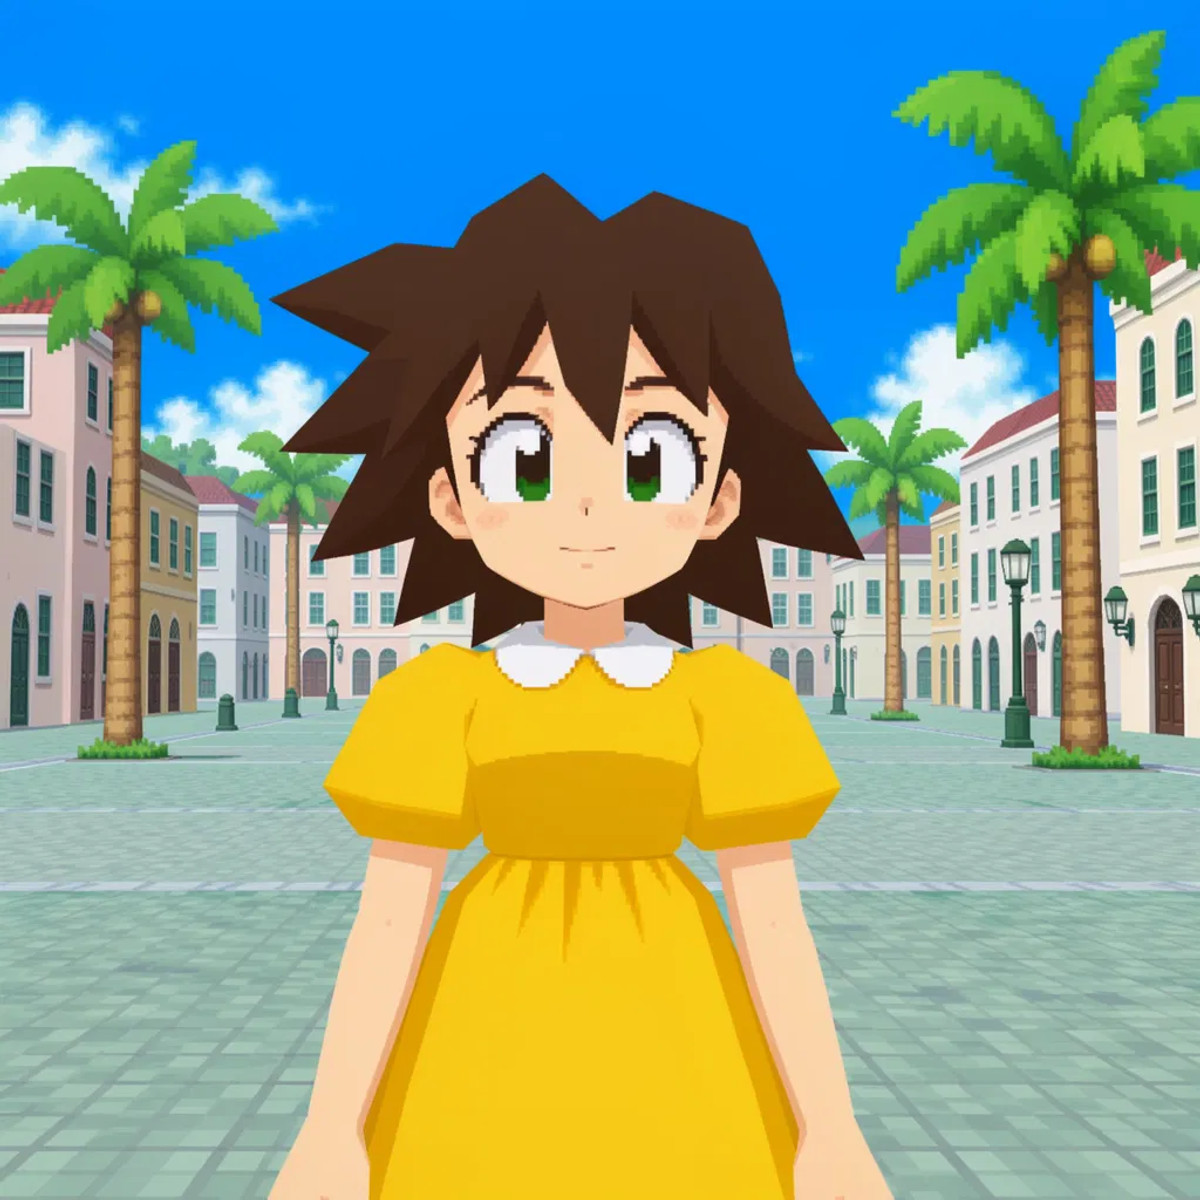
Reasons for Recommendation
- New Model: Serves text-to-image generation for retro PS1 low-poly game screenshot styles; the author states it is best suited for characters, architecture, and landscapes.
- Actionable: No trigger word; describe the scene directly; recommended strength is 1.0-1.3; when drawing organic objects (people, animals, plants), adding 'low-poly 3D model, flat shaded, pixelated texture' helps define the style.
- The author details the training: trained for 1500 steps using 57 screenshots from the game; there are 5 visible examples, and it received 29 downloads within 1 hours of release (indicating attention only).
How to Use
- Load megaman_legends_style.safetensors at strength 1.0-1.3, using natural language prompts to describe the scene.
- When drawing people or animals, add 'low-poly 3D model, flat shaded, pixelated texture'; specify desired eye colors in the prompt.
- The author did not provide steps, CFG, or sampler settings.
Risks and Limitations
- The training set contains no animals; animals and fur only partially adopt the style; green eyes are likely to appear if not specified.
- Training data consists of commercial game screenshots; assess copyright risks before commercial use; 2 sensitive-level examples are hidden; this entry was not run, and example images were not viewed.
[A] Nononononoway Style · Moss-Image v1.5.1 (A)
LoRA · Ported · Author emerjk · Published 11-06 07:35 · Downloads 16
The MOSS version of a style LoRA trained on artist Nononononoway's work: the author describes pushing images toward a glossy 2.5D style, excelling at arthropods, monsters, post-apocalyptic scenes, and machinery, while also being able to push anime character LoRAs toward 2.5D without excessively introducing dystopian elements.
Images
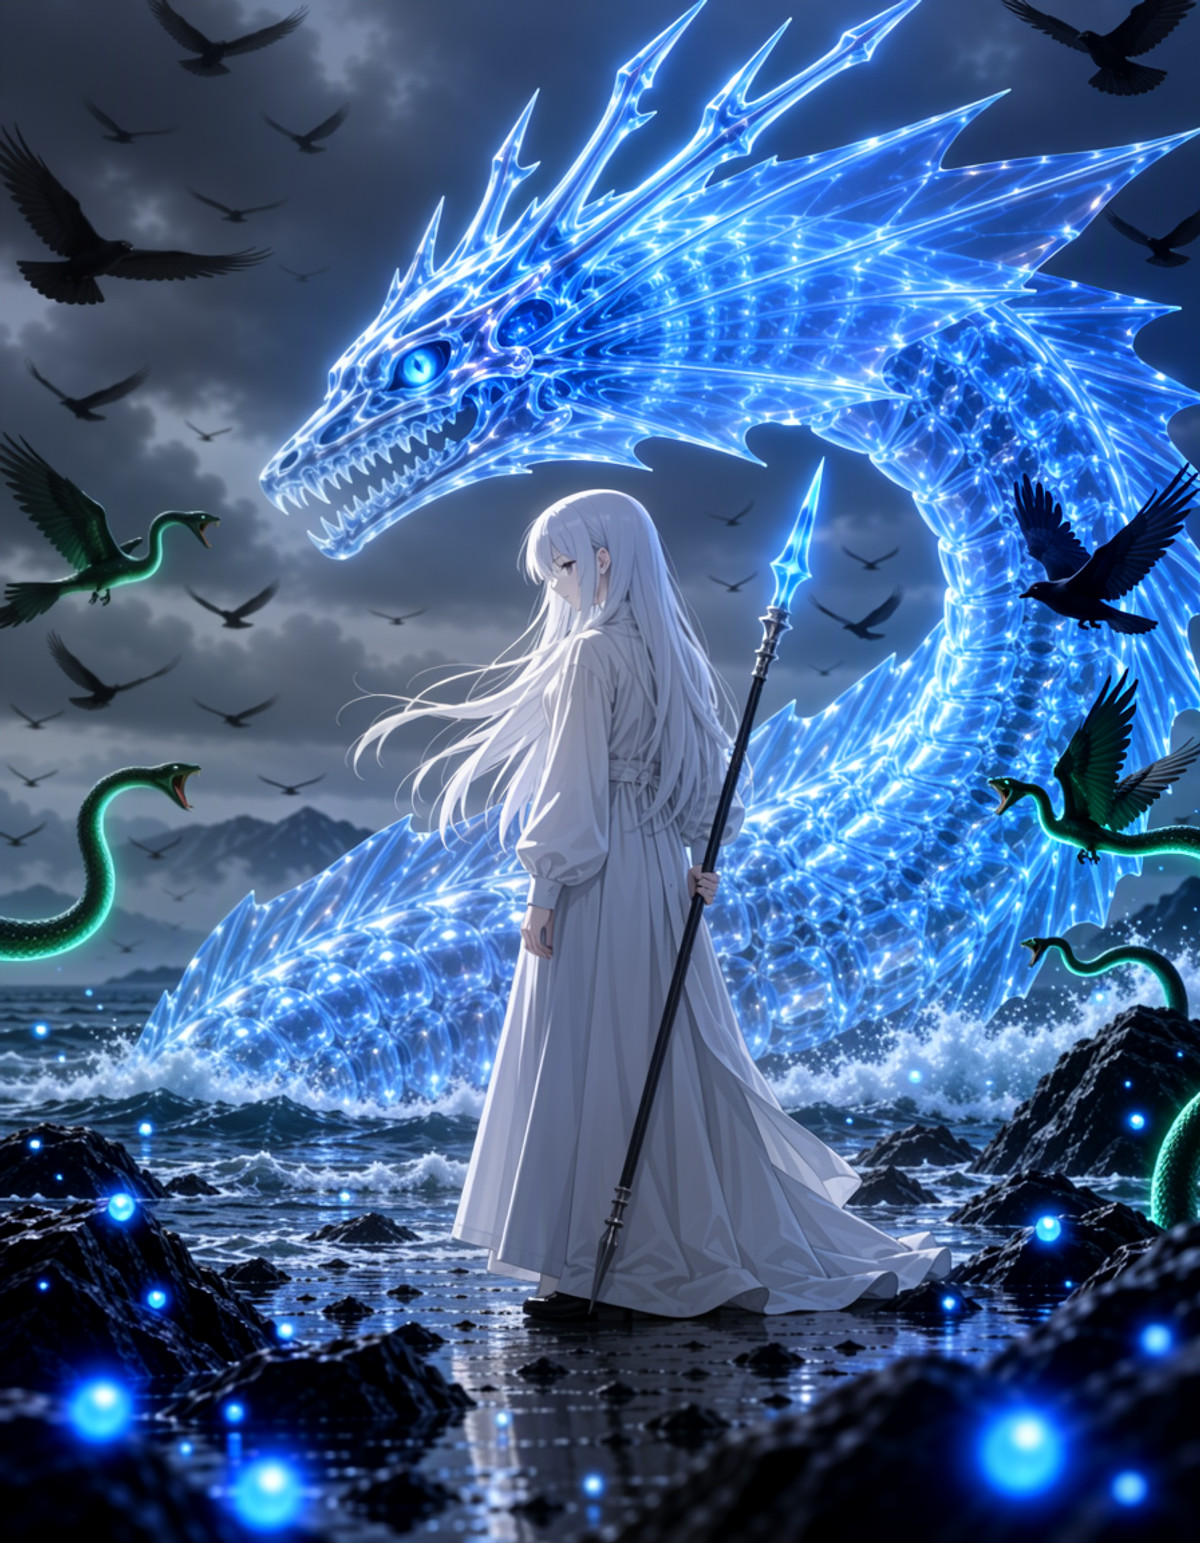
Reasons for Recommendation
- Ported: This style already has ten versions including Flux.1 D, Pony, Illustrious, Chroma, Anima, Z-Image, Klein, and Krea 2; this adds the MOSS version (named v1.5.1, belonging to the author's 1.5 branch which includes some synthetic data).
- Serves dark fantasy, monster/machinery/post-apocalyptic illustration themes, as well as adding 2.5D texture to anime characters.
- Trigger word is 86_(nononononoway); the author also registered a long descriptive style sentence (glossy texture, dramatic lighting, semi-realistic cel shading, low-saturation atmosphere, etc.), which is more stable for narrative-based base models; there are 9 visible examples.
How to Use
- Load nonono_moss-image_1mp_single30.safetensors, starting the prompt with 86_(nononononoway).
- To strengthen the style, append the author's registered long descriptive sentence; the author's suggested order for natural language base models is trigger word → natural language description → tags.
- The author did not provide strength, steps, or CFG settings for the MOSS version.
Risks and Limitations
- The full model card contains no MOSS-specific instructions; the long sentence approach is a suggestion for Klein / Krea 2 / Z-Image, serving only as a starting point for MOSS; the author did not write version notes.
- The author states uncertainty about whether the 1.5 branch is superior to 1.0; 11 sensitive-level examples are hidden, exceeding the number of visible examples; this entry was not run, and example images were not viewed.
Trigger Words: 86_(nononononoway), 86_(nononononoway) , The scene is rendered in the nononononoway digital illustration style characterized by its hyper-detailed glossy textures dramatic lighting and surreal elements. Painterly anime illustration with semi-realistic cel shading with soft painterly light and shadow, dramatic overcast atmospheric lighting, intricate detailed linework cinematic wide composition with strong scale contrast moody desaturated tones, high-detail digital illustration.
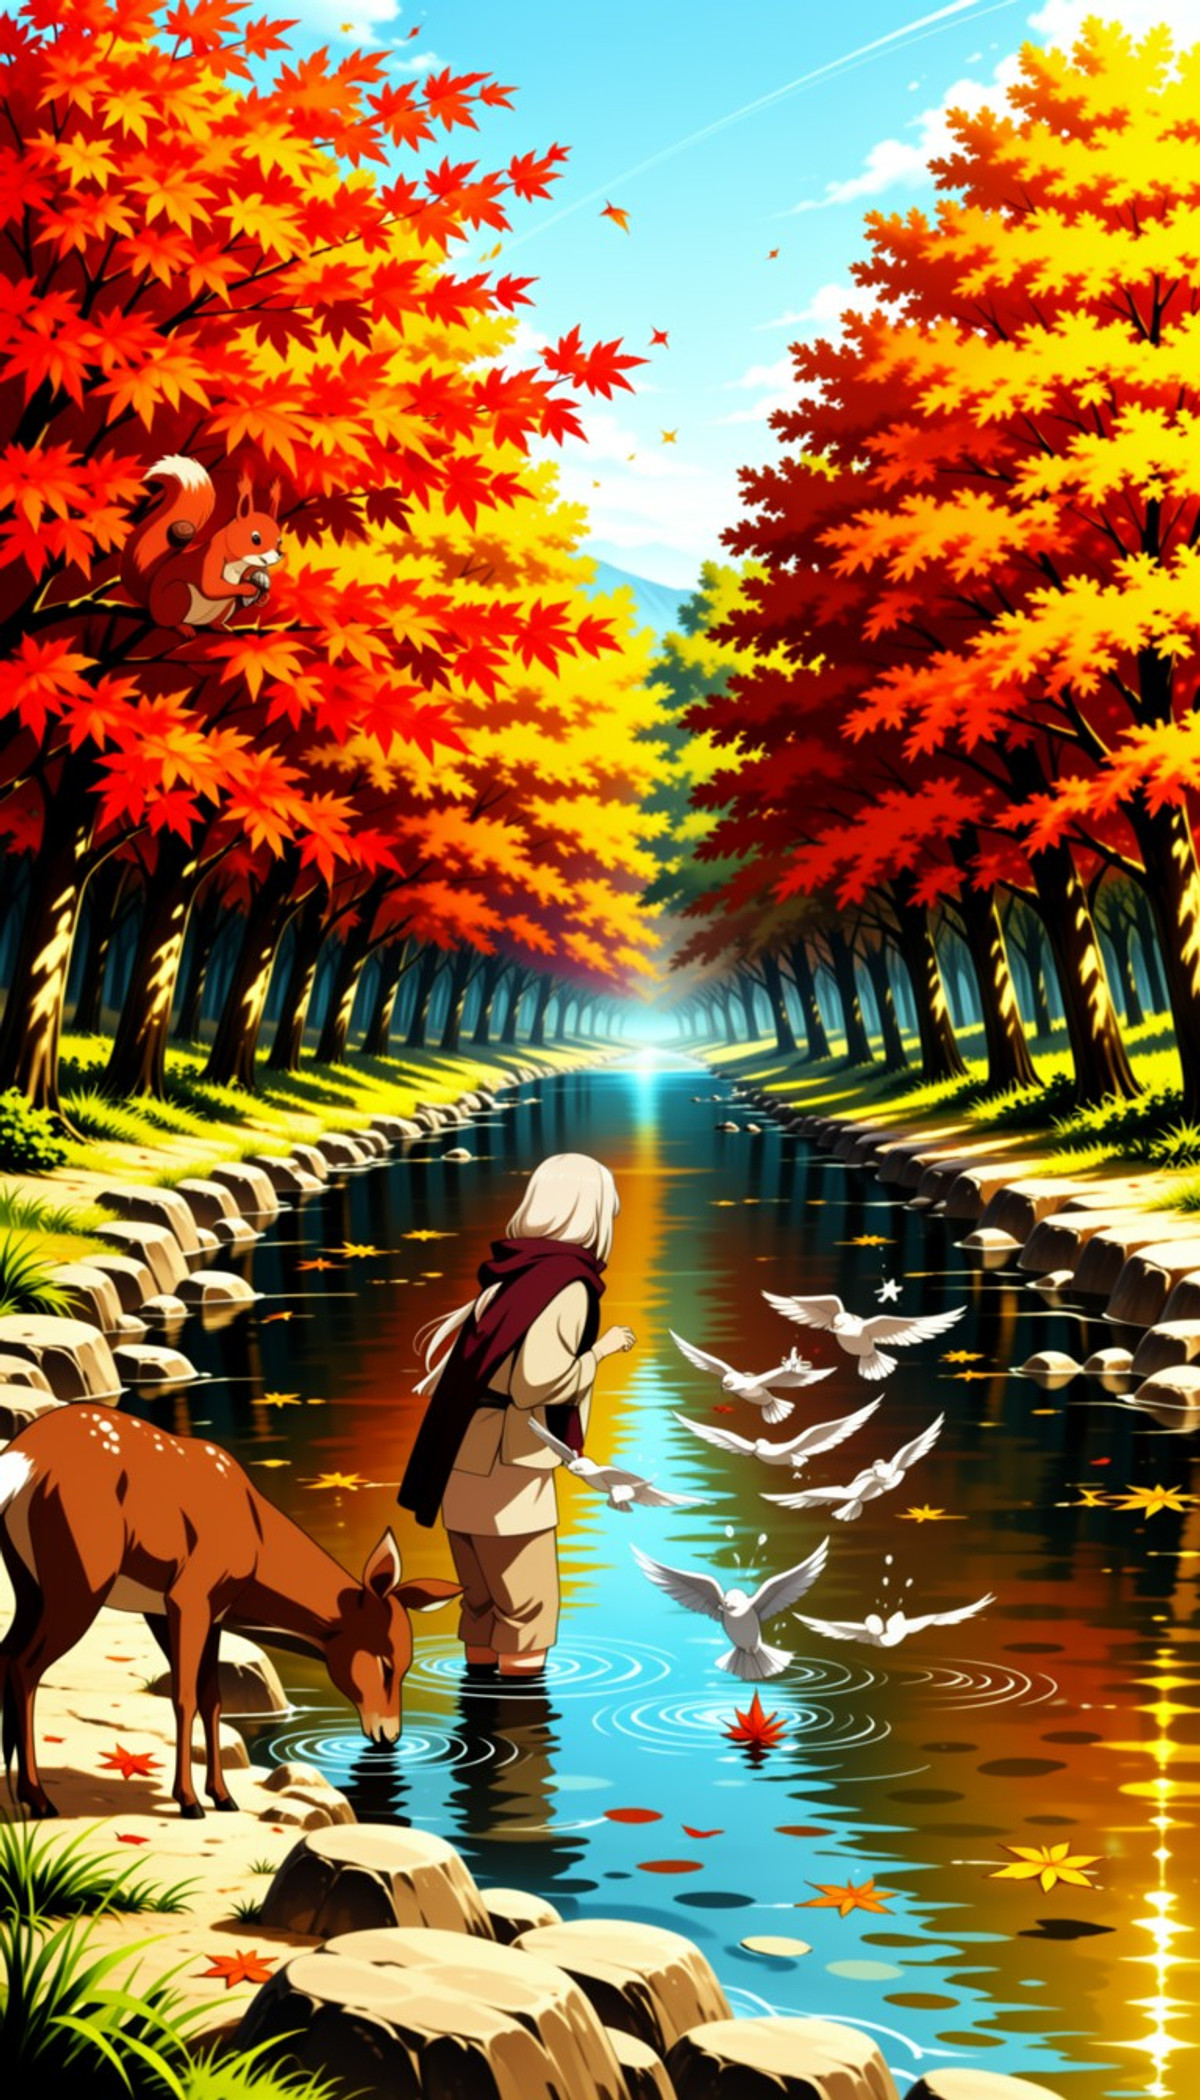
[A] Anime Screencap Style · v1
LoRA · New Model · Author kanakiy · Published 11-06 02:21 · Downloads 37
A style LoRA mimicking modern anime screencaps: the author describes flat cel shading, almost no soft shadows, thick clean lines, high saturation colors, and widescreen-style compositions, appearing 'flatter and harder' than the gradient shading of most anime models.
Images
Reasons for Recommendation
- New Model: An anime screencap style on MOSS, serving text-to-image generation for character art and scene images that look like 'TV anime frames'.
- There are 19 visible examples, with only 1 sensitive-level ones hidden, providing sufficient material to evaluate the effect.
- The author provides a strength setting: 0.6-0.8, explaining that because the training data includes Tsunade and Seiko Ayase, higher strengths tend to introduce features of these two characters.
How to Use
- Load animeScreencapStyle_v1.safetensors at strength 0.6-0.8; no trigger word.
- The author did not provide steps, CFG, or sampler settings.
Risks and Limitations
- Specific characters were mixed into the training set; if the strength is too high, character features may bleed into other outputs
- The description is very short, does not specify whether the base model is Base or SFT, and lacks inference parameters; this entry has not been run, and no example images have been viewed
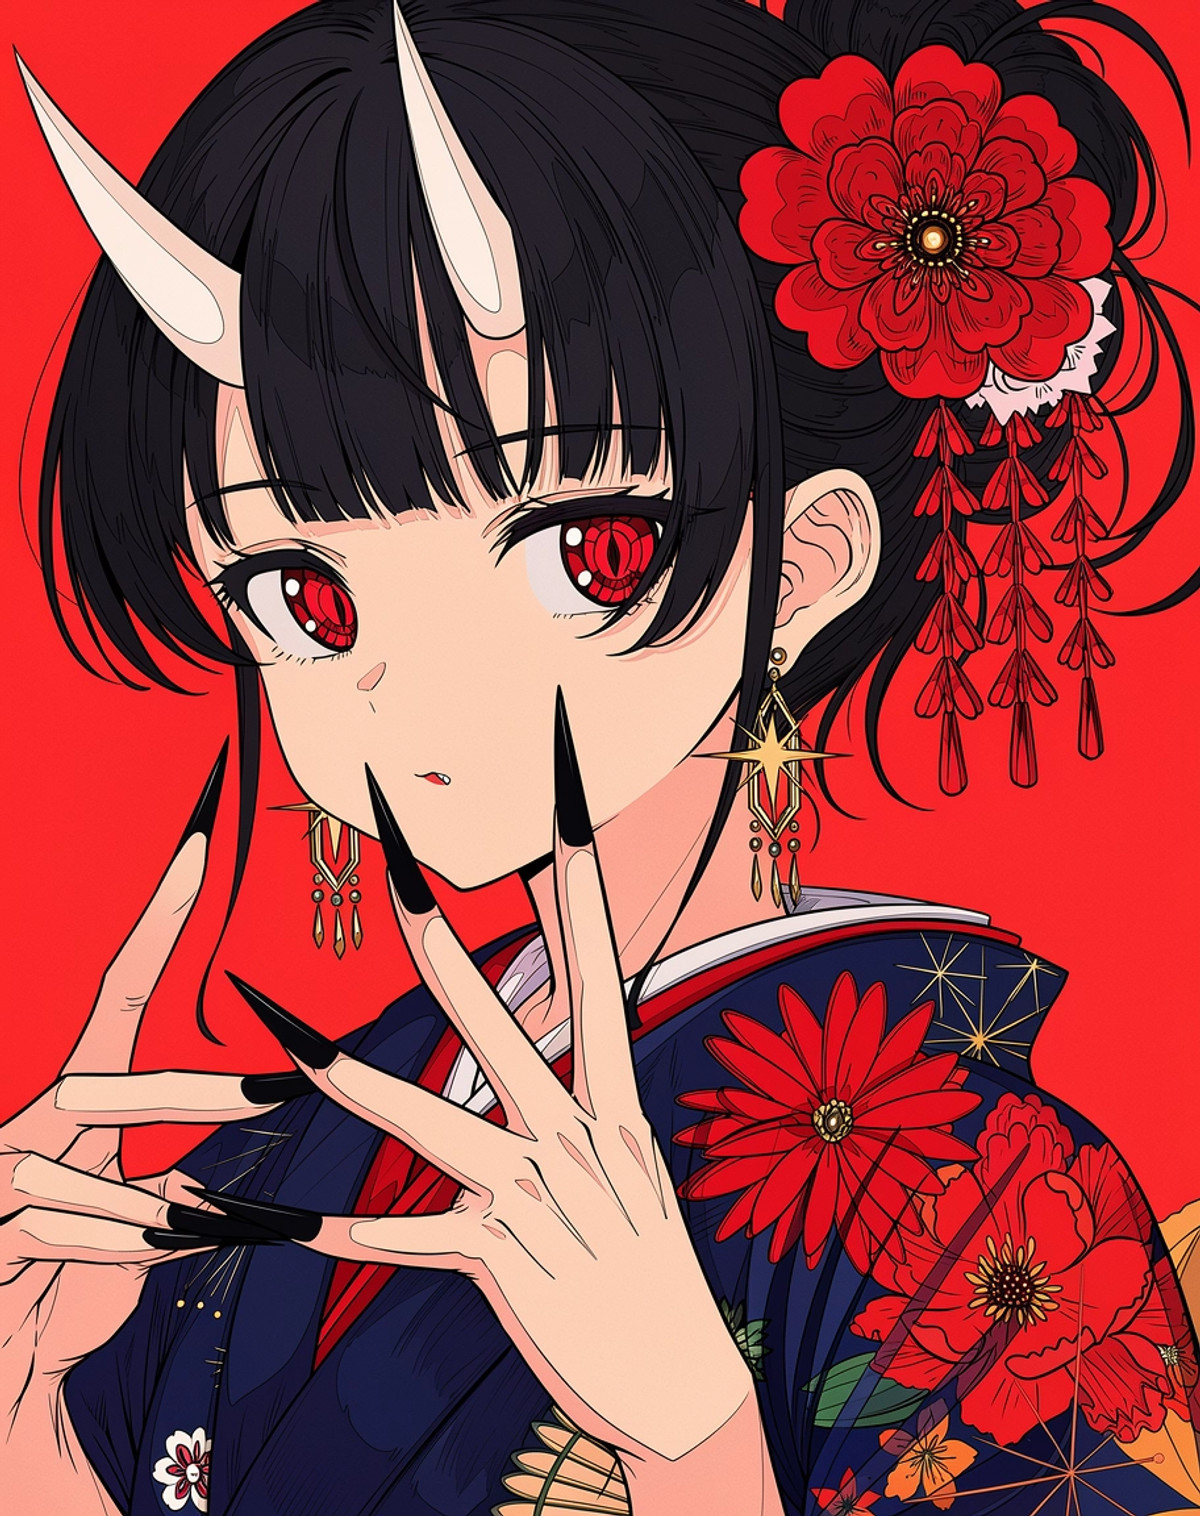
[A] Style: Ligne Claire · MOSS-base v1.0
LoRA · New Model · Author NerissG · Published 11-06 04:17 · Downloads 45
An anime / booru-style "Ligne Claire" LoRA: the author describes it as having clear ink outlines, thin and dense lines, and flat colors, trained on MOSS Base.
Images
Reasons for Recommendation
- New model: serves text-to-image anime illustrations in a Ligne Claire comic style, featuring dense lines and flat colors
- No trigger word is required during training, but the author provides a prompt to enhance the style: illustration in a ligne claire style. Distinctive ink outlines creating a busy lineart. Flat color. Thin busy lines.
- The author suggests stacking a detail slider LoRA if you want more lines and a fuller composition; 7 visible examples are available
How to Use
- Load LigneClaire_MOSS-base_v1.safetensors (small file size), using MOSS Base as the base model
- Add the Ligne Claire description above to your prompt; stack a detail slider for denser lines
- Strength, steps, and CFG are not provided by the author
Risks and Limitations
- The author states they are not yet satisfied: the style does not hold well for content outside the training distribution
- The license requires attribution; 6 sensitive-level examples are hidden; this entry has not been run, and no example images have been viewed
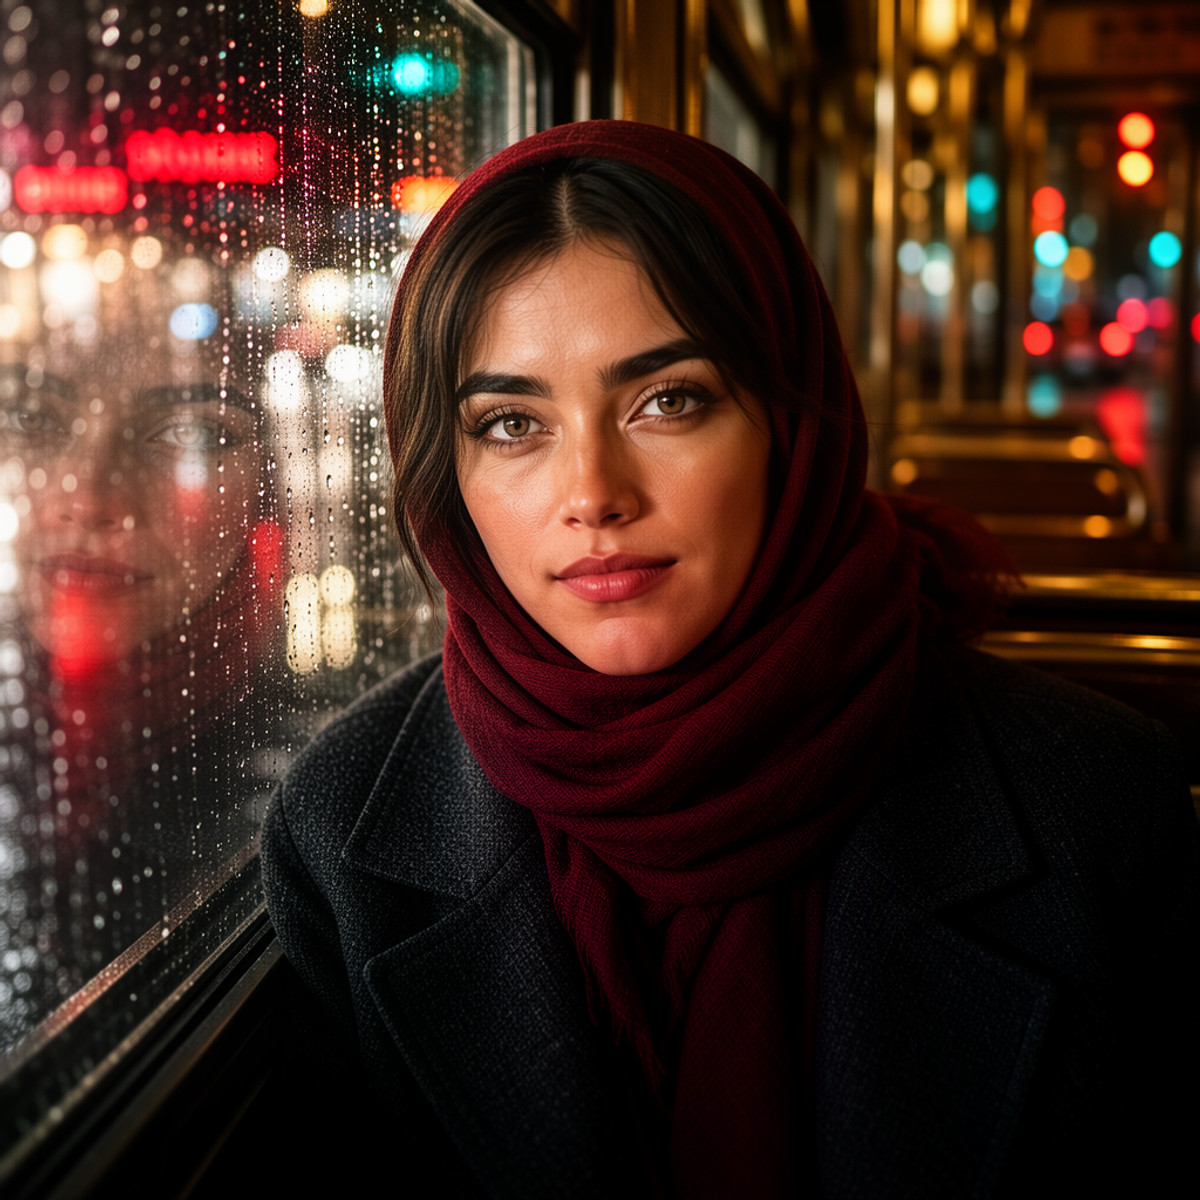
[A] Natural Faces · MOSS-BASE
LoRA · Version Update · Author fyrtyv · Published 11-06 08:15 · Downloads 16
A MOSS Base version of the facial detail / skin texture slider LoRA: positive strength brings out skin details like pores, freckles, and fine lines (the author compares it to "removing beauty filters"), while negative strength makes the skin smoother and softer; the author claims it works during generation, not as post-processing sharpening or smoothing.
Images
Reasons for Recommendation
- Version update: the previous version v2-MOSS-SFT was for MOSS SFT; this update note simply says v2 for MOSS-BASE, meaning the same v2 scheme was retrained on MOSS Base
- Serves realistic portrait text-to-image by controlling the "filter effect": the same prompt can adjust between more realistic skin and smoother skin
- Actionable: trigger word naturskinx, recommended starting strength +1.0, the author tested a range from −1 to +2, and effects stop changing around negative strength -1.0
How to Use
- Use MOSS Base as the base model, load naturskinx-moss-image-base-epoch-06.safetensors, and include naturskinx in the prompt
- Start with strength +1.0: increase for more skin detail, decrease towards negative for smoother skin; no additional effect beyond -1.0
- Steps and CFG are not provided by the author
Risks and Limitations
- This version has only 1 visible examples (3 sensitive-level examples are hidden), making it difficult to preview the Base version's effect
- The trigger word naturskinx is mentioned in the description, but this version does not register a trigger word; users of SFT should choose the previous version v2-MOSS-SFT; this entry has not been run
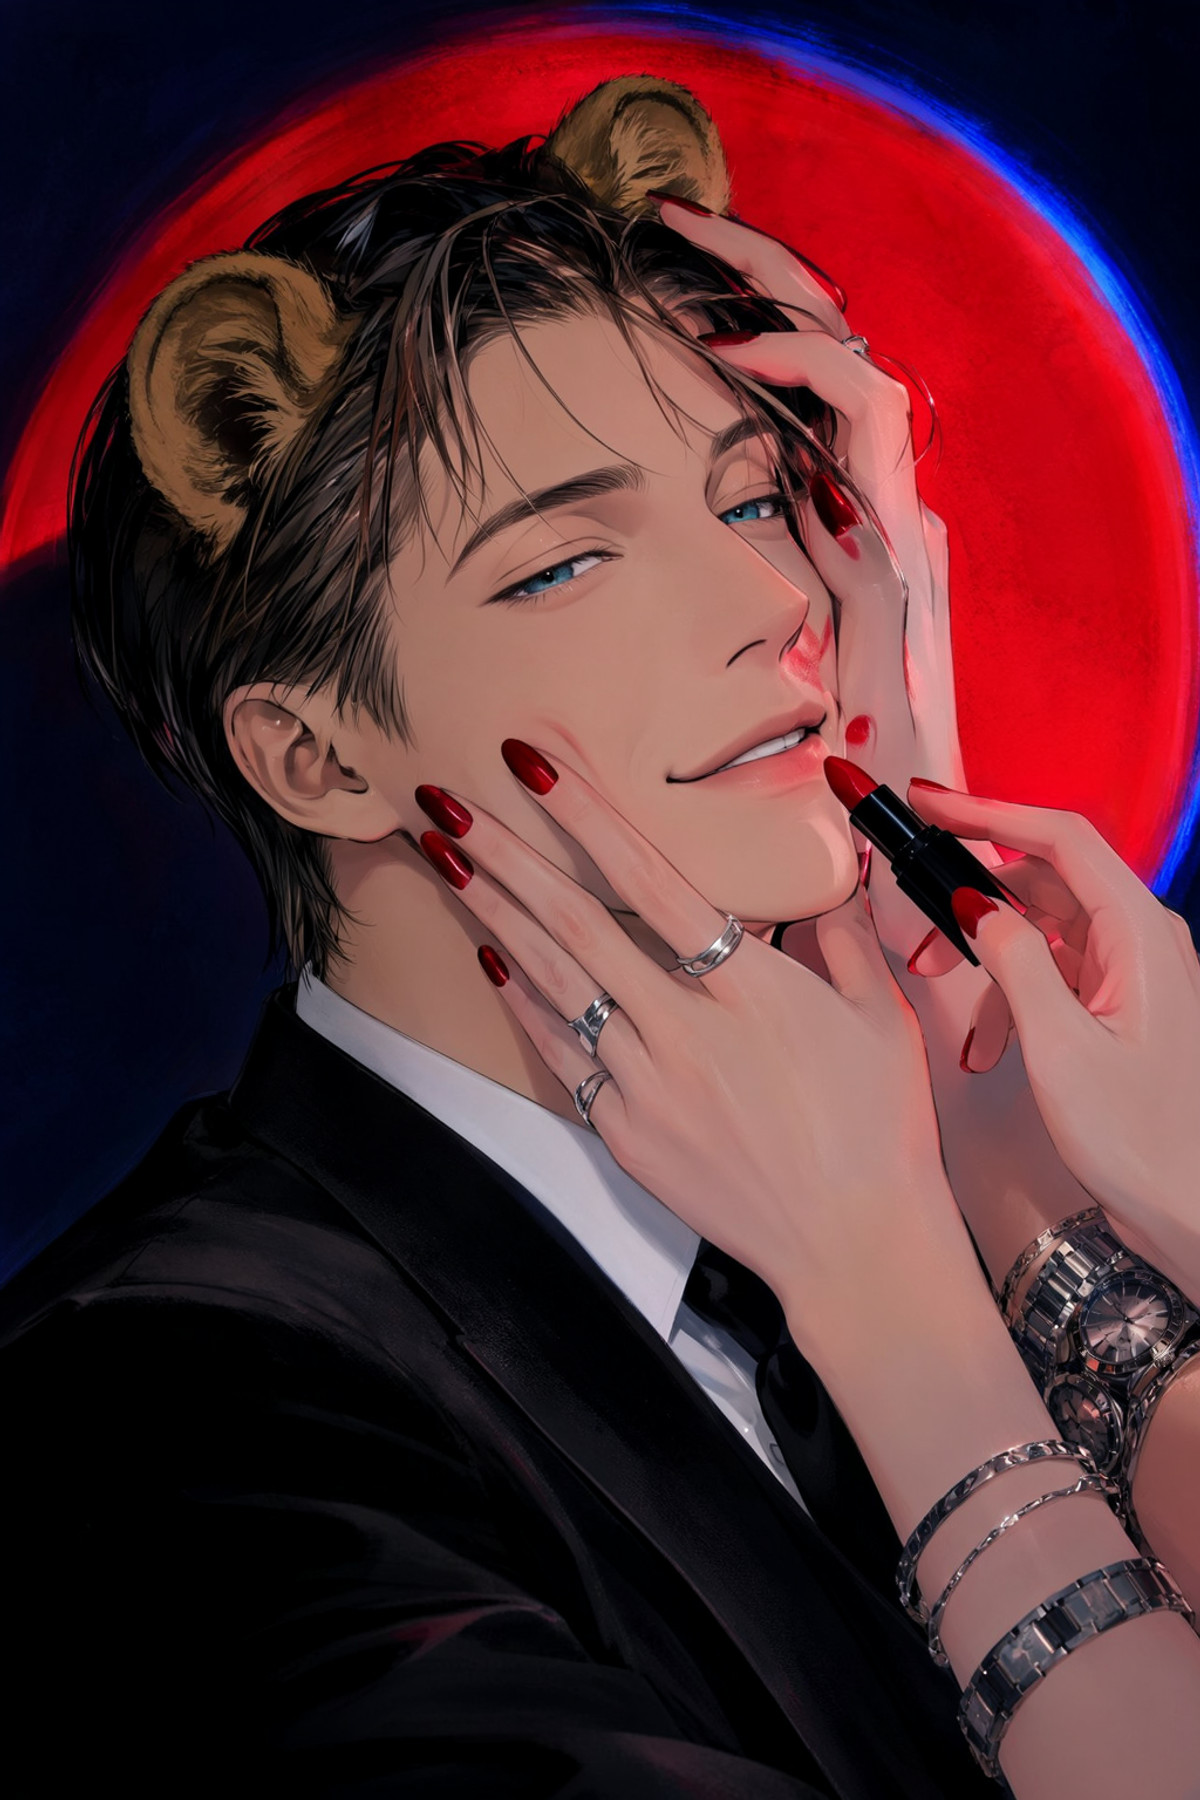
[A] Yayayoshi Style [Anima/Krea2/MOSS] · MOSS v1.0
LoRA · Port · Author Imagine__That · Published 11-05 21:41 · Downloads 51
The MOSS version of the Yayayoshi artist style LoRA: the author describes it as a heavy-line Josei (women's) style, drawing beautiful women and handsome men; ported from the Krea 2 / Anima version.
Images
Reasons for Recommendation
- Port: the same style already exists for Krea2 v1.0 and Anima v1.0; this adds MOSS v1.0, but the version notes are empty, with no explanation of differences from older versions
- Serves character text-to-image in Josei manga / illustration styles
- Trigger word @yayayoshi, recommended strength 0.8-1.00 when used alone; 4 visible examples
How to Use
- Load yayayoshi-lora2k-nb22-comfy.safetensors, strength 0.8-1.00 (the author implies lowering it when stacking with other LoRAs)
- Include @yayayoshi in the prompt (the registered trigger word is yayayoshi without the @; the author does not explain the difference between the two forms)
- Steps and CFG are not provided by the author
Risks and Limitations
- The entire model card is only three lines, with no MOSS-specific parameters; the author did not write version notes
- 5 sensitive-level examples are hidden, more than the visible examples; this entry has not been run, and no example images have been viewed
Trigger Word: yayayoshi
[A] HaDeS MOSS Turbo · v0.6 Diverse - 4steps
LoRA · Version Update · Author _HaDeS_ · Published 11-05 22:36 · Downloads 107
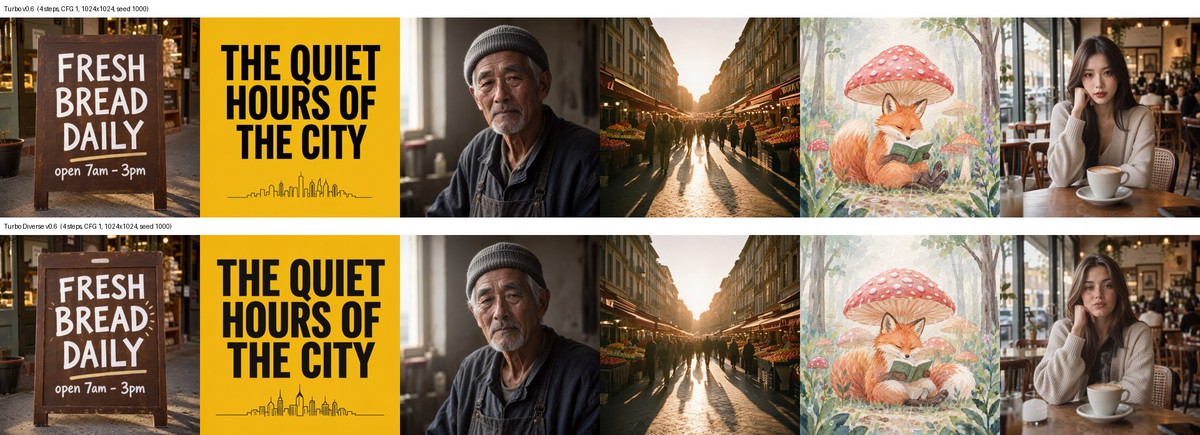
The 4-step acceleration LoRA v0.6 Diverse from the HaDeS MOSS Turbo series: like the v0.6 on the same page, it is self-trained by the author, 3.4 MB, and generates images in 4 steps; the difference is that the author claims it retains more of the original SFT diversity (faces, poses, props) under open-ended prompts.
Images
Reasons for Recommendation
- Version update: released after v0.6, with the update note simply saying v0.6 Diverse; the trade-off is that v0.6 is more stable for text, while Diverse produces less uniform images
- Serves fast image generation for MOSS SFT, suitable for batch character generation, sketches with varied compositions, or gacha-style sampling; the author recommends v0.6 for text layout tasks
- Parameters are the same as v0.6: 4 steps, CFG 1, euler + simple, shift 5, strength 1.0; this version has 107 downloads, the highest among versions on this model page (indicating attention only)
How to Use
- Base model MOSS-Image SFT, load HaDeS-MOSS-Turbo-Diverse-v0.6.safetensors using LoraLoaderModelOnly, strength 1.0; no trigger word
- 4 steps, CFG 1, euler + simple, shift 5; or use the MOSS Turbo LoRA node from the HaDeS MOSS Suite connected to the turbo input of MOSS KSampler
Risks and Limitations
- The author claims that at 4 steps, colors are 6–10% (1024) / 6–14% (2048) lighter than SFT at 25 steps; 8 steps can return to near-SFT levels; the claim of better diversity than v0.6 lacks specific numbers
- Tested only on SFT; only 2 examples; the license does not allow publishing derivative / merged models and requires attribution; this entry has not been run
[A] HaDeS MOSS Turbo · HaDeS v0.7 Turbo 8 Steps
LoRA · Version Update · Author _HaDeS_ · Published 11-06 05:18 · Downloads 61
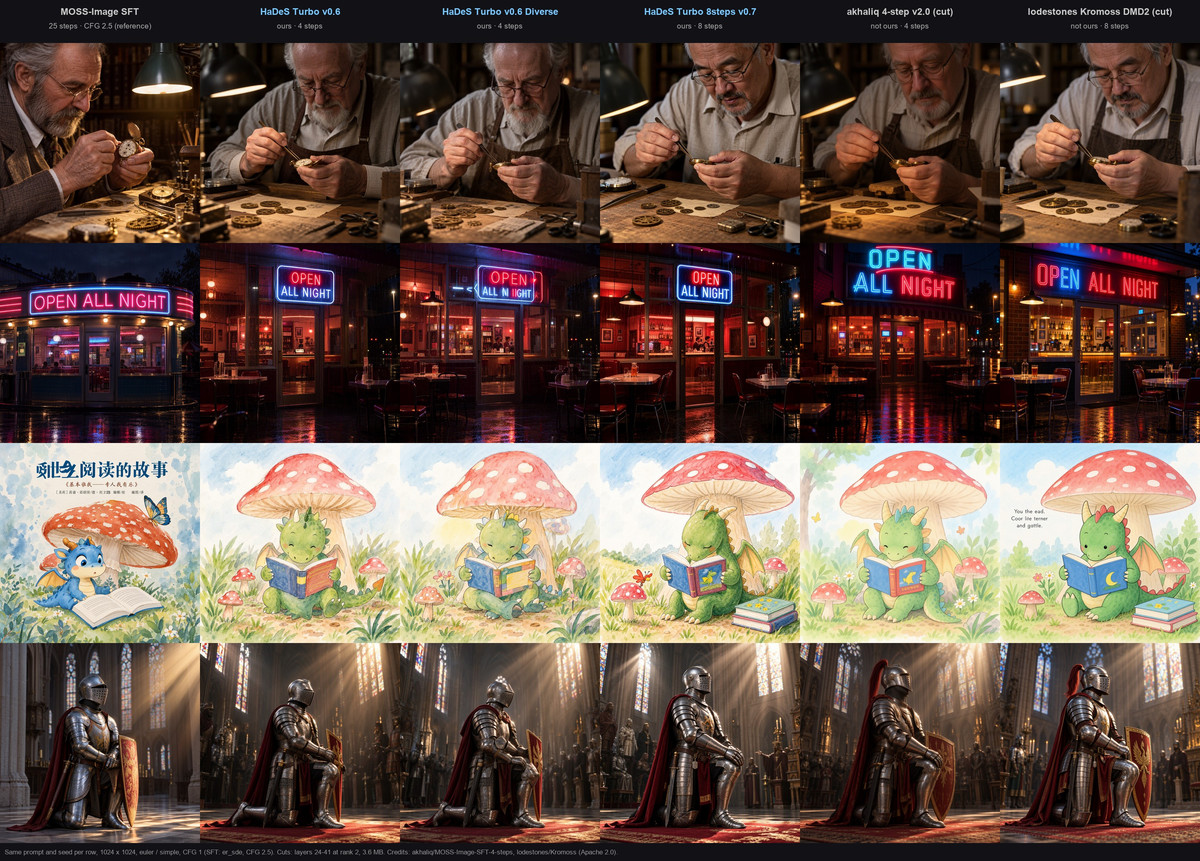
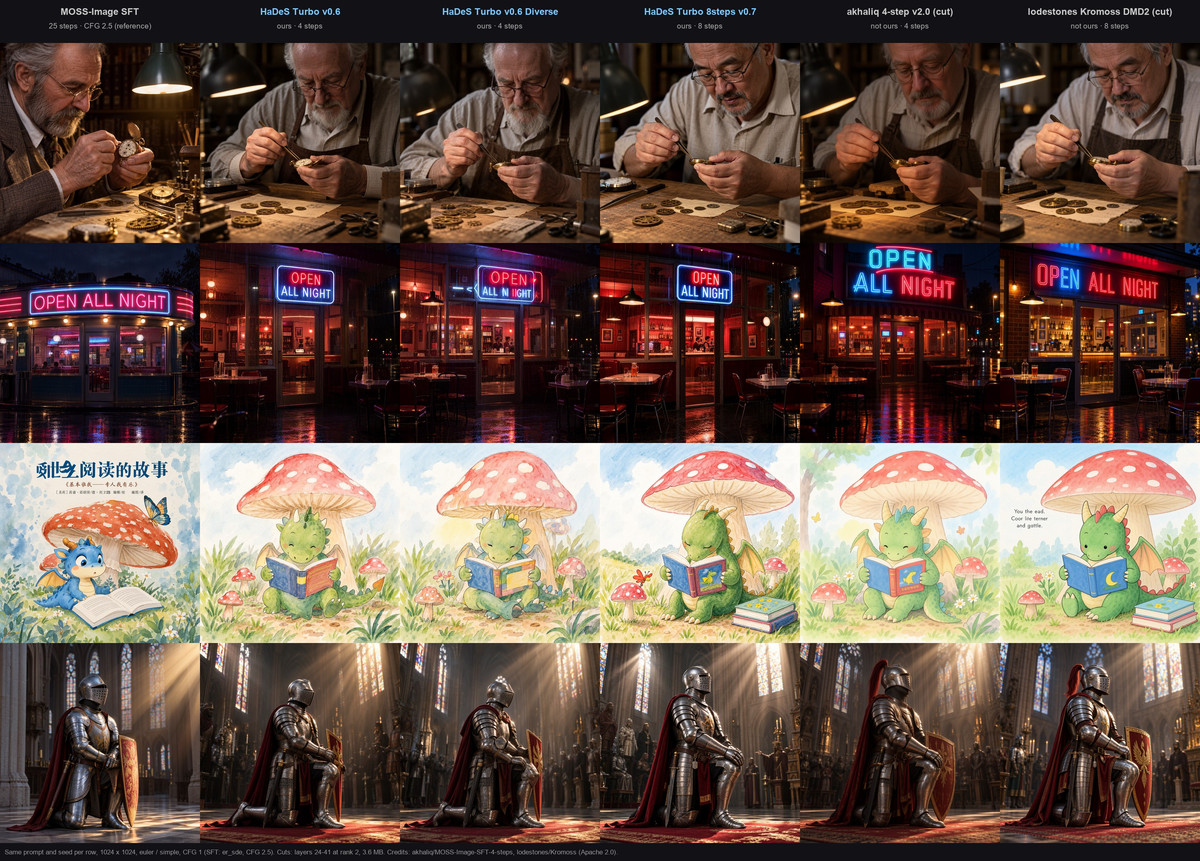
The 8-step acceleration LoRA v0.7 from the HaDeS MOSS Turbo series: self-trained by the author, 3.4 MB, for MOSS-Image SFT to generate images in 8 steps, up to 1024 px; the author claims it won against akhaliq's original 4-step LoRA in pairwise blind tests, and tied or slightly beat lodestones' 8-step LoRA at 1024.
Images
Reasons for Recommendation
- Version updates: Both v0.6 versions on the same page use 4 steps, while v0.7 switches to a 8-step approach; the author states that in blind evaluations using 8 steps and 20 prompt groups, it defeated akhaliq's 4-step LoRA (full 1.2 GB file) with a score of 18 to 5. At 1024, it scored 10 to 7 against lodestones' Base / Kromoss 8-step LoRA, but lost 0 to 5 at 2048.
- Supports fast image generation at the MOSS SFT 1024 level; for 2048 large images, the author's comparison shows that the lodestones version performs better (a 3.6 MB cropped version is available on the same page).
- Complete parameters: 8 steps, CFG 1, euler + simple, shift 5, strength 1.0, with resolution not exceeding 1024 px
How to Use
- Base model MOSS-Image SFT, load HaDeS-MOSS-Turbo-v0.7a-u3000.safetensors using LoraLoaderModelOnly, strength 1.0; no trigger word
- 8 steps, CFG 1, euler + simple, shift 5, keep resolution within 1024 px; or use the MOSS Turbo LoRA node from the HaDeS MOSS Suite, setting steps to 8
Risks and Limitations
- The author did not write update notes; the actual filename is v0.7a-u3000, which is inconsistent with HaDeS-MOSS-Turbo-8steps-v0.7.safetensors listed on the model card, and the author did not explain
- The 8-step performance at 2048 is a weakness listed by the author; all blind test numbers are self-tested by the author
- Tested only on SFT; only 1 examples; the license does not allow publishing derivative / merged models and requires attribution; this entry has not been run
[A] HaDeS MOSS Turbo · V0.6 - 4steps
LoRA · New Model · Author _HaDeS_ · Published 11-05 22:34 · Downloads 44
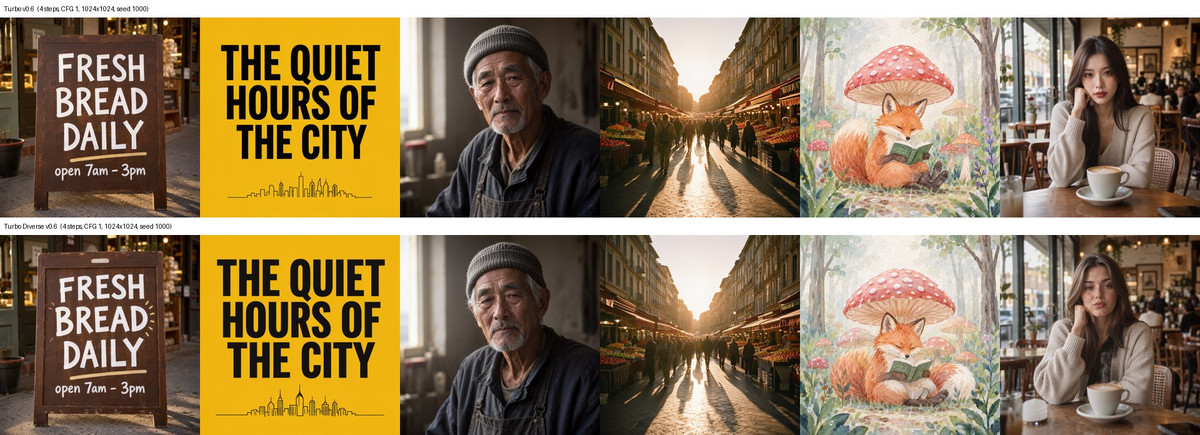
The 4-step acceleration LoRA v0.6 from the HaDeS MOSS Turbo series: a few-step LoRA for MOSS-Image SFT trained from scratch by the author, with a file size of only 3.4 MB (rank 2, affecting only layers 24–41); the author claims it is the most stable version for text in this series at 4 steps.
Images
Reasons for Recommendation
- New model: this is the first version on this model page; the same page also has v0.6 Diverse (4 steps, diversity priority) and v0.7 (8 steps), both self-trained LoRAs by the author, as well as 3.6 MB cropped versions of the community LoRAs akhaliq 4 steps and lodestones 8 steps
- Serves fast image generation for MOSS SFT, especially for layouts and posters with text; the author claims it passed all tests for layout JSON and 16:9 three-line posters in self-tests
- Complete parameters: 4 steps, CFG 1, euler + simple, model shift 5, strength 1.0; after installing HaDeS MOSS Suite, you can connect the MOSS Turbo LoRA node to the turbo input of MOSS KSampler, or use native LoraLoaderModelOnly + KSampler
How to use
- Base model MOSS-Image SFT, load HaDeS-MOSS-Turbo-v0.6.safetensors via LoraLoaderModelOnly, strength 1.0; no trigger word
- 4 steps, CFG 1, euler + simple, shift 5; or use the MOSS Turbo LoRA node from the HaDeS MOSS Suite, set steps to 4
Risks and limitations
- The author states that at 4 steps, colors are 6–10% paler than SFT at 25 steps (1024 resolution), and 6–14% paler at 2048; running 8 steps can restore colors close to SFT; small text is a known weakness at 2048 x 2048
- Tested only on SFT; Base, fine-tuned models, merged models, other strengths, and image-to-image were not tested; all comparison figures are the author's self-tests
- Only 2 sample images; the license does not allow publishing derivative / merged models and requires attribution; this entry was not run
[A] Vintage Drawing - CE · V01a - MossImage Base/SFT
LoRA · Port · Author CreativeEdge · Published 11-06 01:24 · Downloads 55
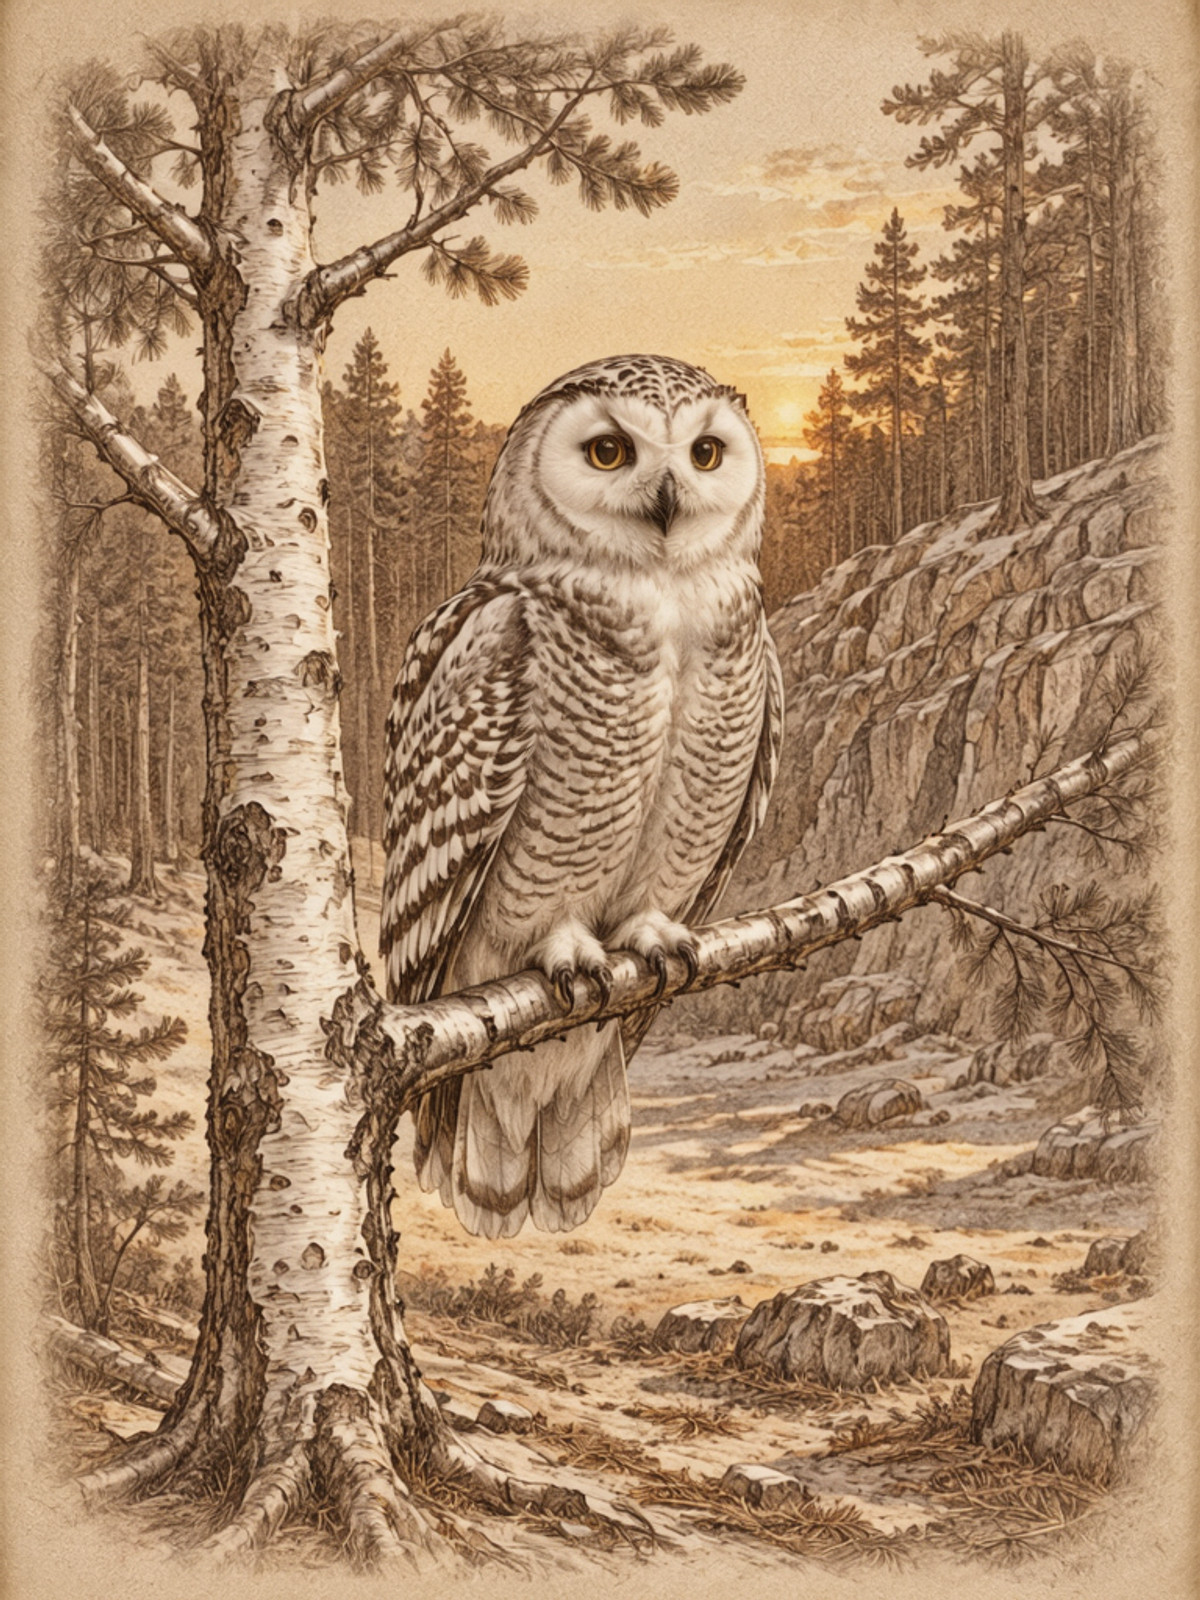
The MOSS version of CreativeEdge's long-standing Vintage Drawing style LoRA: transforms images into the texture of old pencil / copperplate illustrations on yellowed paper, with visible examples covering animals, landscapes, architecture, still life, and people.
Image
Reasons for recommendation
- Port: This style previously had versions for SDXL, Flux.1 D, Qwen, Z-Image (Base / Turbo), Flux.2 Klein, Krea 2, etc.; this adds the MOSS version; the author claims it was trained on the original (raw) version, usable with both the original and Turbo, with all examples generated using the original
- Serves text-to-image for illustration, picture books, and retro posters: from visible examples, it is a sepia monochrome, old-book illustration style with prominent hatching, suitable for various subjects
- The 6 visible examples cover diverse subjects, allowing assessment of style stability across themes; the model page has accumulated 5187 downloads, indicating a long-term audience for this style, but this does not guarantee the quality of the MOSS version
How to use
- Just load the LoRA; the MOSS version has no registered trigger word; the author does not specify if the trigger word vntgdrwngCE_style from the old Krea 2 version works for the MOSS version
- The author does not provide strength, steps, or CFG for the MOSS version; the version name indicates Base/SFT, and it can be attached to either base model
Risks and limitations
- The author did not write version notes; the model card contains only a one-sentence style description, with zero MOSS-specific parameters; strength suggestions from older versions (Qwen version 0.8, Flux version 1.0-1.4) may not apply
- The license does not allow publishing derivative / merged models; 1 sensitive-level examples are hidden; this entry was not run
Worth Watching (16)
[B] MOSS Anime Acrylic Marker · v1.0
LoRA · New Model · Author _Envy_ · Published 11-06 05:57 · Downloads 27
Anime-style acrylic marker style LoRA: the model card only says "An anime style acrylic marker lora," so specific visual characteristics can only be judged from the examples.
Image
[B] MOSS 12 Step Turbo · v5_0
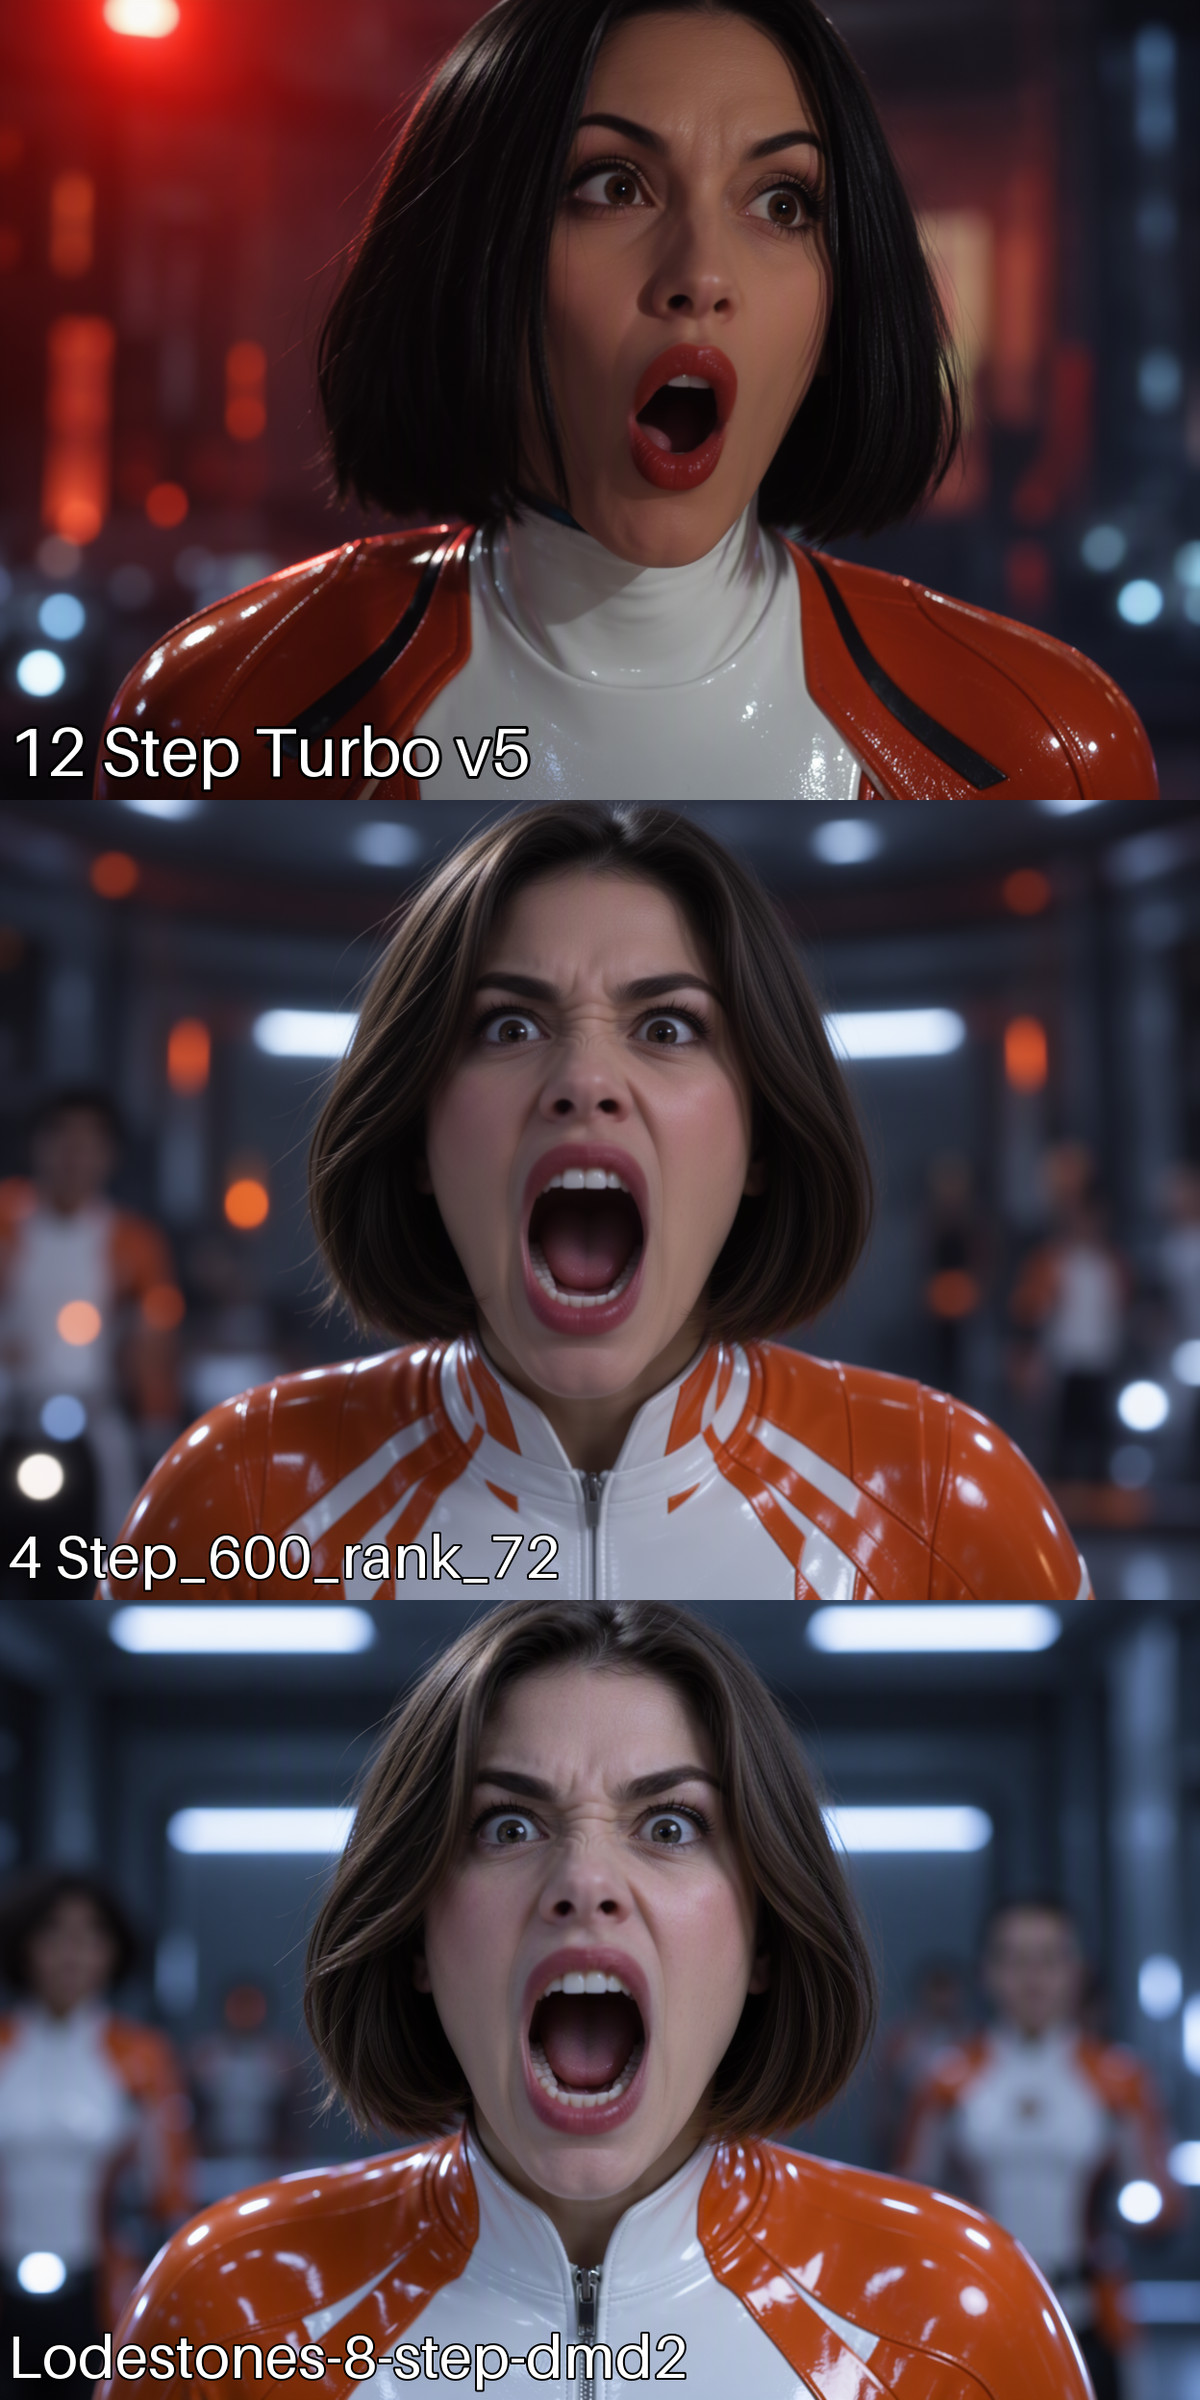
LoRA · Version Update · Author anyMODE · Published 11-06 05:58 · Downloads 90
The second version (v5_0) of anyMODE's 12-step MOSS acceleration LoRA: positioned as a compromise between low step counts and image quality, the author recommends 12 steps, and this version provides three sizes: full, r64, and r32.
Image
[B] cocoamix zero MOSS Image · turbo v1.0
Base Model / Checkpoint · New Model · Author CCOaaOCC · Published 11-05 23:54 · Downloads 78
The Turbo version of the cocoamix zero MOSS merged base model: the author states it is a merge of MOSS-Image + 8-step DMD2 acceleration LoRA + the author's self-trained model, with INT8 full weights around 5 GB; there are no instructions other than the merge list.
Image
[B] (moss-image) 6in1, The Magical Revolution of the Reincarnated Princess and the Genius Young Lady, anisphia wynn palettia + euphyllia magenta + ilia coral + lainie cyan + tilty claret + lumielle_rene_palettia · anisphia-v1.0
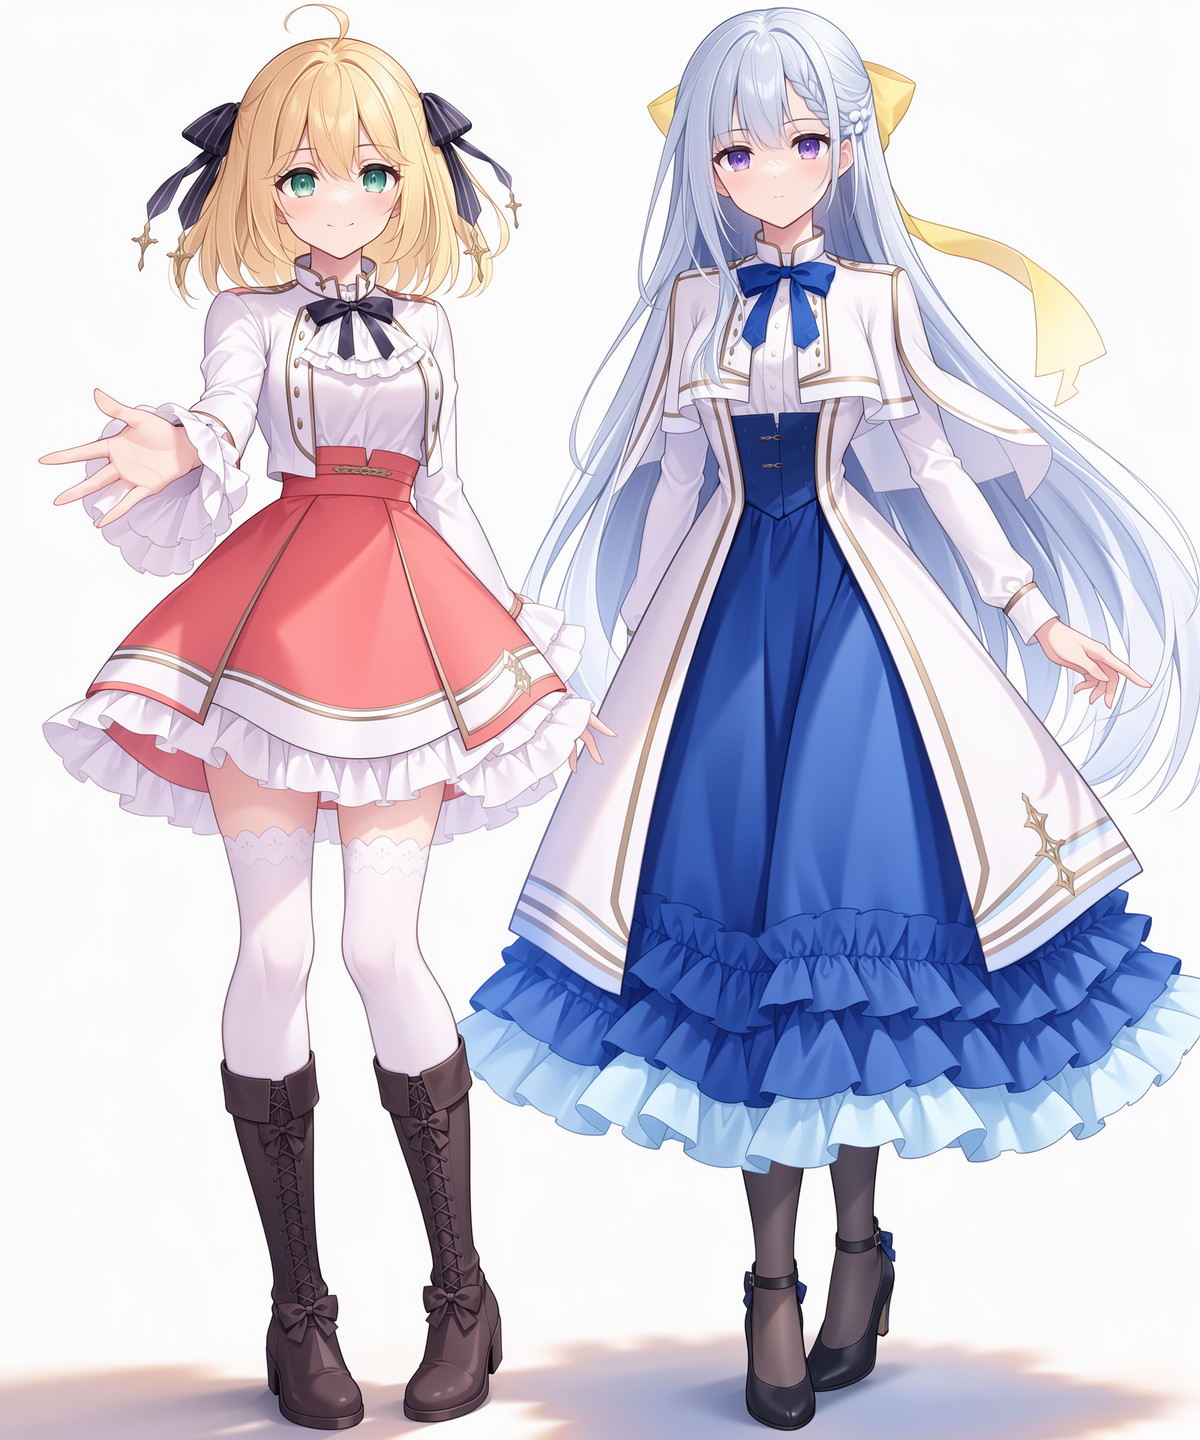
LoRA · New Model · Author k5664335664 · Published 11-06 01:58 · Downloads 44
A 6-character collection LoRA for the anime "The Magical Revolution of the Reincarnated Princess and the Genius Young Lady": one file includes Anisphia, Euphyllia, Ilia, Rene, Tilty, and Lumiere 6 characters, and the author provides natural language prompts for two-character compositions.
Image
[B] AuthentiQ onesie: Bison [Krea2] · MOSS_SFT_v1.0
LoRA · New Model · Author AuthentiQ · Published 11-06 03:02 · Downloads 35
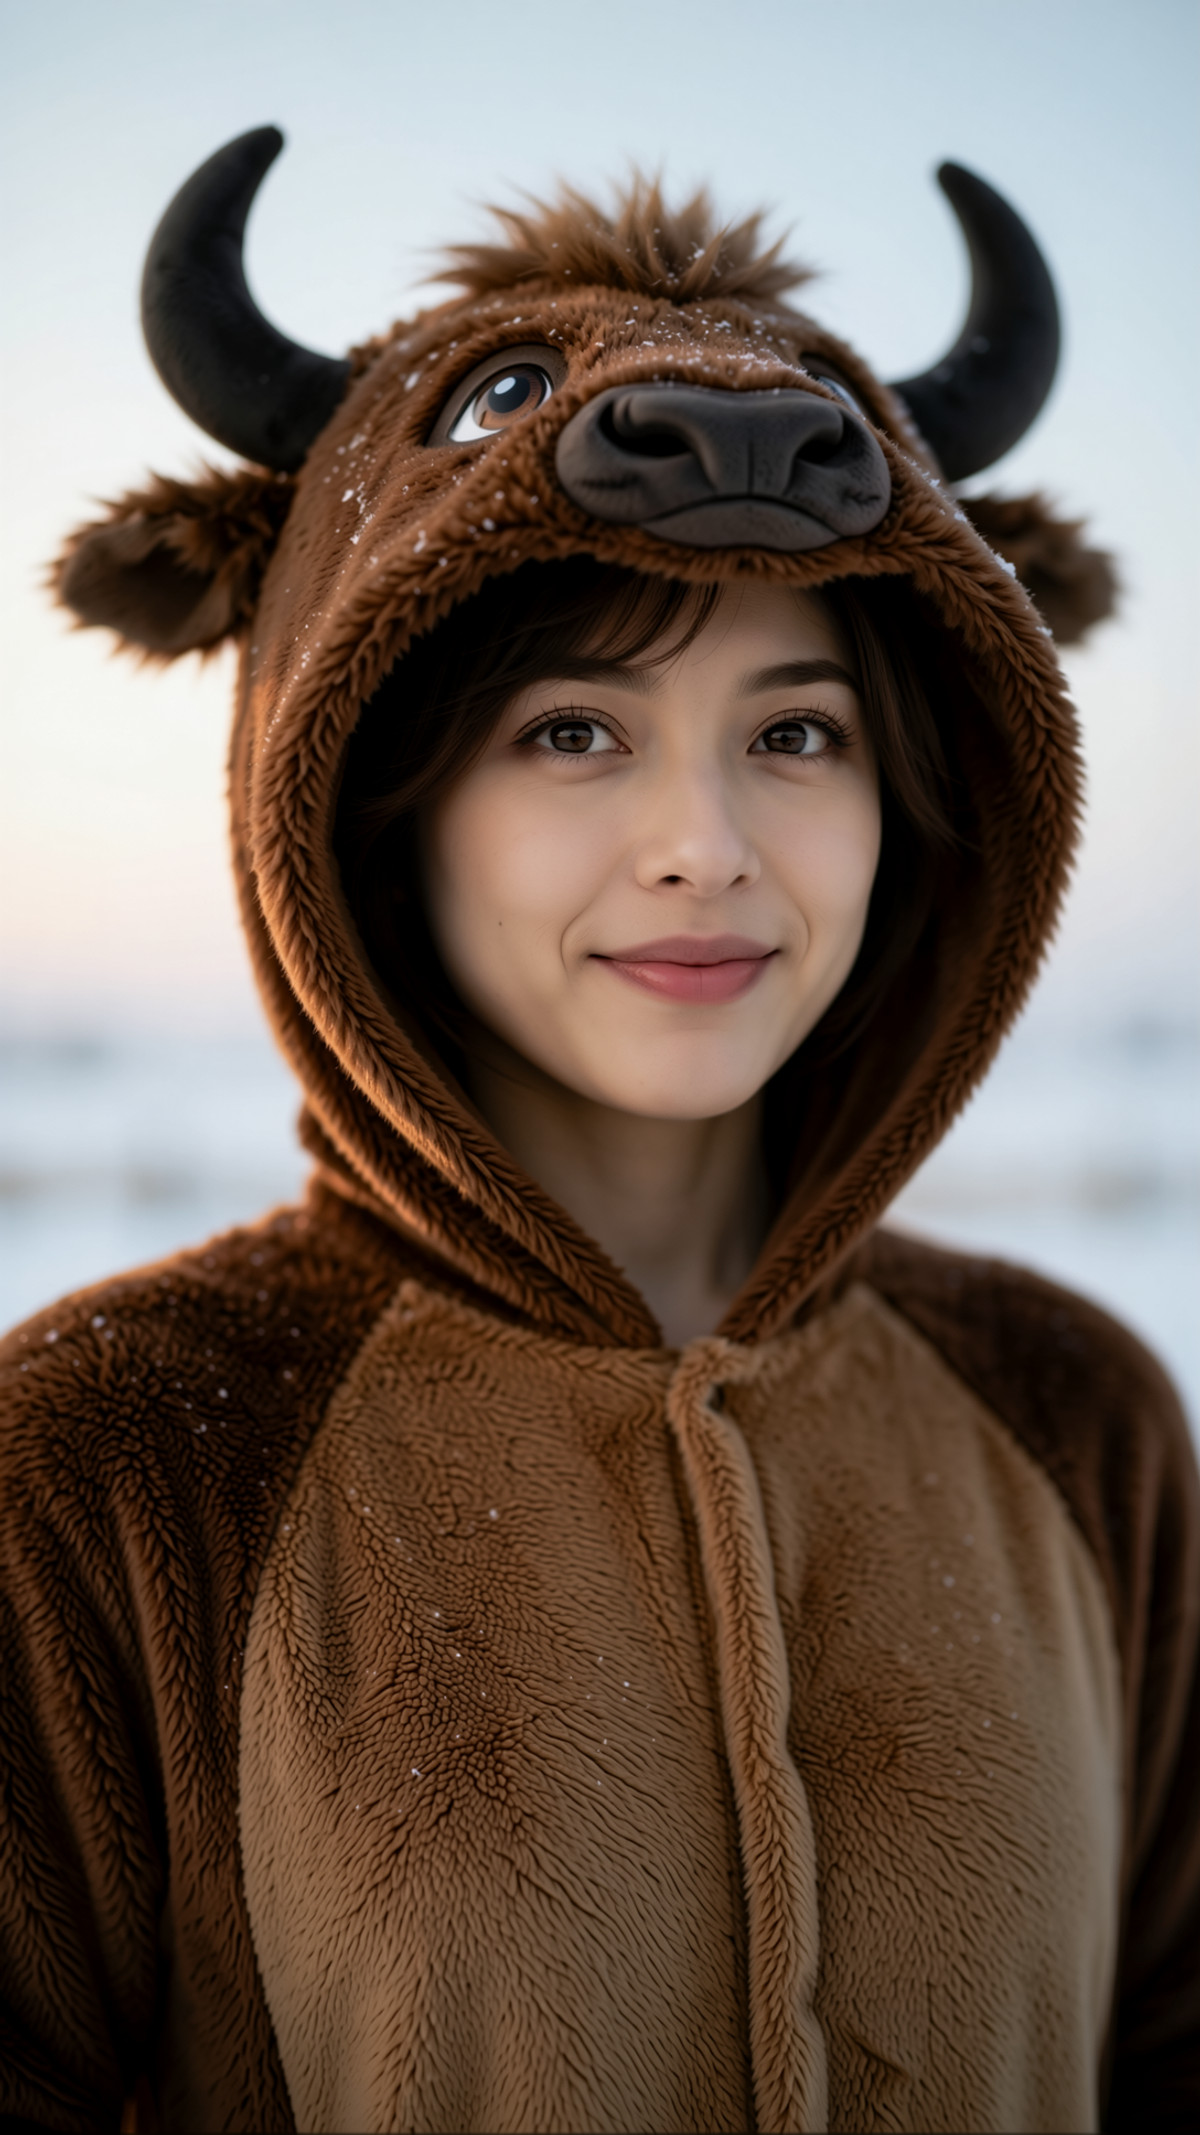
A realistic-style bison kigurumi (onesie) clothing LoRA: puts characters in a brown fluffy onesie with a horned hood, part of the author's "animal onesie" series.
Image
[B] Reacting to Cold · MOSS v0.07
LoRA · Port · Author Invisidude · Published 11-06 02:46 · Downloads 84
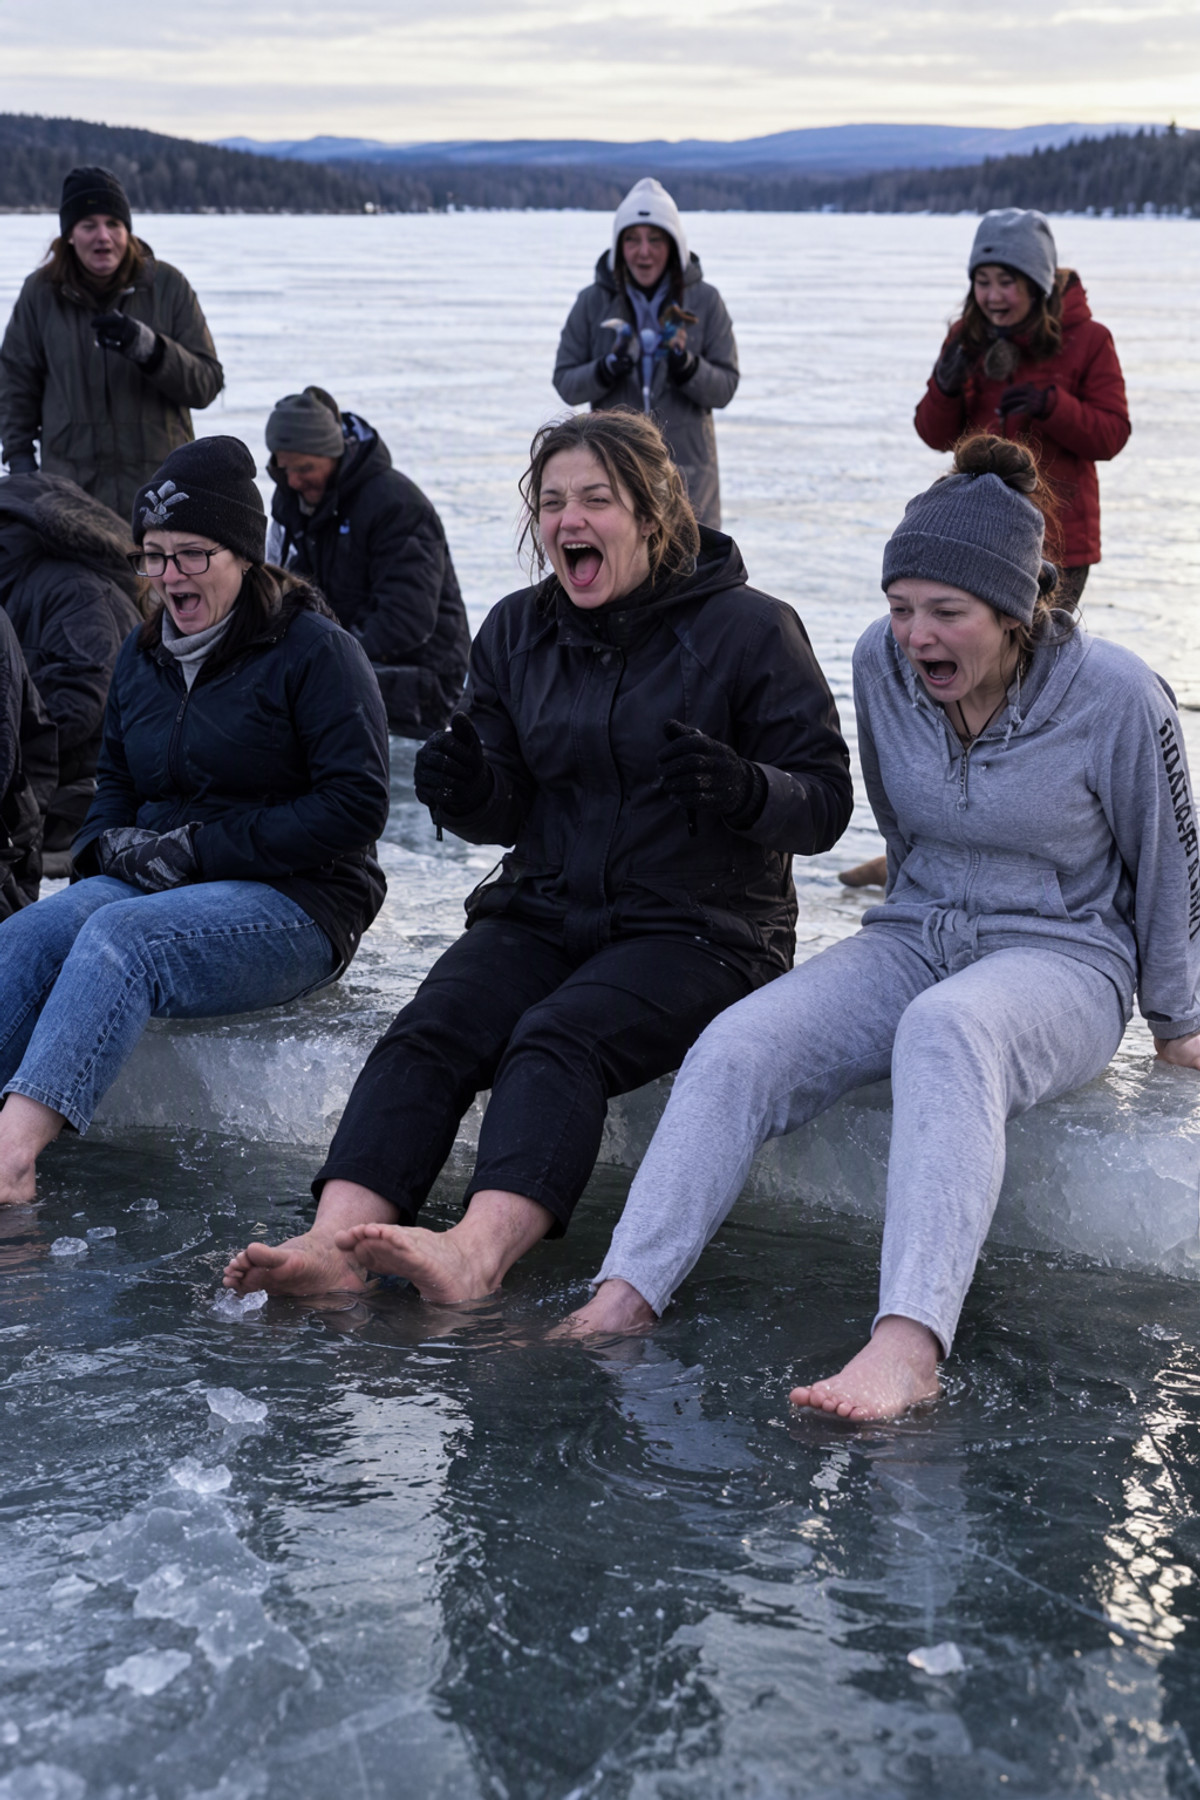
An emotion / reaction concept LoRA depicting "gasping from the cold": the momentary expression of screaming and shrinking when winter swimming, touching ice water, or walking barefoot on snow, ported from Z-Image Turbo.
Image
[B] FFstyle Anima/Moss Heal · v1.0 Moss heal
LoRA · Port · Author FEEEEF · Published 11-06 00:31 · Downloads 88
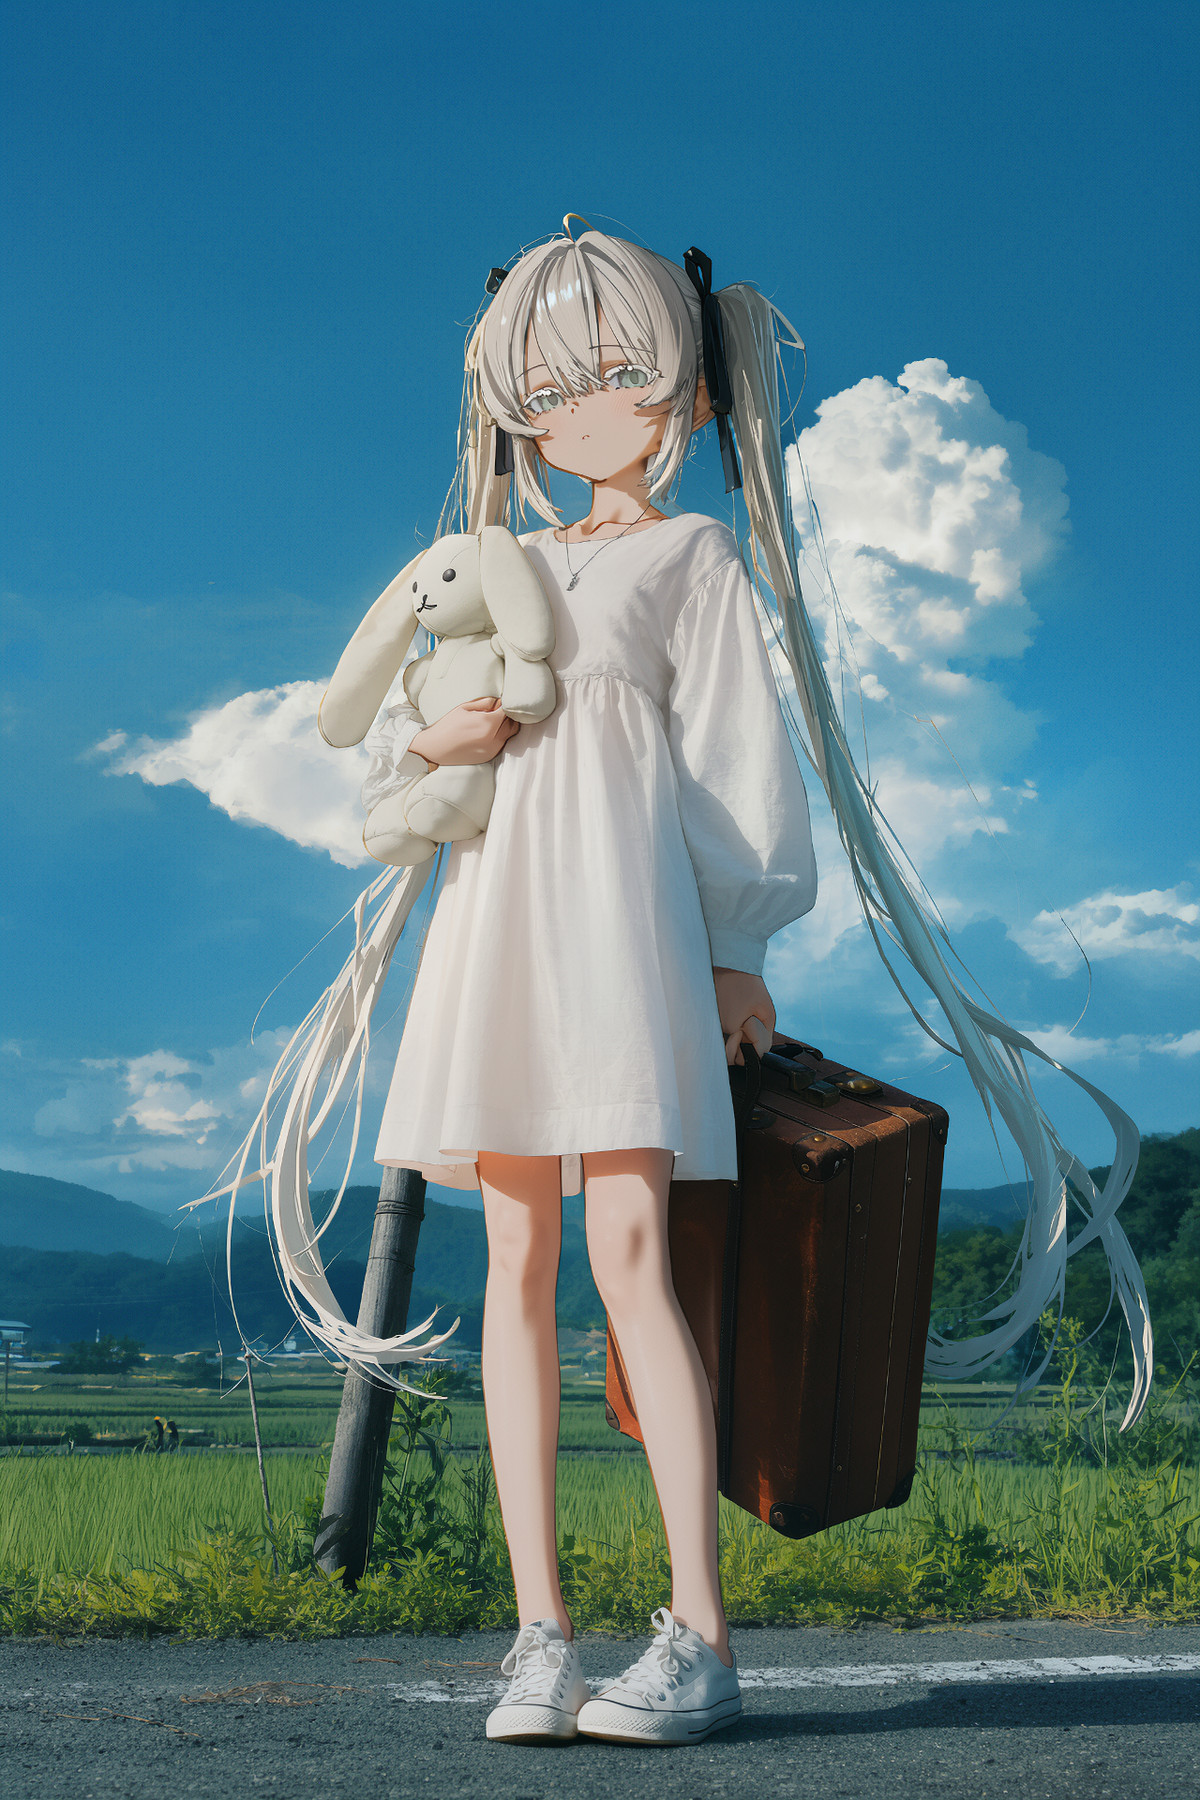
The MOSS version of the FFstyle anime style LoRA, ported from Anima: visible examples are anime girl illustrations with a thick paint feel, strong backlighting, and firelight atmosphere.
Image
[B] Bad Guys Movie Style + Characters · MOSS
LoRA · New Model · Author OrdinaryTwig · Published 11-06 08:47 · Downloads 5
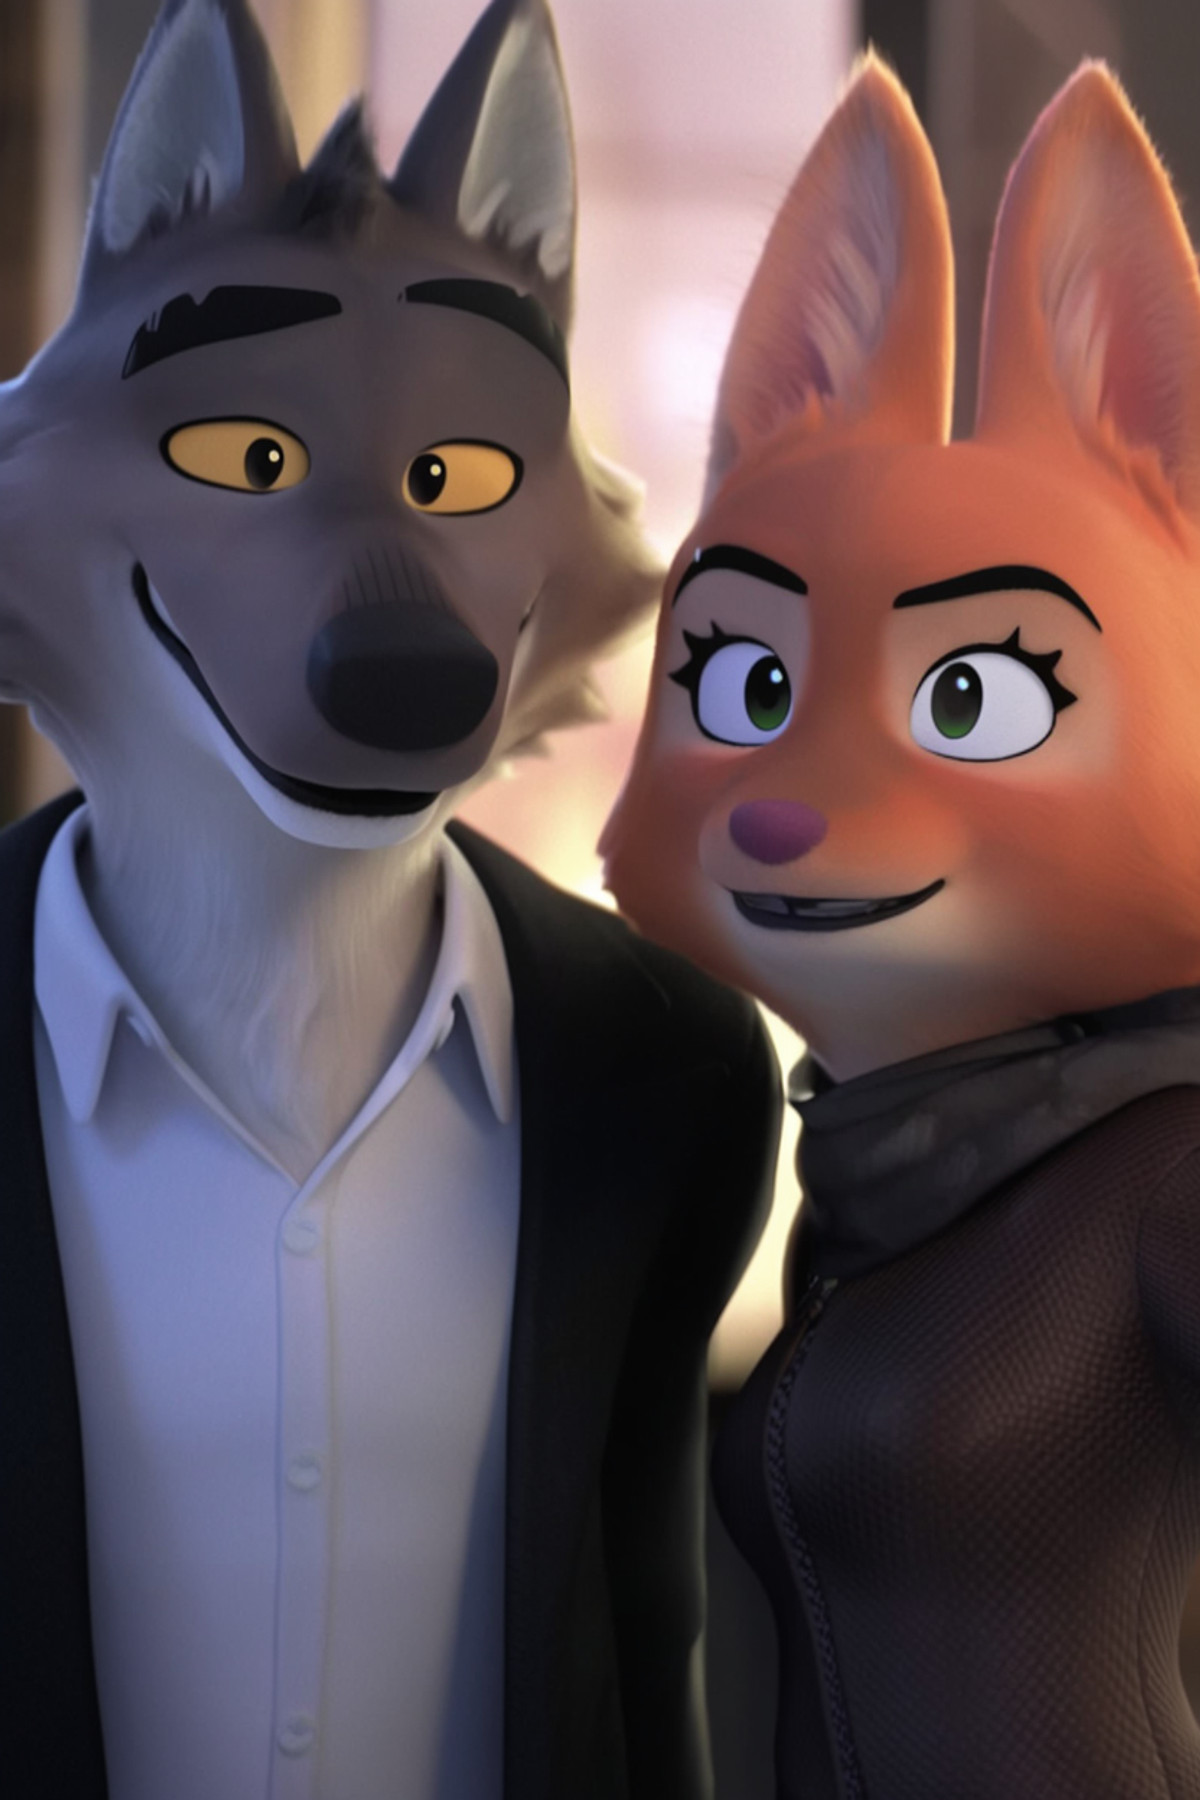
A 3D style + character LoRA for the two DreamWorks animated films "The Bad Guys": one file handles both the style and eleven characters (Mr Wolf, Diane Foxington, Mr Snake, etc.).
Image
[B] Qing Dynasty Concubines · v1.0
LoRA · New Model · Author EDG · Published 11-06 04:55 · Downloads 32
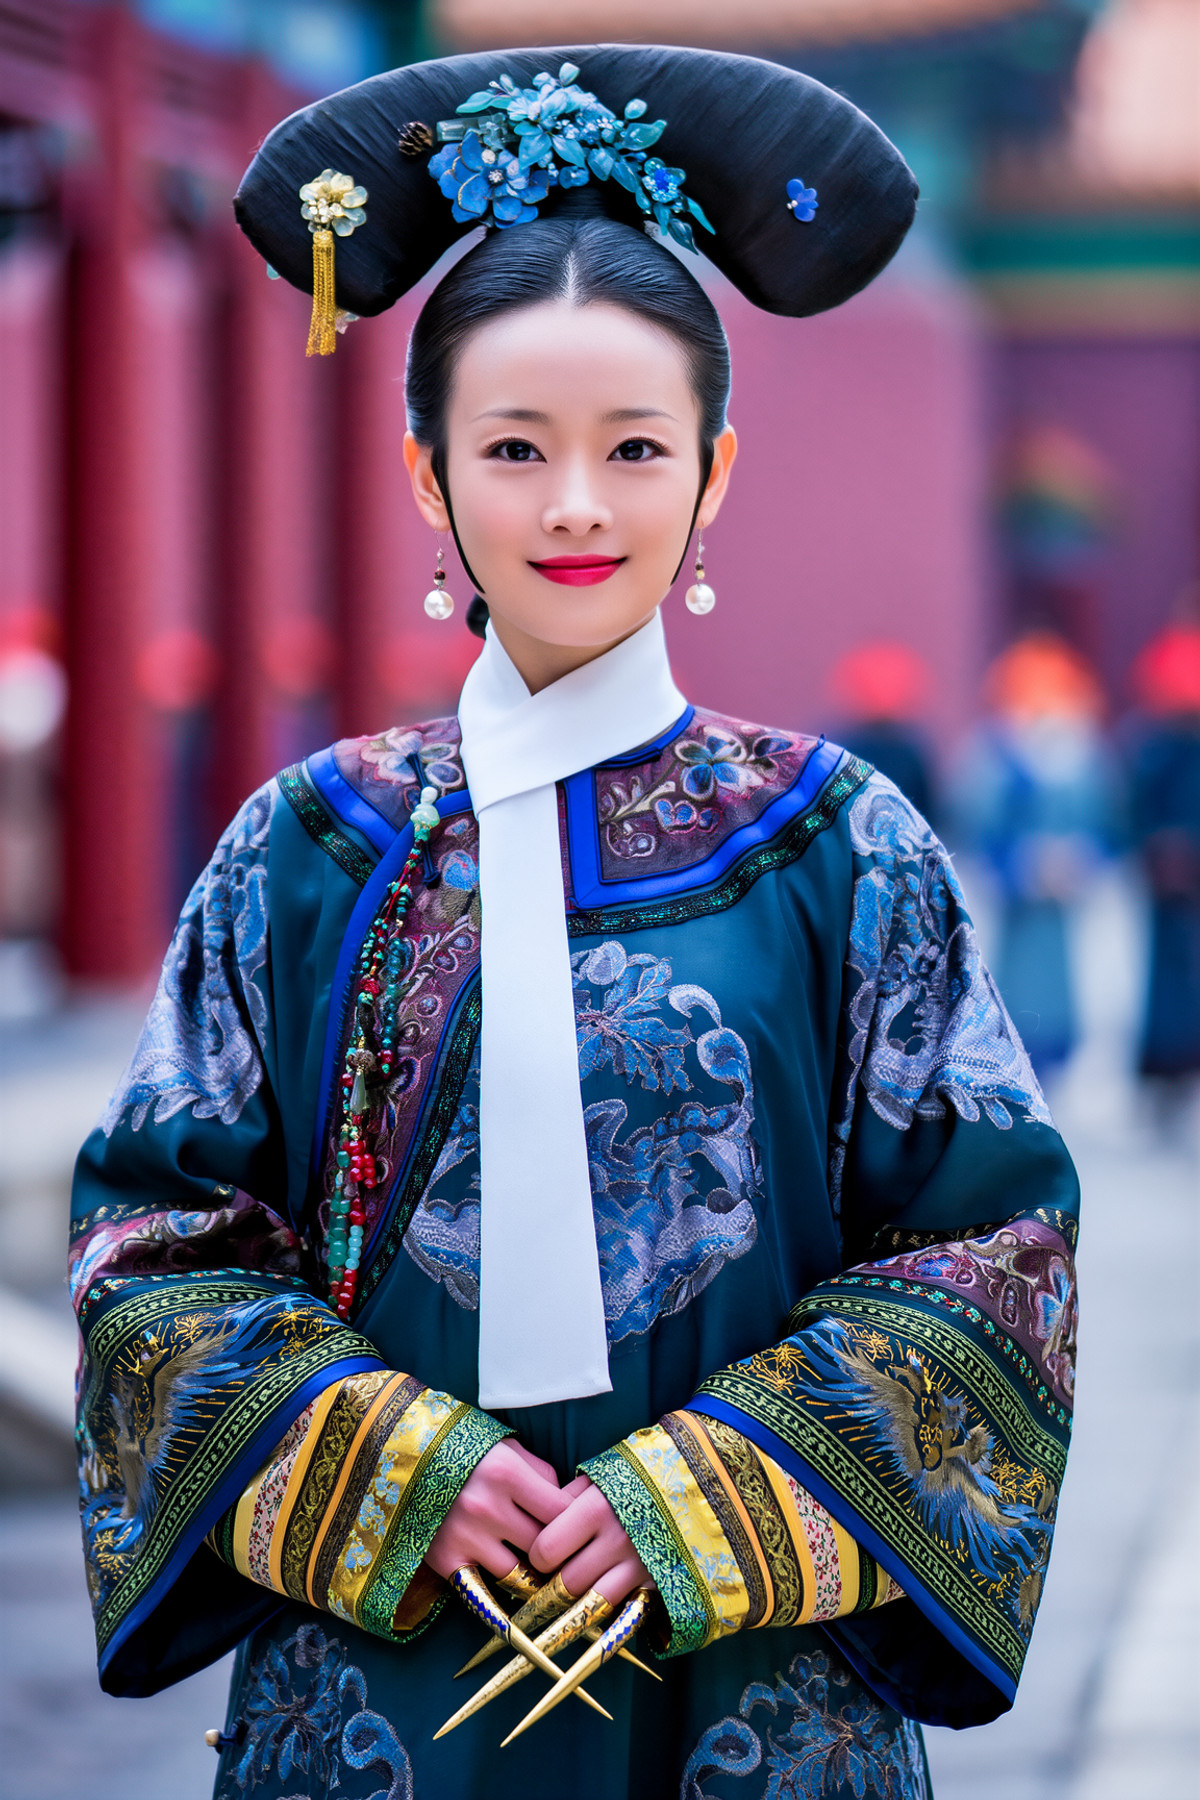
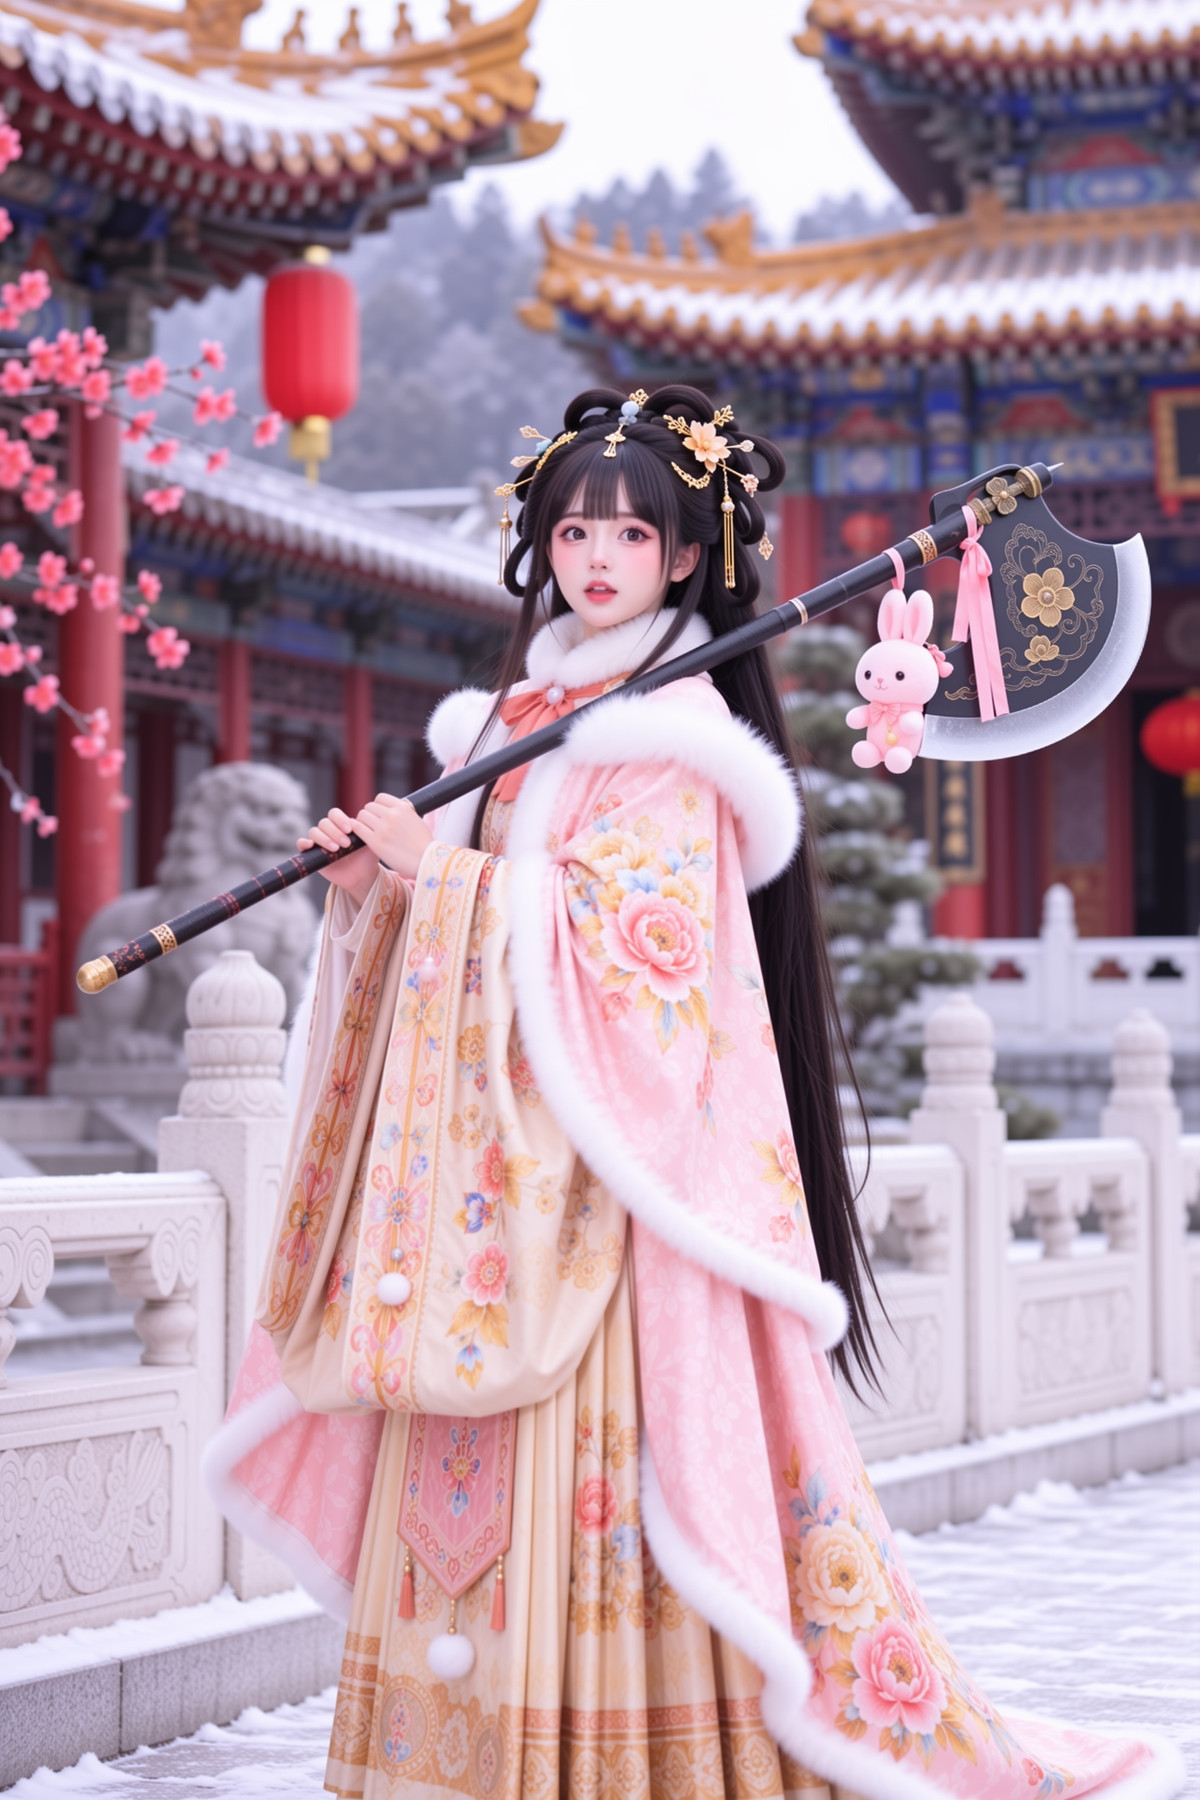
A Qing Dynasty court concubine attire LoRA: realistic portraits wearing embroidered Manchu robes, with Dianzi / Qitou headpieces and tassels, and nail guards on the little finger; visible examples are half-body shots in front of the Forbidden City's red walls and lotus ponds.
Image
[B] HaDeS MOSS Turbo · akhaliq-MOSS-SFT-4step-v2
LoRA · Version Update · Author _HaDeS_ · Published 11-06 05:16 · Downloads 17
A compressed version of the akhaliq 4-step acceleration LoRA from the HaDeS MOSS Turbo page: it retains only layers 24–41 of akhaliq's MOSS-Image-SFT-4-steps v2.0, reduces the rank to 2, and shrinks the size from 1.2 GB to about 3.6 MB; it was not trained by HaDeS.
Image
[B] HaDeS MOSS Turbo · lodestones-8-steps-dmd2
LoRA · Version Update · Author _HaDeS_ · Published 11-06 05:14 · Downloads 20
A compressed version of the lodestones 8-step DMD2 acceleration LoRA from the HaDeS MOSS Turbo page: the original file is a 8-step LoRA distilled by lodestones from MOSS-Image Base and released with the Kromoss fine-tune, cropped to layers 24–41, rank 2, about 3.6 MB.
Image
[B] lite Style | MOSS · lite style moss v1.0
LoRA · New Model · Author svnx7x_ · Published 11-06 08:59 · Downloads 0
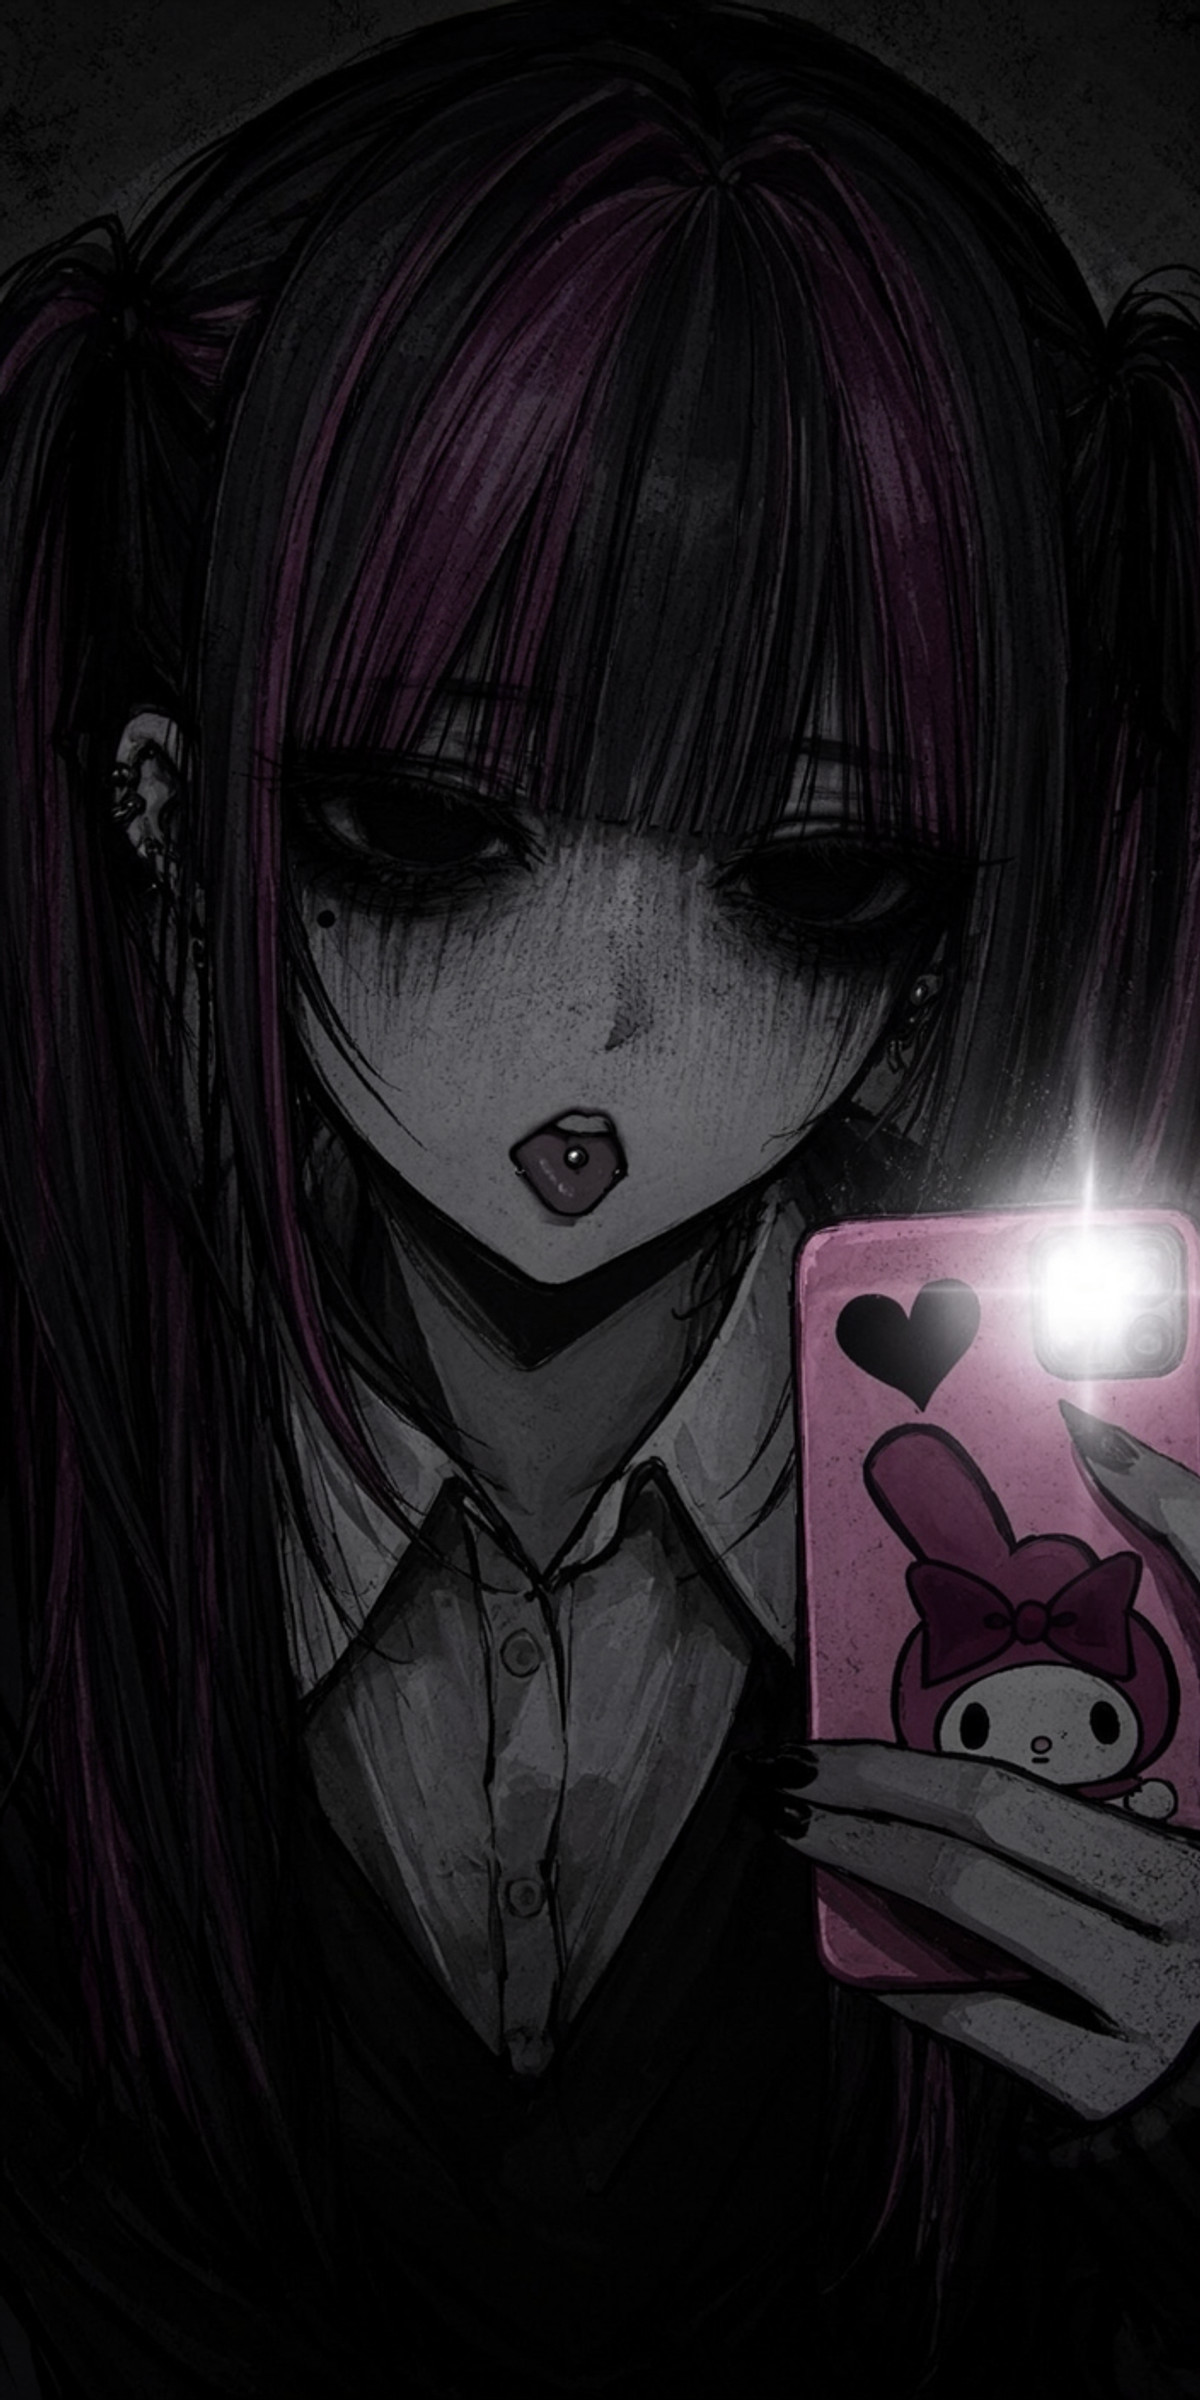
The author's first LoRA: adds a light-colored, soft-line Japanese anime style to MOSS SFT; visible examples are cute-style girls in pink and white, with one dark selfie-style image.
Image
[B] moss base gapteeth · v1
LoRA · New Model · Author hamstornado · Published 11-06 01:15 · Downloads 1 · Paid
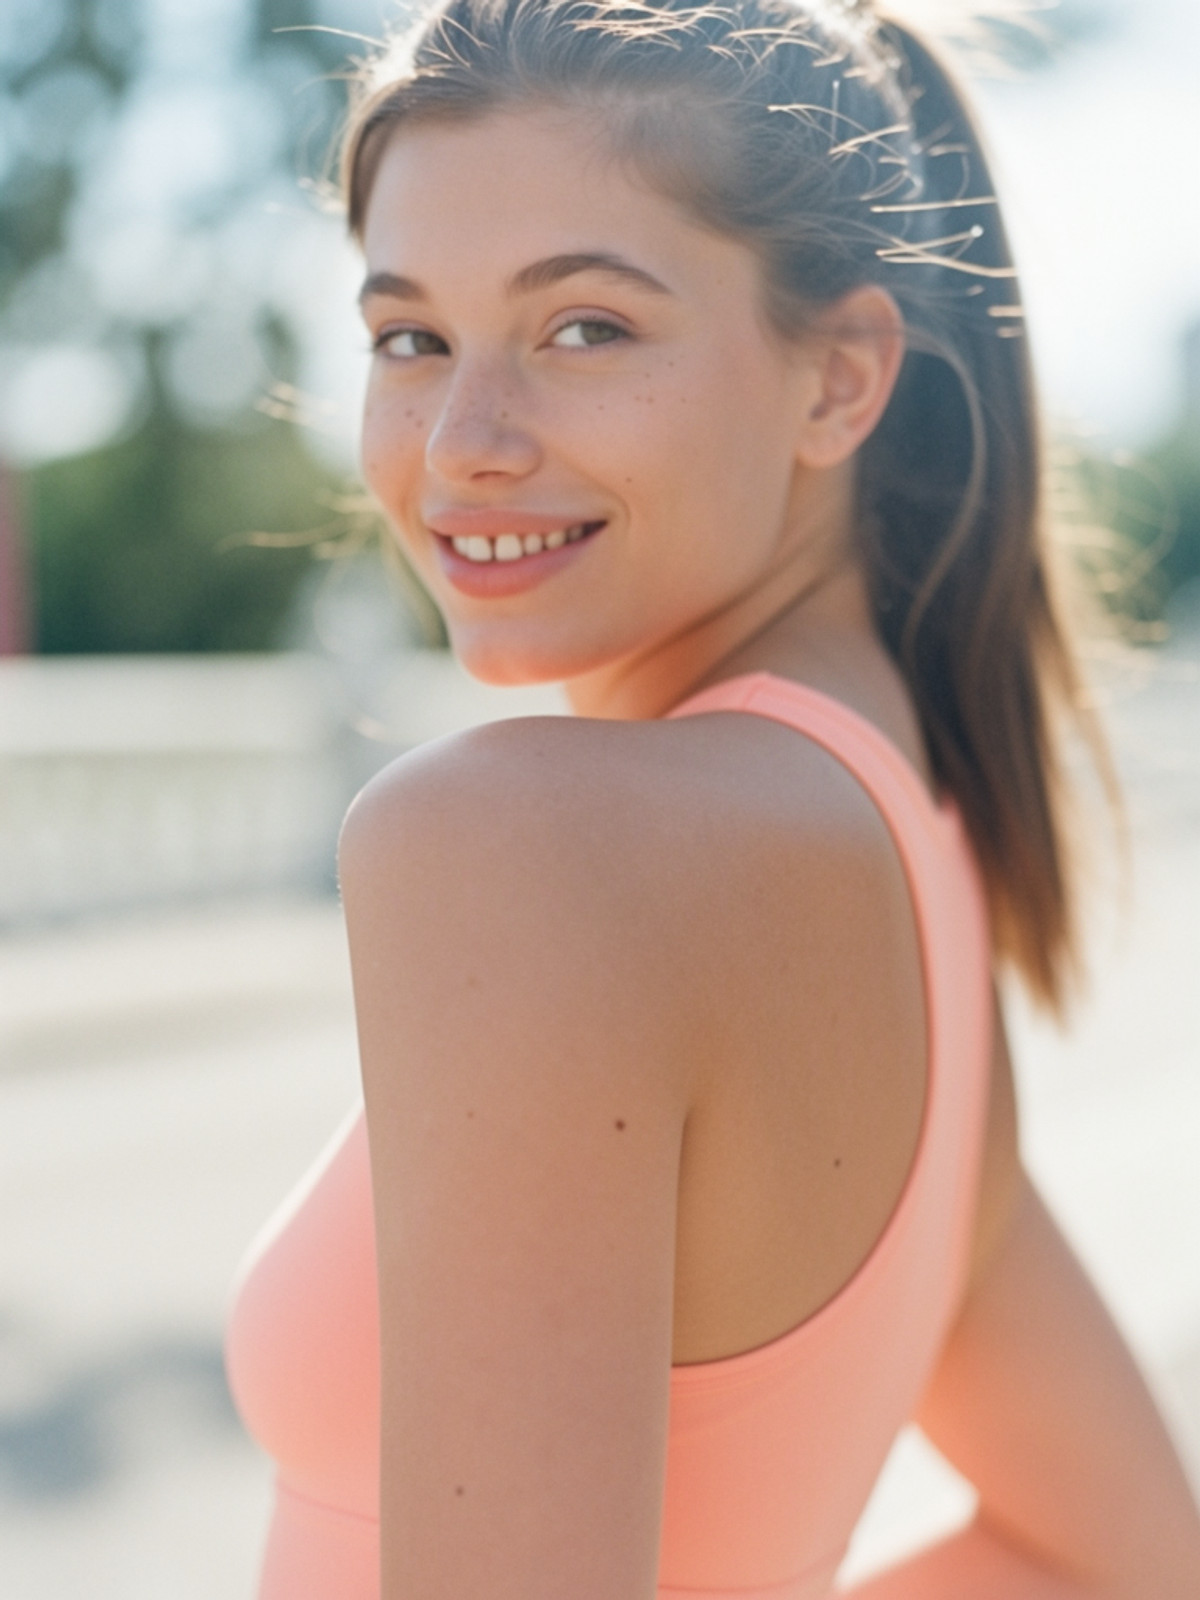
A facial feature LoRA that gives realistic characters a gap between their front teeth (diastema / interdental space), one of hamstornado's three "moss base teeth" series, trained on MOSS Base.
Image
[B] moss base goofyteeth · v1
LoRA · New Model · Author hamstornado · Published 11-06 01:26 · Downloads 0 · Paid
A facial feature LoRA that gives realistic characters uneven, protruding, or misaligned "goofy teeth," part of the same author's teeth series, trained on MOSS Base.
Image
【B】moss base buckteeth · v1
LoRA · New Model · Author hamstornado · Published 11-06 01:48 · Downloads 1 · Paid
A LoRA that adds protruding front teeth (buck teeth) facial features to realistic characters. It is part of the same author's teeth series and was trained on MOSS Base.
Image
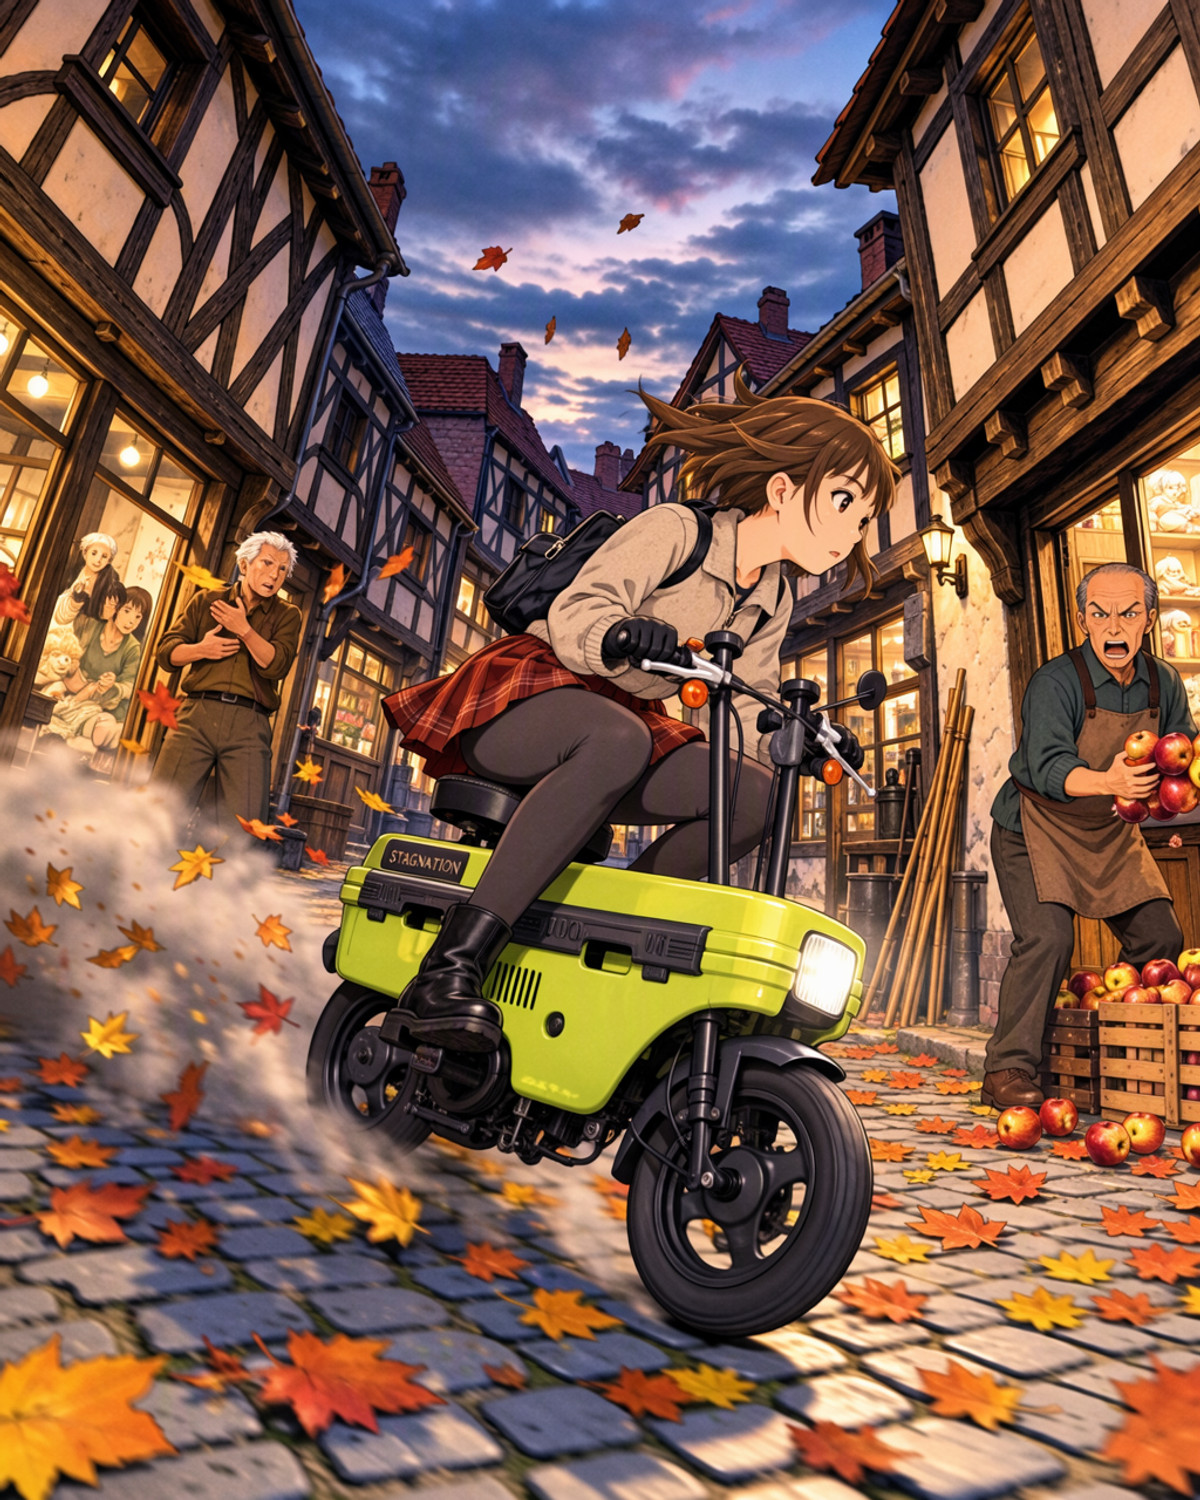
【B】MOSS Honda Motocompo Trunk Bike / Torabi (Real and Anime) · v1.0
LoRA · New Model · Author Stagnation · Published 11-05 23:30 · Downloads 0 · Paid
An object concept LoRA for the Honda Motocompo folding mini-motorcycle ("trunk bike"): trained on a mix of 41 real photos and anime images, capable of generating the vehicle in both realistic and anime styles.
Image
Included Only (8)
- Christie - Dead Or Alive - Krea 2 · MI — LoRA: A character LoRA for Christie from Dead or Alive (short hair style), with an art style between 3D CG and realistic photography. The MOSS version is ported from the Krea 2 version.
- RLY Thot Shot - Helena (MOSS + QWEN2.1 + KREA 2 + Ideogram 4 + ZiB/ZiT + K9B) · MOSS-v1.0 — LoRA: The sixteenth fictional female character LoRA (Helena) in the RLY Thot Shots series, featuring realistic photographic portraits. The MOSS version is ported from Qwen 2.1 / Krea 2 / Z-Image / Klein and other versions.
- ogata ai (Pure Mail) MOSS-image LORA · 002 — LoRA: A character LoRA for Ogata Ai from Pure Mail. The author notes this is the 002th version of the MOSS-image training test.
- Christie - Dead Or Alive (Bob Hairstyle) · MI — LoRA: A character LoRA for Christie from Dead or Alive with a bob hairstyle. This is a separate model from the same author's short hair version. The MOSS version is ported from Krea 2 / Flux.1 D versions.
- Latex Outfit · MossImage — LoRA: The MOSS version of MisterMR's Latex Outfit clothing LoRA. The author describes it as a glossy latex / patent leather tight outfit with cutouts and structured shoulders, ported from MiniMax H3, Krea 2, Pony, and other versions.
- Aurahack Style · MOSS — LoRA: The MOSS version of artist Aurahack18's LyCORIS art style, ported from the same-named model from the Pony / SD 1.5 era. The filename indicates it was trained on MOSS Base.
- Kyoko Kirisaki/霧崎恭子 · v1 — LoRA: An anime character LoRA for Kyoko Kirisaki from To LOVE-Ru.
- Moss DeliceTuned for turbo · cute [8steps] v1.0b — LoRA: A "cute" oriented portrait style / face tuning LoRA that must be used with a 8-step Turbo LoRA. The author states they removed two layers to reduce facial recognizability, acknowledging it as an incomplete semi-personal version.
Data: Civitai Public API (Base Model MOSS Image). Inclusion window: 11-05 20:31 → 11-06 09:01 (Beijing Time). Recommendations are editor-reviewed; download counts only reflect attention.