Zhenzhen's AI Radar · MOSS Image · 2026-11-12 Morning Report
This issue features 28 new versions: Strongly Recommended 4 · Recommended 10 · Worth Watching 6 · Included Only 8
Editor's Note This issue reviewed 37 new MOSS versions: 4 S-tier, 10 A-tier, 7 B-tier, 14 C-tier, with 2 excluded. Top pick: BAStyle, a LoRA for a clear cel-shaded mobile game art style capable of generating character portraits, multi-character CG scenes, and empty skies with concentric rings. It includes complete trigger syntax, parameters, and native workflows, but the license prohibits commercial use. Also S-tier are Dizzle's Midnight Oil and Neon Pop, and Oekaki Doodle Style. A-tier includes BBox Studio (a tool for generating MOSS layout JSON via drag-and-drop boxes), 12-step acceleration LoRA v8.0, and the Anime2Real VRAM reduction workflow. The Klein9B and Anima versions labeled as MOSS on the Neon Gothic page have filenames that are not MOSS and were excluded as mislabeled; multiple standard character LoRAs are C-tier.
Strongly Recommended (4)
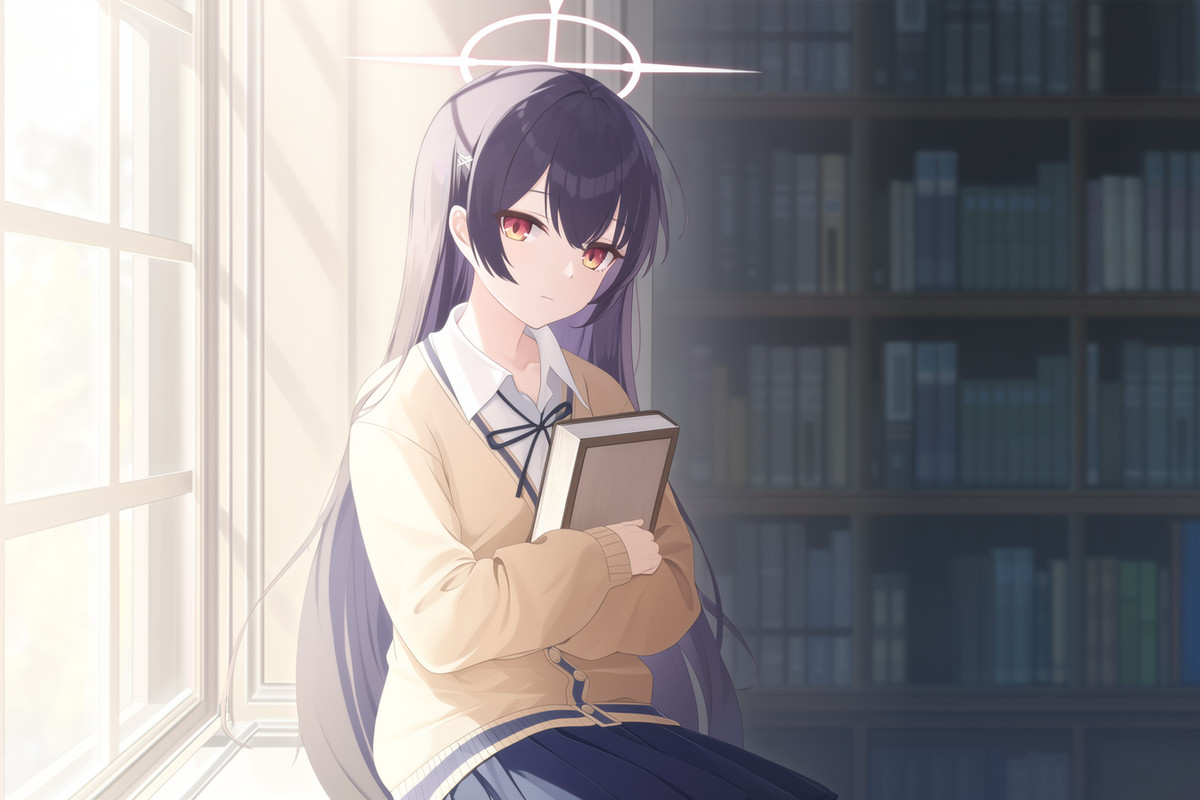
[S] BAStyle - Blue Archive Clean Cel-Shaded Style (MOSS-Image-Base 5B) · v1.0
LoRA · New Model · Author: nekoshrimp · Published 11-12 04:13 · Downloads 25
A LoRA for a clear cel-shaded art style in the vein of Blue Archive, trained on MOSS-Image-Base. It can generate close-up character portraits reminiscent of lobby screens, flat-lit multi-character story CGs, and empty scenes featuring academy buildings and skies with concentric rings.
Upgraded from automatic B to S: The automatic downgrade was solely due to an incomplete security scan of the included workflow zip file; usage instructions, parameters, and examples are the most complete in this group.
Images
Reasons for Recommendation
- New model; suitable for anime illustrations, game-style character portraits, and scene backgrounds. The author trained only the DiT, freezing the Qwen3.5-9B text encoder, claiming to preserve the base model's native understanding of natural language in Chinese and English and its ability to render text within images (example prompts include English text on a blackboard).
- Detailed usage instructions: Place
bastyleat the beginning of the prompt, followed by complete natural sentences; do not use 1girl-style tags. The halo is not tied to the trigger word; specify color and shape if desired. For empty scenes, start with 2D anime background illustration and addwith faint concentric ringsto generate the original's ringed sky. Includes three sets of sentence structures for single characters, multiple characters, and empty scenes, along with 9 example prompts (including pure Chinese). - Complete parameters: Strength 0.90–0.95 (0.85–0.90 when stacking with character LoRAs), euler + simple, 28–32 steps, CFG 3.0. Includes a native ComfyUI workflow with no third-party plugin dependencies, and all 9 example images are visible.
How to Use
- Base model:
moss_image_base_bf16orint8_convrot; Text encoder:qwen3.5_9b_int8_convrot(selectmoss_imagetype in CLIPLoader); VAE:flux2-vae. ForEmptyFlux2LatentImage, set dimensions as multiples of 16, such as 1344x896, 1536x1024, or 896x1344. - Prompt:
bastyle,+ shot framing + hair/eye color, expression/action, optional halo + clothing + environment + lighting. Strength 0.90–0.95, euler + simple, 28–32 steps, CFG 3.0. - Values for flow shift and SkipLayerGuidance are specified in the model card and preset in the included workflow. Leave the negative prompt empty; write
haloif you want to completely suppress the halo.
Risks and Limitations
- License is CC BY-NC 4.0, prohibiting commercial use and paid commission services. Mimics a specific game art style, falling under fan art nature.
- The author states that the v1.0 training set (58 images) primarily consists of distant story scenes and multi-character scenes, with few close-ups of open-eyed frontal faces. When generating original characters alone, facial structures and eye highlights may lean towards an old-fashioned galgame aesthetic. It is recommended to stack character LoRAs or clearly describe facial features in the prompt.
- The included workflow zip file is labeled as Training Data, and the security scan is incomplete (the main weight scan has passed).
Trigger Word: bastyle
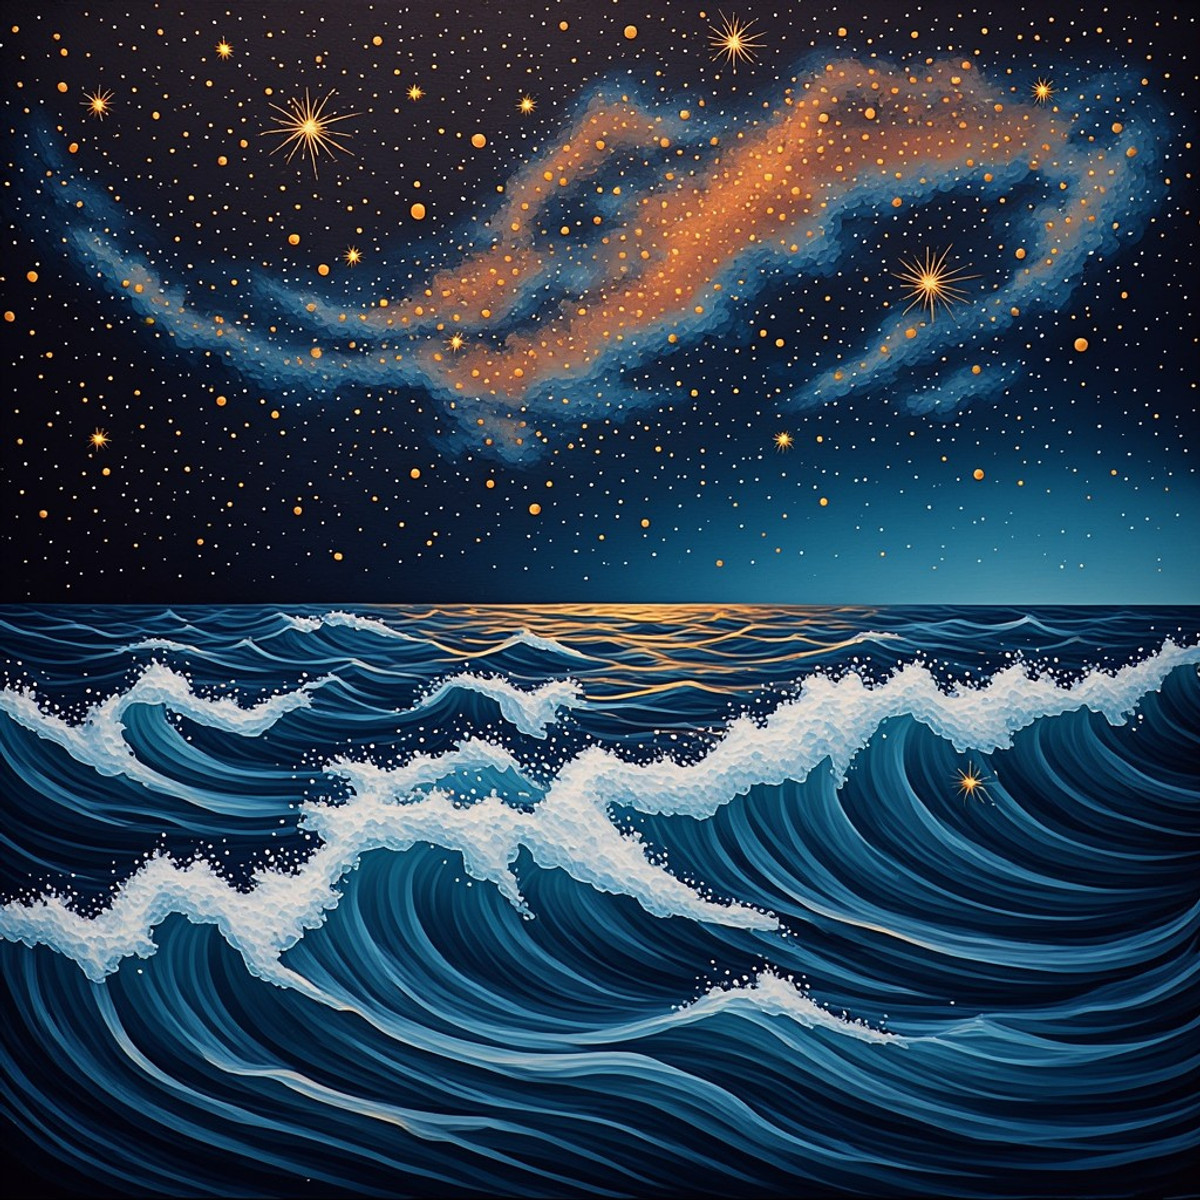
[S] Dizzle's Midnight Oil - MOSS · v1
LoRA · New Model · Author: Maridizzle · Published 11-12 05:15 · Downloads 20
A "Midnight Oil Nocturne" style LoRA: Places the subject in a night of ink blue and black, illuminated by candlelight, low-hanging moonlight, and golden star points, featuring the soft depth and visible brushstrokes of old oil paintings.
Images
Reasons for Recommendation
- New model; suitable for dark-toned images such as night scene illustrations, candlelit interiors, starry skies, and night portraits. The same author's paper art LoRA from the previous issue (dz_card) uses the same syntax.
- Complete usage instructions: Start the prompt with
dz_night, midnight oil nocturne, then describe the scene using complete sentences (the author emphasizes that MOSS reads natural language; do not stack tags). Strength 0.9–1.0. MOSS default settings are approximately 30–50 steps, CFG 3, Euler flowmatch. - The author provides generation tips: Dark backgrounds yield the best results. Placing a warm light source (candle, crescent moon) within the cool ink blue tones enhances the warm-cool contrast. 6 visible example images.
How to Use
- Start the prompt with
dz_night, midnight oil nocturne, then describe the scene using complete sentences, and arrange a warm-colored light source. - Strength 0.9–1.0; 30–50 steps, CFG 3, Euler flowmatch.
Risks and Limitations
- 3 examples are hidden, and the page contains mixed content. The license does not include selling rights.
- The step count of 30–50 is relatively high, and the author does not mention performance when paired with acceleration LoRAs. No examples are provided for bright or daytime scenes.
Trigger Word: dz_night
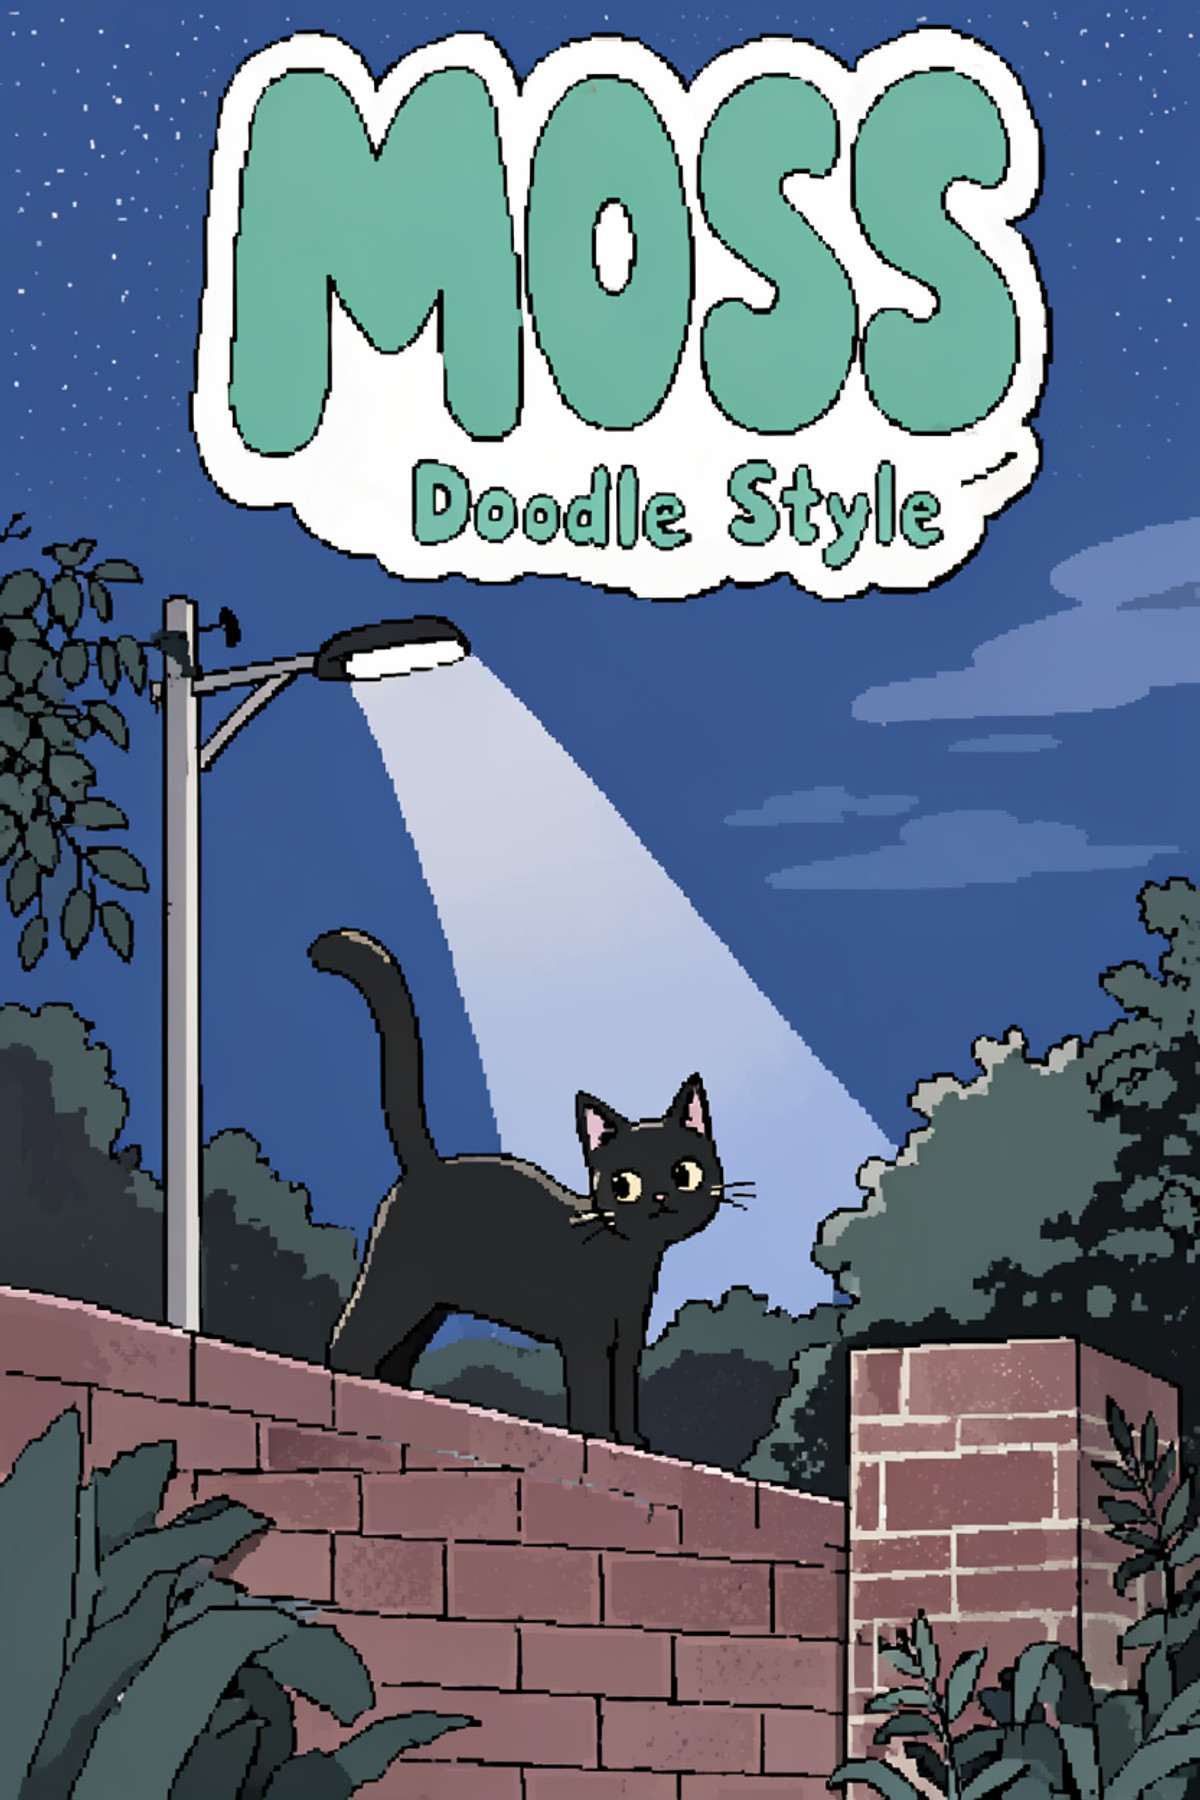
[S] [MOSS] Oekaki/Doodle Style · v1.0
LoRA · New Model · Author: SoyKaf · Published 11-11 22:55 · Downloads 85
An Oekaki (Japanese doodle board) style LoRA: Limited color palette, low resolution, rough digital hand-drawn strokes with a smeared feel, similar to pixel art but without strict pixel precision.
The step count of 50-70 is the author's personal preference. For faster results, try comparing with the Turbo configuration first.
Images
Reasons for Recommendation
- New model; suitable for illustrations, avatars, and small comic images seeking an early internet doodle board / MS Paint hand-drawn vibe.
- The author provides their complete settings: MOSS SFT, CFG 3, 50-70 steps, Euler / Beta57, with SkipLayerGuidanceDiTSimple enabled (single layer 22, start 0.0, end 1.0). The author claims that settings for Base / Turbo etc. should also work.
- Specific tuning advice: Strength 1.0 (adjustable between 0.5 - 1.5). Works with or without the trigger word. Adding
illustrationanddoodleto the prompt strengthens the effect; simpler prompts result in a stronger doodle feel. 3 visible example images.
How to Use
- Add
In the style of lokulo.to the prompt (optional), then addillustrationanddoodleto enhance the effect. Keep the prompt as short as possible. - Strength 1.0 (0.5 - 1.5). Author's settings: MOSS SFT, CFG 3, 50-70 steps, Euler / Beta57, SkipLayerGuidanceDiTSimple single layer 22, start 0.0, end 1.0.
Risks and Limitations
- 3 examples are hidden, with only 3 visible. The file is FP32, approximately twice the size of similar LoRAs.
- The trigger word
lokuloappears to be an artist's name, and the author does not specify the training data source. The license does not allow derivatives.
Trigger Word: In the style of lokulo.
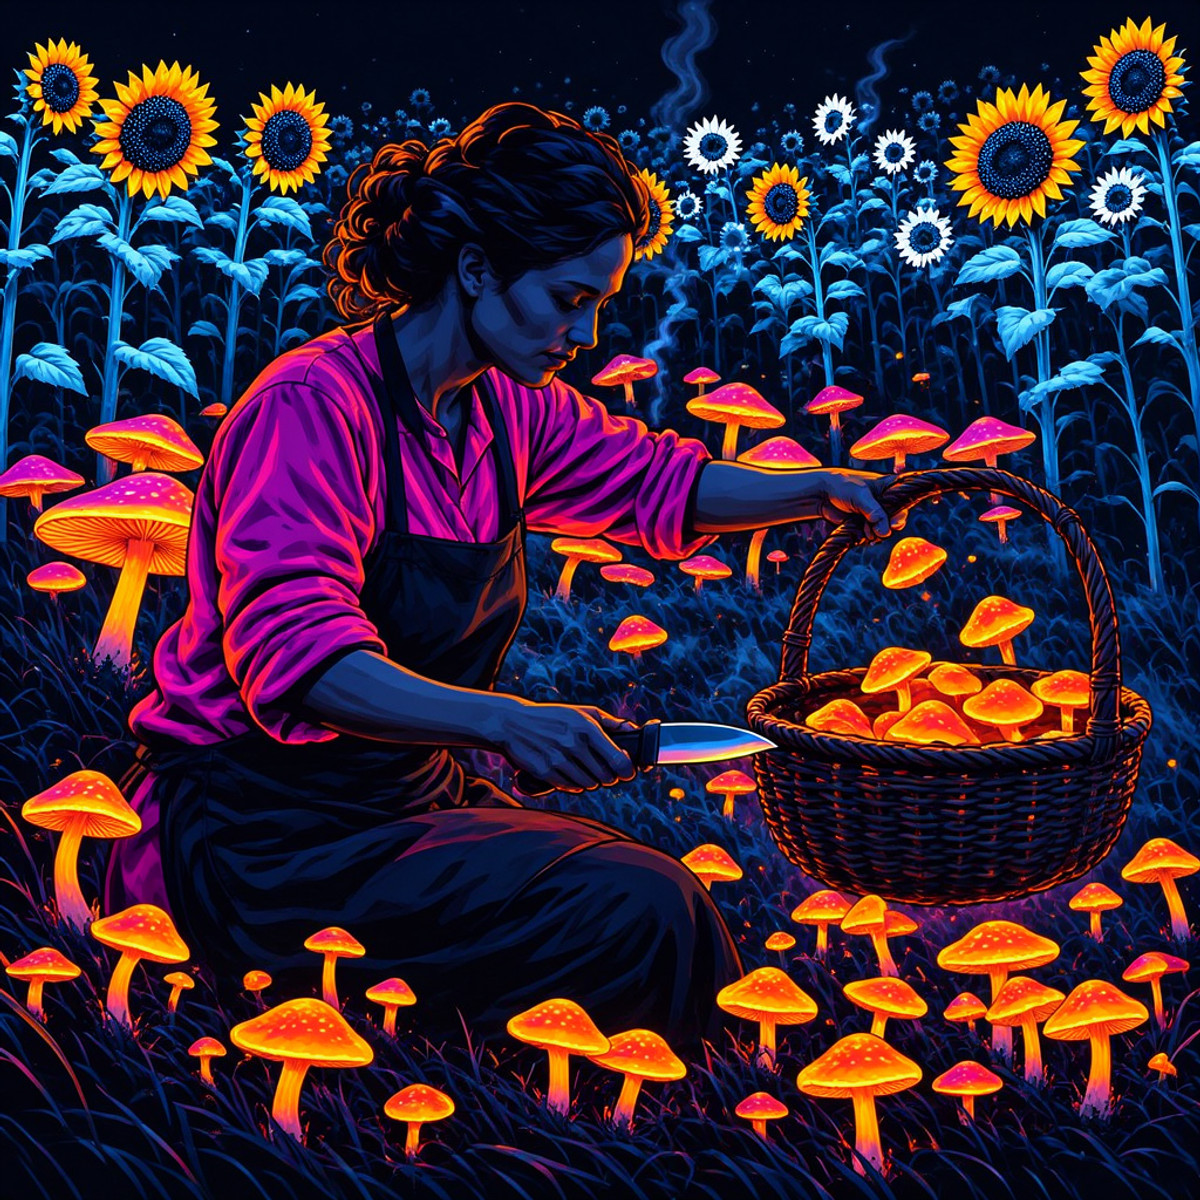
[S] Dizzle's Neon Pop - MOSS · v1
LoRA · New Model · Author: Maridizzle · Published 11-11 21:42 · Downloads 35
A blacklight poster-style neon pop LoRA: Renders the subject in high-saturation neon colors like acid green, magenta, molten orange, and electric blue, glowing against a pure black background, resembling a UV poster illuminated by backlighting.
Uses the same syntax as the same author's corrugated cardboard collage LoRA (dz_card) from the previous issue: Trigger word at the front, description in natural sentences, same default parameters.
Images
Reasons for Recommendation
- New model; suitable for single-subject images that need to grab attention at a glance, such as posters, covers, and social media graphics. The author claims that the blacker the background, the brighter the neon, and that rough silhouettes and single subjects yield the best results.
- Complete usage instructions: Start the prompt with
dz_pop, neon pop art on a black background, then describe the scene using complete sentences. Strength 0.9–1.0. MOSS default settings are approximately 30–50 steps, CFG 3, Euler flowmatch. - Controllable color scheme: Simply name the desired neon colors in the prompt. 3 visible example images.
How to Use
- Start the prompt with
dz_pop, neon pop art on a black background, then describe the scene using natural sentences. To change the color scheme, specify the concrete neon colors, keeping the background black or near-black. - Strength 0.9–1.0; 30–50 steps, CFG 3, Euler flowmatch.
Risks and Limitations
- Only 3 visible examples, with another 4 hidden. The page contains mixed content.
- The step count of 30–50 is relatively high, and the author does not mention performance when paired with acceleration LoRAs. The effect is diminished on light backgrounds.
Trigger Word: dz_pop
Recommended (10)
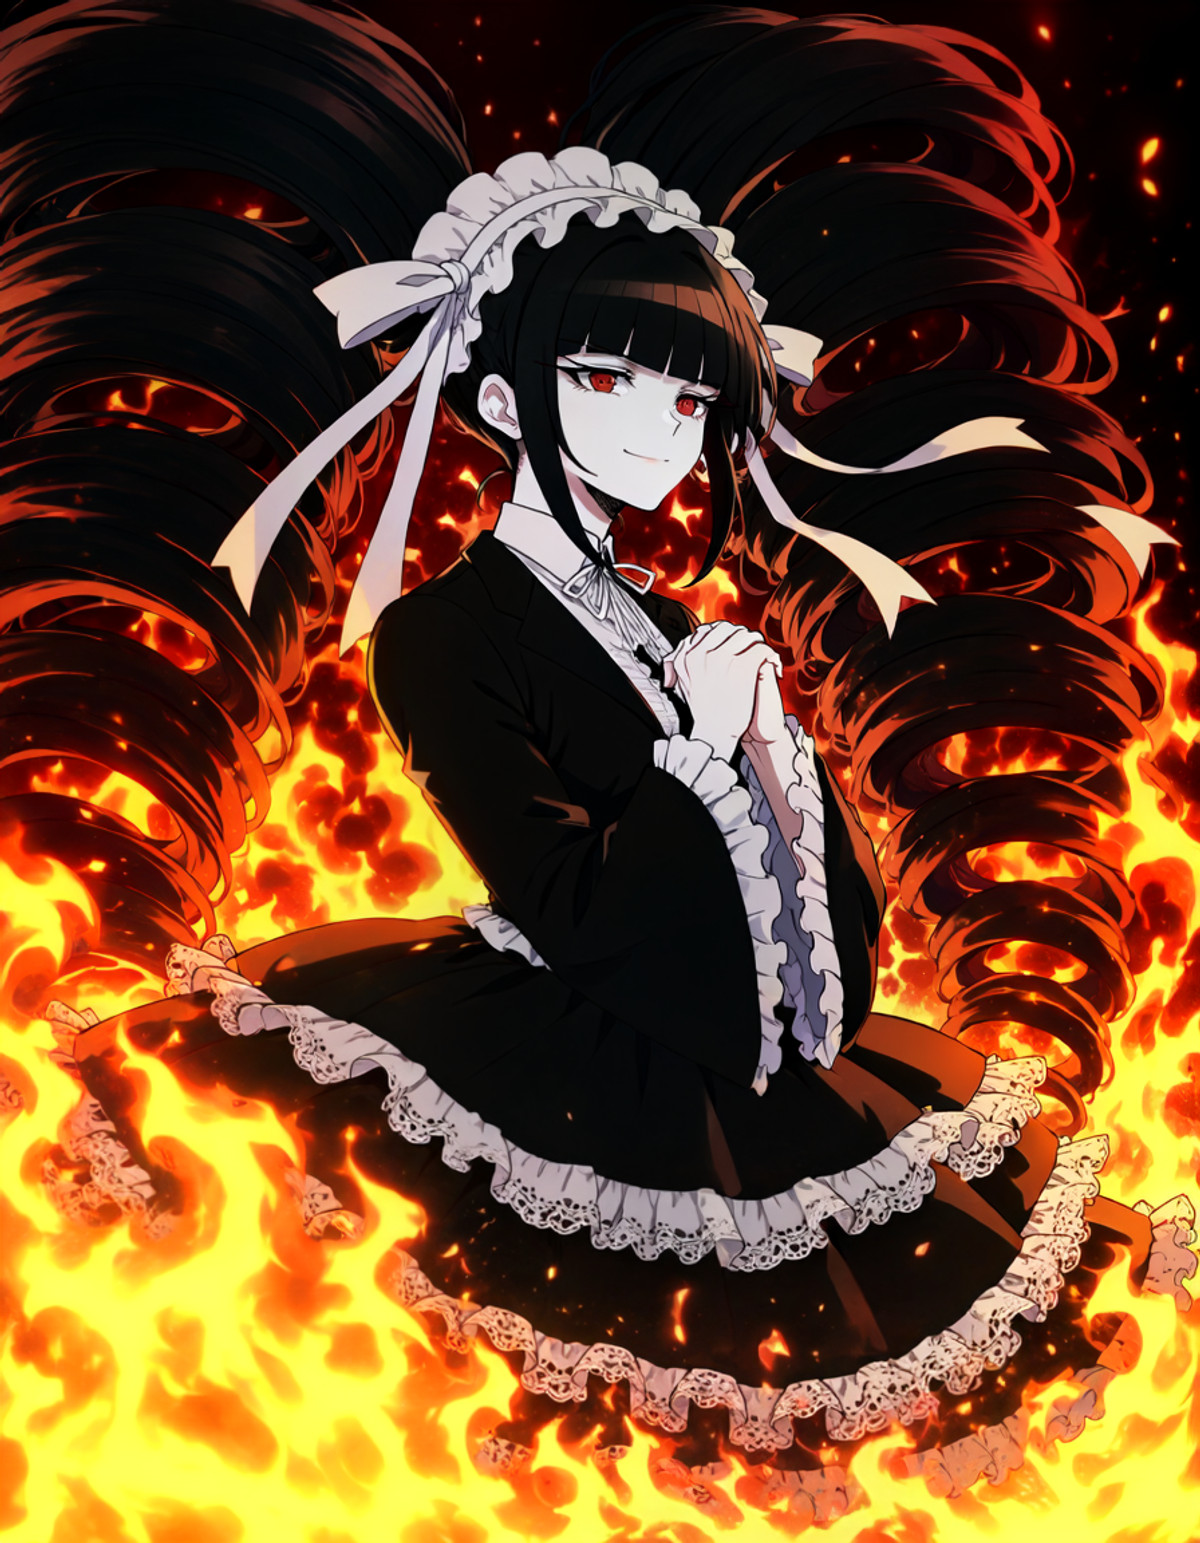
[A] Ccdanganart (style and Danganronpa booster) · Moss-Image v3.0
LoRA · Ported · Author: emerjk · Published 11-12 07:35 · Downloads 9
A MOSS version of the Danganronpa fan art style LoRA by artist criis-chan: Retains Danganronpa character designs and thematic elements within their art style.
Images
Reasons for Recommendation
- Port (the page already has Krea 2, Anima, Chroma, and Illustrious versions): The MOSS version belongs to the author's 3.0 dataset branch; the version itself has no separate description
- Usage of the 3.0 branch: Start with
ccdanganart , In the ccdanganart style.as a base, then select one phrase from the dozen or so style phrases listed by the author (e.g., low-saturation dusty colors, watercolor sketch, impasto line art, pencil draft, etc.) to fine-tune the direction - The author suggests that when pairing with their own Danganronpa character LoRA, lower the character LoRA to around 0.3 while keeping this LoRA at full strength; 8 visible example images are provided
How to Use
- Prompt:
ccdanganart , In the ccdanganart style.+ one style phrase listed by the author + image content; addingkomatsuzaki_rui_(style)will get closer to the official Danganronpa art style - The author did not provide strength, steps, or CFG for the MOSS version (the CFG suggestion in the model card is written for the Chroma version)
Risks and Limitations
- 9 examples are hidden, and the page contains mixed content; it is a fan-art style imitating a specific artist, and the license does not allow commercial use of generated images
- The description primarily focuses on Krea 2 / Chroma; there is no textual description of the MOSS version's performance
Trigger Word: ccdanganart , In the ccdanganart style.
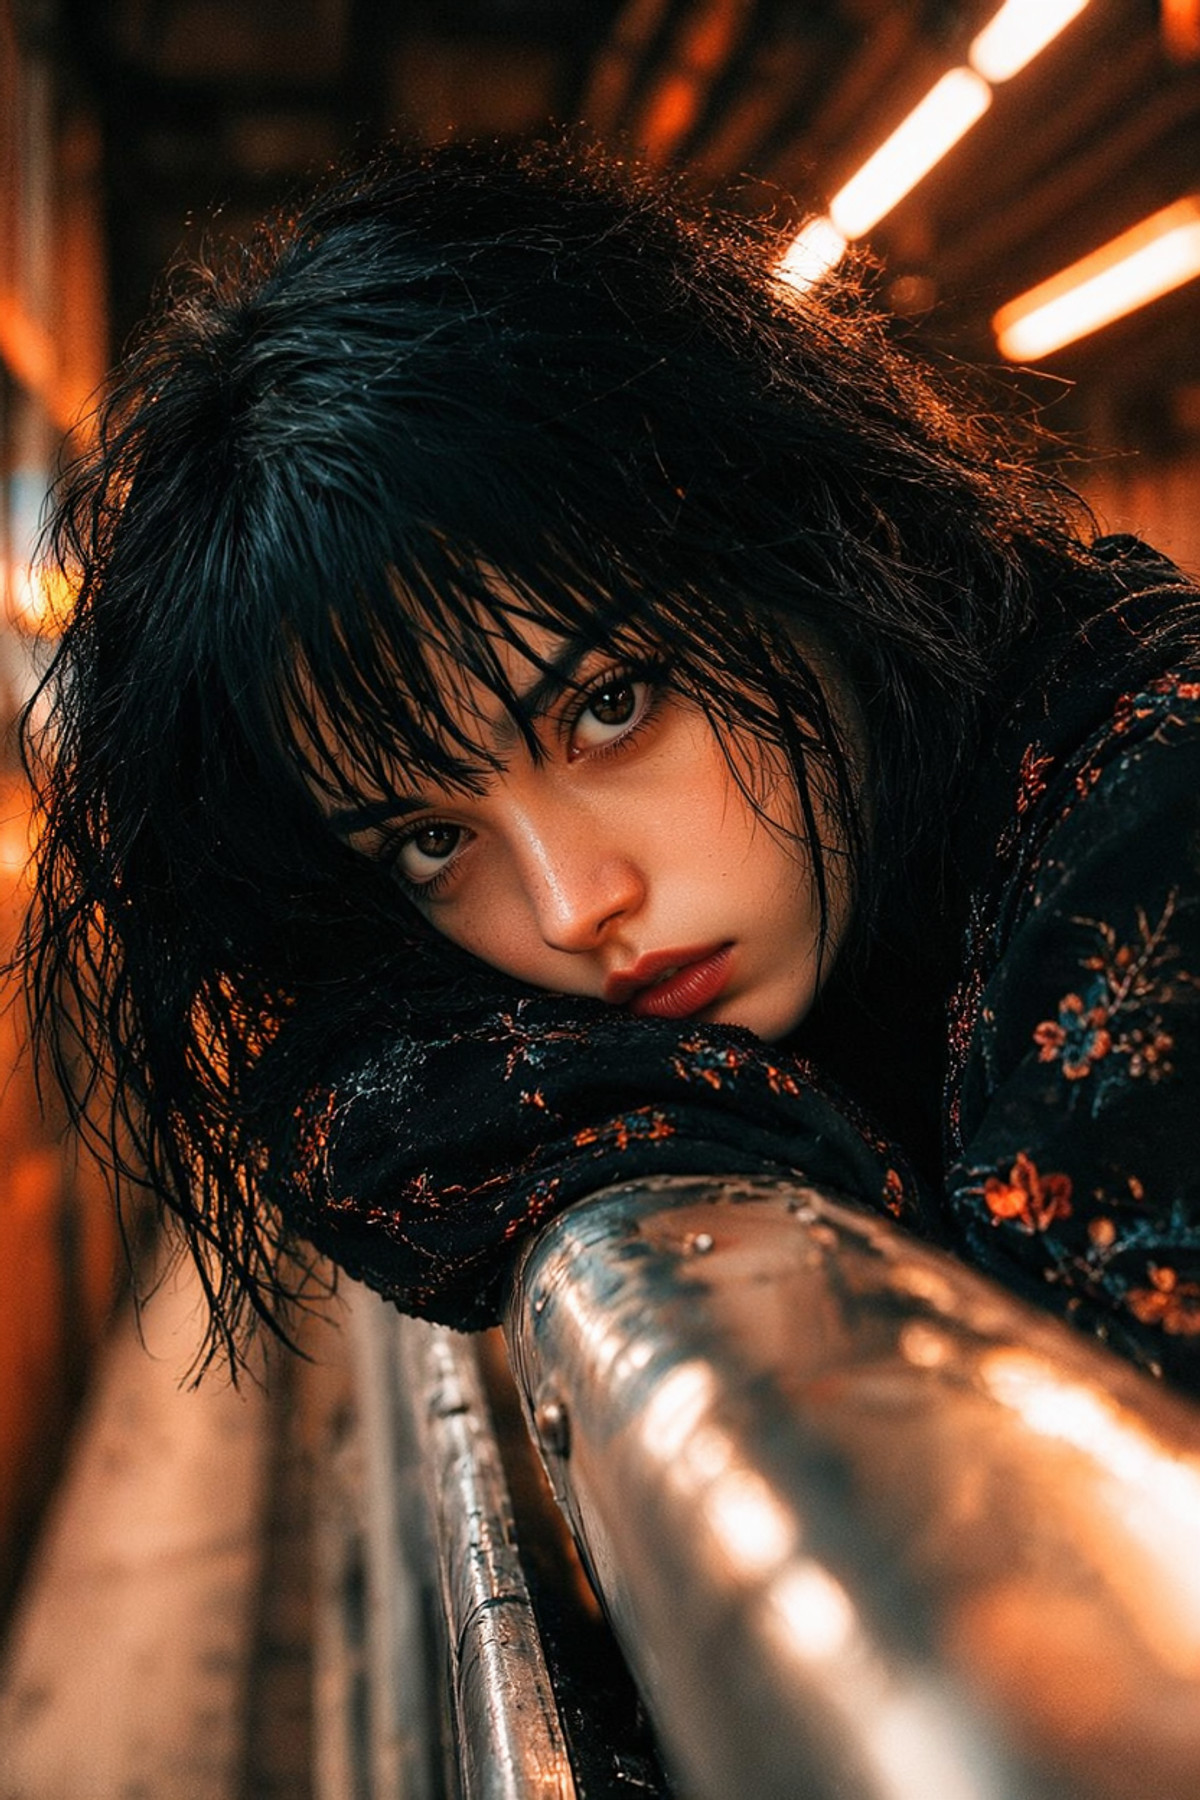
[A] The Look · v1.0 Moss
LoRA · Port · Author Daalis · Published 11-12 03:04 · Downloads 67
The MOSS version of The Look: Helps portraits avoid the common AI issue of dull, direct gazes, providing more diverse expressions, gaze directions, and head angles.
Images
Reasons for Recommendation
- Port (the page already has Krea 2, Anima, Flux.2 Klein, Z-Image Turbo, Qwen, Illustrious, Flux.1, etc.); the MOSS version description is just one sentence: It took several tries to get a version that doesn't always look shocked, doesn't have over-the-top emotions, and doesn't deviate from the subject
- Serves portraits and character images: Expressions and gazes such as smiling, focused, looking sideways, and daydreaming, as well as natural head tilts and poses; the author claims it works with realistic, painting, and anime styles
- Trigger word
LookDaal, strength 1.0; the author also released a set of random prompt wildcards; 4 visible example images
How to Use
- Add
LookDaalto the prompt and clearly specify expression, gaze, and emotion; strength 1.0; the author did not provide steps or CFG - Can be stacked with clothing, background, and lighting LoRAs
Risks and Limitations
- The model card body text was written for the initial Flux release; the MOSS version has no separate parameters; 3 examples are hidden, and the page contains mixed content
- The cumulative 11918 downloads for the entire page are the total for multiple base model versions, indicating only the level of attention
Trigger Word: LookDaal
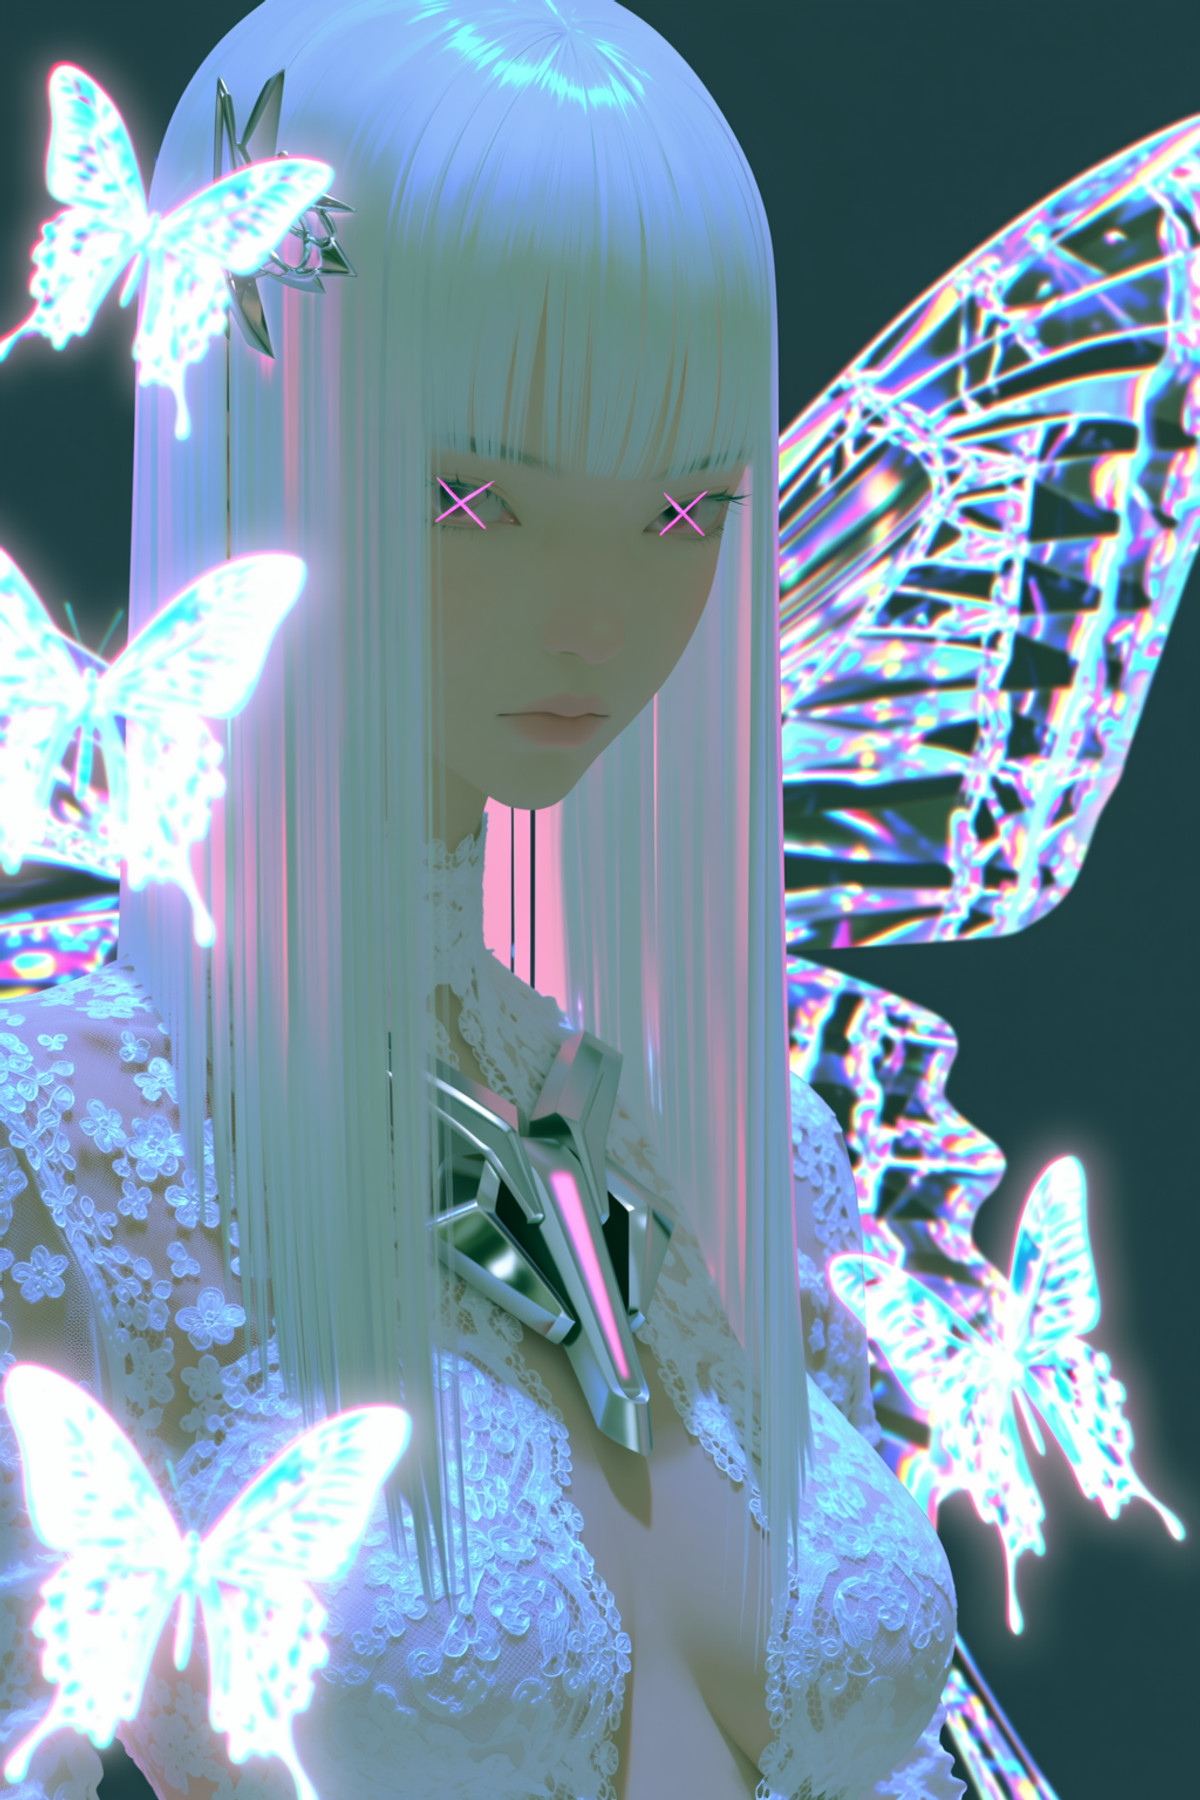
[A] AG: Glasya - Surrealistic Sparkle · MOSS-Image
LoRA · Port · Author Azriaelis · Published 11-12 09:10 · Downloads 11
The MOSS version of the Glasya style LoRA from the Ars Goetia series: The author describes it as a surreal, semi-realistic painting style with glittery particles.
Downgraded from automatic S to A: Parameters are complete, but the author admits it is experimental in nature, and the style is not described.
Images
Reasons for Recommendation
- Port (the page already has Krea 2 and Anima versions): The MOSS version provides specific settings—MOSS Base with 8 step Turbo LoRA, euler + simple, strength 0.8-1.2, 8-16 steps, CFG 1-3
- Trigger word
@GL4SY4R4V; the author claims the style becomes much stronger when the trigger word is added; 15 visible example images - The author says this series is a series of small experiments done on a whim, with varying quality across the LoRAs, and training images are mixed from sources like Midjourney, NijiJourney, and Tumblr
How to Use
- Add
@GL4SY4R4Vto the prompt; MOSS Base + 8 step Turbo LoRA, euler, simple, strength 0.8-1.2, 8-16 steps, CFG 1-3
Risks and Limitations
- The style is only defined by name and tags, with no textual description of visual features; training images include other AI-generated images and web images with unclear sources
- 5 examples are hidden; the license does not allow derivatives
Trigger Word: @GL4SY4R4V
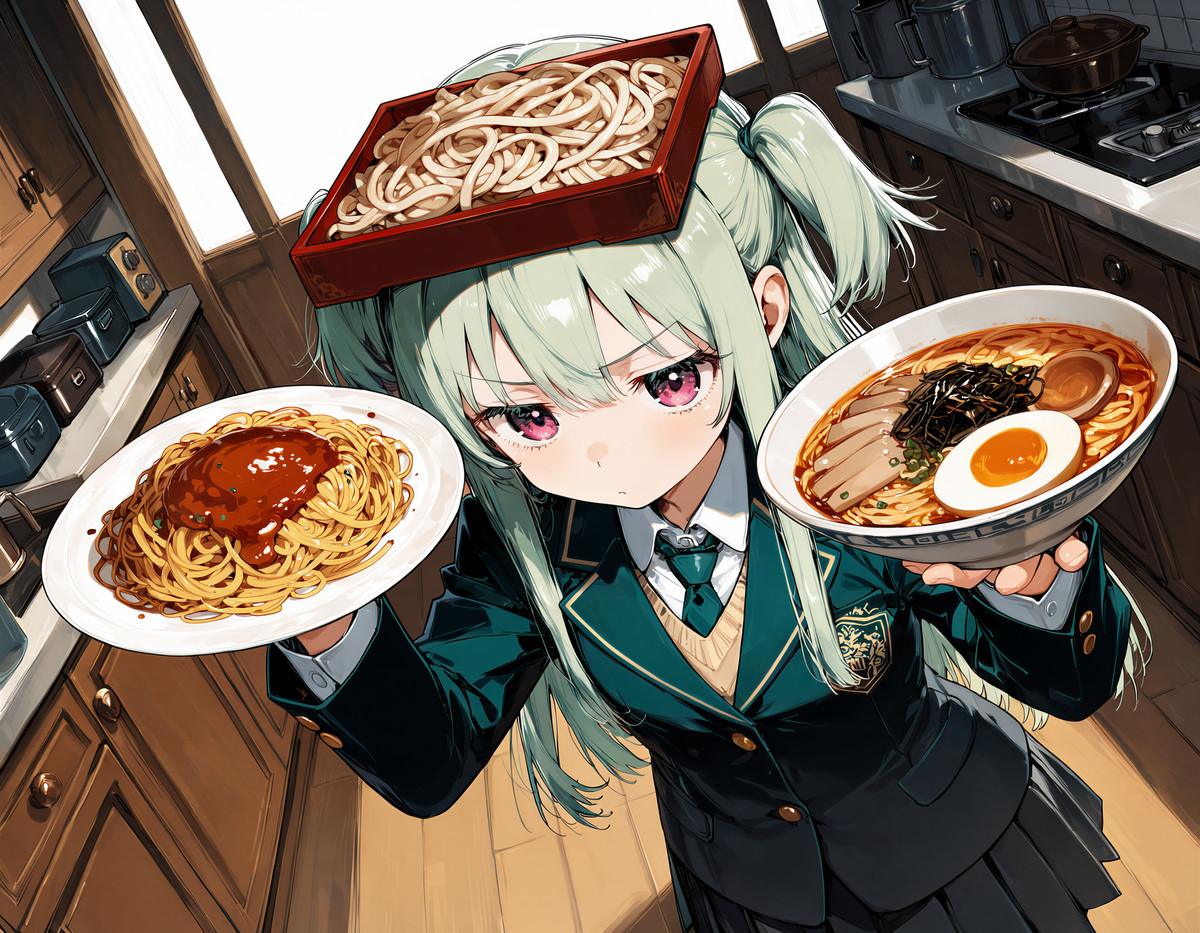
[A] MOSS-RiceBranOil-MoreOily · v01.0
Base Model / Checkpoint · New Model · Author toshi_autumn · Published 11-12 01:25 · Downloads 34
MOSS-RiceBranOil-MoreOily: A "more oily" branch base model obtained when redoing RiceBranOilMix, with a heavier oil painting feel and more prominent eyelashes than the standard version.
Downgraded from automatic S to A: Same origin as the new version of the standard RiceBranOilMix, with few visible examples.
Images
Reasons for Recommendation
- New model; the author claims it is a byproduct of redoing RiceBranOilMix, with an art style that better fits their personal preferences, and suggests using it in combination with the standard version depending on the desired effect
- Tuning direction: Heavier oil paint / painterly coloring, denser eyelashes, thin eyebrows, thin lips; base model is MOSS-Image-Base
- Parameters are the same as the standard version: 40 - 55 steps, CFG 3.0, dpmpp_2m_sde, normal or simple, denoise 0.90 - 1.00, Skip Layer Guidance is recommended (single layer 22, 0.000–0.500); 3 visible example images
How to Use
- Load by replacing the base model (INT8 convrot single file); add
This is anime-style illustration.to the positive prompt, and use the string of quality words provided by the author for the negative prompt - 40 - 55 steps, CFG 3.0, dpmpp_2m_sde; euler and res_multistep are not recommended; hand gestures must be specified in the prompt
Risks and Limitations
- 4 examples are hidden, and the page contains mixed content; the author self-describes it as an "unhealthy" taste version
- Contains only the diffusion model; text encoder and VAE must be prepared separately; Turbo LoRA compatibility has not been tested by the author
[A] MOSS-RiceBranOilMix · v02.0
Base Model / Checkpoint · Version Update · Author toshi_autumn · Published 11-12 01:25 · Downloads 40
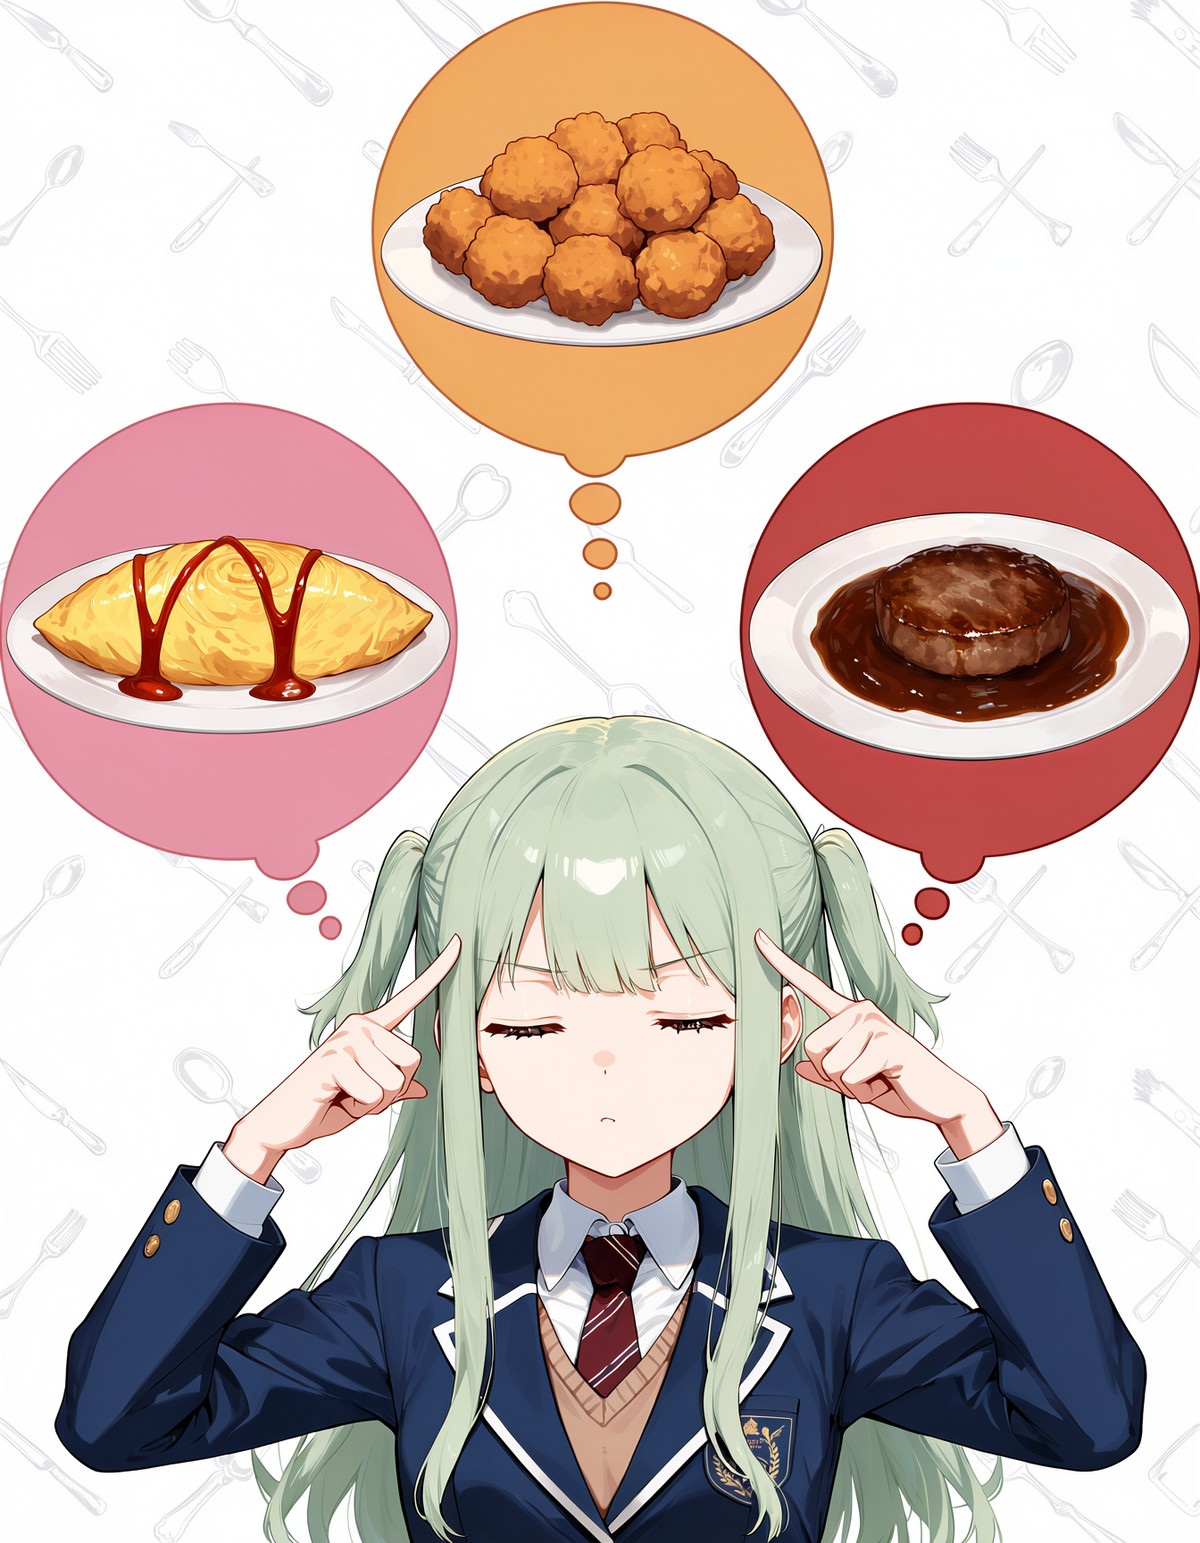
MOSS-RiceBranOilMix v02.0: An anime illustration base model with an oil painting / impasto texture; this version was redone from scratch to improve prompt response.
The same author released the "more oily" MOSS-RiceBranOil-MoreOily on the same day; both have the same parameters, so you can choose one based on the desired oil painting intensity.
Images
Reasons for Recommendation
- Version update: v01.0 was reported to have poor prompt response, so the author redid it from scratch and changed the base model from MOSS-Image-SFT to MOSS-Image-Base; the author says the art style is therefore somewhat different from v01.0 but closer to their original intent
- Tuning goals: Add oil painting / painterly texture, beautiful eyes and dense eyelashes, thin eyebrows, thin lips
- Parameters are fully provided: 40 - 55 steps, CFG 3.0, dpmpp_2m_sde, normal or simple, denoise 0.90 - 1.00; Skip Layer Guidance is recommended (single layer 22, 0.000–0.500)
How to Use
- Load by replacing the base model (INT8 convrot single file); add
This is anime-style illustration.to the positive prompt, and useworst quality, bad anatomy, bad hands, extra fingers, watermark, jpeg artifactfor the negative prompt - 40 - 55 steps, CFG 3.0, dpmpp_2m_sde, normal / simple; euler and res_multistep are not recommended (the author claims they produce too much detail); hand gestures must be specified in the prompt
Risks and Limitations
- Only 2 visible examples, 5 are hidden, and the page contains mixed content
- Contains only the diffusion model; text encoder and VAE must be prepared separately, and the INT8 convrot format requires loader support; Turbo LoRA compatibility has not been tested by the author
[A] MOSS 12 Step Turbo · v8.0 SFT
LoRA · Version Update · Author anyMODE · Published 11-12 04:38 · Downloads 72
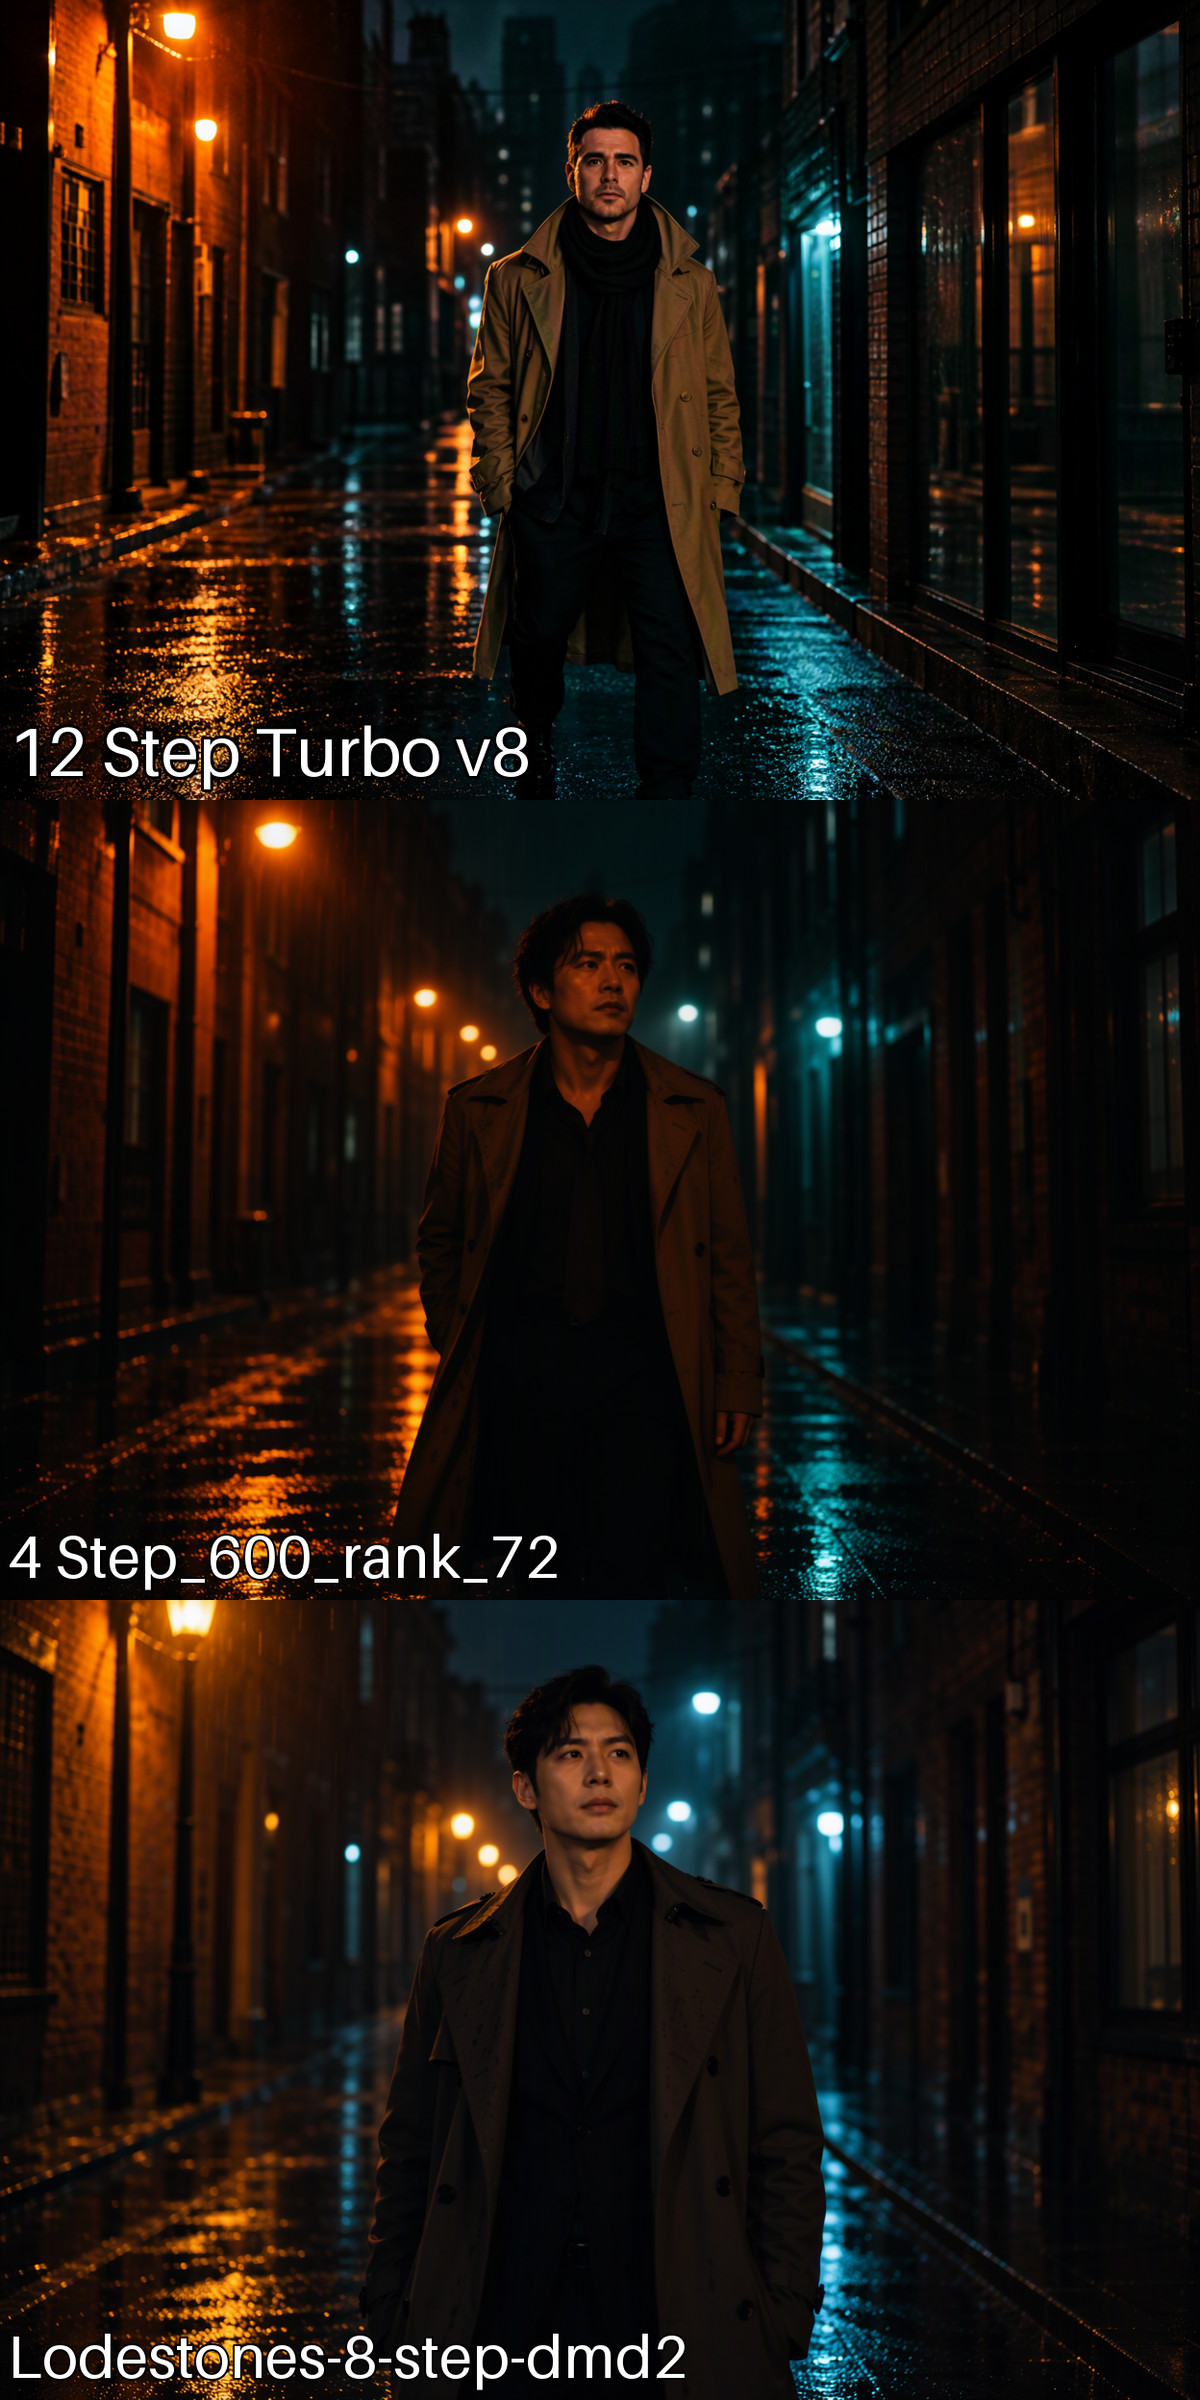
The third version of the MOSS 12 step acceleration distillation LoRA (Rank 64): After loading, it generates images in 12 steps with CFG 1.0, with no trigger word.
Downgraded from automatic S to A: Parameters can be followed, but this is a version update, and the changes are not clearly written.
Images
Reasons for Recommendation
- Version update: The update note is just one sentence: "Trained from scratch, not based on any other model"; the filename is marked v8, r64, while the previous version v5 had several files for r32 / r64, but the author did not write what the specific differences between the two versions are
- The author claims it was distilled directly from the 5.2B base model using online teacher-student trajectory matching, compressing the contrast, prompt adherence, and human anatomy of 24 steps and CFG 3.0 into 12 steps
- Usage is clear: In ComfyUI, use the simple scheduler, 12 steps, CFG 1.0, strength 1.0; 5 visible example image, none hidden
How to Use
- Load the LoRA, strength 1.0; 12 steps, CFG 1.0, simple scheduler; no trigger word, the sampler was not provided by the author
Risks and Limitations
- The author did not write what changed in this version compared to the previous one; the version name says SFT, but the description says it was distilled from the base model, and it is unclear whether it should be paired with Base or SFT
- "No quality loss" is the author's self-statement, and there are 1 downvotes
[A] StyleLoRA Ikusagami VERITA Style Battle Goddess VERITA Style | MOSS-Image-Base/SFT · sft v1.0
LoRA · Version Update · Author Moon_NE · Published 11-12 05:38 · Downloads 16
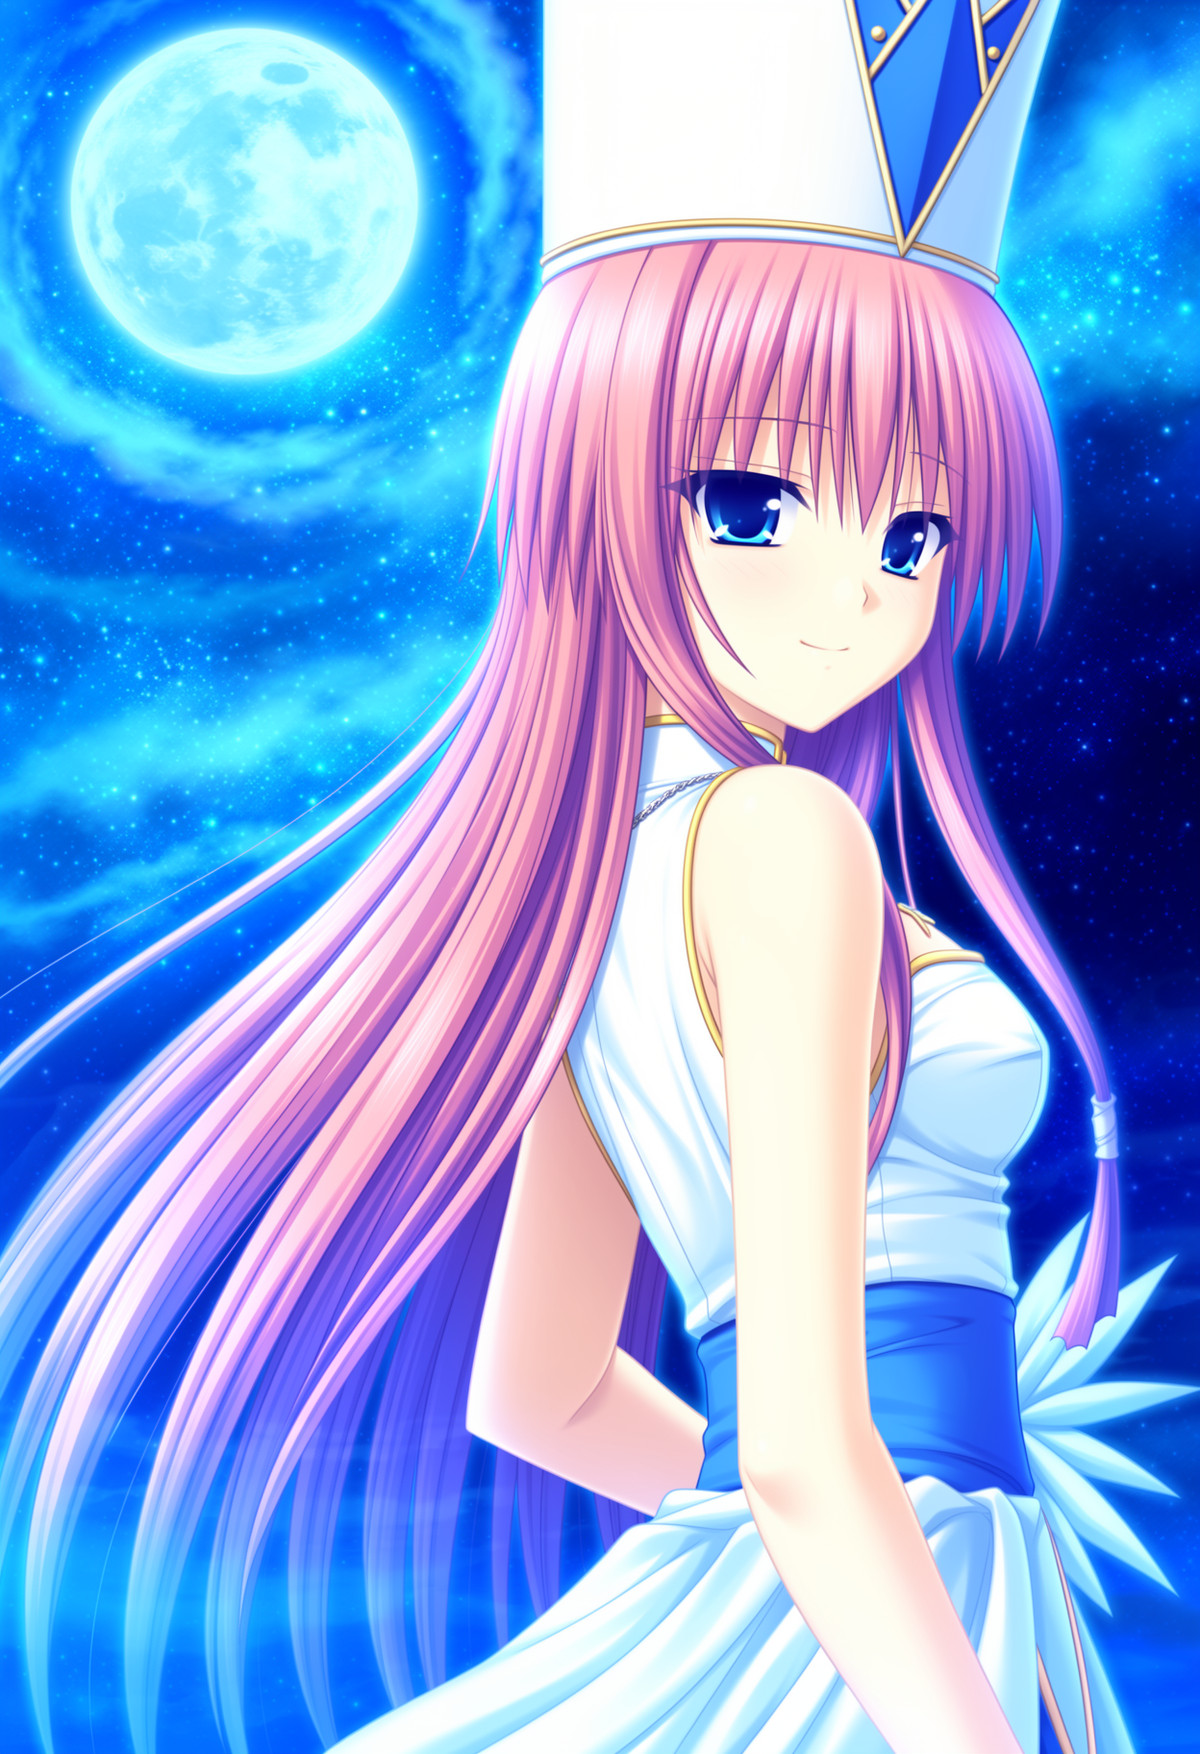
The MOSS SFT version of the art style LoRA trained on 2,194 CGs from the PC game Ikusagami VERITA: A fantasy illustration style with delicate anime line art, vibrant colors, and soft shadows.
Images
Reasons for Recommendation
- Version update: The previous version was the MOSS-Image-Base version; this is the first SFT version; the update note specifies the same 2,194 game CGs, trained for 2,000 steps, LoRA rank/alpha 32/32
- Serves those wanting Japanese fantasy RPG / galgame original art style anime illustrations; trigger word
ikusamegamiV, the author suggests starting strength at 1.0 and adjusting based on style intensity; 4 visible example images, none hidden
How to Use
- Add
ikusamegamiVto the prompt (written in the description, not registered as a trigger word); start adjusting strength from 1.0 - Use this version with the SFT base model, and use the base version on the same page with the Base base model; the author did not provide steps or CFG
Risks and Limitations
- The license is limited to personal non-commercial use; the author explicitly prohibits commercial use of the LoRA and generated images
- It is an unofficial fan LoRA, and the training data consists of game original art, with copyright belonging to the original rights holders; steps and CFG were not provided
【A】Cinematic Painterly | Game Illustration & Character Portrait for Qwen2.1/Moss · moss
LoRA · Port · Author chase1johnson1 · Published 11-12 02:52 · Downloads 30
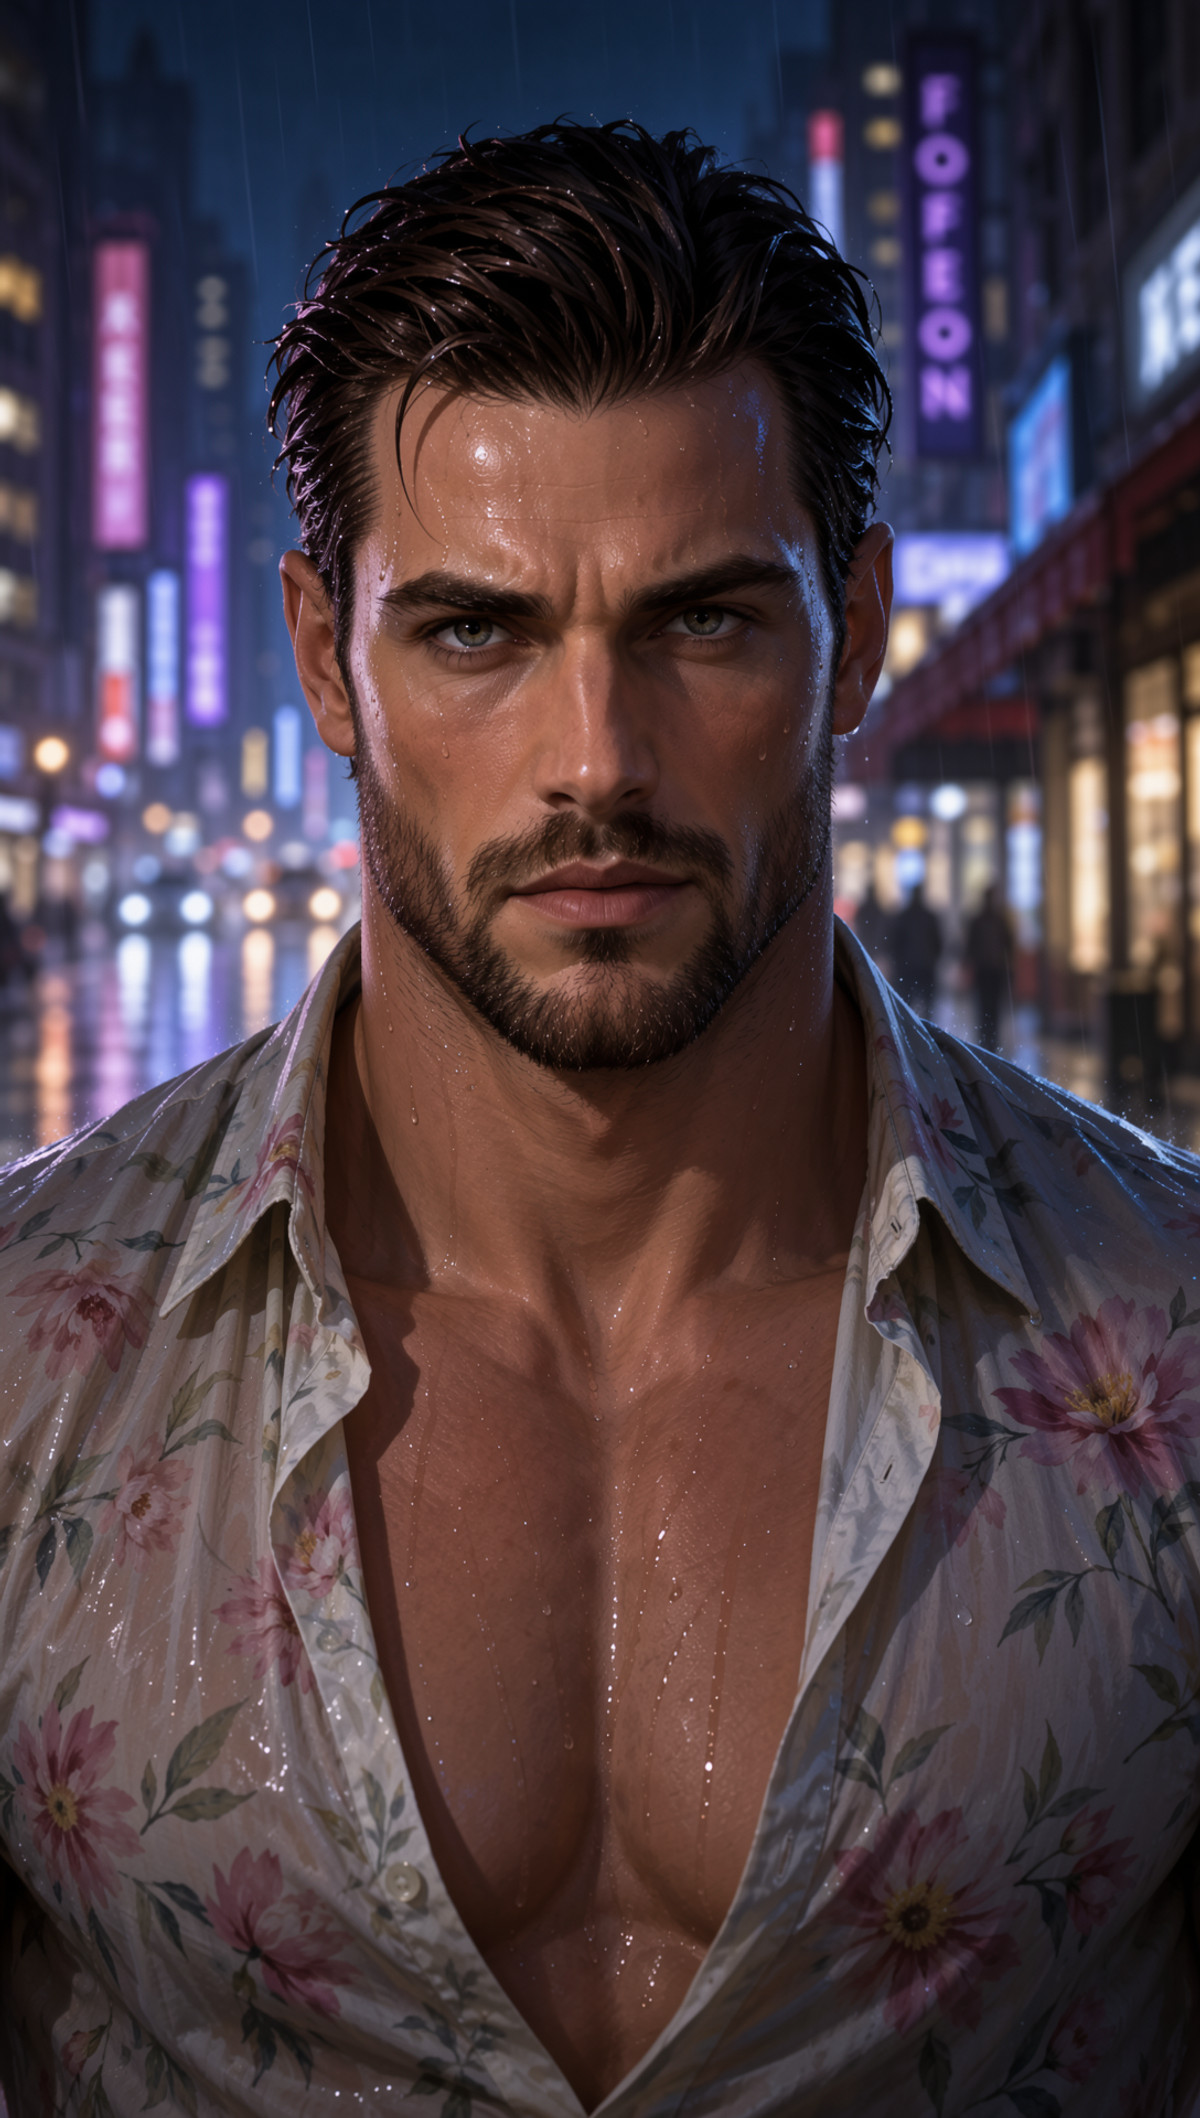
The MOSS version of the cinematic thick-paint style LoRA: focused on character portraits and figure illustrations, featuring dramatic lighting, visible brushstrokes, and detailed textures for skin, hair, fabric, leather, and metal.
Images
Reasons to Recommend
- Port (Qwen 2.1 version already on the same page): The MOSS version author only added a note—without the 8-step acceleration LoRA, it may require around 25 steps
- Serves character standing illustrations and cinematic portraits for genres like fantasy, dark fantasy, and cyberpunk; the author claims that faces of different characters do not easily converge, it works for both human and non-human characters, and is best suited for night scenes, rain, neon, and strong directional light
- Strength 0.6–1.0: Low strength approaches realism with only subtle brushstrokes, high strength has heavier lighting and brushstrokes; trigger word cine1p; 3 visible example images
How to Use
- Add cine1p to the prompt; strength 0.6–1.0, adjust according to the desired painting feel
- Approximately 25 steps if not using the 8-step acceleration LoRA; CFG not provided by the author
Risks and Limitations
- The author states that limbs such as hands and arms may be incorrect in complex poses; this LoRA does not perform anatomical correction
- 3 examples are hidden, the page contains mixed content; the MOSS version has no separate description, the text follows the Qwen 2.1 version
Trigger Words: cine1p
【A】[Moss Edit] Anime2Real Workflow (Anime to Realistic) · v3.0
Workflow · Version Update · Author xmsthc · Published 11-12 00:27 · Downloads 61
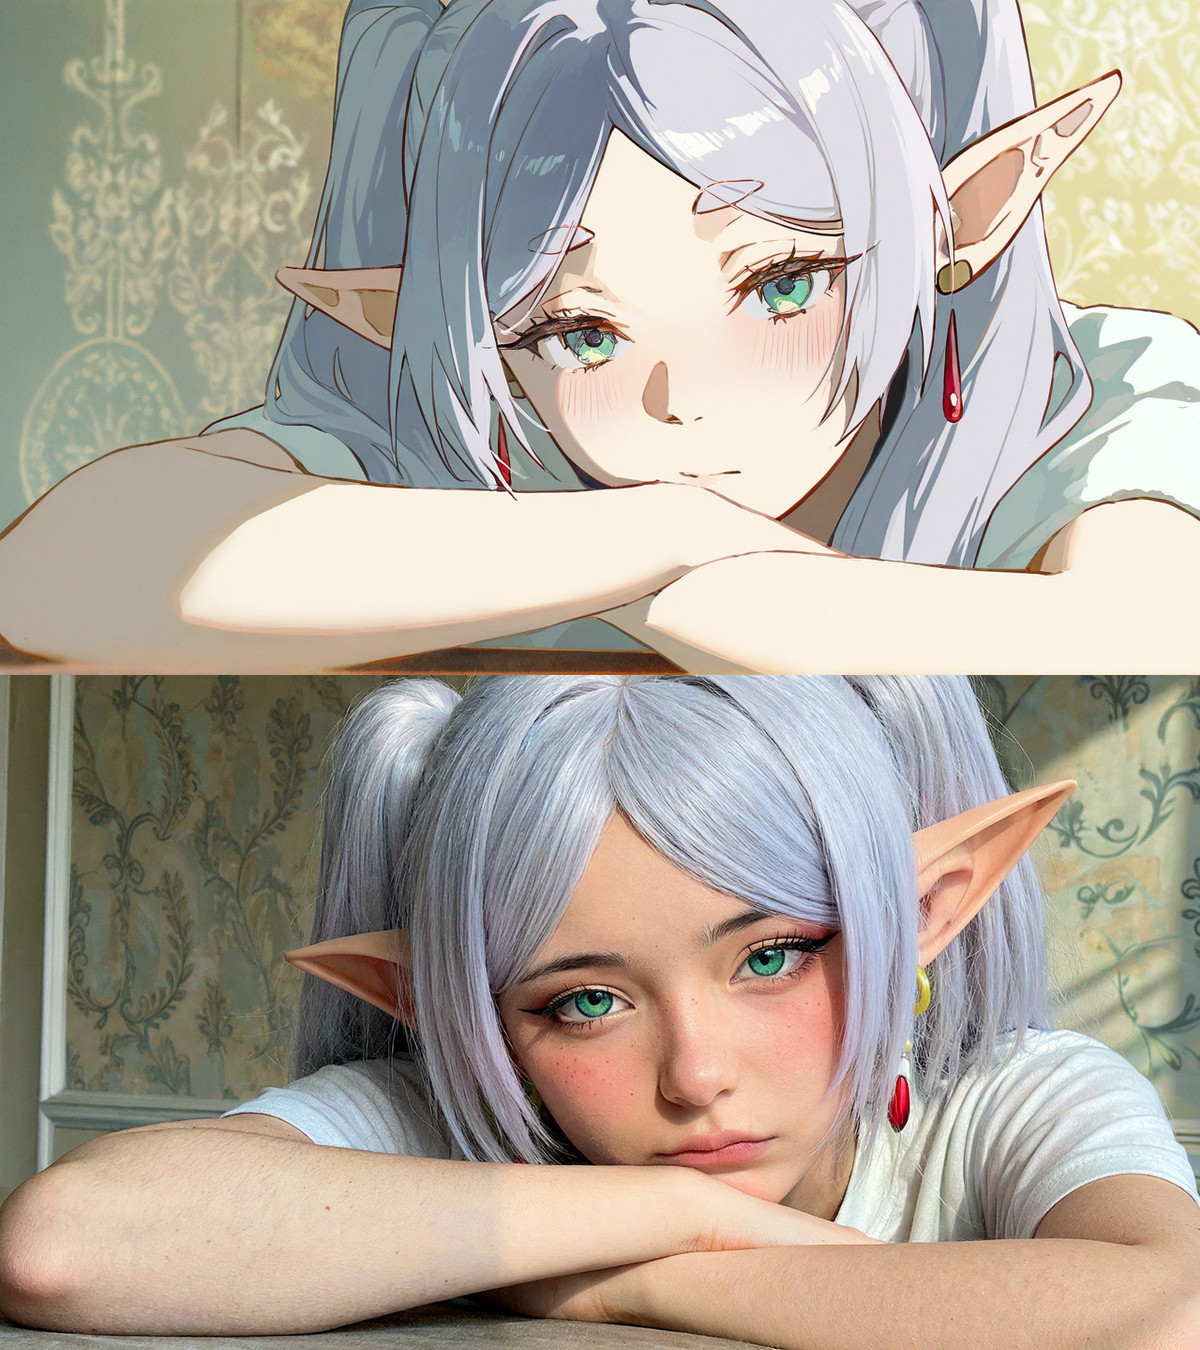
A ComfyUI workflow using the MOSS edit model to convert anime images into realistic photos; v3.0 mainly focuses on reducing VRAM usage and streamlining nodes.
Images
Reasons to Recommend
- Version update: Fixed VRAM peaks caused by the Ostris model patch node; added comfyui-h3-multishot node to release text encoder VRAM during generation; replaced Ostris Edit nodes with Comfy native nodes, and SageAttn with Comfy Kitchen Attn
- Also removed color transfer, SeedVR2 upscaling, and automatic prompt nodes; the author claims that 1536 pixels can now run on 12GiB graphics cards
- Serves image-to-image: input an anime image, output a realistic version; the author recommends pairing it with their [Moss Edit] Anime2Real LoRA (model page 3009913); the model page has accumulated 2218 downloads, which only indicates attention level
How to Use
- Import [I2I] A2R V3.json, install the comfyui-h3-multishot custom node, then load the author's accompanying Anime2Real LoRA
- If VRAM still overflows, lower the Long Side Target of Unified Resize Image / Mask from 1536 to 1376 or lower; steps and CFG should follow the presets within the workflow
Risks and Limitations
- It is a workflow JSON, not new weights; the accompanying LoRA link points to the civitai.red mirror domain
- This version has only 1 example images; the author did not state how the detail and tone of the final images compare to v2.0 after removing upscaling and color transfer
【A】BBox Studio · v1.0
Workflow · New Model · Author plk · Published 11-12 07:56 · Downloads 4
A desktop widget for drawing "bounding box layout prompts" for MOSS-Image: drag boxes on the canvas, write descriptions, and automatically generate bbox JSON in MOSS-Image format.
If you want to try MOSS's partitioned composition capabilities but are too lazy to calculate coordinates manually, you can use it to draw two or three boxes, export the JSON, and compare it with the official format.
Reasons to Recommend
- New tool (not weights): MOSS-Image supports specifying the position of each object, character, and text via structured JSON, but writing coordinates by hand is troublesome; this program turns it into a visual operation of dragging boxes, stretching, and double-clicking to edit descriptions, suitable for text-to-image generation requiring control over composition and multi-subject placement
- According to the GitHub instructions, each box can be set as one of three types—object / character / text—with individual descriptions; reference images can be imported as a base, the canvas can be set to common output resolutions, the output coordinates are in yxyx format with the canvas center as the origin, can be copied with one click or exported as .json, and existing layouts can be read back from PNG / JPEG metadata
- Written in pure Python + Tkinter, the compressed package is only 24 KB, requires no third-party packages, and can be run by double-clicking or via command line with bbox_studio.py
How to Use
- After unzipping, run python bbox_studio.py (requires Python 3.x with Tkinter)
- Set the canvas resolution → drag boxes and write descriptions for each box and the overall composition → copy the generated JSON and paste it into a workflow that supports MOSS-Image bbox layout prompts
- To continue editing, save as a .bbox project file; use .json for output; the author did not specify which MOSS node reads the JSON
Risks and Limitations
- Only 1 software interface screenshots, no example outputs generated with it, and the adherence of the layout JSON in MOSS is not demonstrated
- Requires running the Python script in the compressed package locally; it is recommended to review the source code first (public repository on GitHub); the README states "Coded with Grok, All rights reserved," which is inconsistent with the permissive license checked on Civitai
Worth Watching (6)
【B】Octanix - Semi Realistic 3D Style · v1.0
LoRA · New Model · Author trendingvibestar · Published 11-12 04:53 · Downloads 52
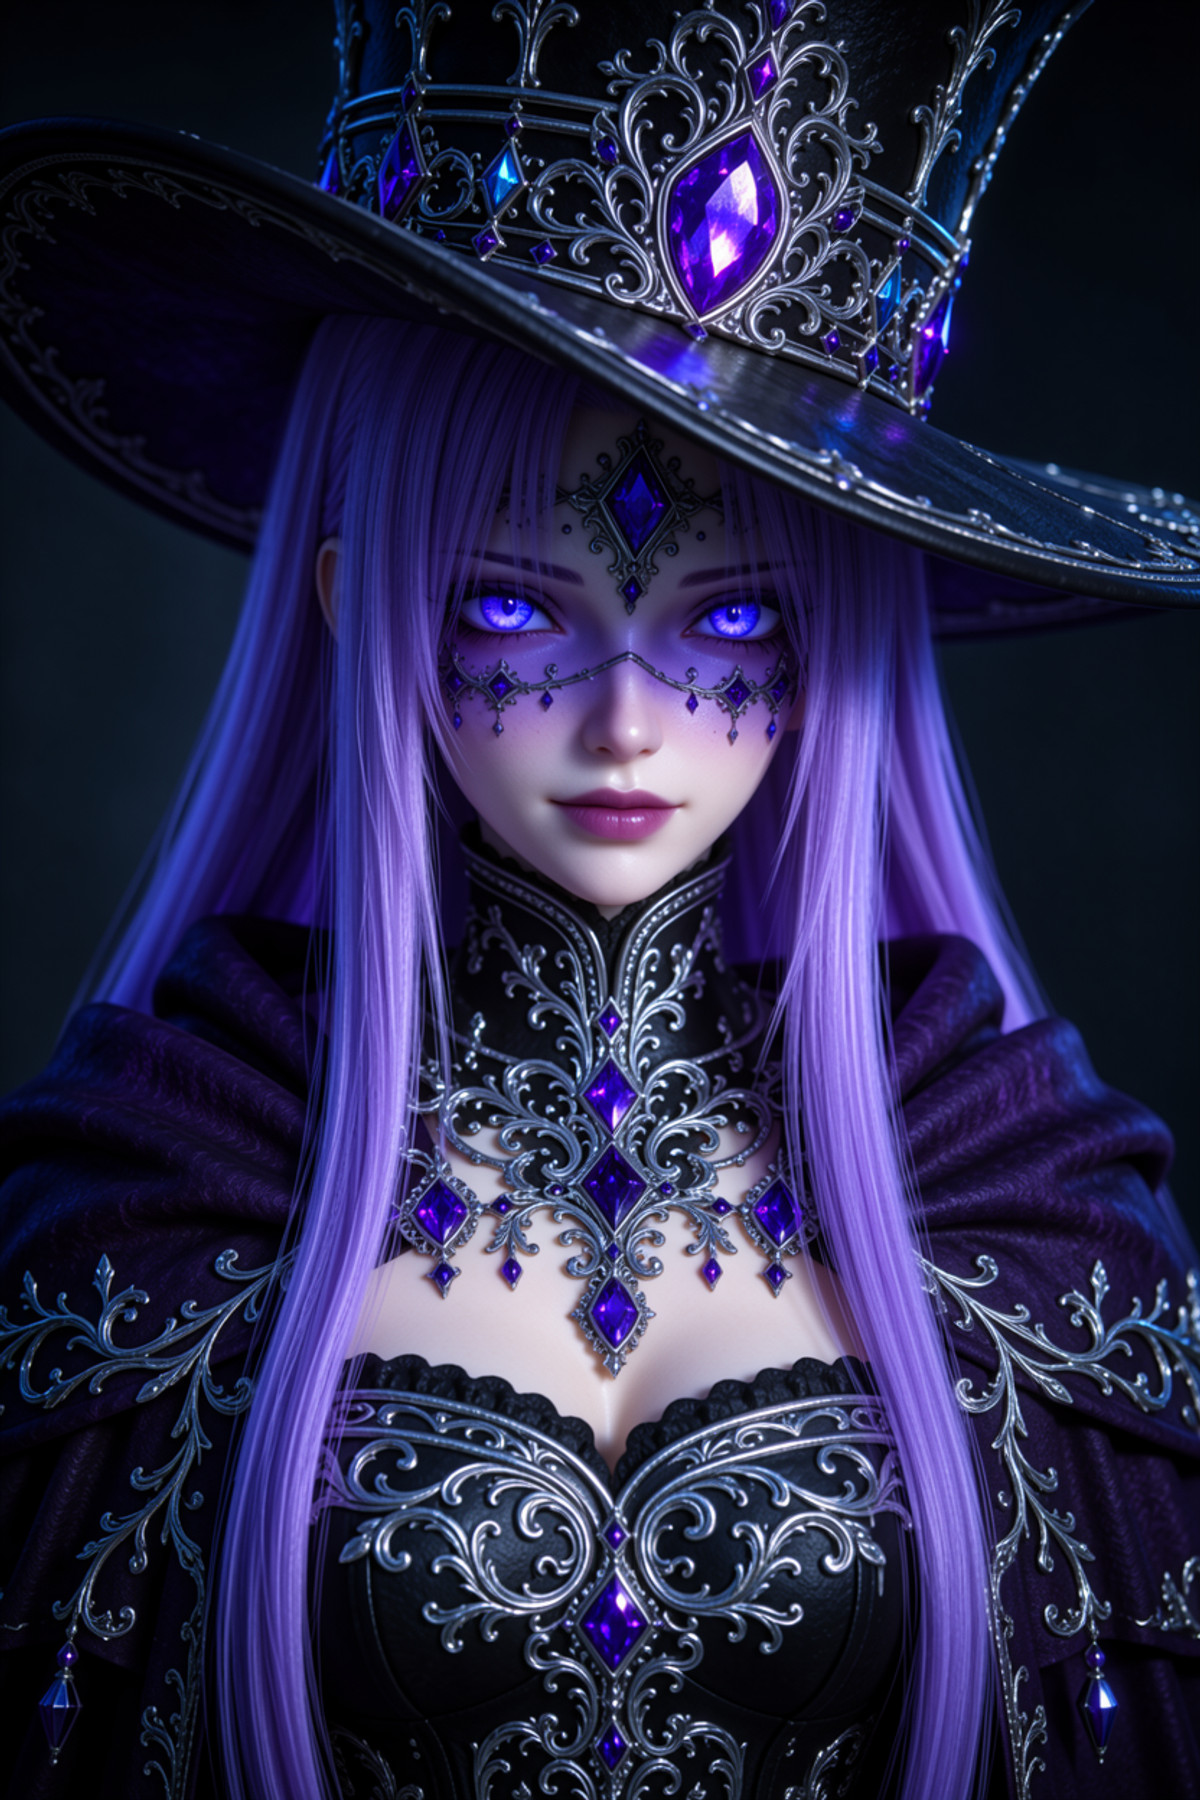
A semi-realistic 3D style LoRA named Octanix; judging by the title and tags, it has a texture similar to Octane rendering / game CG.
Downgraded from automatic S to B: No description other than trigger words and strength.
Images
Reasons to Recommend
- New model; direction is game characters, semi-realistic 3D rendered images
- Trigger word octanix, strength 0.75-1.0; 6 visible example images
How to Use
- Add octanix to the prompt; strength 0.75-1.0; steps and CFG not provided by the author
Risks and Limitations
- The description only has two lines for trigger words and strength; style characteristics rely entirely on judging from examples
- 6 examples are hidden
Trigger Words: Octanix
【B】Baichuan Baichuan Style [Anima/Krea2/MOSS] · MOSS v1.0
LoRA · Port · Author Imagine__That · Published 11-12 00:16 · Downloads 51
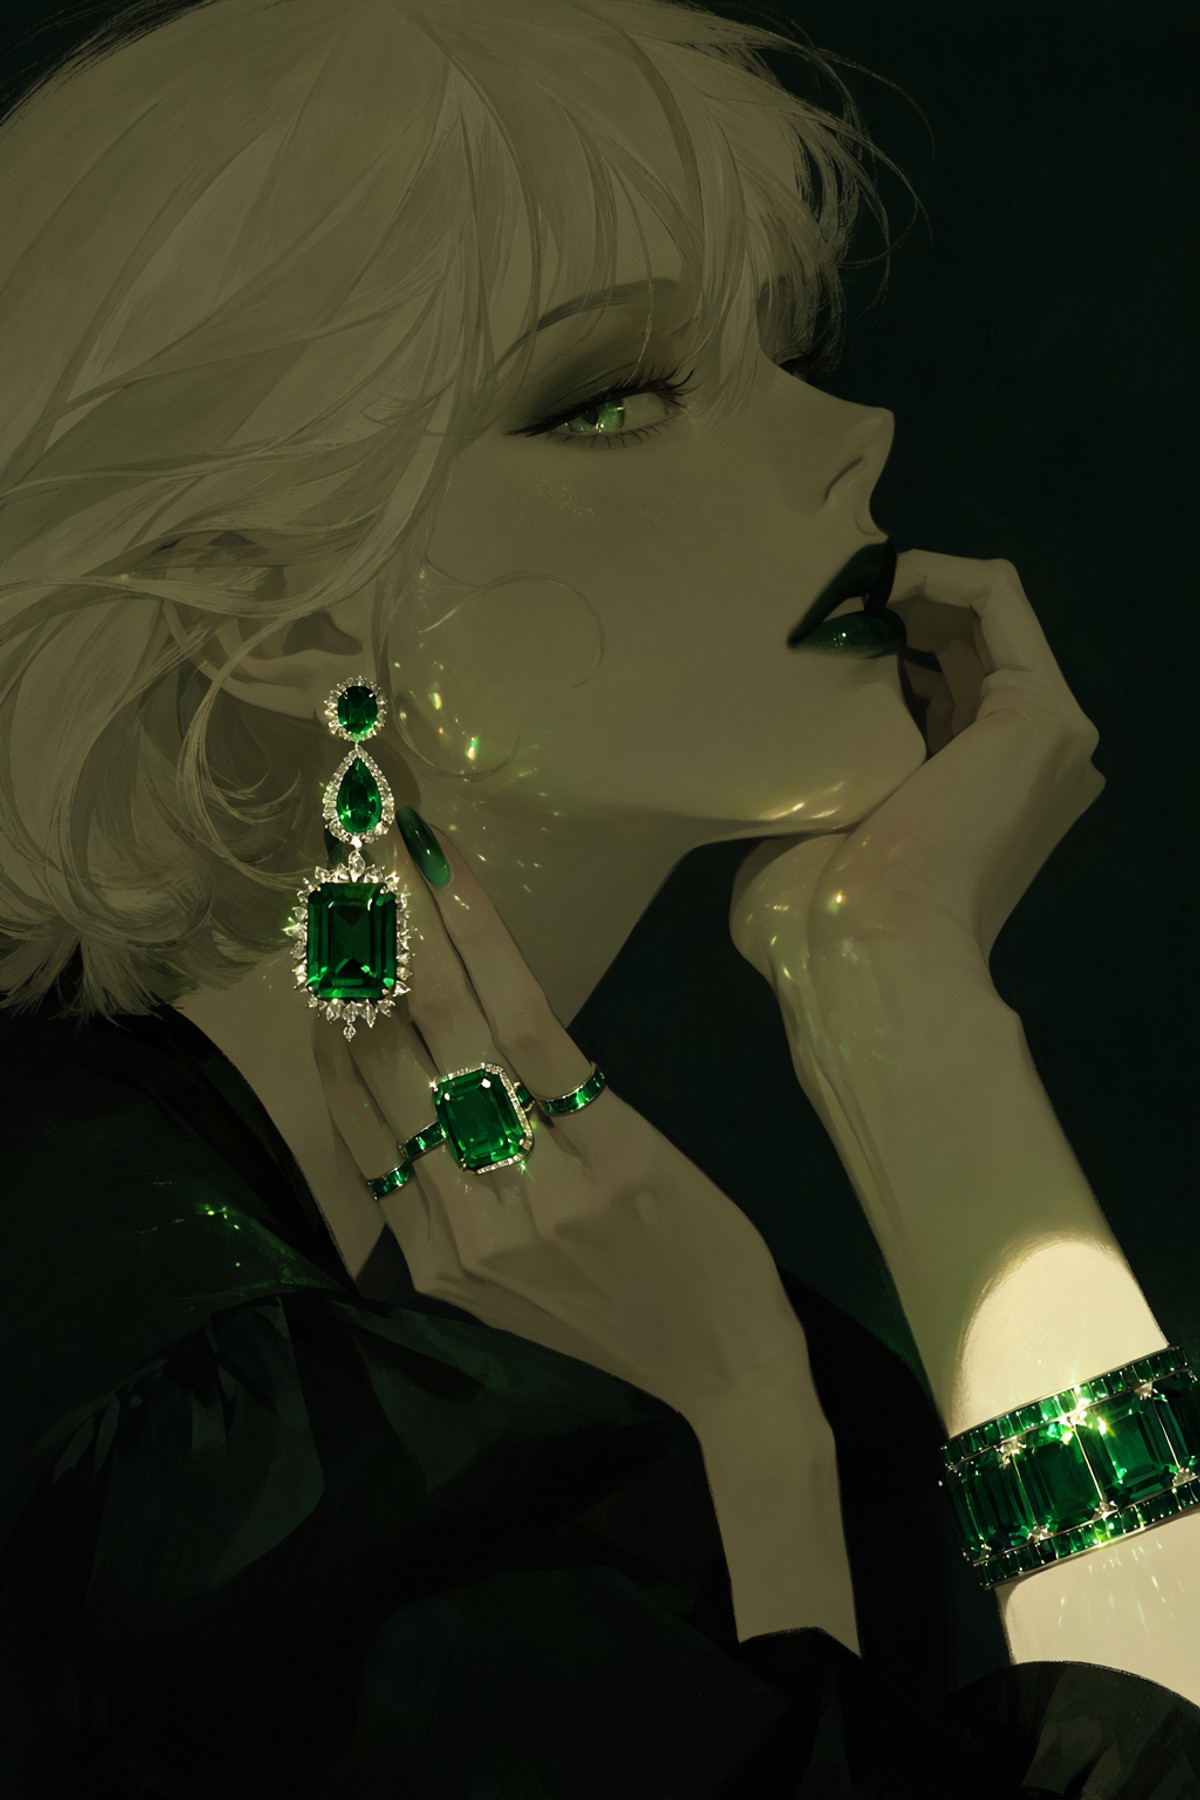
The MOSS version of a thick-paint style LoRA imitating the art style of artist baichuan_baichuan.
Downgraded from automatic S to B: The description is only three lines, with no description of the art style.
Images
Reasons to Recommend
- Port (Krea 2 and Anima versions already on the same page); the MOSS version has no separate description
- Strength 0.8-1.00 when used alone; 5 visible example image
How to Use
- The trigger word registered for the MOSS version is baichuanbaichuan (the @baichuan_baichuan written on the model card is for the Anima version); strength 0.8-1.00 when used alone; steps and CFG not provided by the author
Risks and Limitations
- Imitates the art style of a living artist, the license does not include commercial use of outputs
- No textual description of the style; 4 examples are hidden
Trigger Words: baichuanbaichuan
【B】Hyperdetailed Colored Pencil · MOSS
LoRA · Port · Author ArsMachina · Published 11-11 23:49 · Downloads 7 · Paid
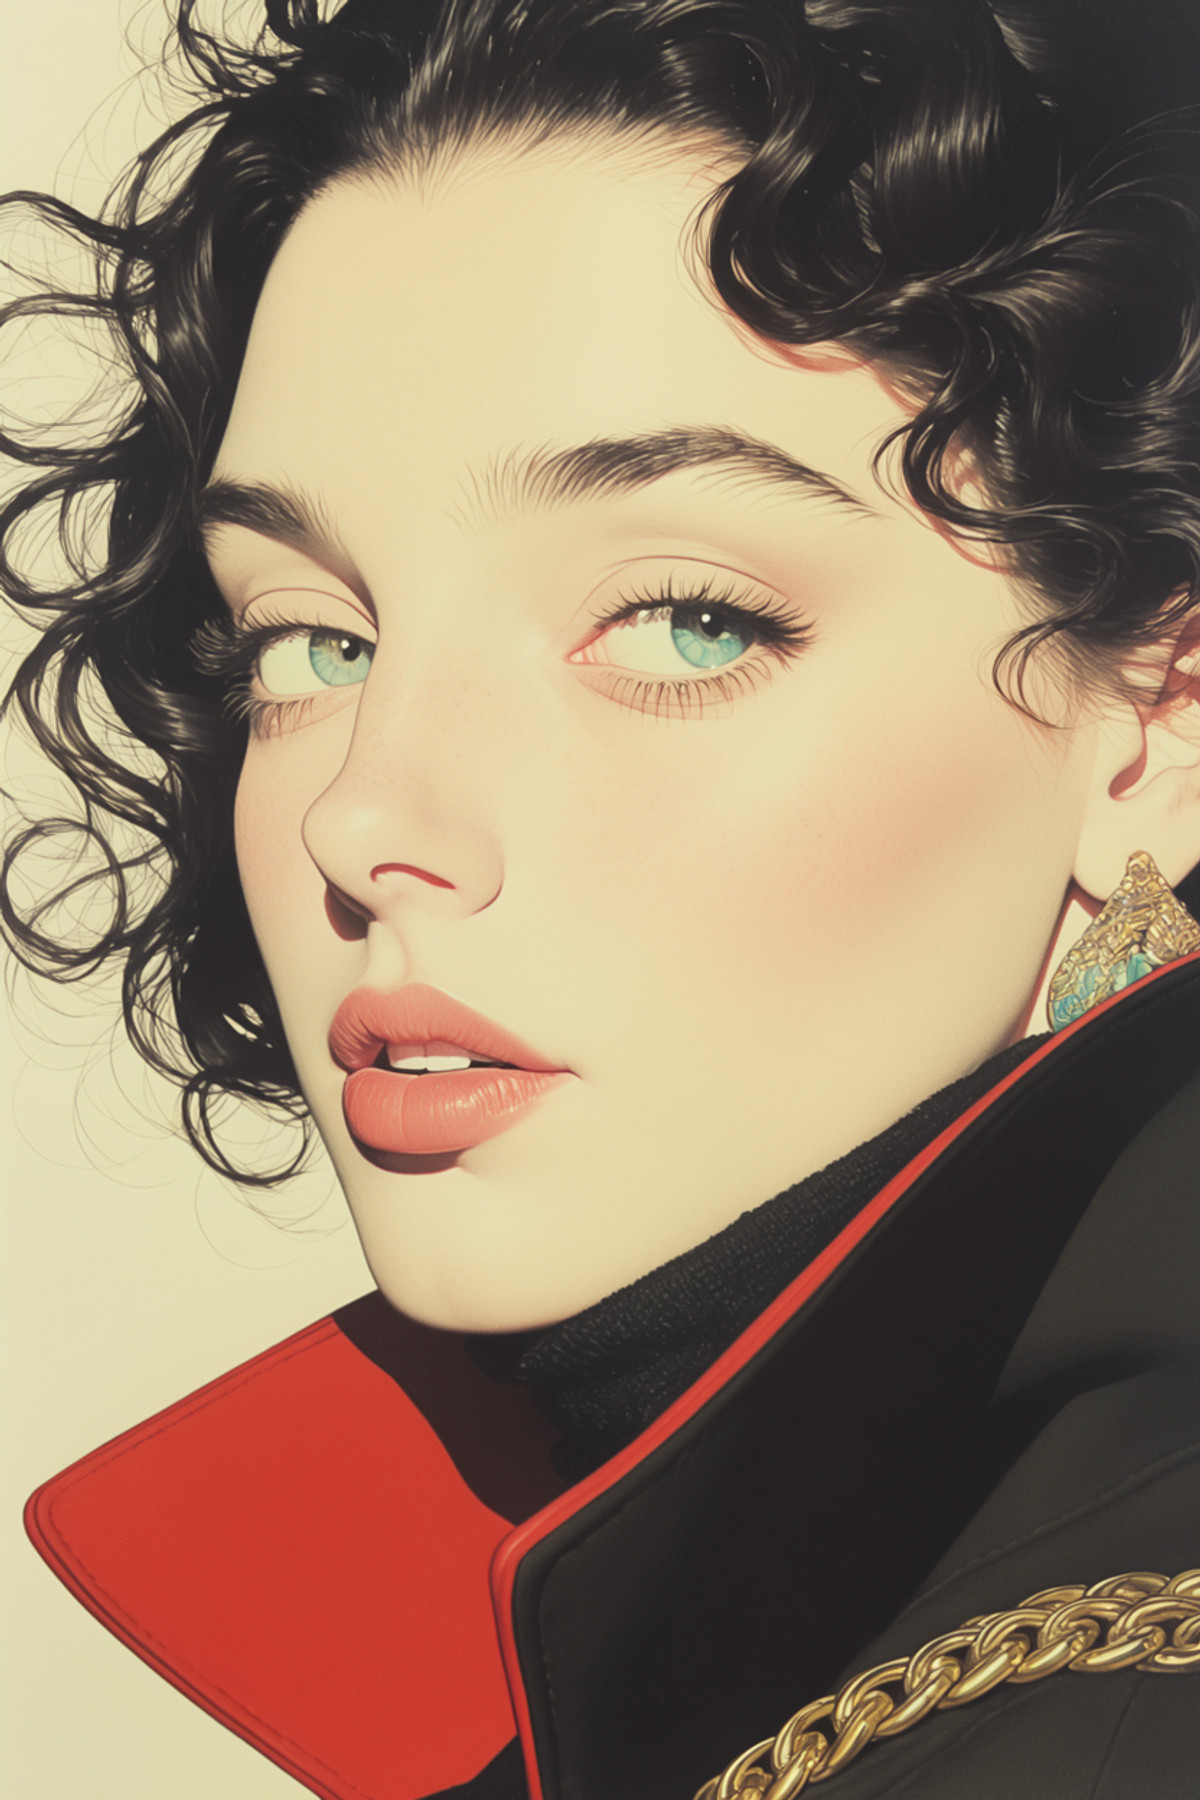
The MOSS version of ArsMachina's hyper-detailed colored pencil style LoRA: warm texture with fine hatching and colored pencil strokes, leaning towards character portraits, intricate clothing, and accessory details.
Images
Reasons to Recommend
- Port: Over a dozen base model versions including MiniMax H3, Krea 2, Qwen 2.1, Anima, Flux, and SDXL are already on the same page; the MOSS version provides both SFT and Base files at once, corresponding to two base models
- Trigger words ArsMJStyle, Colored pencil hyperdetailed realism; the author warns that acceleration (Turbo) LoRAs weaken the style, and when stacking, increase this LoRA's strength to 1.2–1.7, but this note is under the H3 version description, and it is not stated if the same applies to MOSS
- 13 example images, the author retained ComfyUI metadata, so workflows can be viewed
How to Use
- Add ArsMJStyle, Colored pencil hyperdetailed realism to the prompt; use the MossSft file for the SFT base model, and the MossBase file for the Base base model
- Strength, steps, and CFG not provided by the author; when stacking Turbo LoRA, refer to the H3 version's suggestion to increase strength
Risks and Limitations
- Paid download
- The model card is a general description for multiple base models, the MOSS version has no separate parameters; the license does not allow derivatives; 3 examples are hidden
Trigger Words: ArsMJStyle, Colored pencil hyperdetailed realism,
【B】CROWN Official ComfyUI Workflow: 2D Anime-to-Real 1:1 Photorealistic Redraw | MOSS-Image Edit · v1.0 - ComfyUI 0.43+ Native MOSS-Image Edit (ai-toolkit mode)
Workflow · New Model · Author NineCrowns · Published 11-11 22:40 · Downloads 40
A ComfyUI workflow packaged by NineCrowns for their "CROWN 2D Anime-to-Real 1:1" MOSS edit LoRA, redrawing anime images 1:1 into realistic photos, with the key being the preset edit_format = ai-toolkit.
Downgraded from automatic A to B: The workflow is not new weights, the value mainly lies in the edit_format setting tip, which users of their own MOSS edit workflows can also use for self-checking.
Images
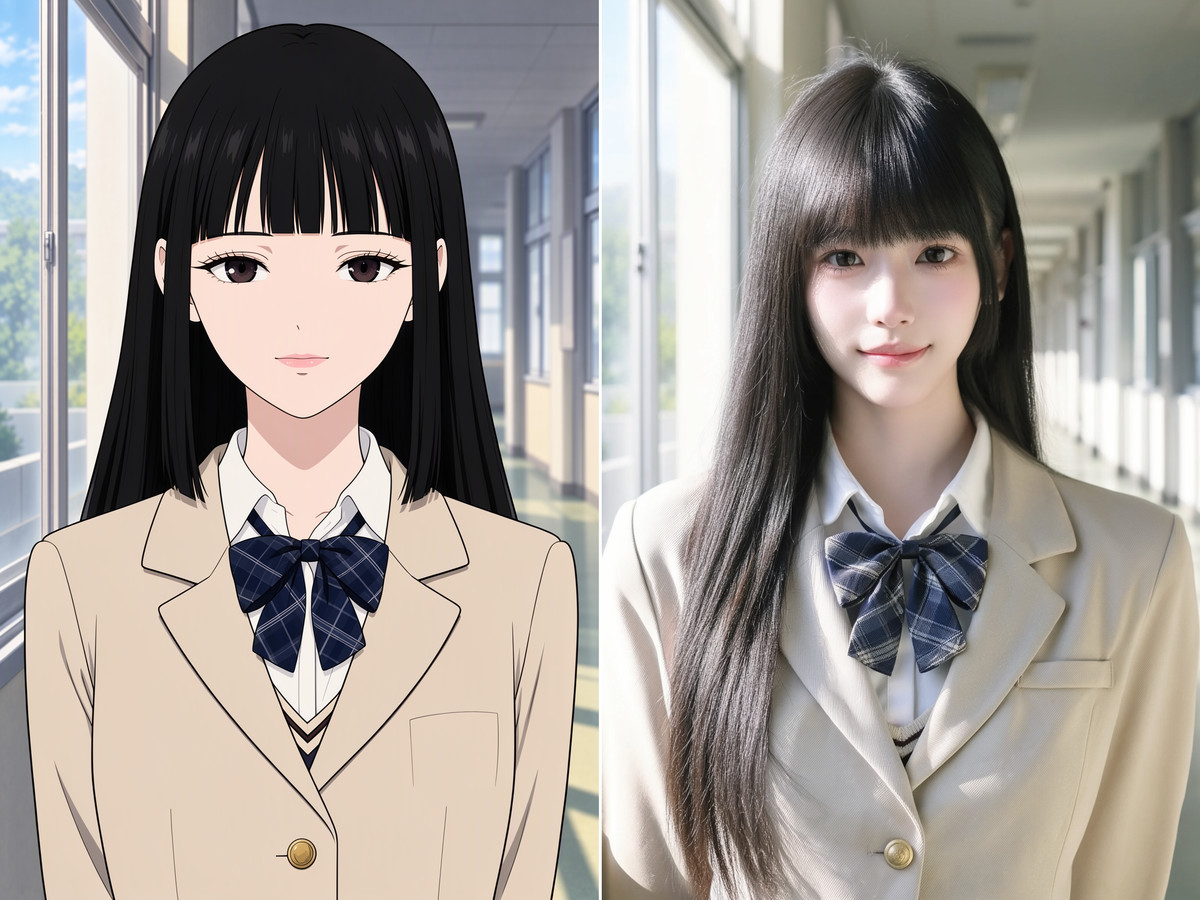
Reasons to Recommend
- Newly listed, but not new weights: Requires pairing with the same author's CROWN_MOSS_Image_Edit_Anime2Real_1to1_V1_r64 LoRA; the author claims that using this LoRA alone at strength 0.95 is sufficient, without needing to stack an edit LoRA
- Key point highlighted by the author: The built-in templates in ComfyUI 0.43.0 and above default edit_format to Moss-Image-Edit, which turns off the visual tokens of Qwen3.5-9B; both positive and negative TextEncodeMOSSImageEdit nodes need to be changed to ai-toolkit
- The compressed package contains the workflow JSON, draggable PNGs, example input images, and instructions; presets include 1024×1536 scaling, SkipLayerGuidanceDiTSimple layer 22, 28 steps, CFG 3.5; 3 visible example images
How to Use
- First, download the CROWN 2D Anime-to-Real 1:1 MOSS editing LoRA by the same author, with a strength of 0.95
- After importing the workflow, confirm that the edit_format for both the positive and negative TextEncodeMOSSImageEdit nodes is set to ai-toolkit; 28 steps and CFG 3.5 are pre-set
Risks and Limitations
- Relies on a LoRA from another page, which itself already includes a workflow zip file, causing overlap with this page
- Claims such as "100% standalone" are author marketing; 1 examples are hidden, and the page contains mixed content
[B] Neon Gothic · MOSS
LoRA · Version Update · Author ArsMachina · Published 11-11 23:52 · Downloads 2 · Paid
The MOSS version of the "Neon Gothic" style LoRA: a high-contrast dark fantasy art style featuring pastel goth, occult fantasy, and electric neon lighting.
Images
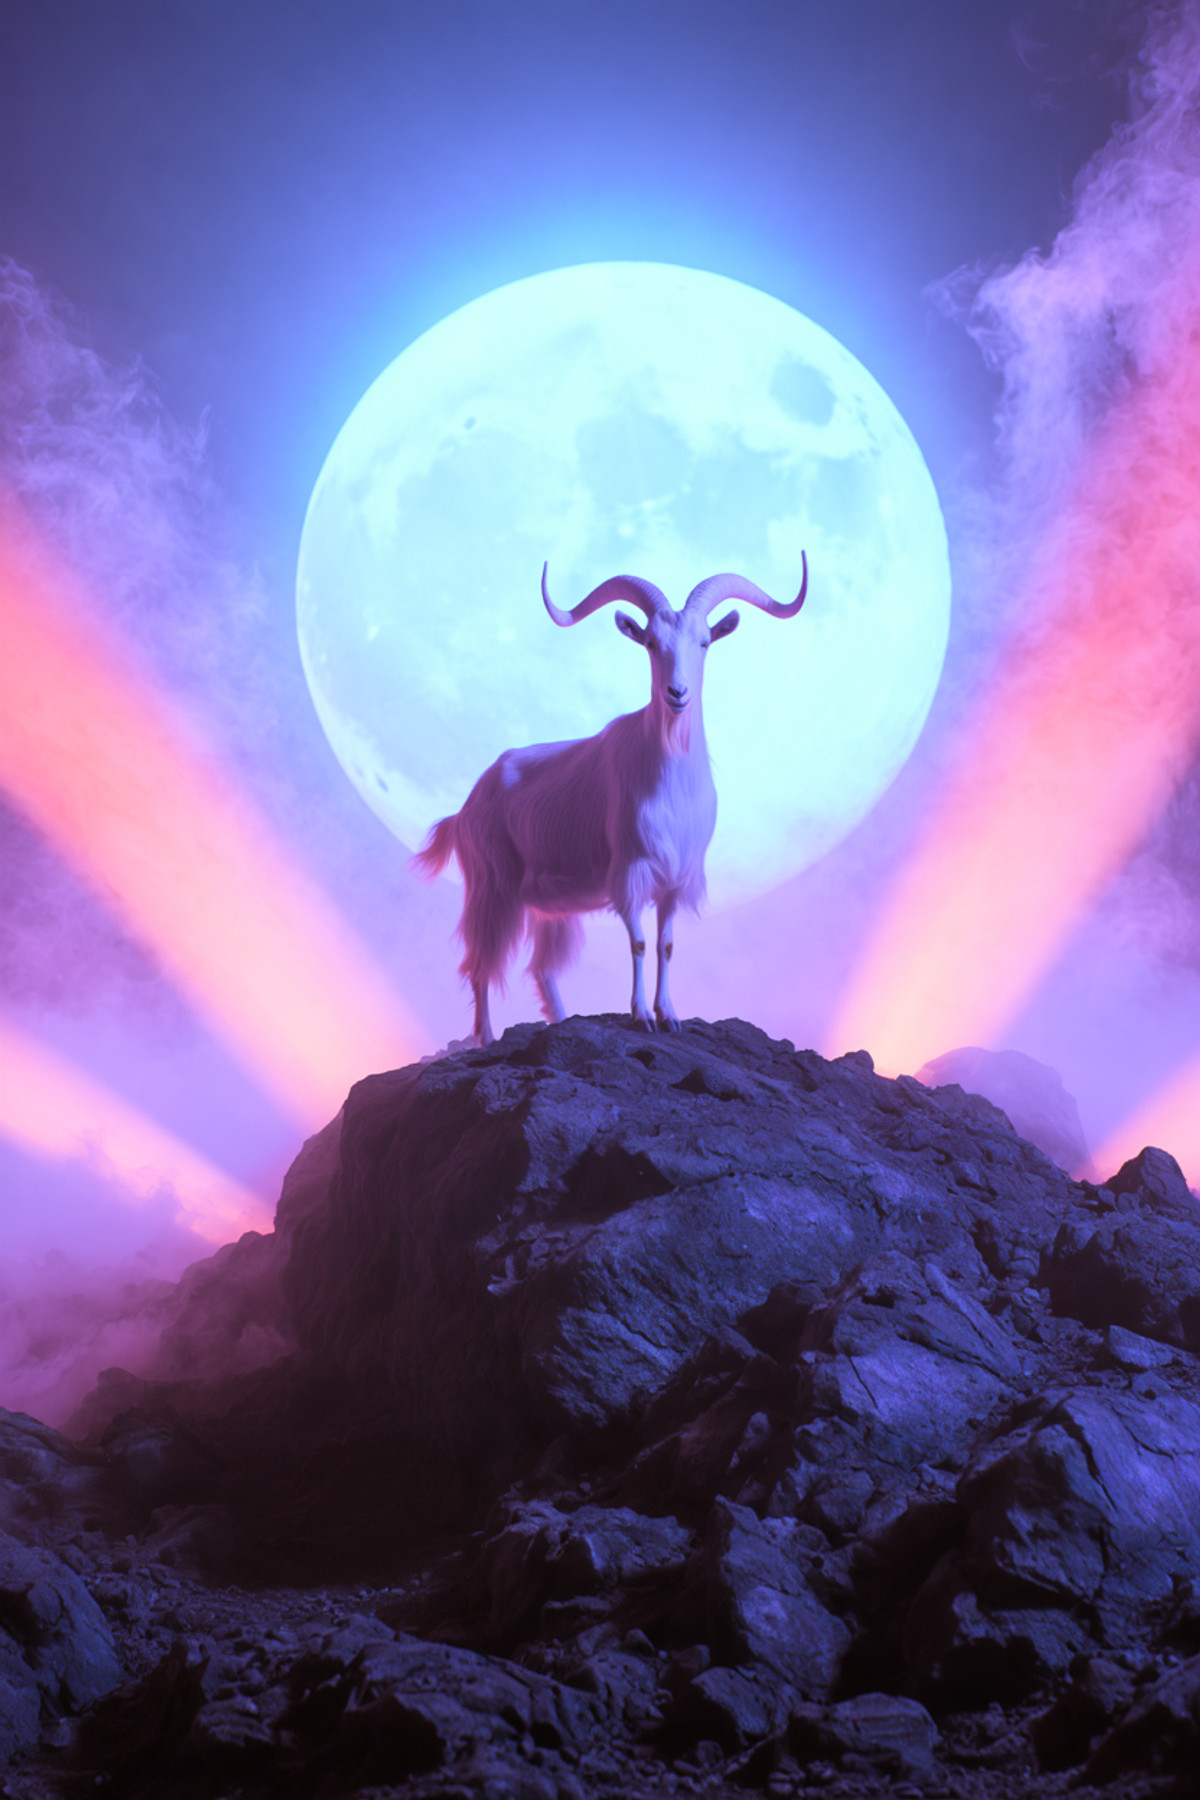
Reasons for Recommendation
- Multiple versions, including Krea 2 and ZImageBase, were released on the same model page on the same day; this is a version trained on MOSS SFT (filename NeonGothicMossSft). The author did not specify what changed compared to other versions
- The intended use is clearly stated: atmospheric cosplay portraits, magical still lifes, glowing dreams, and gothic alleys under neon lights; trigger word: Neon Gothic
- 9 visible example images are available to preview the art style
How to Use
- Add Neon Gothic to the prompt, then describe the character or scene
- The author did not provide strength, steps, or CFG settings
Risks and Limitations
- Paid download; the author did not write update notes, nor did they explain the differences between the MOSS version and other base model versions
- 2 examples are hidden; the license does not allow derivatives
Trigger Word: Neon Gothic
[B] Sorcery & Steel · MOSS
LoRA · Ported · Author ArsMachina · Published 11-11 23:54 · Downloads 3 · Paid
The MOSS version of a LoRA combining D&D character concepts with heavy metal fantasy illustration style: featuring rough comic ink lines, exaggerated muscles, and high-contrast lighting for a poster-like effect.
Images
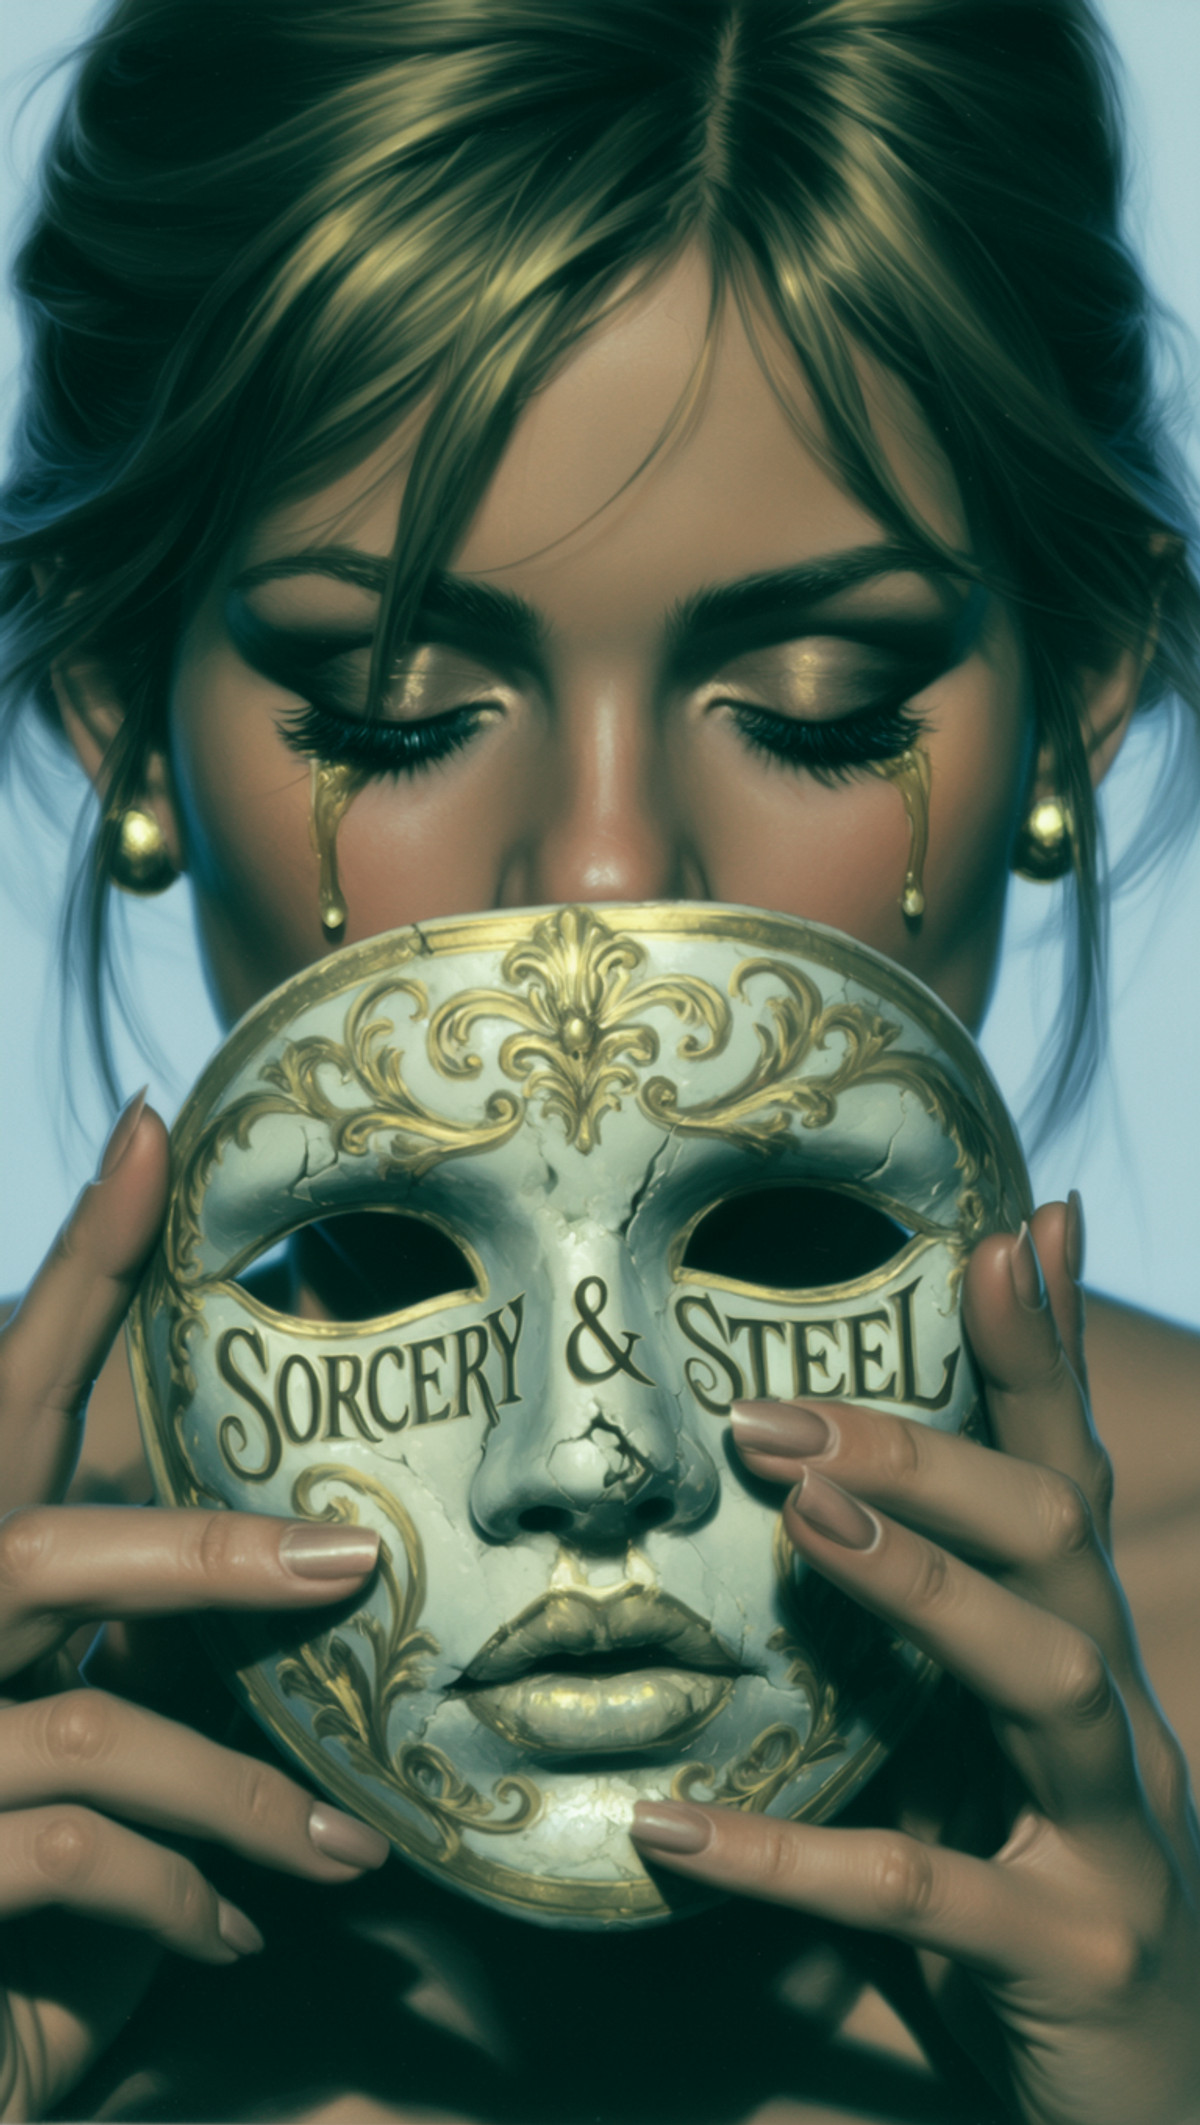
Reasons for Recommendation
- Ported version: The same page already includes versions for Krea 2, ZImageBase, Flux.2 Klein 9B, Anima, Qwen 2.1, etc.; this version is trained on MOSS SFT (filename Sorcery&SteelMossSft). The entire model page has accumulated 1140 downloads
- The art style direction is specifically described: armored warriors, dark sorcery, abyssal monsters, retro sci-fi heroes, with asymmetric, off-center poster-style compositions. The author cites inspiration from Simon Bisley and Richard Corben
- The dataset was additionally tagged with Digital / Airbrushed; using either term in the prompt biases the output toward that sub-style (digital coloring or airbrush texture). The author recommends an aspect ratio of approximately 1:2
How to Use
- Add the trigger word Sorcery & Steel to the prompt, and optionally add Digital or Airbrushed to select the sub-style; use a tall vertical aspect ratio of approximately 1:2
- The author did not provide strength, steps, or CFG settings
Risks and Limitations
- The license does not allow derivatives
Trigger Word: Sorcery & Steel
Included Only (8)
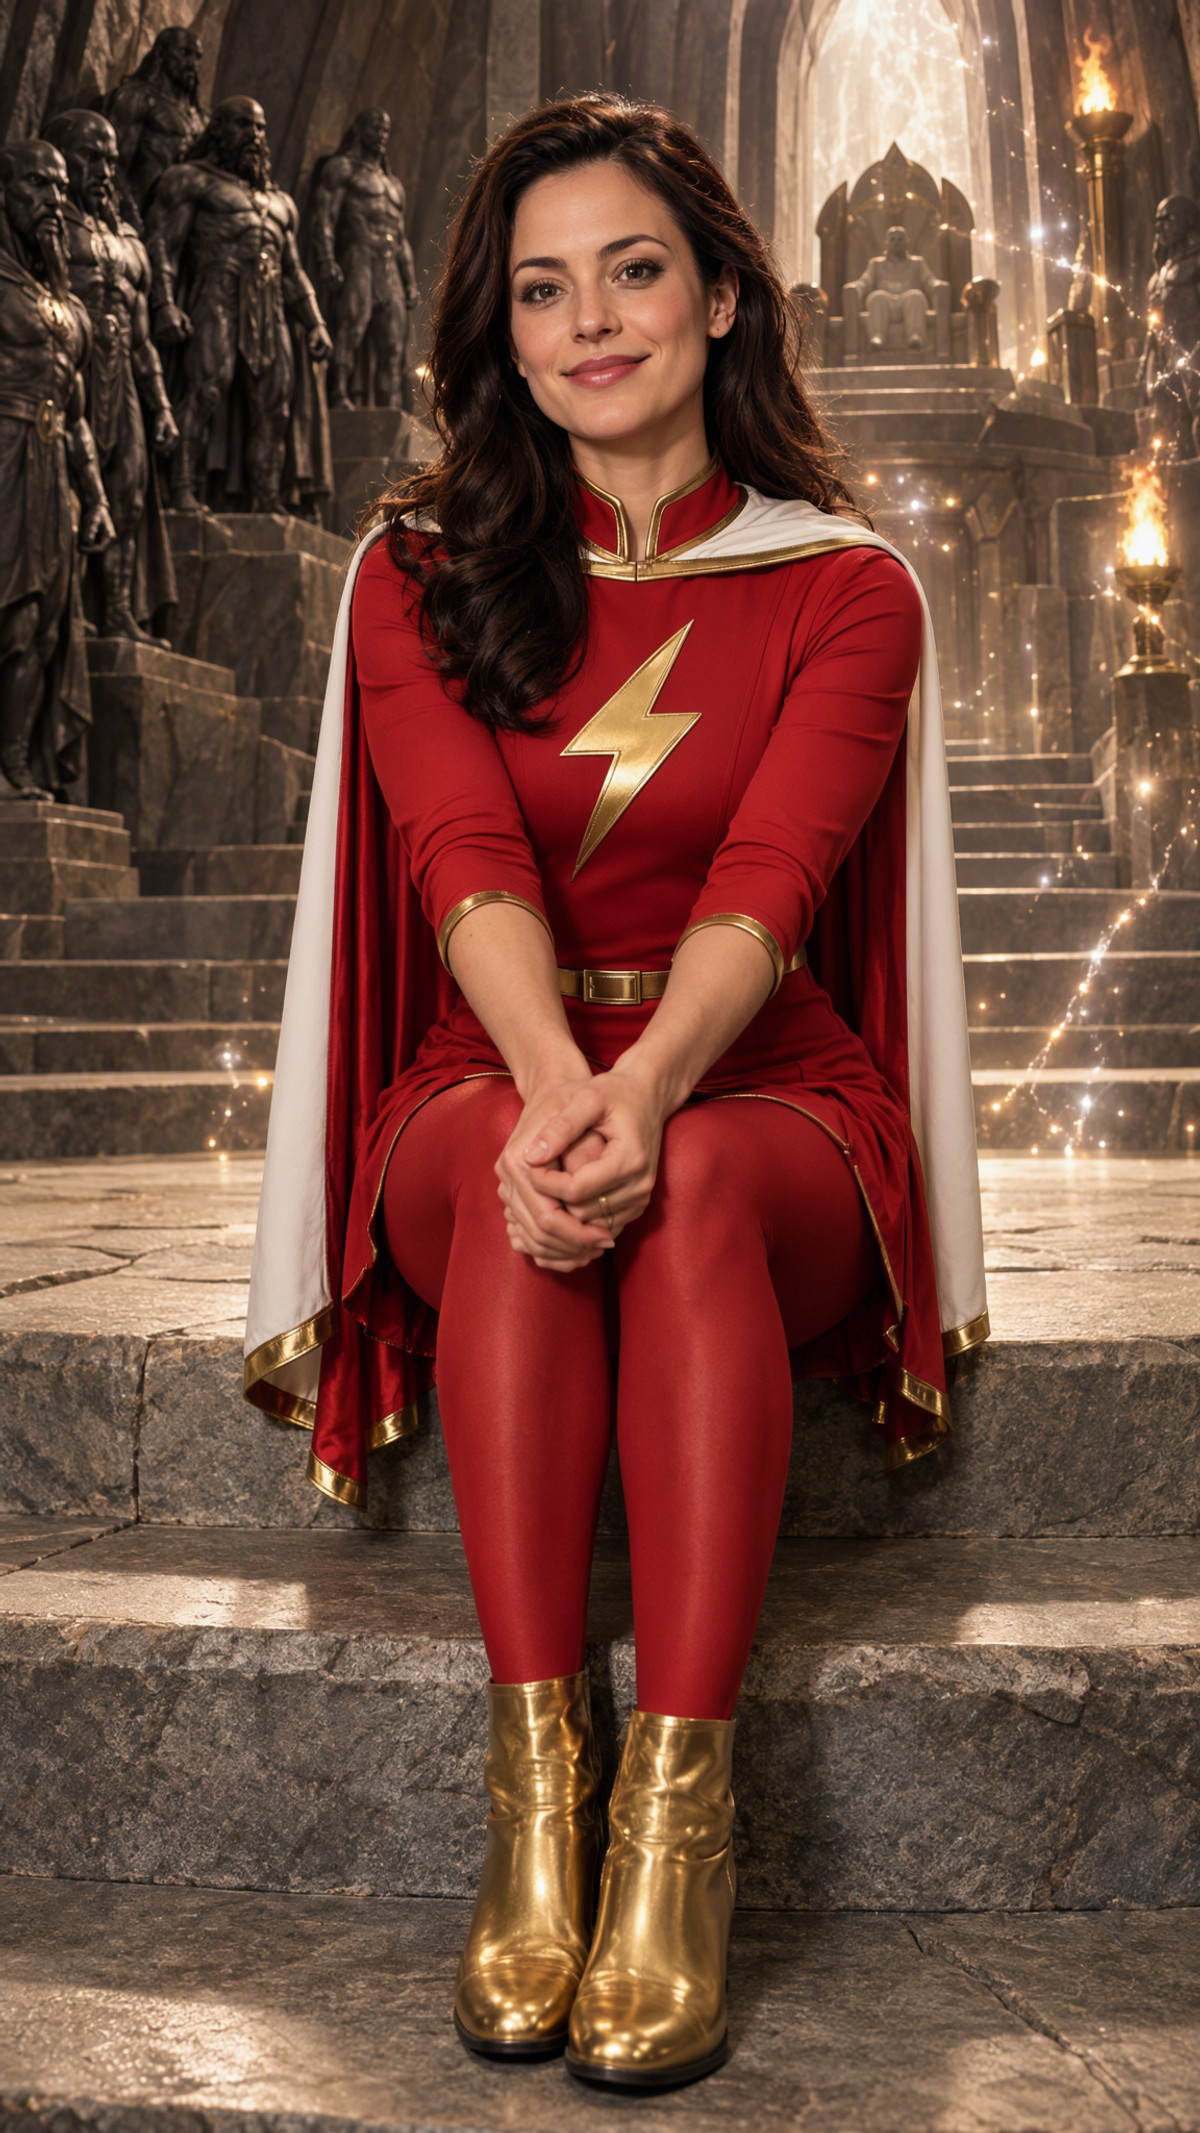
- Mary Marvel (DC Comics | Justice League) · MOSS Image — LoRA: The MOSS version of a character LoRA for Mary Marvel (a member of the Shazam family) from DC Comics.
- Ninjartist - Semi-Realistic Style MOSS LORA · v1.0 — LoRA: Konan's Ninjartist semi-realistic digital illustration style LoRA, where prompts begin with a fixed opening phrase.
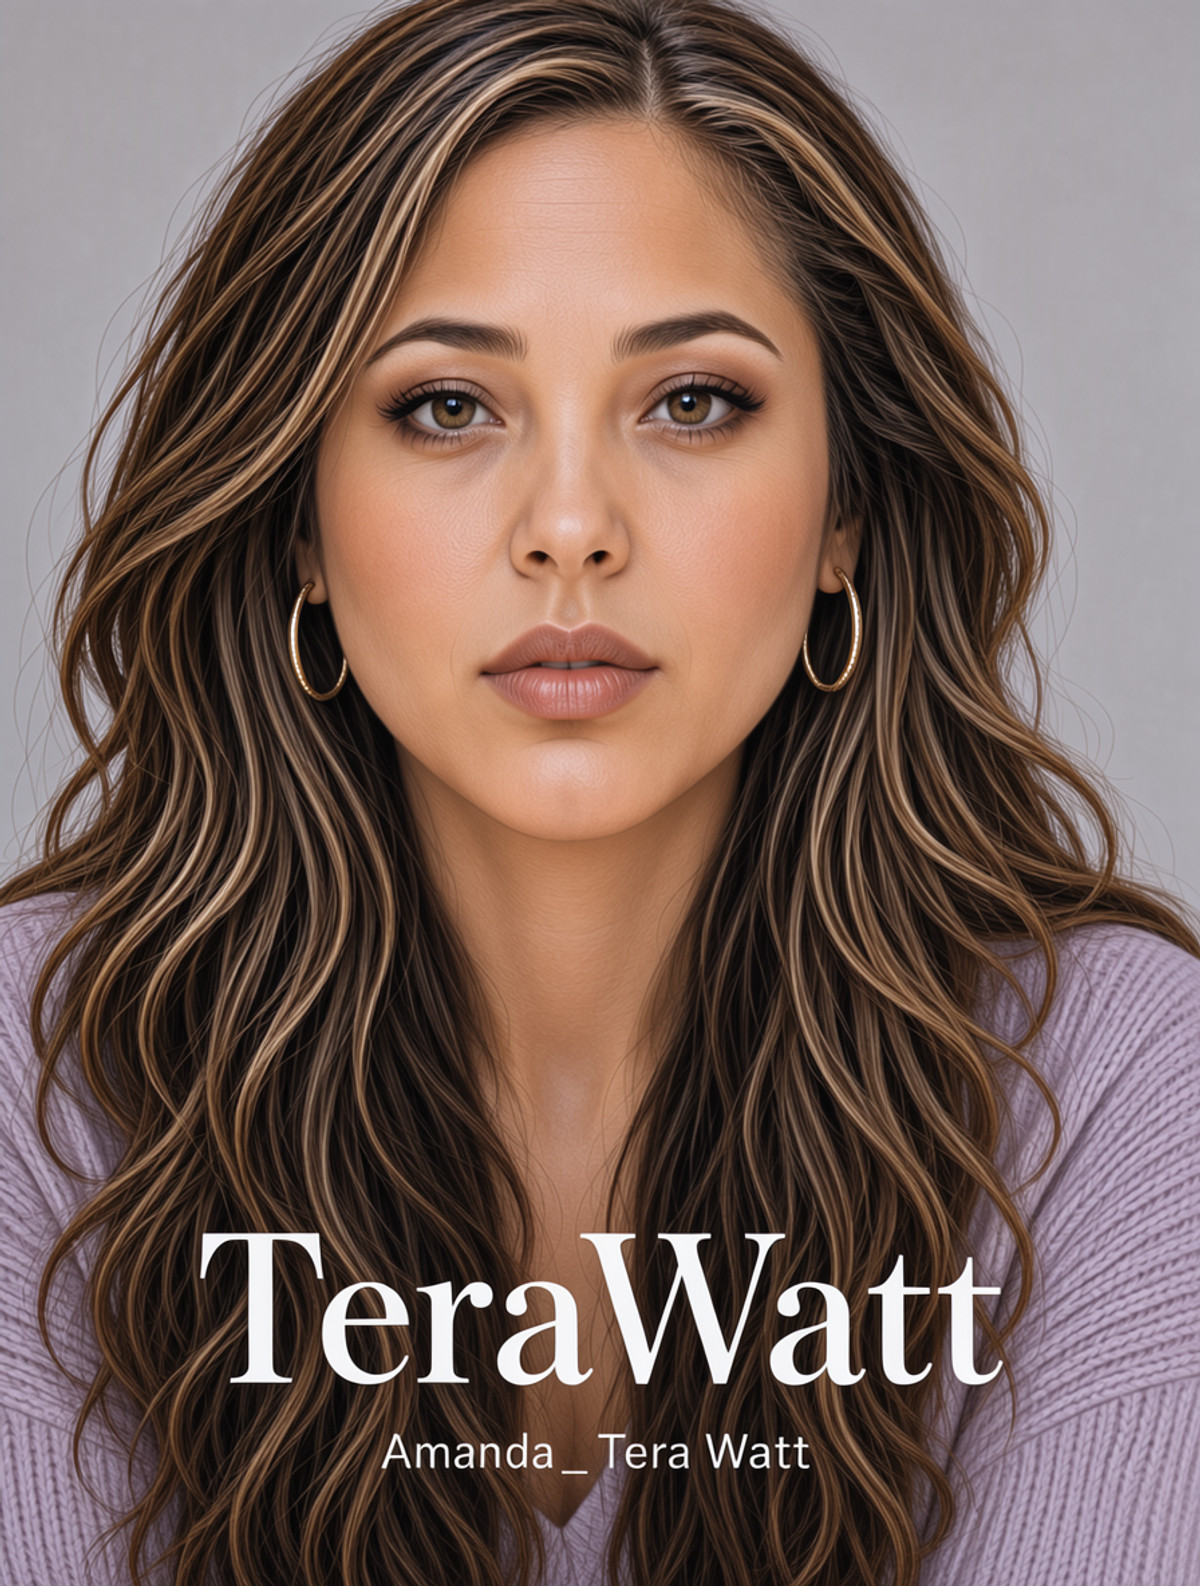
- Amanda (Test model) · MOSS v1.0 — LoRA: A character LoRA for the fictional female character Amanda (long dark brown curly hair, brown eyes), which the author describes as a test training version.
- xCarri · MOSS Image — LoRA: The MOSS version of a character LoRA for the fictional female character xCarri, trained on AI-generated data.
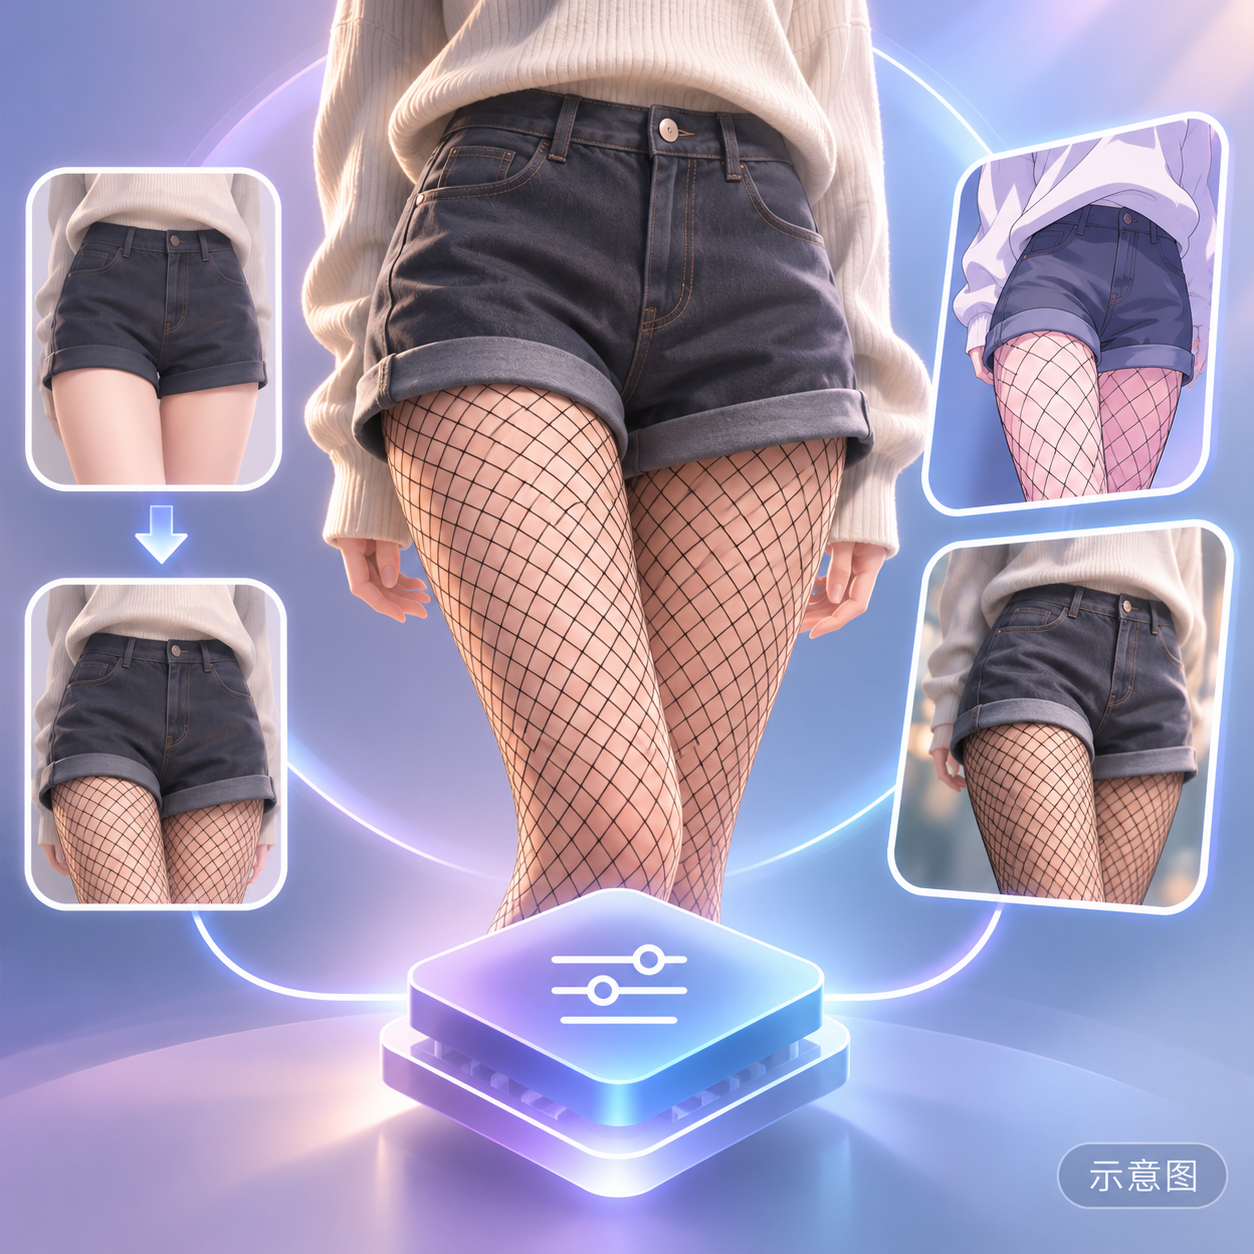
- Shorts & Fishnets (MOSS) [Anime & Realism] · v1.0 — LoRA: A clothing concept LoRA for "fishnet stockings under shorts," usable in both realistic and anime art styles.
- Videl - Dragon Ball Z · Moss — LoRA: A character LoRA for Videl from Dragon Ball Z, capable of generating two hairstyles: long hair with low twin tails and short spiky hair.
- RAWsome · Moss-RAWsome — LoRA: The MOSS version of a LoKr trained on RAW photos for a photographic realism style, aiming for a texture closer to original camera shots.
- Jason Duval GTA 6 · moss — LoRA: The MOSS version of a realistic character LoRA for Jason Duval, the protagonist of GTA 6, with the trigger word gta6jason.
Data: Civitai Public API (base model MOSS Image), inclusion window 11-11 21:03 → 11-12 09:33 (Beijing Time). Recommendation reasons have been reviewed by editors; download counts only reflect attention.