Zhenzhen's AI Radar · MOSS Image · 2026-11-17 Evening Report
This issue features 31 new versions: Strongly Recommended 1 · Recommended 8 · Worth Watching 7 · Included Only 15
Editor's Note This issue reviews 31 new MOSS versions, with 1 S-tier, 8 A-tier, 7 B-tier, and 15 C-tier entries, and no exclusions. The top pick is the Konya Karasue style LoRA: cool cyan-blue tones, backlit rim lighting, semi-thick impasto brushstrokes, and atmospheric illustrations featuring small figures with ample negative space. Trigger words, strength, CFG, sampling, mandatory negative prompts, and known issues are all fully documented, but the author's text restricts usage to non-commercial purposes, which conflicts with the license field. The single-image character reference editing LoRA CharRef V2, the 90-era Chinese calendar layout, TTRPG character token ring frames, Gustave Doré woodcut style, and the 1111 Asian portrait base model R4 are listed as A-tier. The Ishida Sui style LoRA, which the author admits has weak effects, and the prop LoRA with a hat on top 0/8 are downgraded to B-tier. Standard copyrighted characters, fictional characters, and style LoRAs with only one or two sentences of description are listed as C-tier.
Strongly Recommended (1)
[S] Style: Konya Karasue · v1.0
LoRA · Version Update · Author nomarks0 · Published 11-17 13:10 · Downloads 56
A MOSS style LoRA based on the artist Konya's style: cool cyan-blue tones, backlighting and rim lighting, semi-thick impasto brushstrokes, floating particles, and depth-of-field bokeh, featuring atmospheric illustrations with small figures and ample negative space.
It is suitable to run one image for each of the three starter prompts provided by the author to observe the effects of backlighting and negative prompts for overexposure.
Images
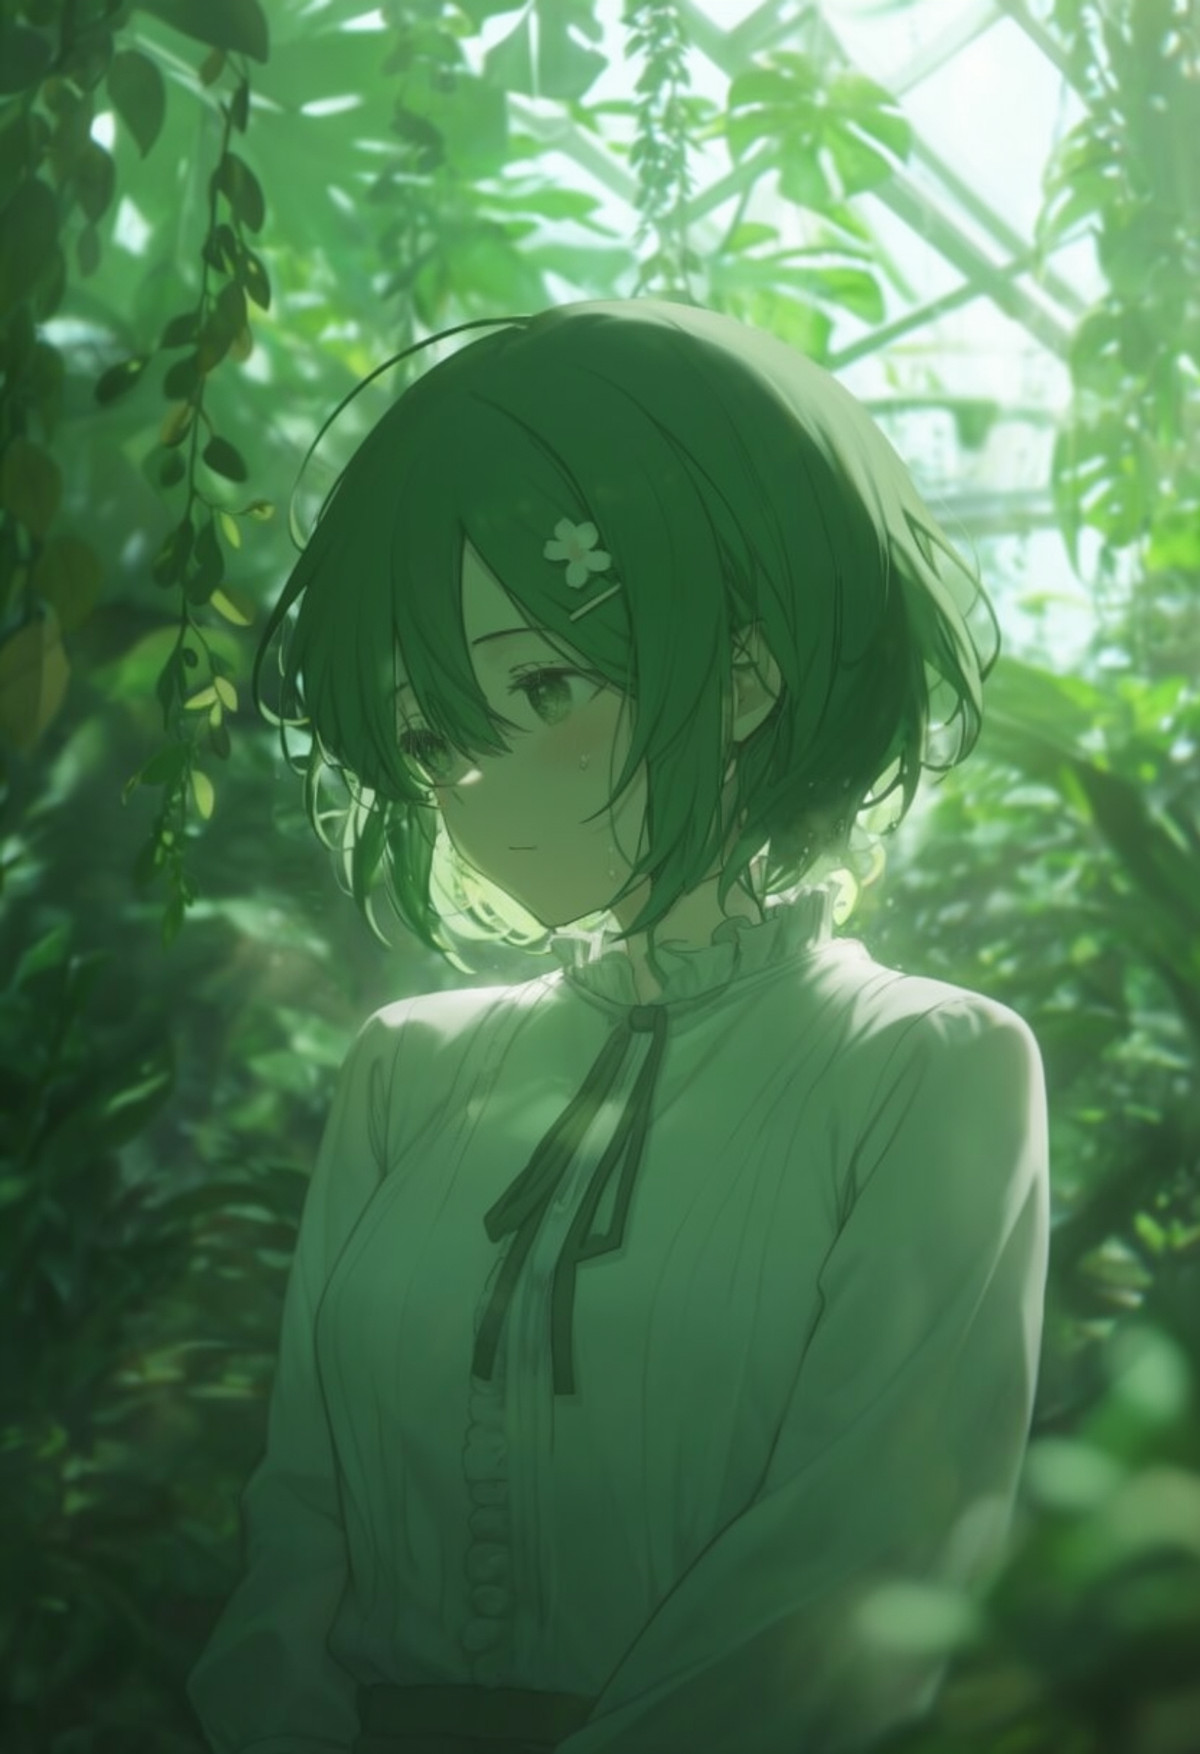
Reasons for Recommendation
- Version update: An earlier version exists on the same page; the update notes for this version only specify training conditions—50 curated images trained for 12 epochs on the heal model, but the author did not write what visual changes were made compared to the previous version
- Serves atmospheric illustrations, single-panel narratives, covers and posters, and character images with strong lighting design; the author provided starter prompts for three subjects: close-up frontal faces, backlit silhouettes, and small figures in large scenes
- Parameters and limitations are the most comprehensively documented: trigger words, strength, CFG, sampler, steps, resolution, optional Skip Layer Guidance, and mandatory negative prompts are all included; known issues such as overexposed frontal faces, asymmetric eyes on distant small faces, and short-haired dark jackets tending to appear male are also listed; 8 visible examples; free
How to Use
- Prompts should start with konya, followed by a mix of tags and a natural language sentence; the author states that the text encoder of this base model understands long sentences well, making sentences more effective than stacking tags
- Strength 1.0 (0.8 is nearly equivalent with slightly less style fixation, style starts to drop at 0.6); start with CFG 2.5-3.0, increase to 5.0 when fully opening up the face; er_sde + simple, 30 steps (euler + simple is also acceptable); 832×1216 / 1216×832, square images 1024×1024
- Negative prompts must include overexposed, blown highlights, washed out, otherwise close-up frontal faces with frontal lighting are prone to overexposure and washing out; optional Skip Layer Guidance: single_layers 22, start 0 / end 0.5
- For compositions with short hair and dark jackets, specify 1girl, long hair to constrain gender
Risks and Limitations
- The trigger word konya is only written in the description and not registered in the trigger word field
- Imitates the style of a living artist; the author explicitly states in the English section of the model card that it is for learning and non-commercial experimentation only, prohibiting the sale of generated images and redistribution of weights, with removal upon artist request—this conflicts with the selling permissions checked in the Civitai license field, so the author's text takes precedence for commercial use
- The author states that training was led by deepseek-flash; the author did not explain which base model the heal model is; the author states that changing the base model requires readjusting strength and CFG; 1 sensitive-level examples have been hidden
Recommended (8)
[A] 1111 - MOSS Image Asian Utopian · R4
Checkpoint · Version Update · Author hinablue · Published 11-17 10:55 · Downloads 342
The R4 version of 1111 Asian Utopian: A full MOSS Image base model biased towards Asian female portraits with Japanese, Taiwanese, Korean, and Thai faces; this version was retrained with a new dataset and registers trigger words by nationality.
Images
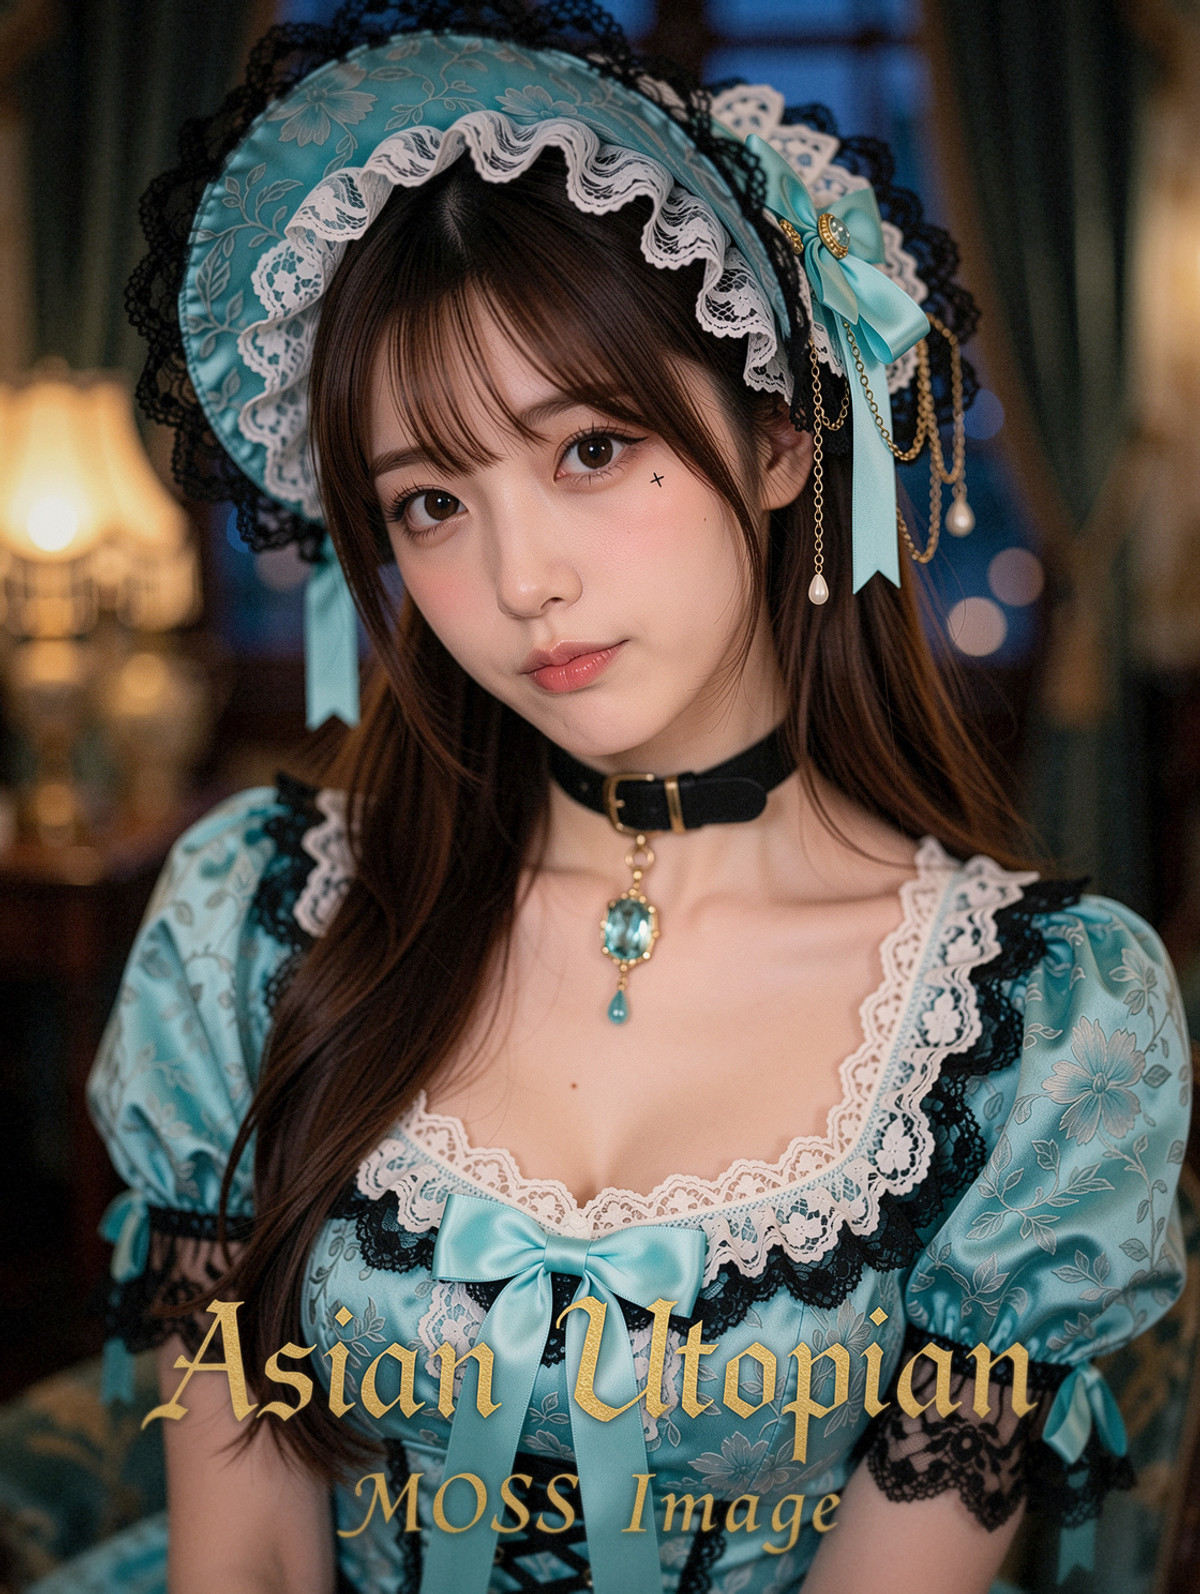
Reasons for Recommendation
- Version update: The author states that R4 was retrained with a completely new dataset of 7,660 entries (Japanese, Taiwanese, Korean, Thai faces); the previous UBW version used 8,000 entries to train a full fine-tuning LoRA on the Base model, then fused layer weights back into the base model. The trigger words for R4 expanded from just asian woman to five: Taiwanese / Japanese / Korean / Thai woman, allowing specification of faces by nationality
- Serves Asian female portraits and photorealistic text-to-image generation; the author explicitly states that no acceleration LoRA is fused, preserving the adjustability of full step counts, and suggests attaching a 8-step or 4-step acceleration LoRA if speed is desired
- Provides both bf16 and int8-convrot files; the int8 version can be used if VRAM is insufficient; approximately 10 hours after release, it has 342 downloads, making it the most watched entry in this group (download count only indicates attention level)
How to Use
- Load as a base model (choose either bf16 or int8-convrot); write asian woman in the prompt, or use Taiwanese woman, Japanese woman, Korean Woman, Thai Woman to specify nationality
- Resolution 1.2-1.6 megapixels; to increase speed, attach lodestones' MOSS-Image-Base-8-steps-dmd or MOSS-Image-SFT-8-steps-dmd acceleration LoRA
- The author did not provide step counts, CFG, or samplers for when no acceleration LoRA is attached
Risks and Limitations
- The author did not write update notes, the version description is empty, and changes for R4 are only written in the first paragraph of the model card; the end of the model card separately lists 7,780 entries of data, batch size 2, 4 epochs, and fusion weights 0.7, which do not match the 7,660 entries described for R4, and it is unclear whether the layer fusion parameters belong to R4 or UBW
- The page contains mixed content, and 9 sensitive-level examples have been hidden; the bf16 file is approximately 9.5 GB, and int8 is approximately 5 GB
- The author wrote Apache-2.0 derivative in the model card, but the Civitai license field does not allow derivatives and only checks image output and on-site rental, so the page license takes precedence
Trigger Words: asian woman, Taiwanese woman, Japanese woman, Korean Woman, Thai Woman
[A] Gustave Doré illustration style - artist style - wood engraving · moss_v1.0
LoRA · Ported · Author RisingV · Published 11-17 14:09 · Downloads 45
The MOSS version of the Gustave Doré woodcut illustration style: black and white, dense hatching 19th-century literary illustration style, excelling at large scene long shots and full-body portraits of characters, monsters, and mythological creatures.
Images
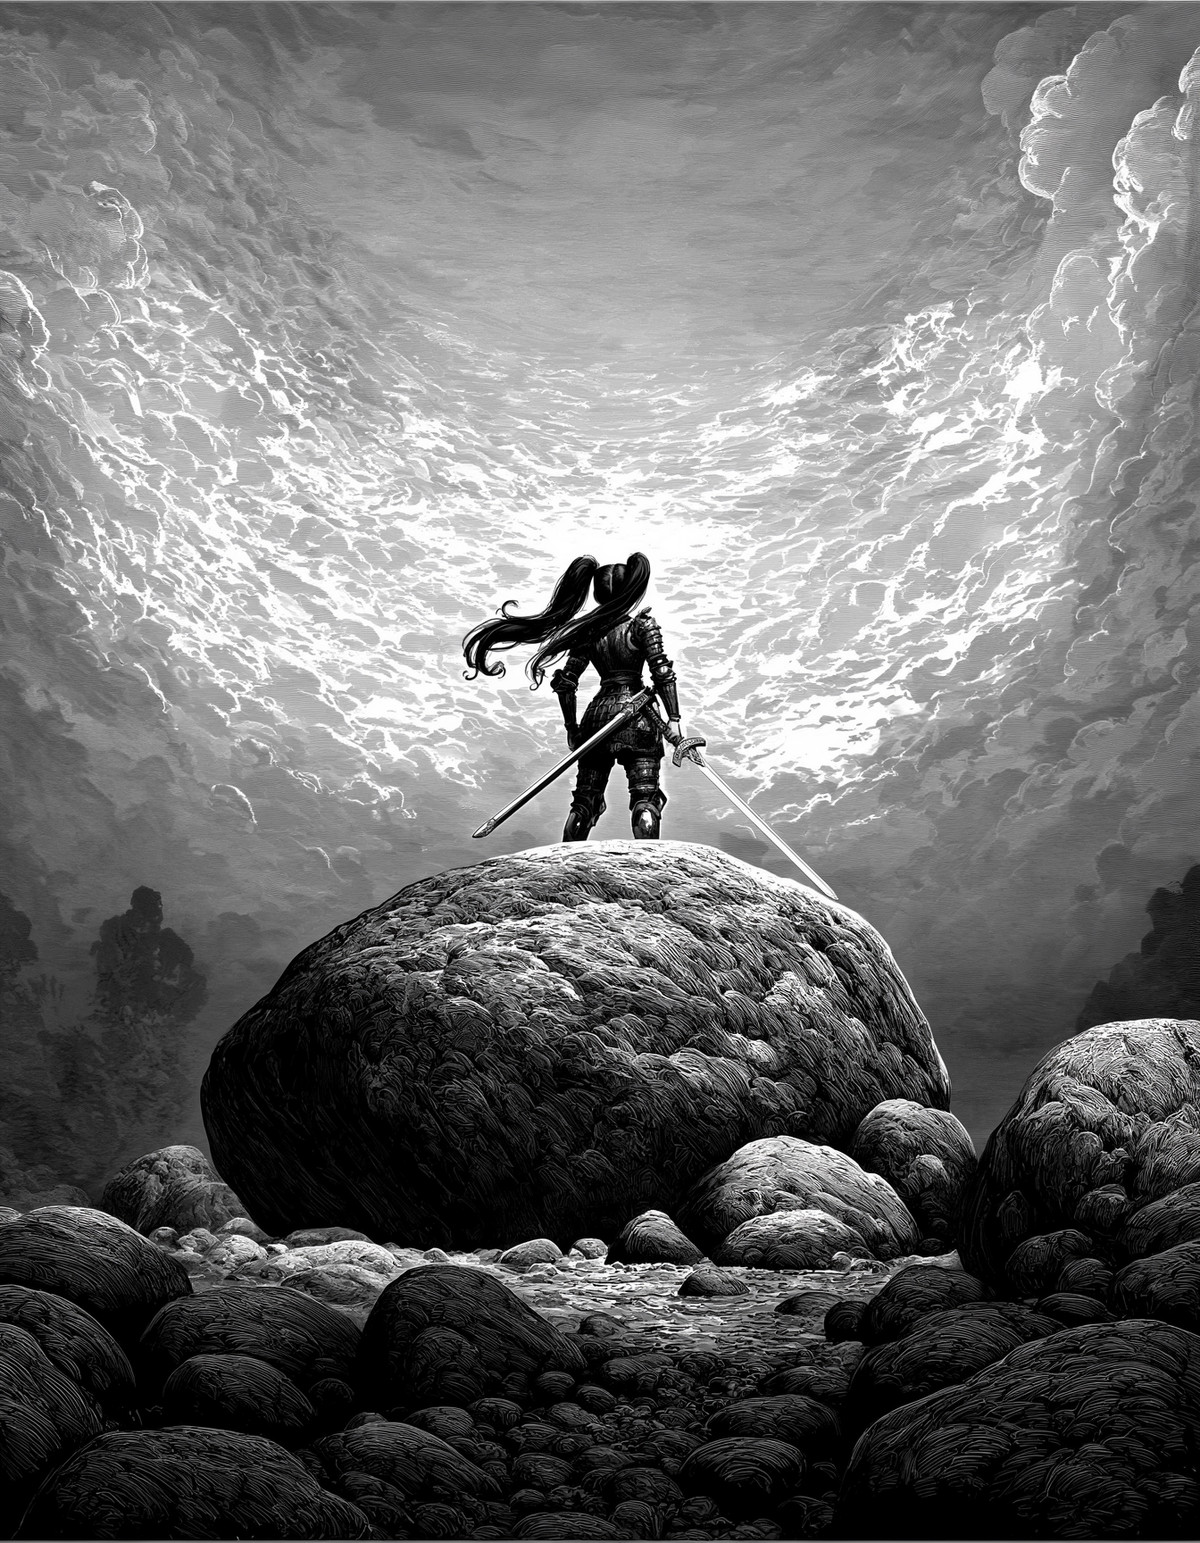
Reasons for Recommendation
- Ported: Krea 2, Anima, and Illustrious versions exist on the same page with consistent trigger words; the author specifies the differences—the MOSS version was trained at low resolution, and the author claims the style comes out better on Kromoss
- Serves fantasy illustrations, book illustrations, and woodcut-style scenes; training images are public domain Doré illustrations, with no copyright issues regarding living artists
- 12 visible examples, none hidden; trigger words and supplementary tags are provided; free
How to Use
- No trigger word was used during training, but the author states that writing monochrome, greyscale in the prompt yields the most obvious style; graphite (medium), traditional media, extremely detailed linework, and linear hatching can be added
- Prioritize using Kromoss as the base model; the author did not provide strength, steps, or CFG
Risks and Limitations
- Trained at low resolution, detail performance at high resolutions is unknown; no parameters are provided
- The license only checks on-site rental and does not allow commercial use of generated images (selling outputs), and the author did not specify whether Base or SFT was used for training
Trigger Words: monochrome, greyscale, extremely detailed linework
[A] TTRPG Token Rings for Moss · v1.0
LoRA · New Model · Author Razira · Published 11-17 13:53 · Downloads 34
A character avatar ring frame LoRA for tabletop RPGs: generates circular token borders (white background, decorated in specified styles), which can be cut out and used as outer frames for TTRPG character tokens.
Images
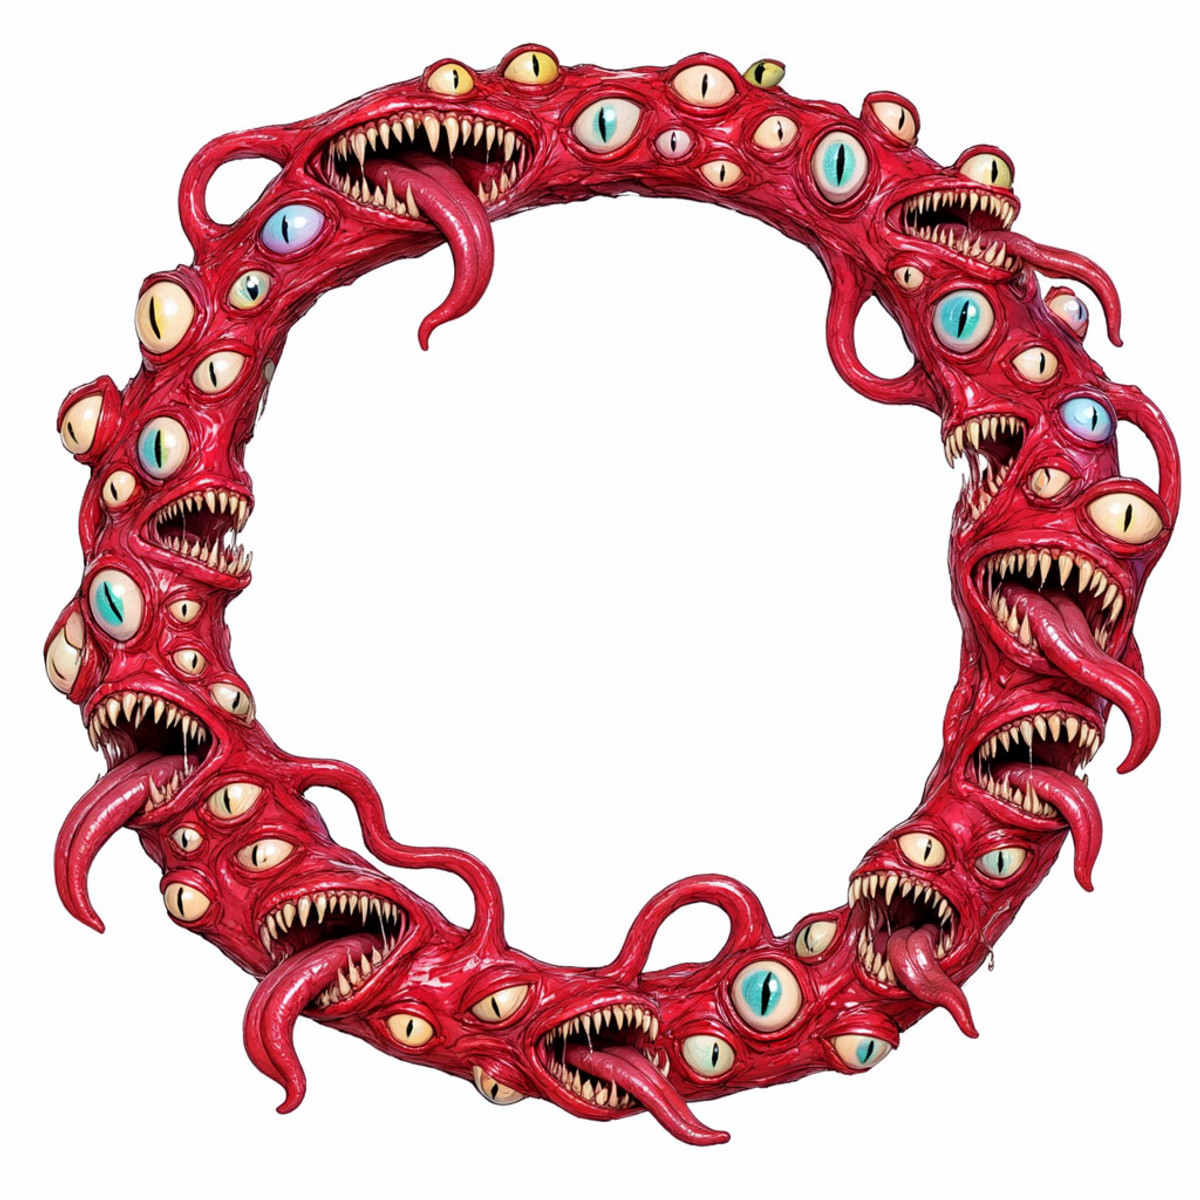
Reasons for Recommendation
- New model; a rare practical asset LoRA, creating decorative frames for character tokens on virtual tabletops for D&D and other tabletop RPGs, which can be placed around your own character avatars with slight editing after generation
- The trigger sentence and tuning are clearly written: 'thin' in the trigger sentence controls the thickness of the ring, removing 'thin' allows for more decoration; adding illustration concept art style prompts leans towards illustration, while omitting them results in a more realistic look, selectable based on game art style
- 9 visible examples; free
How to Use
- Prompts should start with A thin token ring styled like, followed by the ring's style (material, theme), then add white background, Illustrated concept art style,
- For effects like characters popping out of the frame, use A token ring styled like, instead; after generation, cut out the center and white background before pasting the character image
- The author did not provide strength, steps, or CFG
Risks and Limitations
- The page contains mixed content, and 11 sensitive-level examples have been hidden, exceeding the number of visible examples
- Manual cropping and center alignment are still required after image generation; it is not a directly usable transparent PNG; the license only allows on-site rental, does not allow derivatives, and requires attribution
Trigger Words: A thin token ring styled like,, white background,, Illustrated concept art style,
[A] MOSS-Image Edit CharRef (beta) · v0.1 | Recipe V2
LoRA · Version Update · Author bag3l · Published 11-17 14:38 · Downloads 68
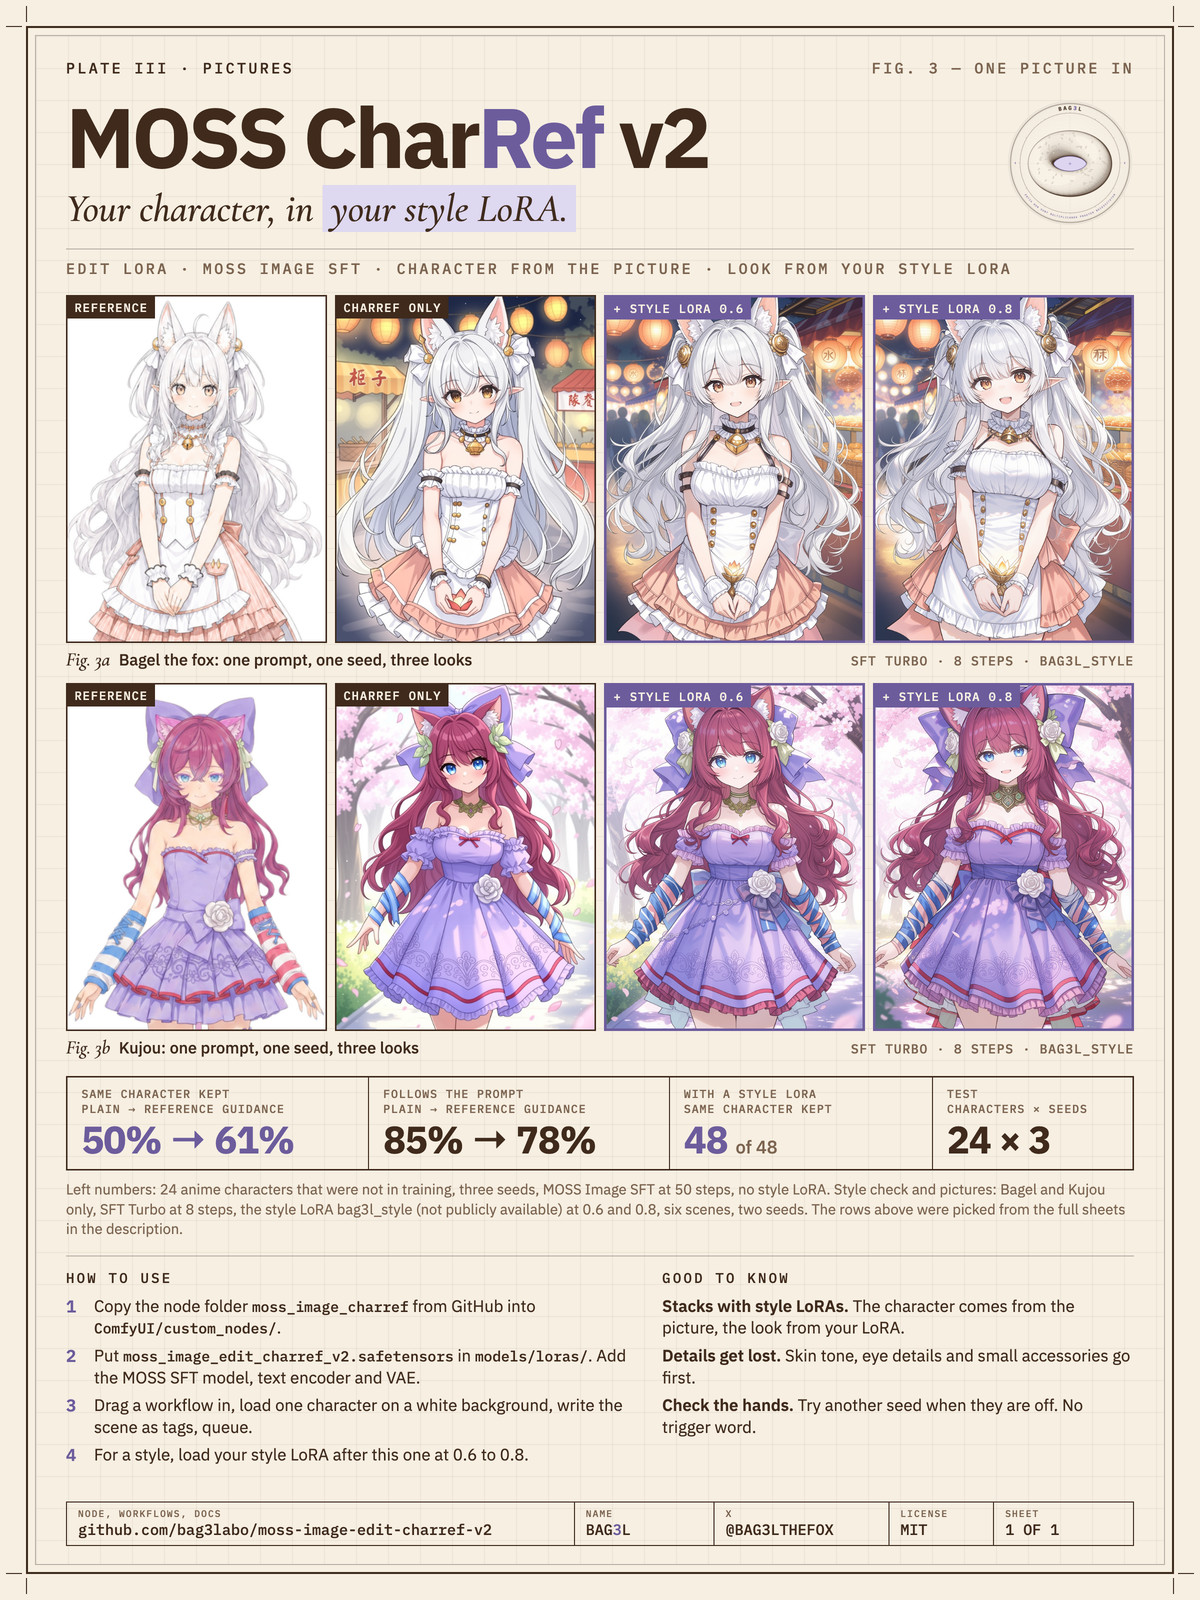
Recipe V2 for MOSS-Image Edit CharRef: An editing LoRA that takes a single anime character image and a scene prompt to draw the same character in a new scene and pose; hairstyle, face, clothing, and accessories are taken from the reference image, while pose, composition, and background are taken from the prompt.
Top pick for this group: A rare "single-image character reference" editing LoRA on MOSS, where the author has laid out failure cases and limitations, making it suitable for first running your own original character design sheets through standard workflows and reference-guided workflows for comparison.
Images
Reasons for Recommendation
- Version update: The same page previously featured a PoC (Recipe V1, based on MOSS Base, relying on ostris's editing nodes, with prompts requiring appearance tags); this version trains on MOSS SFT, replacing the node with the author's own moss_image_charref small node, eliminating the need for trigger phrases, with prompts specifying only scene, pose, and composition, while appearance is entirely handled by the reference image; the update note highlights a new selling point in one sentence: this LoRA carries only the character and has no strong style of its own, allowing it to be stacked with style LoRAs
- Serves character consistency tasks for "generating multiple scene images from a single character sheet": fan art, standing illustration extensions, character sticker packs, and storyboard sketches, without needing to train a separate LoRA for each character
- The author provides detailed instructions: three ready-made workflows are provided (the reference-guided version with the highest fidelity, a faster standard version, and an SFT Turbo 8-step version with a style LoRA slot), guidance on selecting reference images, and the position and strength for stacking style LoRAs; two comparison tables state "every render is released, none deleted," with 48 auto-checks for the same character passing after stacking styles, and 12 out of 11 passing without stacking; the author notes this is only a preliminary check for two characters; free, with a permissive license
How to Use
- Place the moss_image_charref node folder into ComfyUI/custom_nodes/ and restart (no additional dependencies required; requires a newer version of ComfyUI that includes the Text Encode MOSS-Image Edit node); place the LoRA in models/loras/ and name it moss_image_edit_charref_v2.safetensors; use the MOSS SFT model from Comfy-Org (not the Base model)
- Use reference images with a white background, a single person, and a neutral pose with arms hanging naturally; full-body images preserve the entire outfit and shoes, while crops from the head to the thighs better preserve the face, eye color, and ears; flat, clean illustrations yield the best results
- Write prompts using comma-separated tags for scene, pose, composition, and expression, starting with 1girl, solo or 1boy, solo; do not describe character appearance and do not use trigger words; set LoRA strength to 1.0; steps, CFG, sampler, and skip-layer guidance for SFT are already configured in the first two workflows, while SFT Turbo runs for 8 steps
- Stacking style LoRAs: load immediately after this LoRA and before the Reference layout node, with a strength of 0.6-0.8; place style trigger words at the beginning of the prompt; 0.8 styles are heavier but result in more character drift
Risks and Limitations
- The author marks this as an early version: the full model card states that on 24 anime characters outside the training set, same-character checks pass at approximately 50% with standard sampling, and approximately 61% with reference guidance enabled (2.5); skin tone, pupil details, and small accessories are the first to be lost, with significant variation between seeds, and extra props (such as handbags or forehead gems) may appear
- The author's custom node must be installed, otherwise it "does not work as tested"; the security scan for the zip package containing the node and workflows is not yet complete, so it can be obtained from the author's GitHub instead
- Supports only anime characters, single character with single reference image, and does not support real-person photos; raising hands in the reference image results in four hands, and heavily painted or effect-heavy reference images introduce brushstrokes and color casts into the output
- Untested: MOSS Base, sizes above approximately 0.6 MP (the full model card cites 672 x 896 as an example), multiple reference images, other strengths, and samplers; under Turbo, reference guidance must be disabled or kept below 1.5, as 2.5 will copy the reference image pose exactly
- The only style LoRA tested in the comparison table (bag3l_style) is not public, and the stacking performance of other style LoRAs is unknown; data comes from a single training run
【A】Scumble · moss heal-v1.0
LoRA · New Model · Author soda_Cookie · Released 11-17 13:31 · Downloads 32
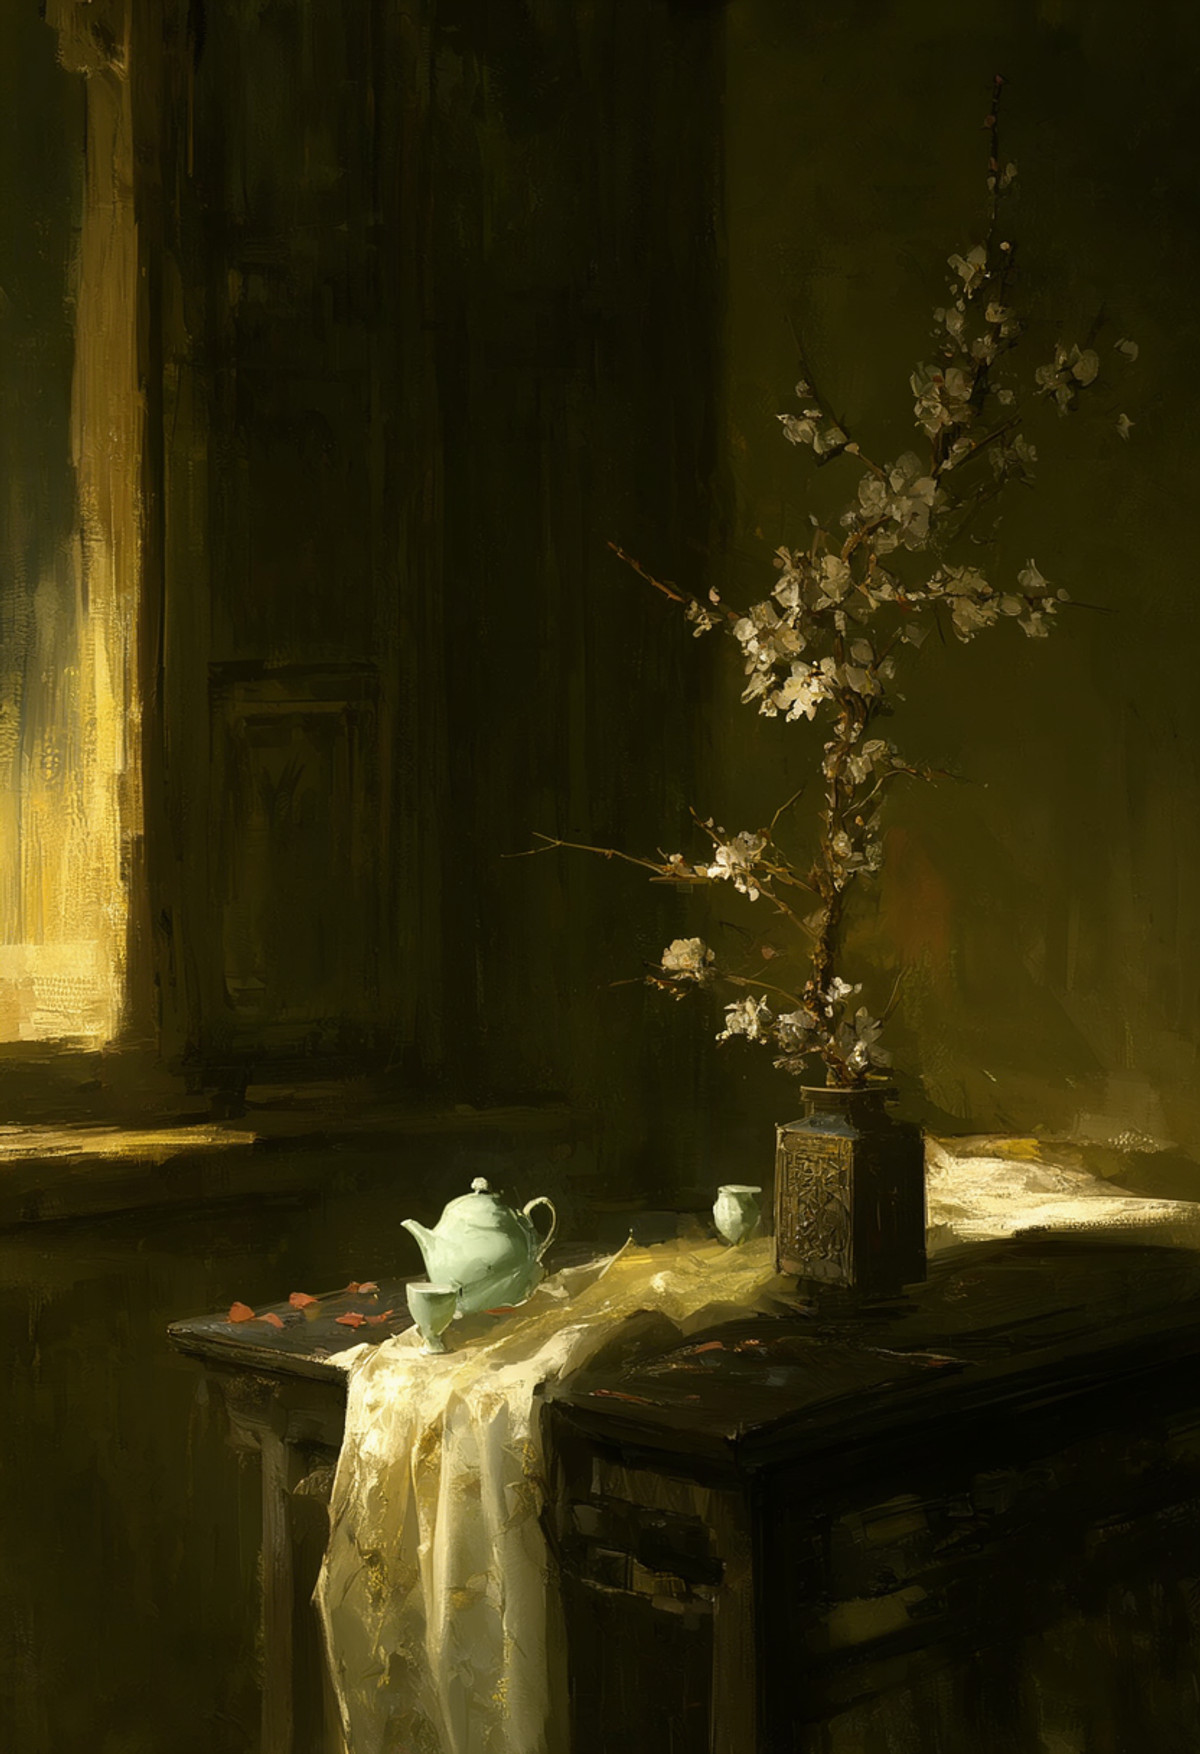
Scumble: A painterly style LoRA focused on ancient-style characters and scenes, featuring dry-brush matte strokes, fragmented color blocks, and coarser textures for clothing and backgrounds, while retaining relatively detailed character faces.
Images
Reasons to Recommend
- New model: The author states the style can be used for characters, scenes, and still life; examples show it stacked with Luo Tianyi and Claude Girl character LoRAs, functioning as a "style coat" for character LoRAs
- Serves ancient-style illustrations, Chinese-style character standing illustrations, and scene concept art
- Training information is public: 59 main images plus 59 regularization images, native GBC descriptions, rank 32, alpha 128, trained to EP15/885 steps; 7 examples have no hidden elements; free, with a license permitting commercial output and derivatives
How to Use
- Trigger word: @scumble; the author does not provide recommended strength, steps, CFG, or sampler settings
- When stacking with character LoRAs, the author warns that results will vary with style strength, prompts, and the character LoRA, requiring manual adjustment of the strength ratio between the two
Risks and Limitations
- Trained using MOSS-Image-heal; the author does not explain performance differences on MOSS Base / SFT
- No recommended parameters are provided; the version note only says "V1"; released approximately 7 hours ago, with very few downloads so far
Trigger words: @scumble
【A】Harlequin Art [MOSS / KREA / ZIT] · MOSS Image - v1.0
LoRA · Port · Author egpieper · Published 11-17 11:09 · Downloads 33
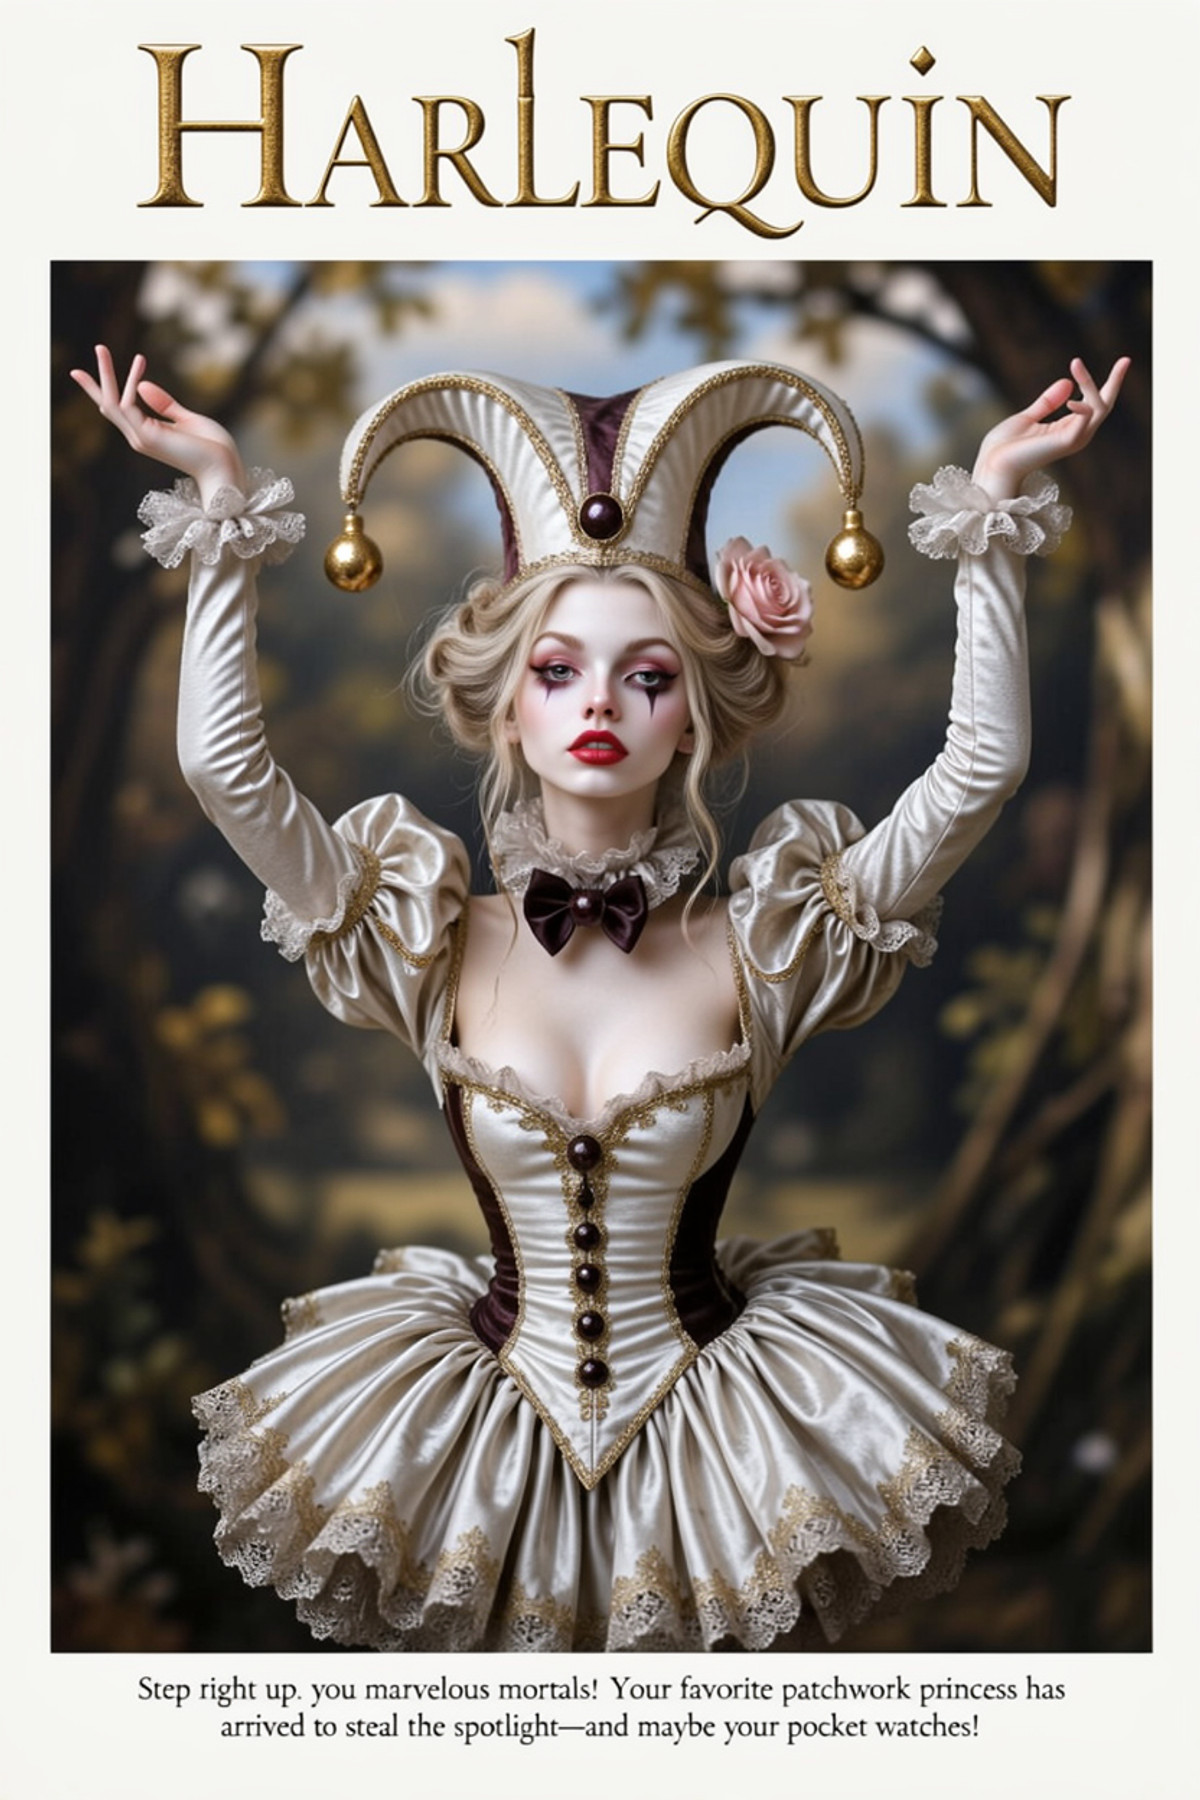
The MOSS version of Harlequin Art: a fantasy-style LoRA featuring harlequins and dolls as subjects. The same page also includes Krea 2 and Z-Image Turbo versions.
Images
Reasons for Recommendation
- Port: Moved from the Krea 2 / ZIT version to MOSS; the author notes that the difference is that the MOSS version requires a slightly higher strength, and the MOSS version does not register trigger words (other versions register harlequin_art, fantasy)
- Suitable for concept art and illustrations featuring fantasy dolls, clowns, and circus themes
- The author provides two sets of MOSS parameters: For Base / FST, use strength 1.0, 25 steps, CFG 3.5; when using the Speed-up INT8 FST model or an acceleration LoRA, use strength 2.0, 8-12 steps, CFG 2.0. The author states that the example images were generated using a locally fine-tuned ComfyUI workflow; it is free with a permissive license
How to Use
- MOSS Base / FST: strength 1.0, 25 steps, CFG 3.5; accelerated version: strength 2.0, 8-12 steps, CFG 2.0. The author only provided samplers for Krea 2 Turbo (DPM++ 2M / SGM_UNIFORM or Euler / Simple); no specific samplers were given for the MOSS version
- Prompts can refer to the author's examples, starting with harlequin_art, fantasy followed by a description of the subject, such as "a close up of a doll with a red hat"; the author did not specify whether these two words are mandatory for the MOSS version
Risks and Limitations
- Only 3 visible examples are available (2 hidden), and the description for the MOSS version consists of only one sentence: "increase strength slightly"
- The author did not specify which MOSS variant "FST" refers to; the MOSS version does not register trigger words
【A】Harlem Renaissance · Moss Image - v1.0
LoRA · Port · Author egpieper · Published 11-17 19:22 · Downloads 10
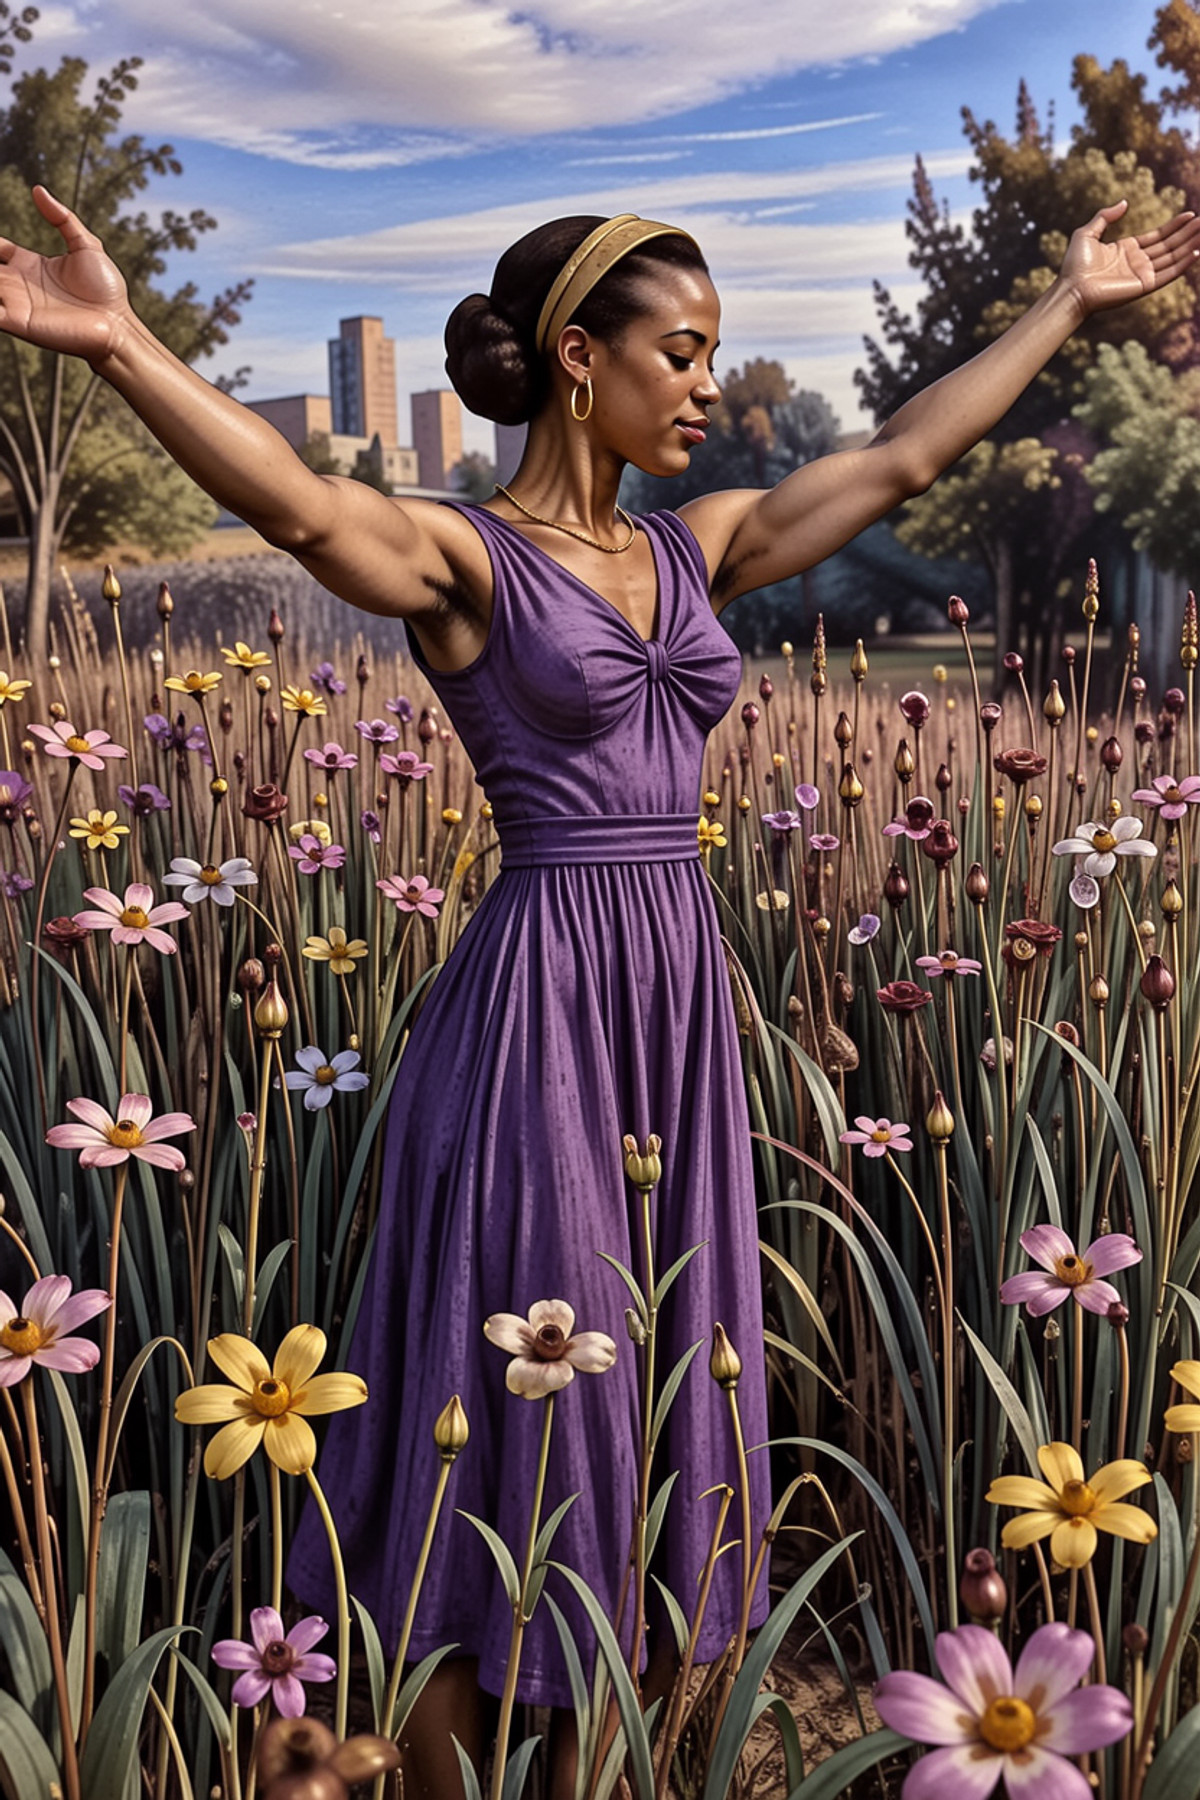
The MOSS version of Harlem Renaissance: a LoRA mimicking the style of African American art from the Harlem Renaissance period in the 1920s-1930s. The same page also includes Krea 2, Z-Image, SDXL, Illustrious, and Flux versions.
Images
Reasons for Recommendation
- Port: Five other base model versions already exist in the same art style, and the author has detailed the differences for each version (e.g., the Illustrious version leans towards manga, the Z-Image version is only suitable for short prompts, etc.); the difference for the MOSS version is that the strength needs to be increased, recommended at 2.0
- Serves illustrations with historical art styles such as retro posters, the Jazz Age, and portraits or group shots of African American figures
- 5 visible examples, no hidden ones; free, license allows commercial use and derivatives
How to Use
- Strength 2.0; CFG / guidance 2.0 under the FST specified by the author; steps and sampler not provided by the author
- The MOSS version has no registered trigger word, while other versions use harlem_renaissance, which can be placed at the beginning of the prompt
Risks and Limitations
- The MOSS version has only a single sentence of parameter description; steps, sampler, and whether a trigger word is needed are not specified; released less than 2 hours ago, with very few downloads
- The page contains mixed content; it is not specified which MOSS variant the "FST" mentioned by the author refers to
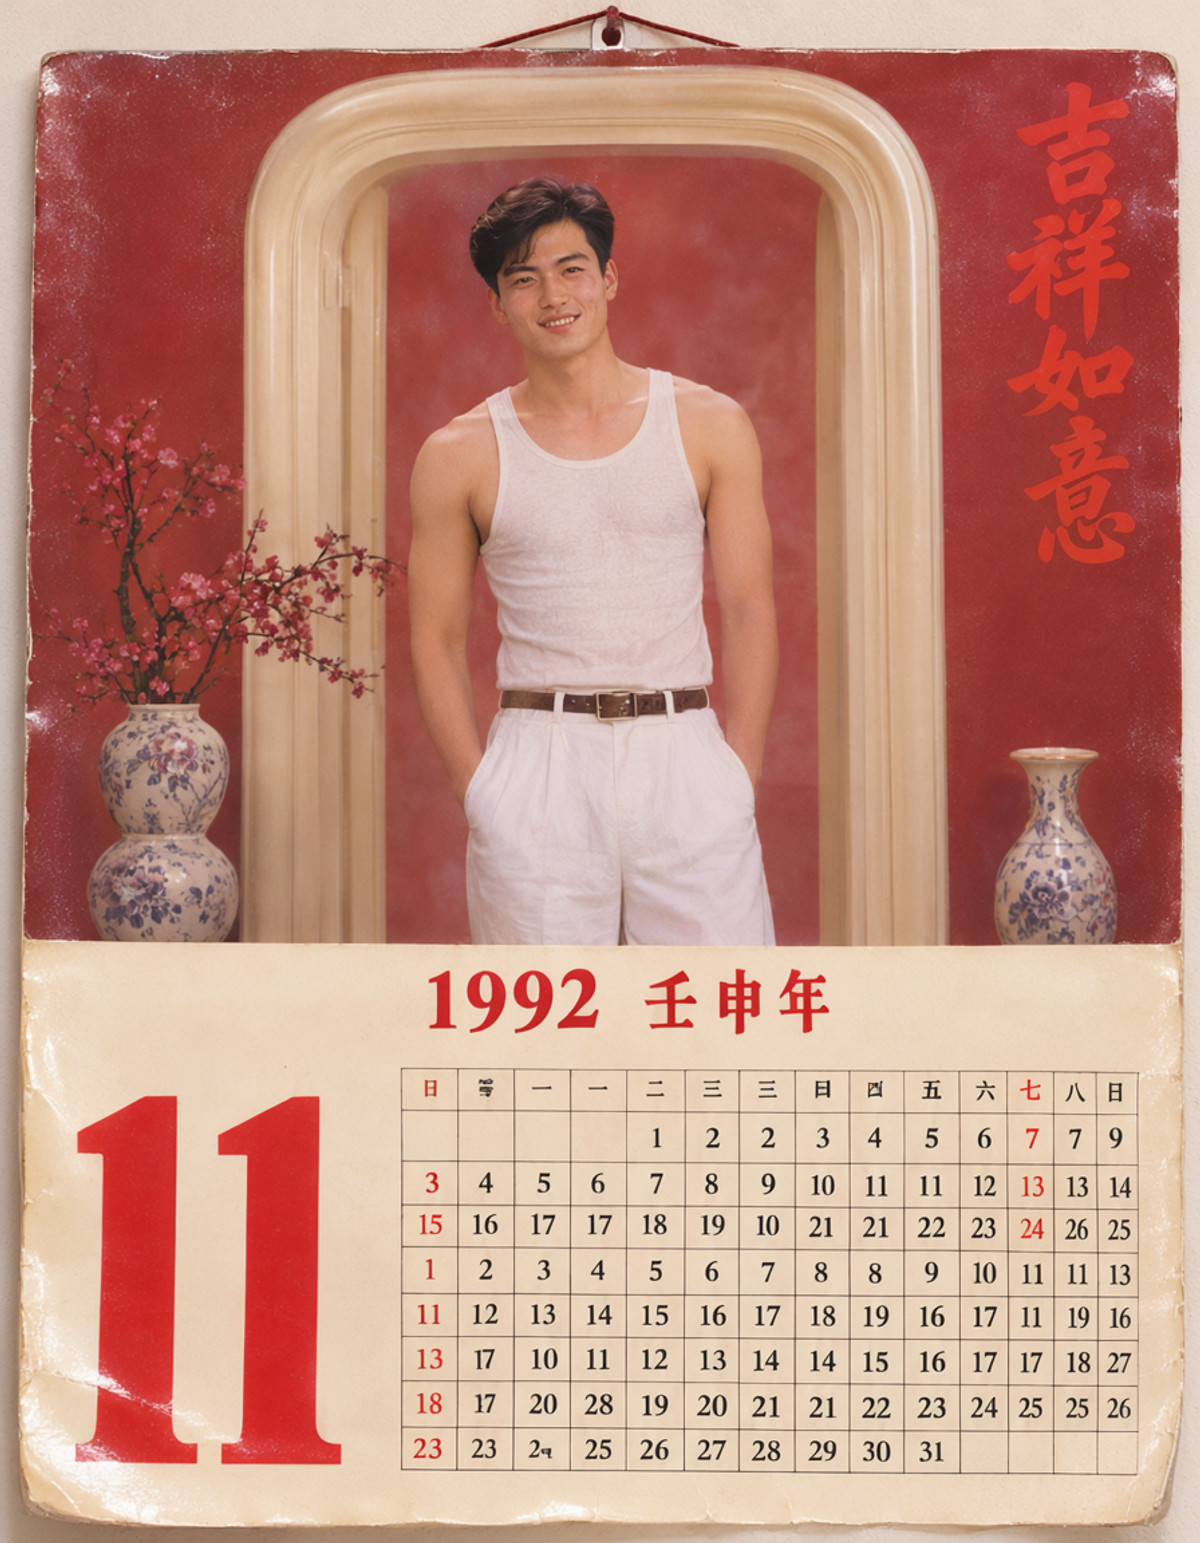
[A]1990s Chinese wall calendar · MOSS
LoRA · Port · Author 858654128784 · Released 11-17 18:03 · Downloads 24
The MOSS version of the "90s Chinese wall calendar" concept LoRA: makes the image look like a wall calendar from that era printed on coated paper—soft studio lighting, high saturation colors, models standing in front of backdrops with arches, vases, curtains, or balustrades, with red auspicious phrases, the year, and the zodiac animal at the top, and a monthly calendar grid with Sundays marked in red at the bottom.
Images
Reasons for Recommendation
- Port: A Krea 2 version was previously on the same page, but the author did not specify the differences between the MOSS and Krea versions, nor whether they use the same dataset
- Serves nostalgic posters, vintage visuals, and Spring Festival or retro-themed designs: it is not just about color grading, but also includes the layout (title text, year and zodiac, calendar grid); the title example given by the author is "Good Fortune 1992 Ren Shen Year"
- Has 2 visible examples; released 3 hours ago with 24 downloads and 4 comments, ranking high in attention within this group; free, license allows image generation, sales, and derivatives
How to Use
- The author has not registered a trigger word, nor provided strength, steps, or CFG; write prompts based on the model card description: 1990s Chinese wall calendar, glossy paper, soft studio light, saturated colour, then describe the backdrop (arches / vases / curtains / balustrades) and the red auspicious phrases, year, zodiac at the top, and the calendar grid at the bottom
- To get a specific year, include the year and the corresponding Heavenly Stem and Earthly Branch zodiac in the prompt, such as 1992 Ren Shen Year in the author's example
Risks and Limitations
- Out of 8 examples, 6 sensitive ones are hidden, leaving only 2 visible; the page contains mixed content
- The author does not specify whether the Chinese auspicious phrases, year, and calendar numbers in the MOSS version can be rendered correctly; text and date layouts need to be checked image by image
- The description consists of only a single paragraph of style description, with no parameters; the version notes for the MOSS version are empty
Worth Watching (7)
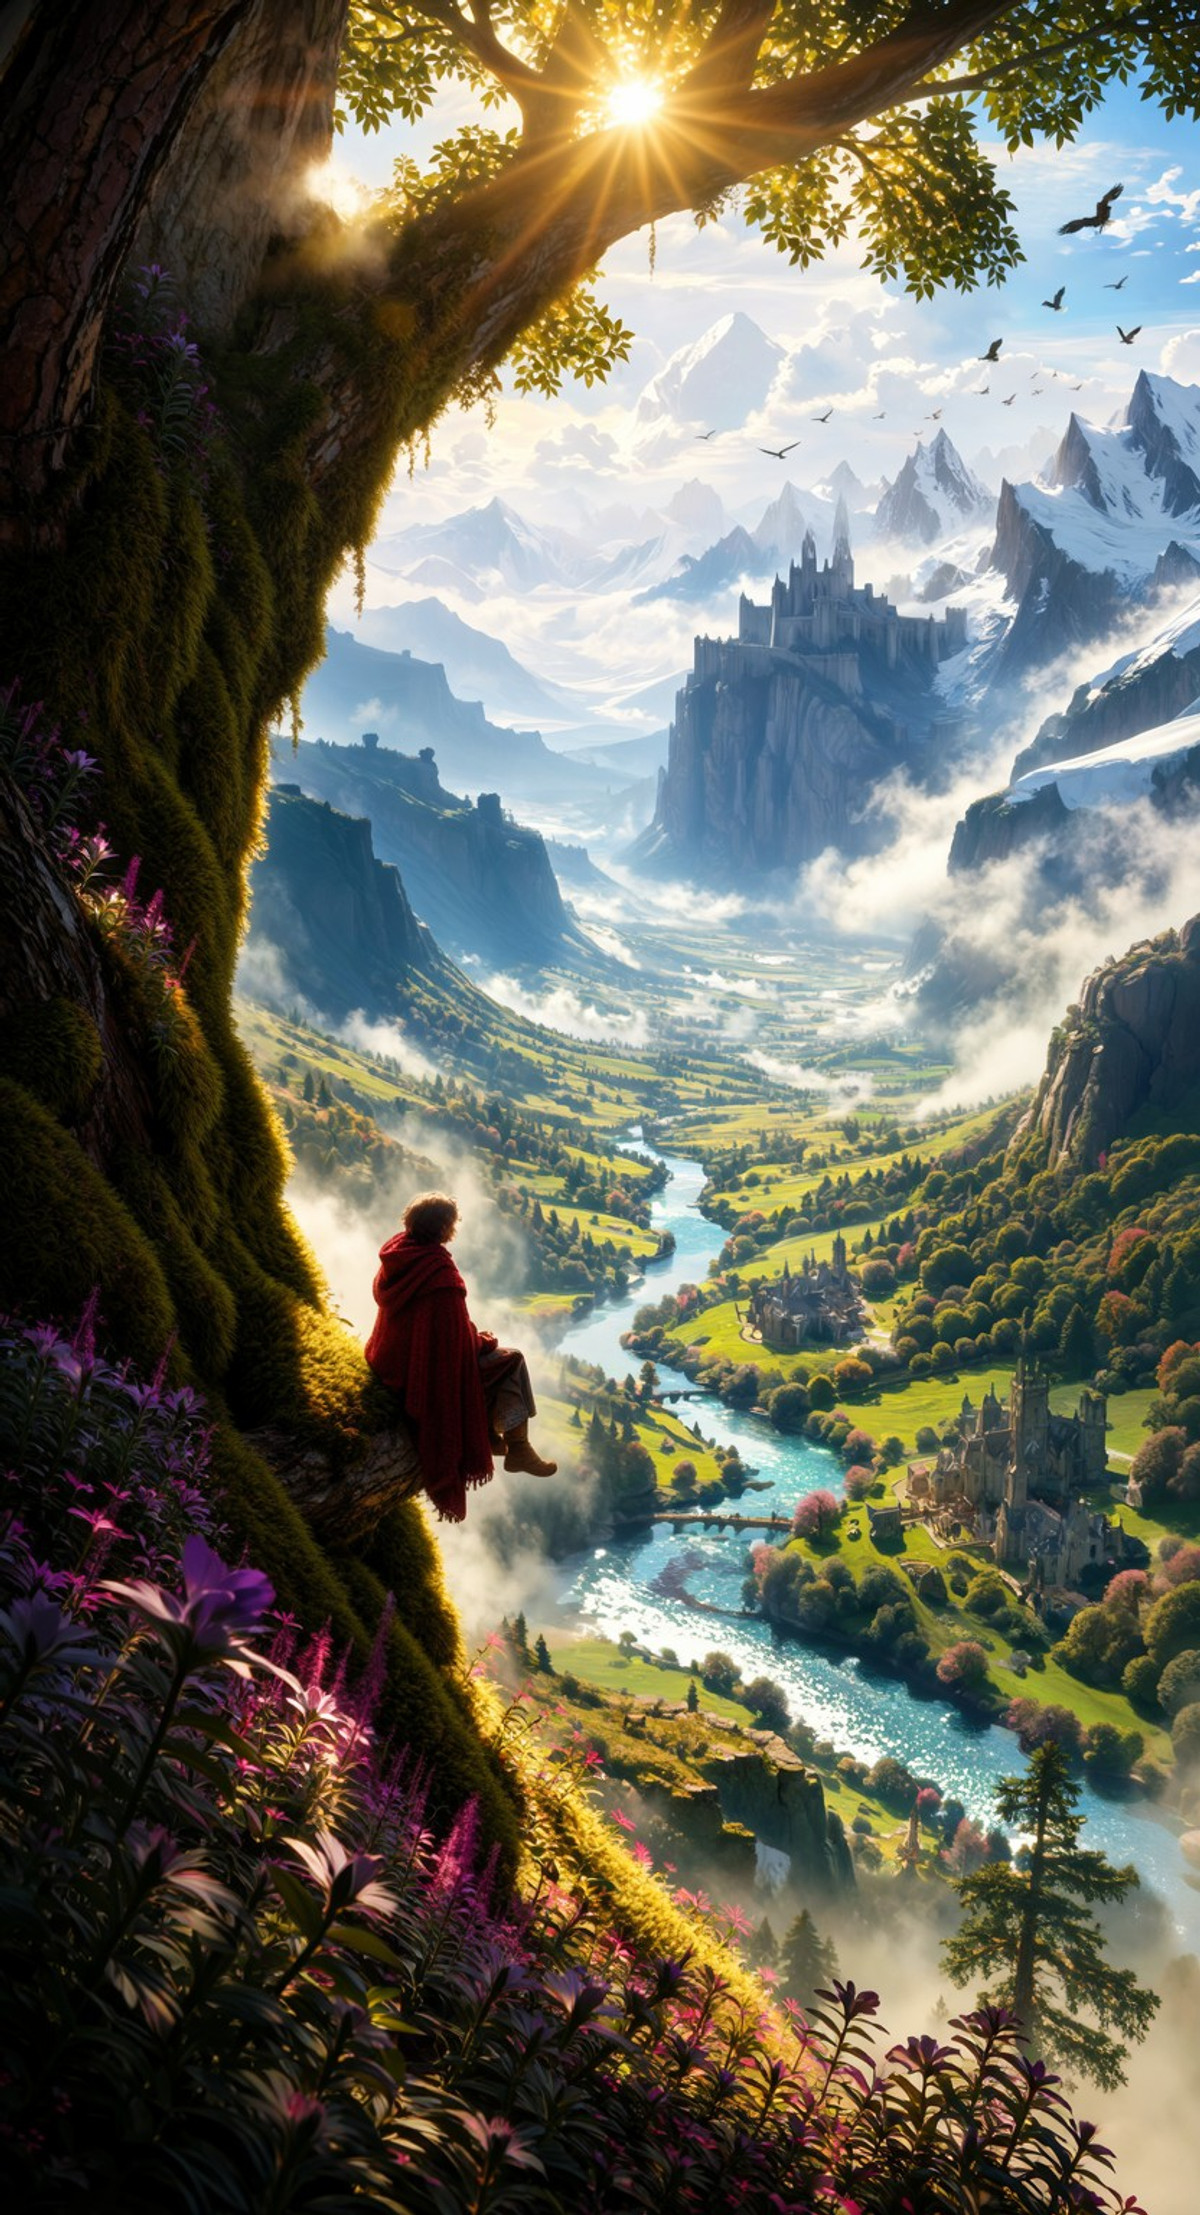
[B]Delicate-oil-paint-brushstroke-style-moss-image · v1.0
LoRA · New Model · Author Bigesila · Released 11-17 18:16 · Downloads 47
A style enhancement LoRA: trained on reference images in NAI5 style, the author claims it is used to improve brushstroke delicacy, local textures, and detail layers, without binding to specific characters or concepts, and no trigger word is required.
Images
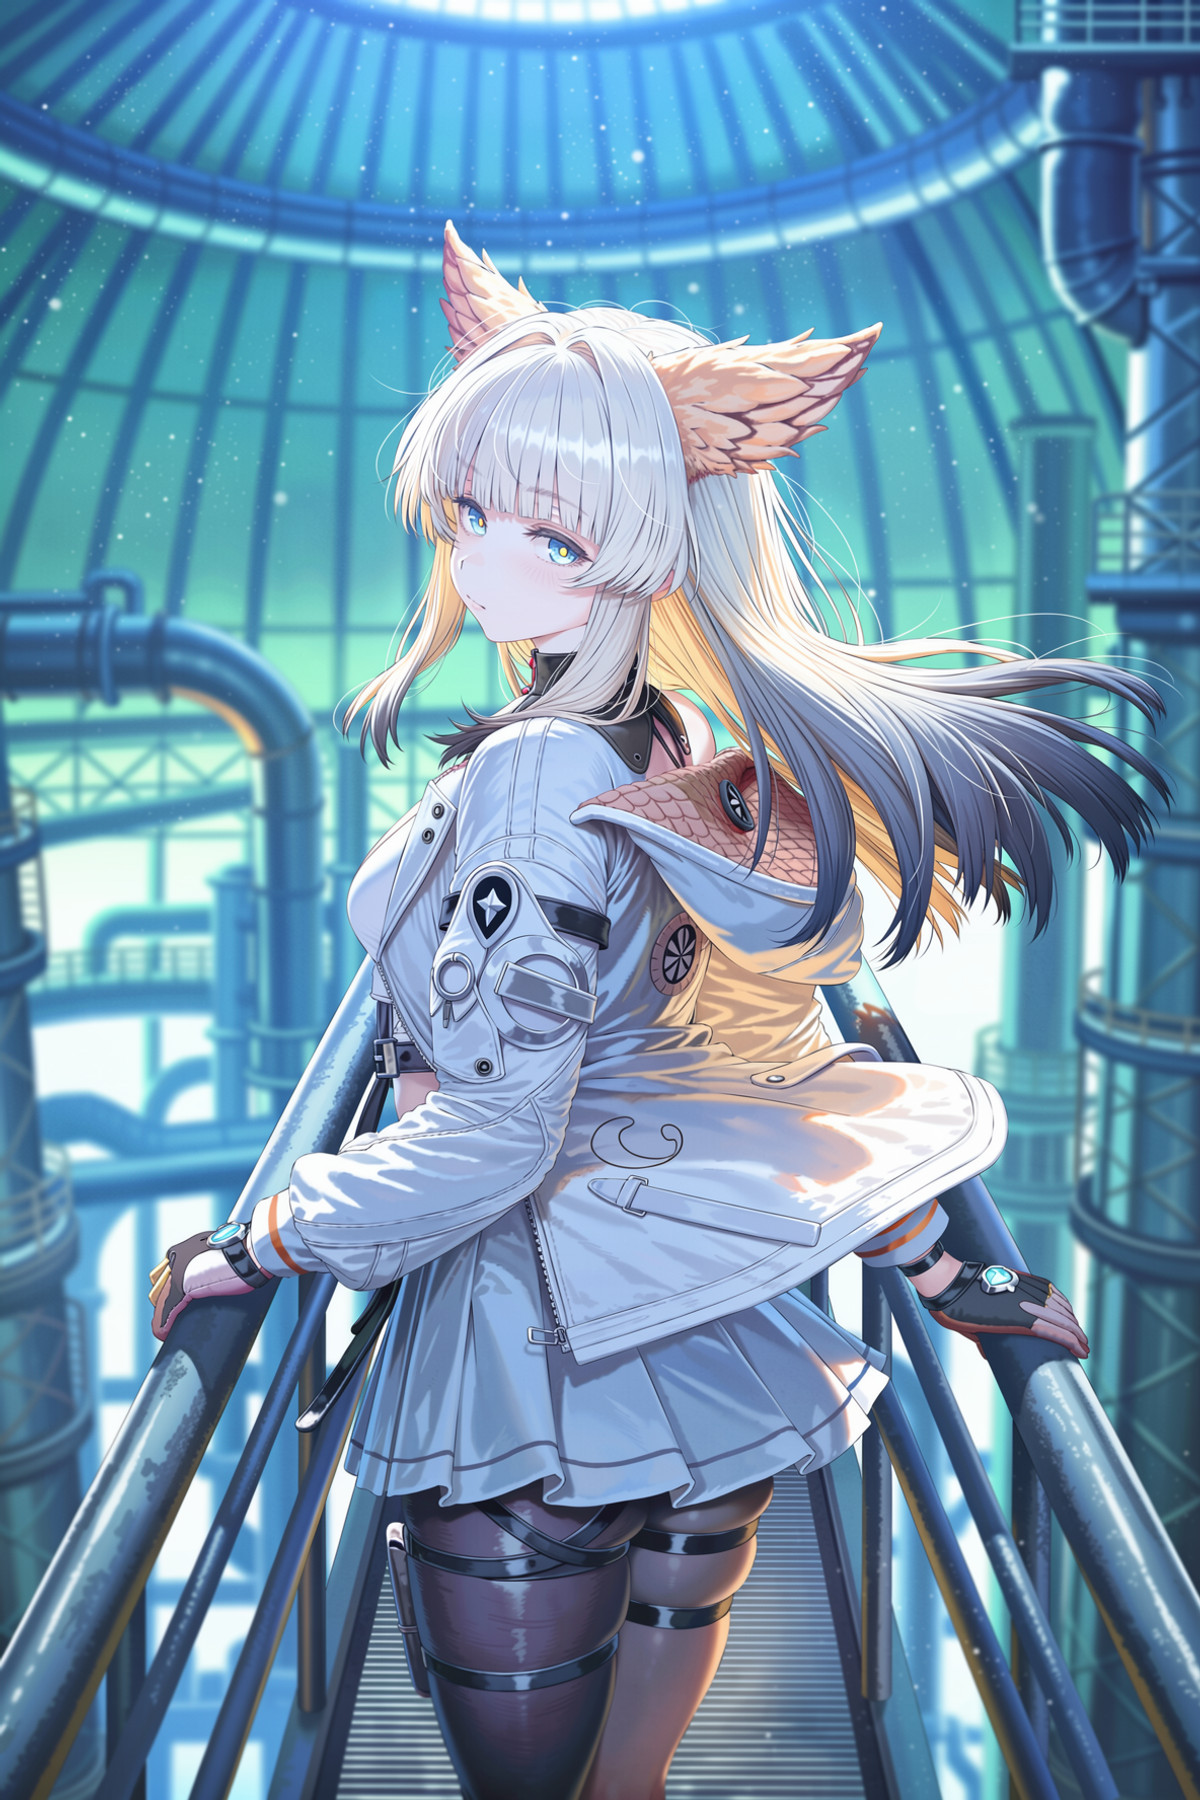
[B]My fantasy origins · v2-Moss
LoRA · Port · Author Grimm0 · Released 11-17 16:26 · Downloads 30
The MOSS version of My fantasy origins: an illustration/painting style LoRA for general fantasy and sci-fi themes, the author claims it covers warriors, elves, angels, demons, surreal landscapes, as well as robots, cyborgs, and neon cities.
Images
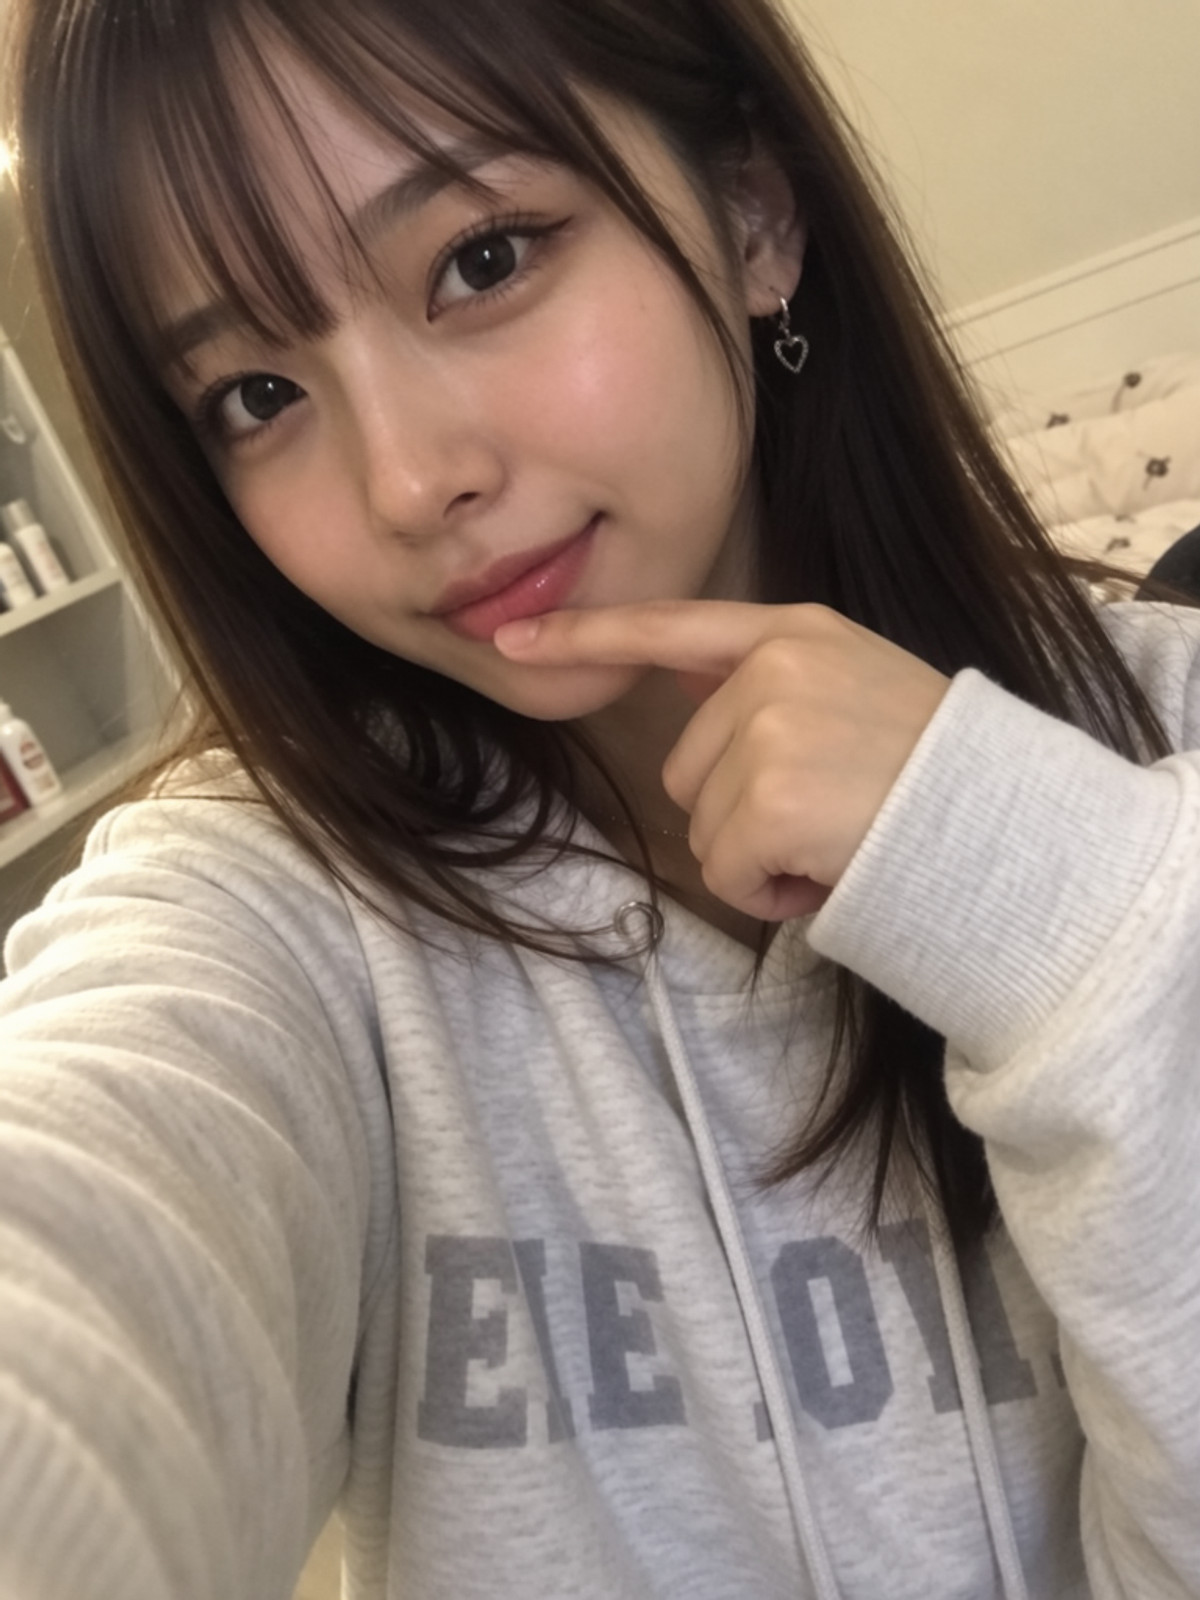
[B]moss base flirty finger on mouth · v1
LoRA · New Model · Author hamstornado · Released 11-17 20:02 · Downloads 24
A gesture concept LoRA: makes characters perform a playful "finger on mouth" gesture, with the index finger or thumb lightly touching the lower lip, trained on MOSS Base.
Images
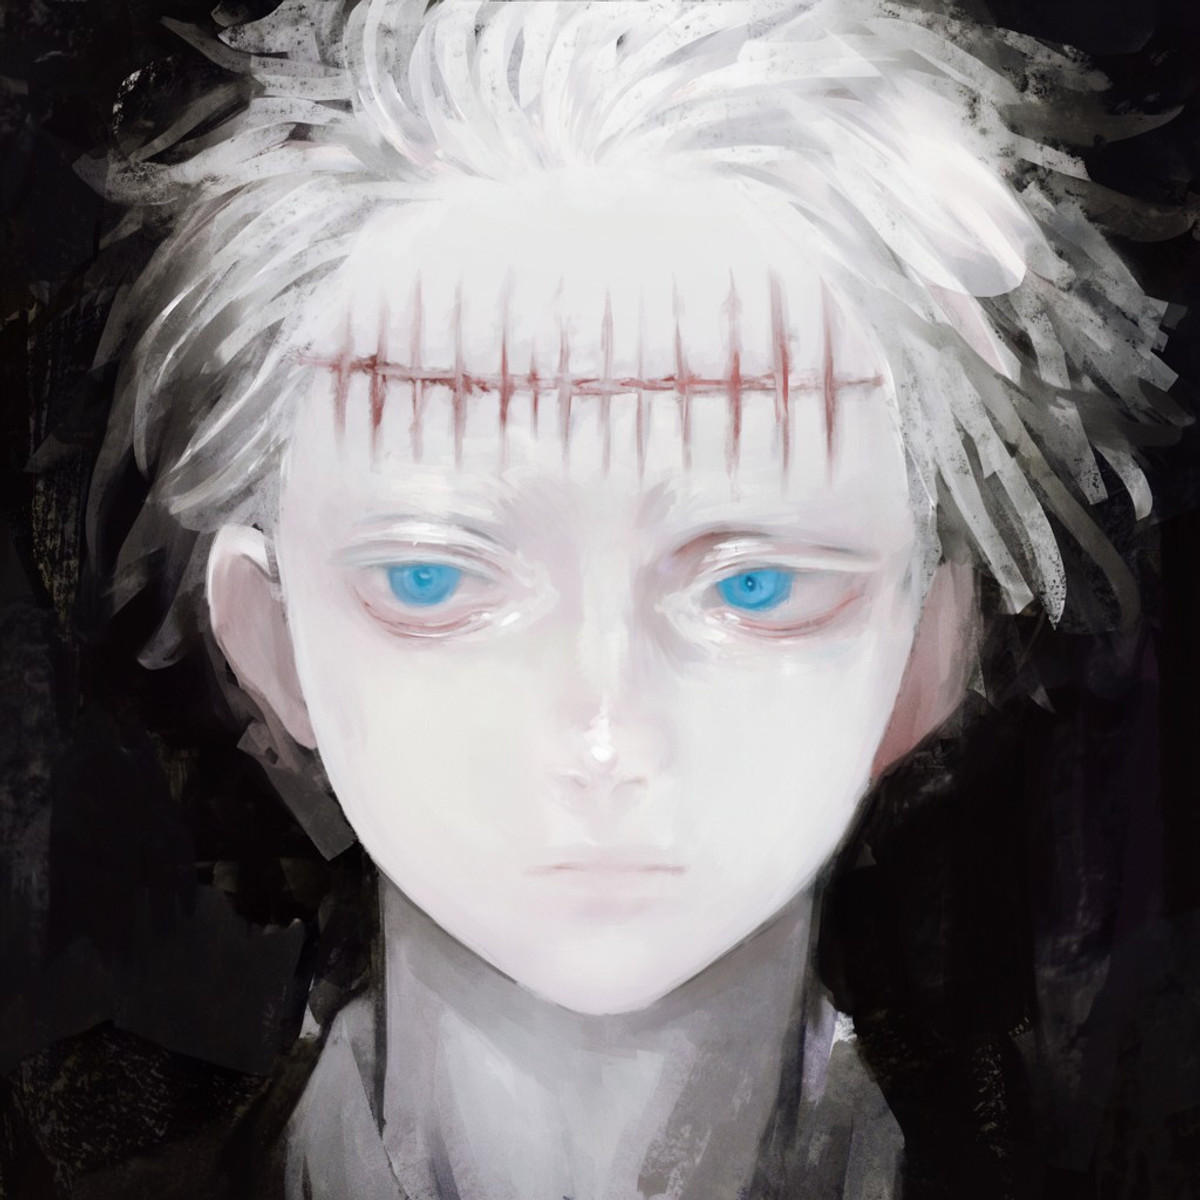
[B]Sui Ishida Style [Moss-Image] · v1
LoRA · New Model · Author Autokrator_Mechanicus · Published 11-17 17:41 · Download 17
A LoRA mimicking the art style of Sui Ishida, the author of Tokyo Ghoul, trained using the Civitai online LoRA trainer. The author states that the effect is very weak.
Image
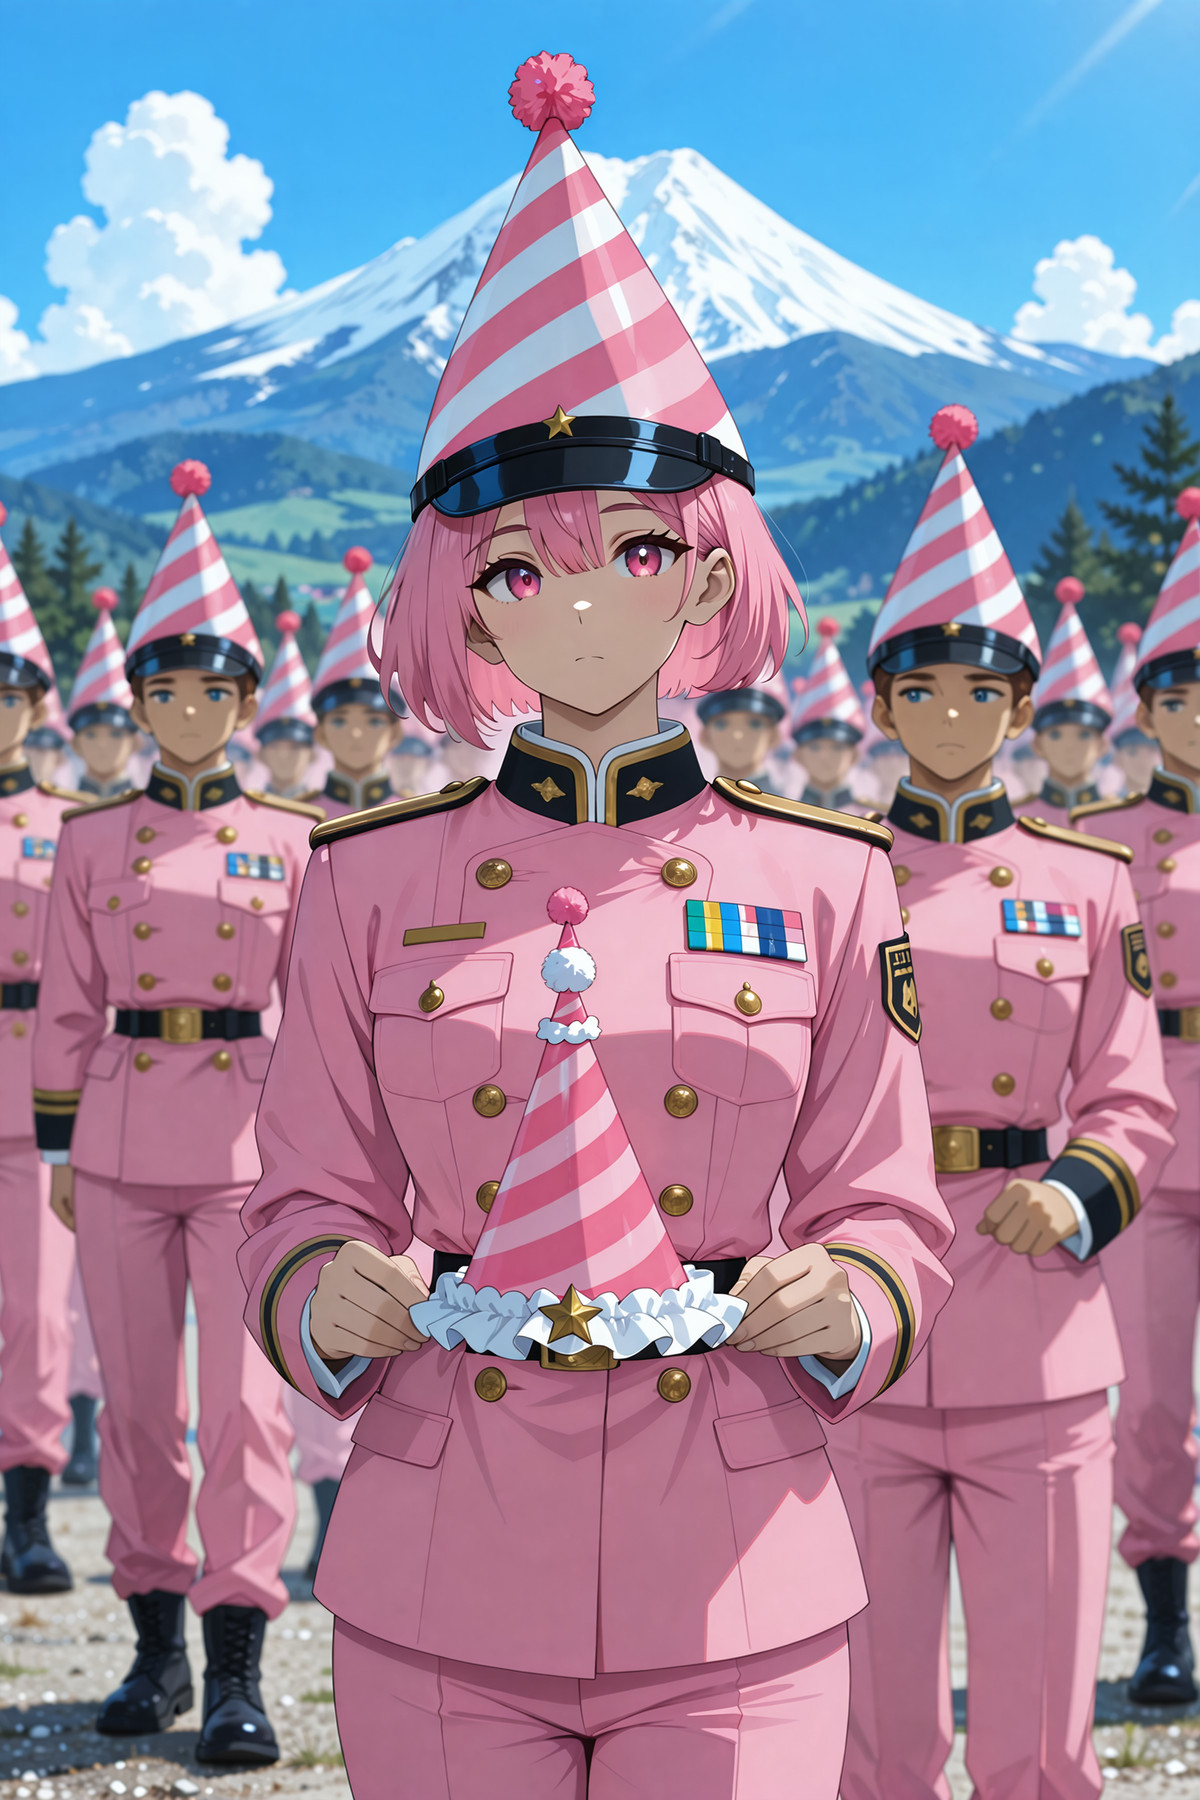
【B】Pink Army: Umbrium Hat War Ammo · MOSS v1
LoRA · Port · Author umbrium2835 · Published 11-17 20:40 · Download 4
The MOSS version of Pink Army: a prop LoRA that places a pink birthday event hat with white trim into the scene. It can be worn on a character's head, placed on an object, or set on a table.
Image
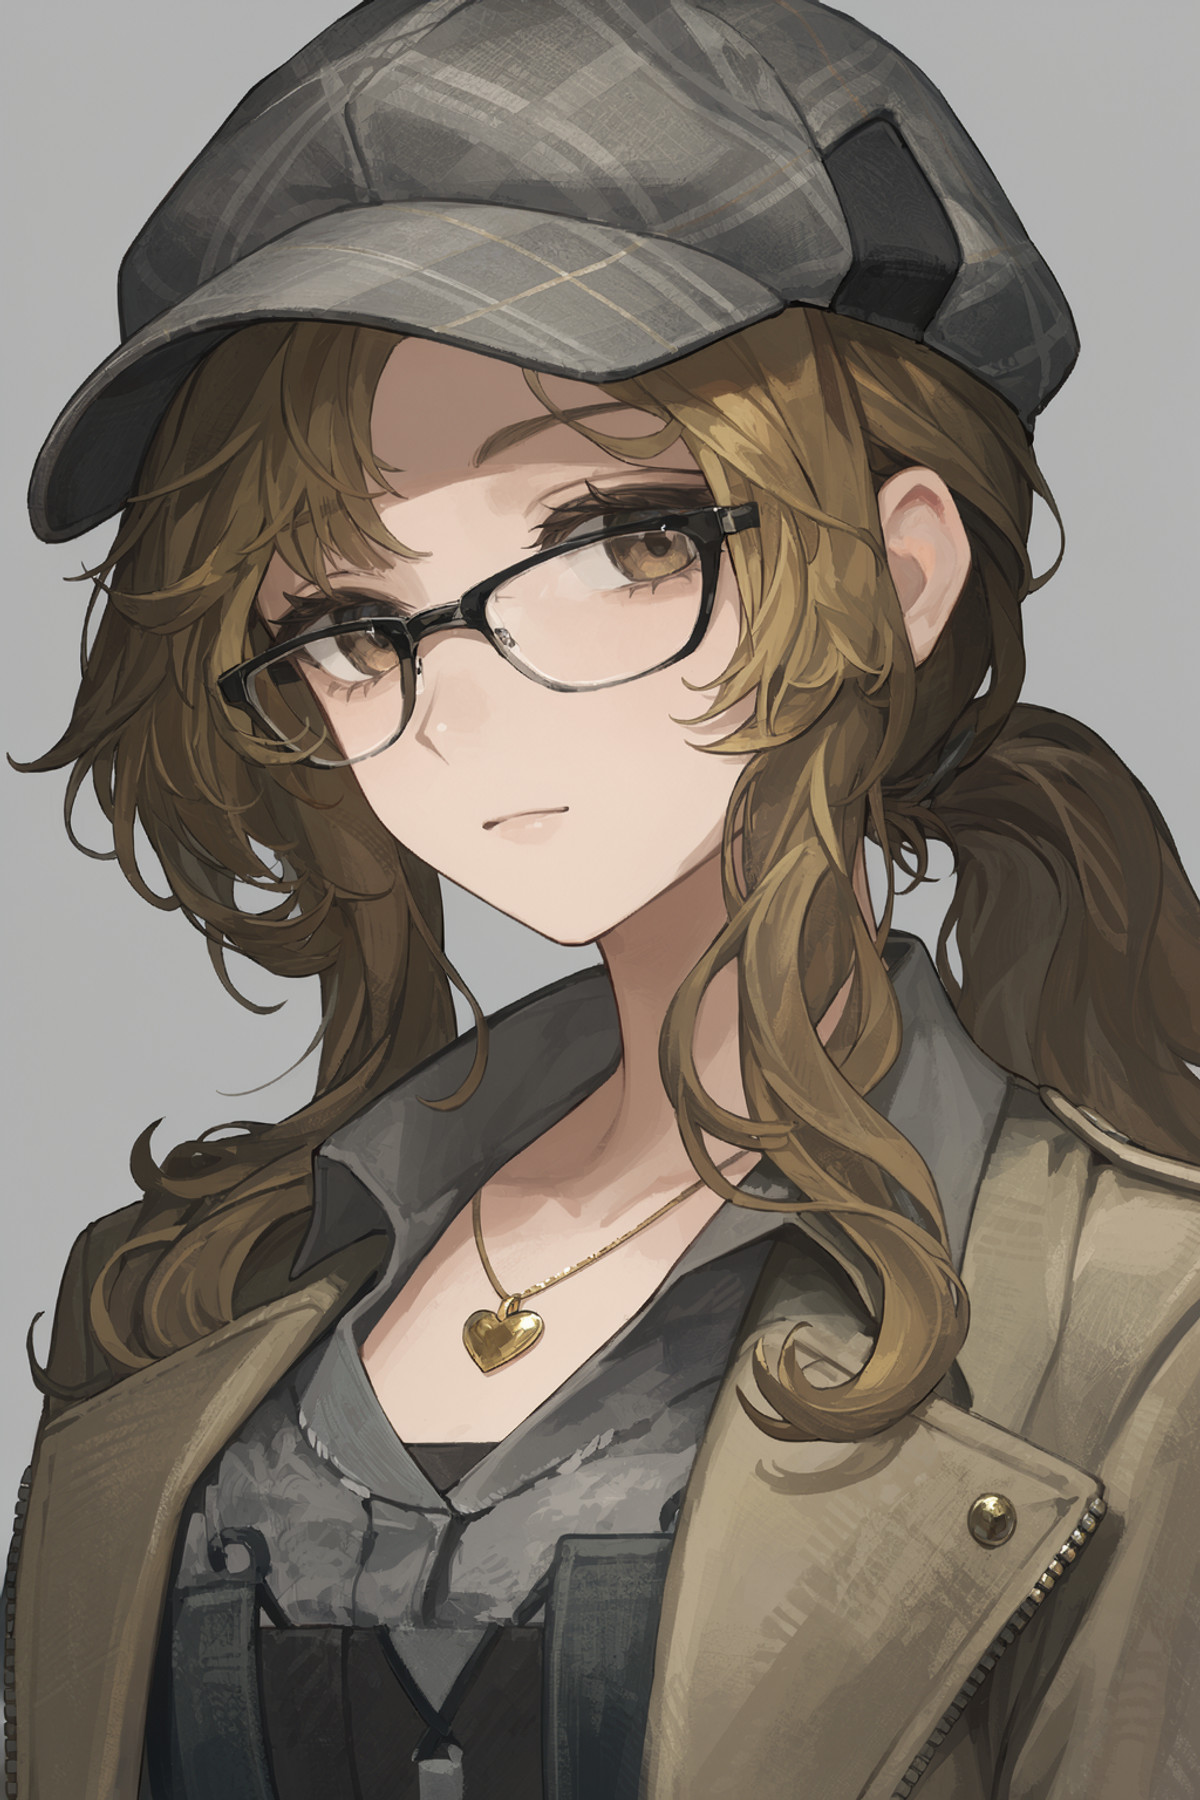
【B】Reverse:1999 Style [Reverse:1999:1999 anima/moss] · moss_v1.0
LoRA · Port · Author zyz292 · Published 11-17 17:32 · Download 29
MOSS version of the LoRA in the official illustration style of Reverse: 1999 1999: Recreates the official illustrations' color palette, hair block shapes, brushstroke texture, and lighting atmosphere, targeting character portraits, half-body shots, and character illustrations with scenes.
Image
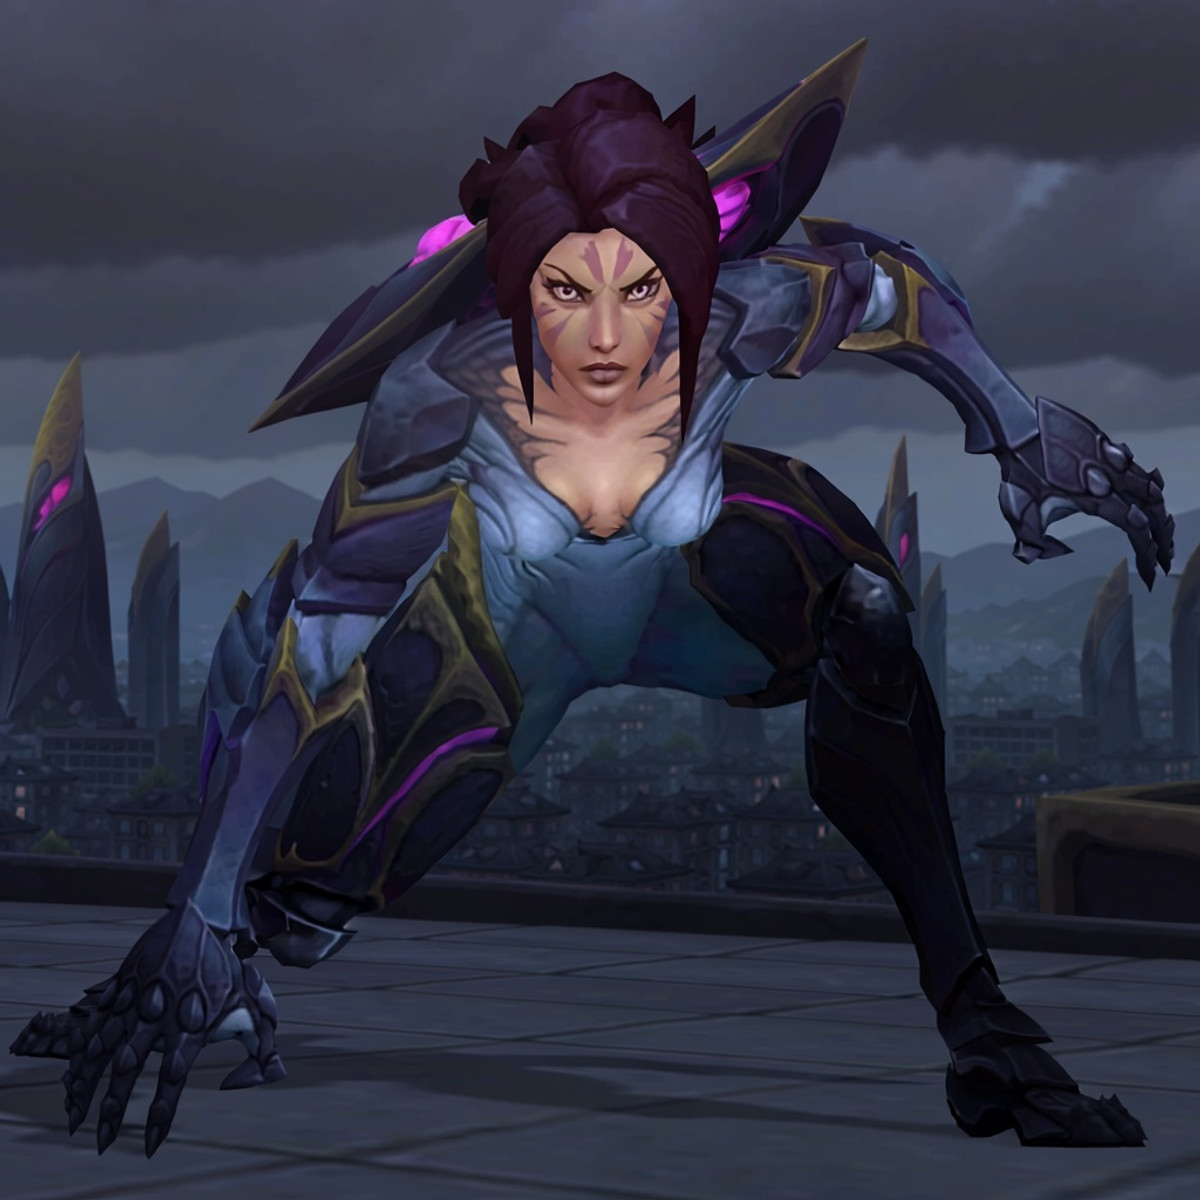
【B】Kai'Sa (League of Legends) [MOSS IMAGE] · v1.0
LoRA · New Model · Author CharacterForge · Published 11-17 20:36 · Download 5
A MOSS character LoRA for Kai'Sa from League of Legends (default skin), trained on 3D game character renders and used with MOSS-Image SFT.
Image
Included Only (15)
- V67 Perfect Prompt · V1 MOSS — LoRA: The MOSS version of V67 Perfect Prompt: a quality-oriented "prompt engineering" LoRA, used in conjunction with the author's complete method for writing prompts (subject action, master style, camera lens parameters).
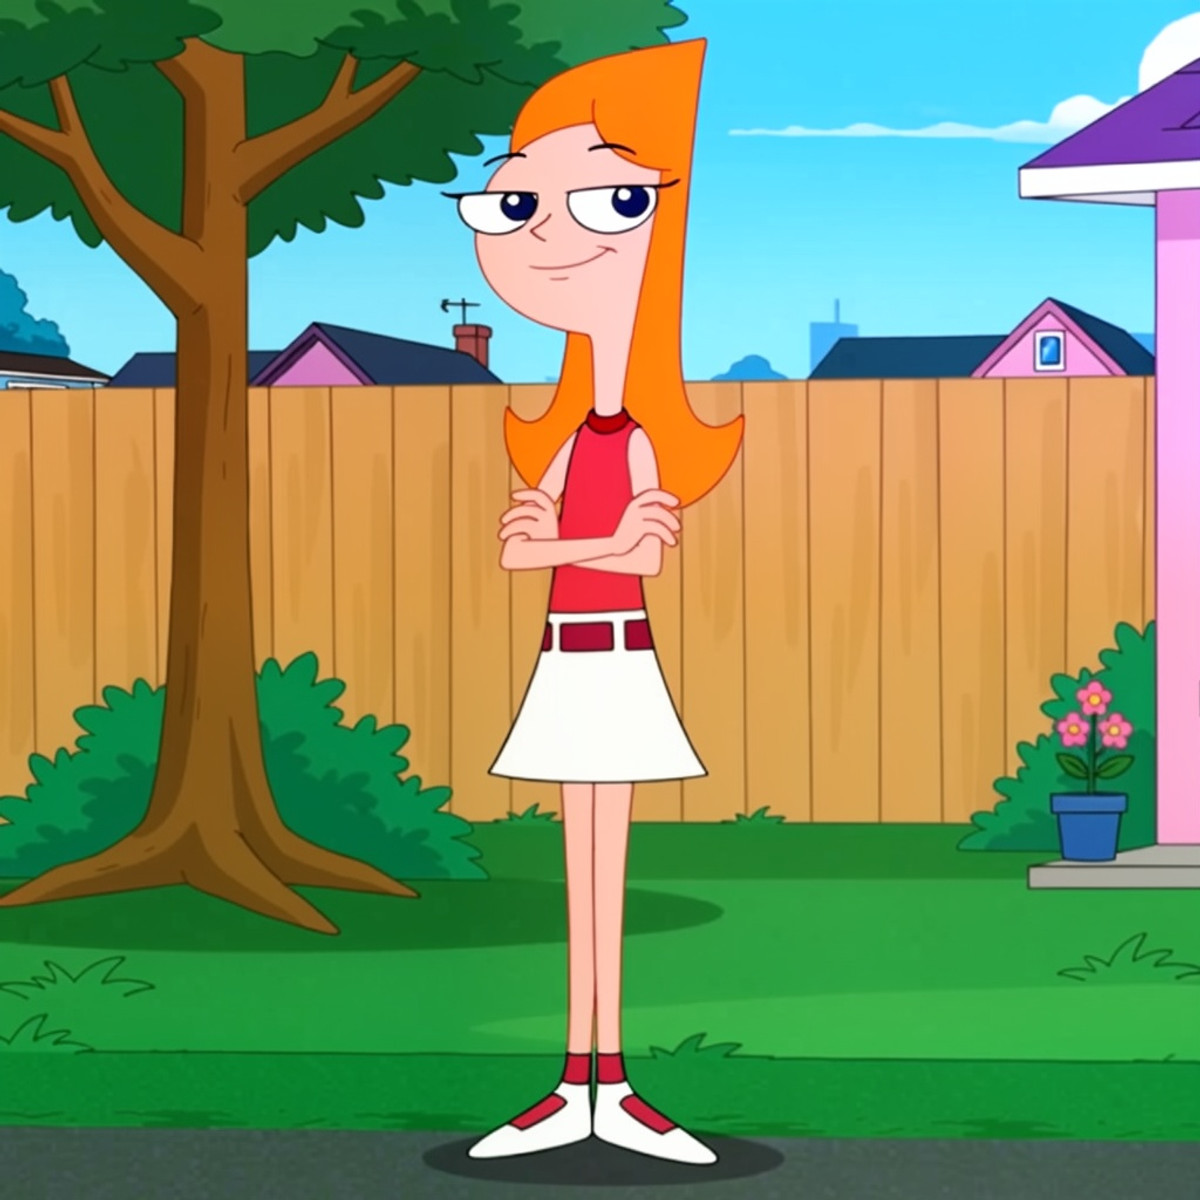
- Candace Flynn [MOSS IMAGE] · v1.0 — LoRA: A MOSS character LoRA for Candace Flynn (the older sister from Phineas and Ferb): generates 2D animation-style images of this cartoon character.
- Ratatatat74 - Style MOSS LORA · v1.0 — LoRA: A MOSS style LoRA for the art style of artist Ratatatat74, with the starting phrase "sketchy comic panel illustration".
- Kira — The final [MOSS / Krea 2,Qwen 2.1] · Final MOSS — LoRA: The MOSS "Final" version of Kira, a realistic Slavic female character, which the author claims is the final version of this character's cross-architecture series.
- Yuzuha / Japanese AI girl · MOSS — LoRA: The MOSS version of a realistic character LoRA for Yuzuha, an original fictional Japanese female character created by the author, trained on MOSS-Image-Base and used only for single-person generation.
- Emilia true eyes | Re:Zero | MOSS-Image lora · MOSS — LoRA: A concept LoRA that enables MOSS to draw Emilia's iconic purple eyes and blue pupils from Re:Zero, including two weight files, v1 and v2, in the same version.
- SoulTide 灵魂潮汐 Silenus 西勒诺斯 DiT · MOSSTagFlowV1.1 — LoRA: A MOSS character LoRA for Silenus from the mobile game Soul Tide, with separate trigger words for four outfits: default, student, wedding dress, and witch.
- SoulTide 灵魂潮汐 HagakureRuri 叶隐琉璃 DiT · MOSSTagFlowV1.0 — LoRA: A MOSS character LoRA for Hagakure Ruri from the mobile game Soul Tide, using one base trigger word plus five outfit trigger words to switch between five looks: pajamas, swimsuit, casual wear, Christmas, and wedding.
- SoulTide 灵魂潮汐 QingHao 青蒿 DiT · MOSSTagFlowV1.0 — LoRA: A MOSS character LoRA for Qing Hao from the mobile game Soul Tide, using one base trigger word plus three outfit trigger words to switch between three looks: New Year, swimsuit, and casual wear.
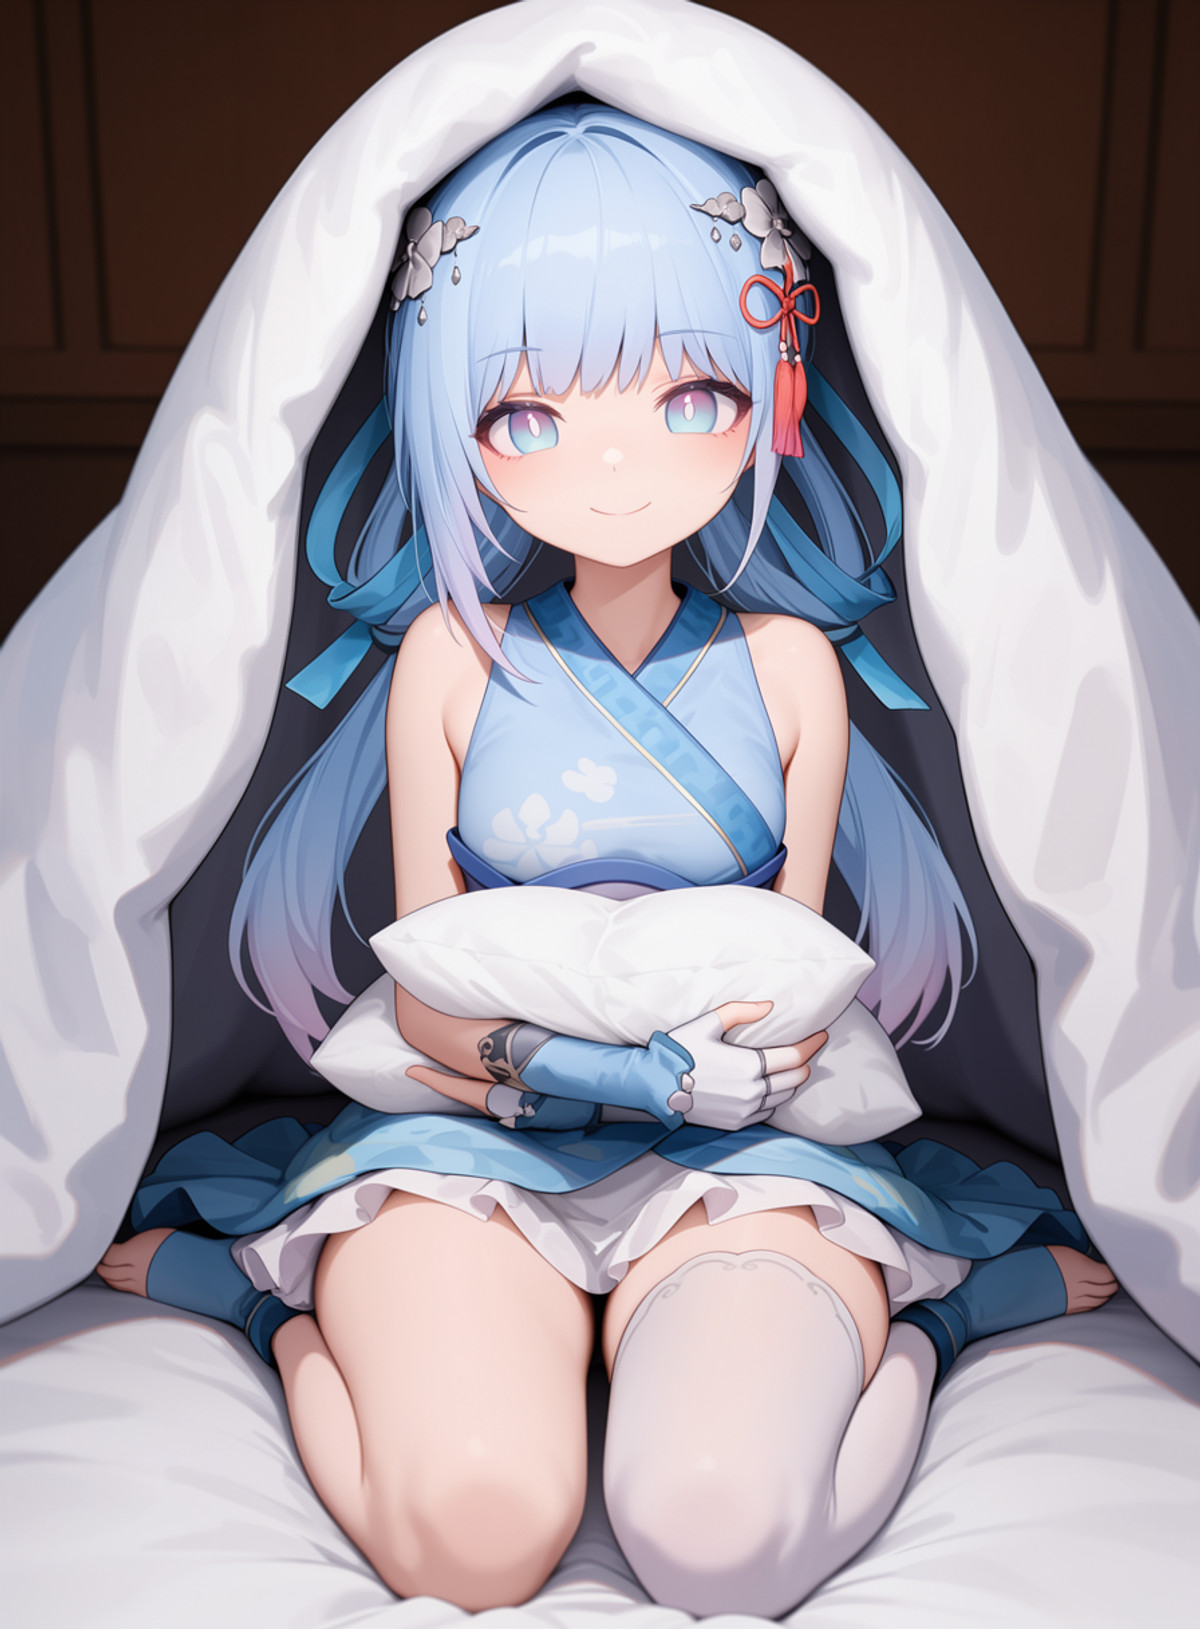
- Character | Ajitani Hifumi | 阿慈谷ヒフミ · v1.0 — LoRA: A MOSS character LoRA for Ajitani Hifumi from Blue Archive, using three trigger words to switch between three looks: default, racing suit, and swimsuit.
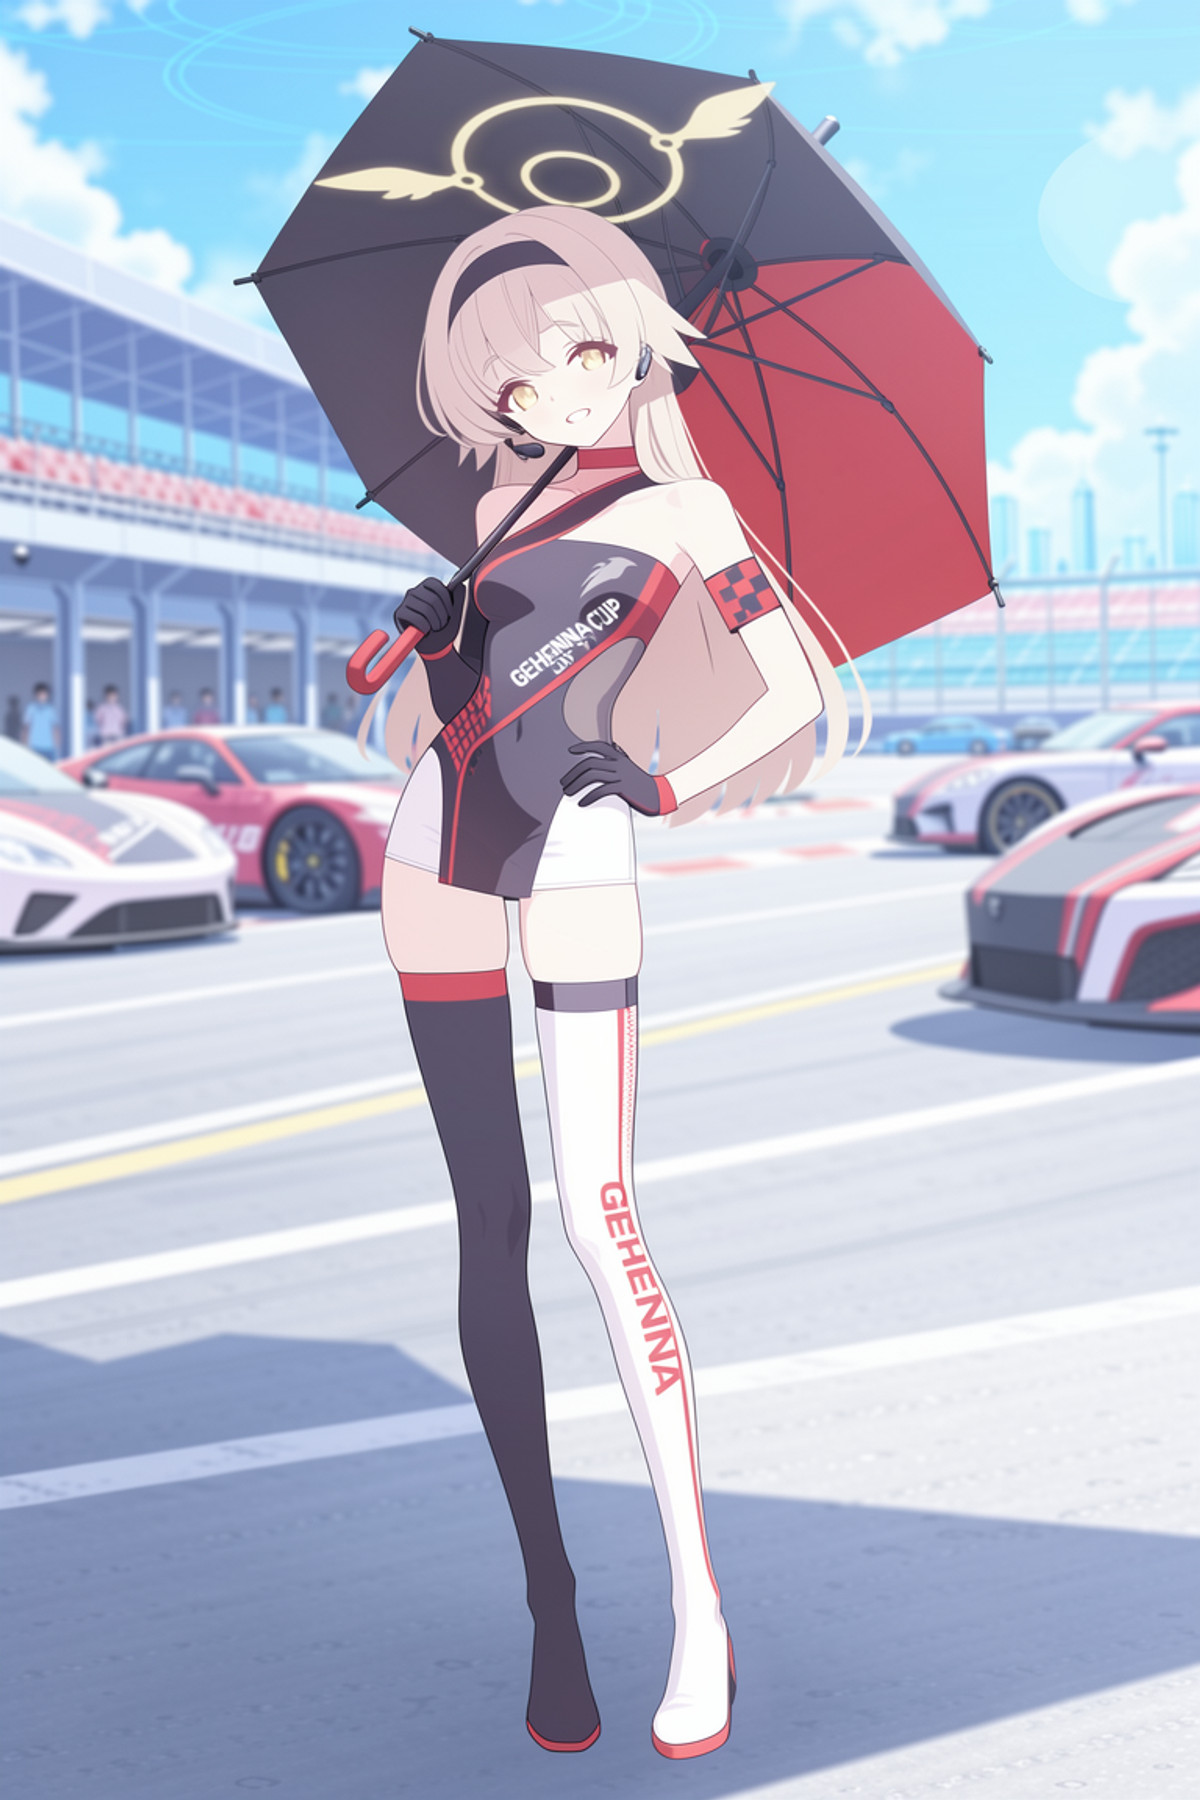
- MOSS image 异环 Lora 合集 | MOSS image Neverness to Everness LoRA Collection · 曳尔沐_v2 — LoRA: v2 of the character Elyms from the "MOSS image Neverness to Everness LoRA Collection": a retrained version of the character LoRA for the game Neverness to Everness.
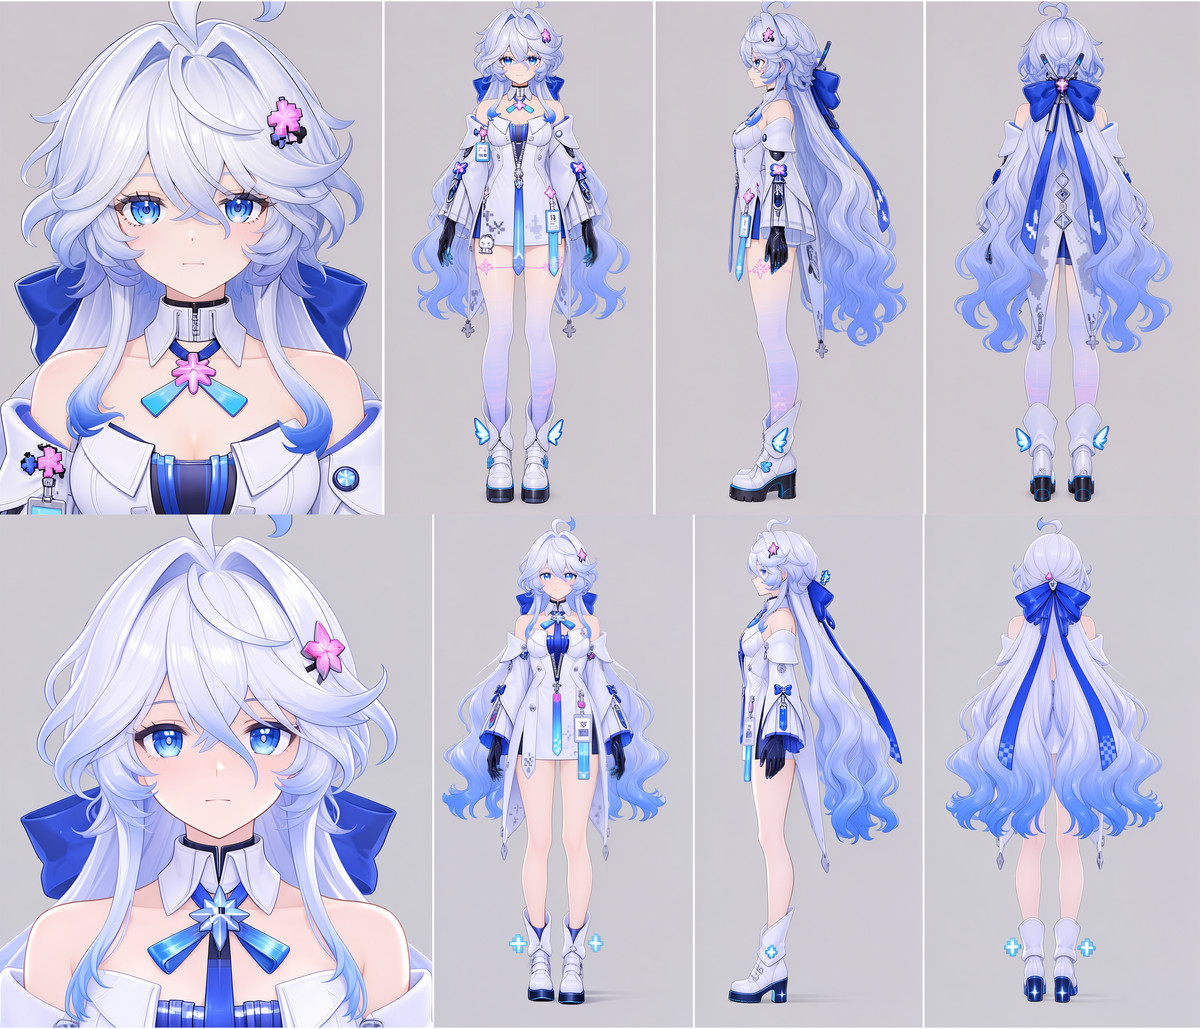
- Gogo · v1 — LoRA: A character LoRA named Gogo. The model card only says "character LoRA," with no information on which character or what art style it is, so one can only judge from the examples.
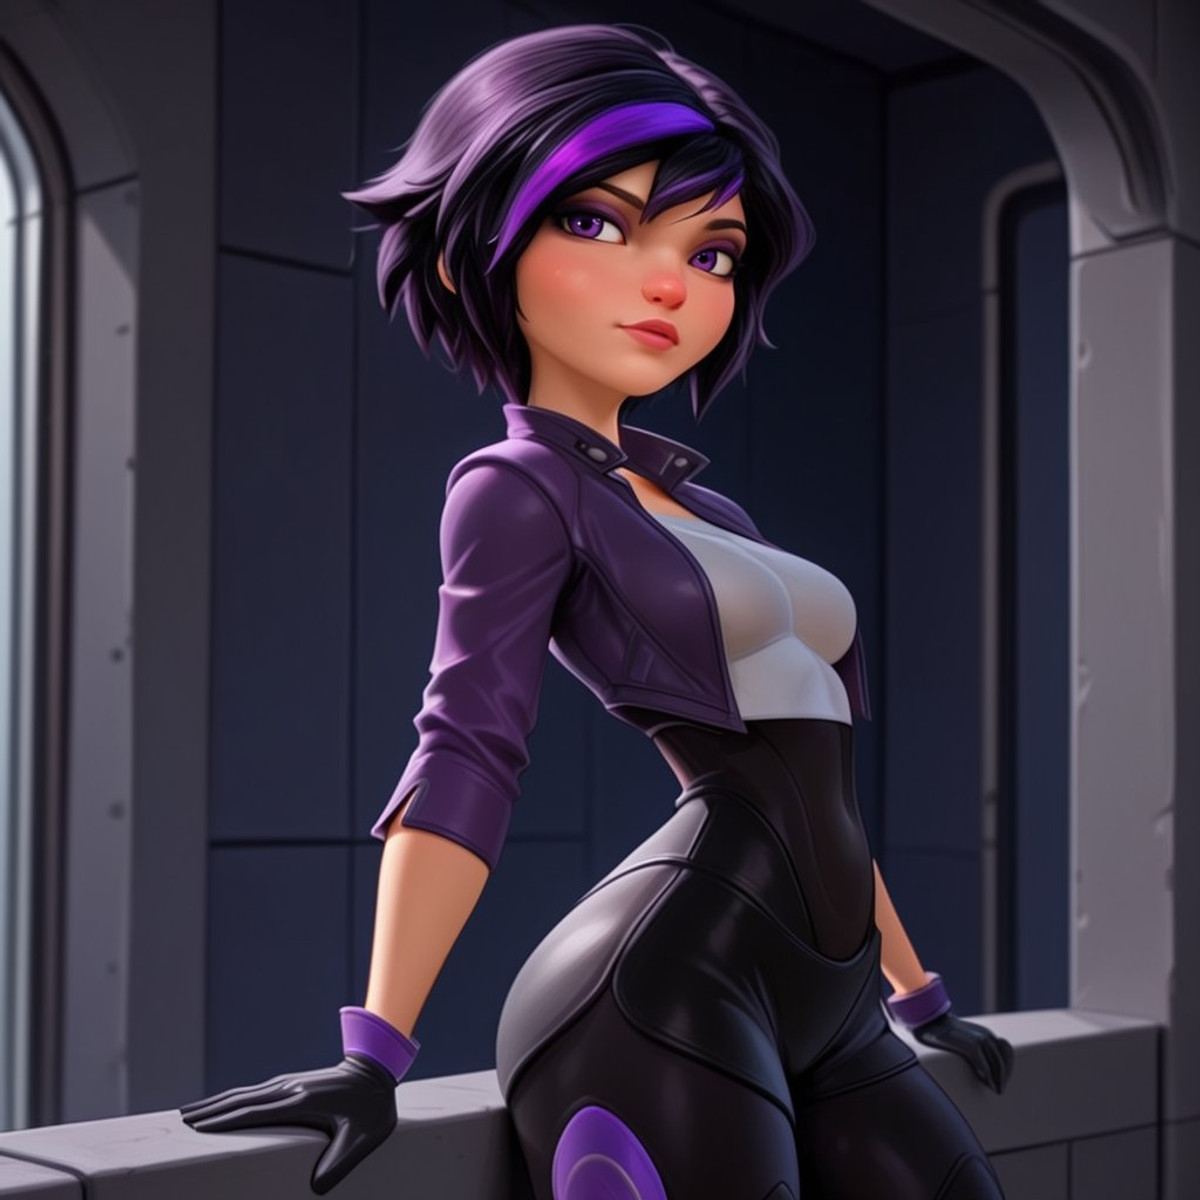
- Artist Style | Mikagami Mamizu | 水鏡まみず · sft — LoRA: The MOSS SFT version of the art style LoRA for artist Mikagami Mamizu: it is a separate weight file from the base version on the same page, used with MOSS Image SFT.
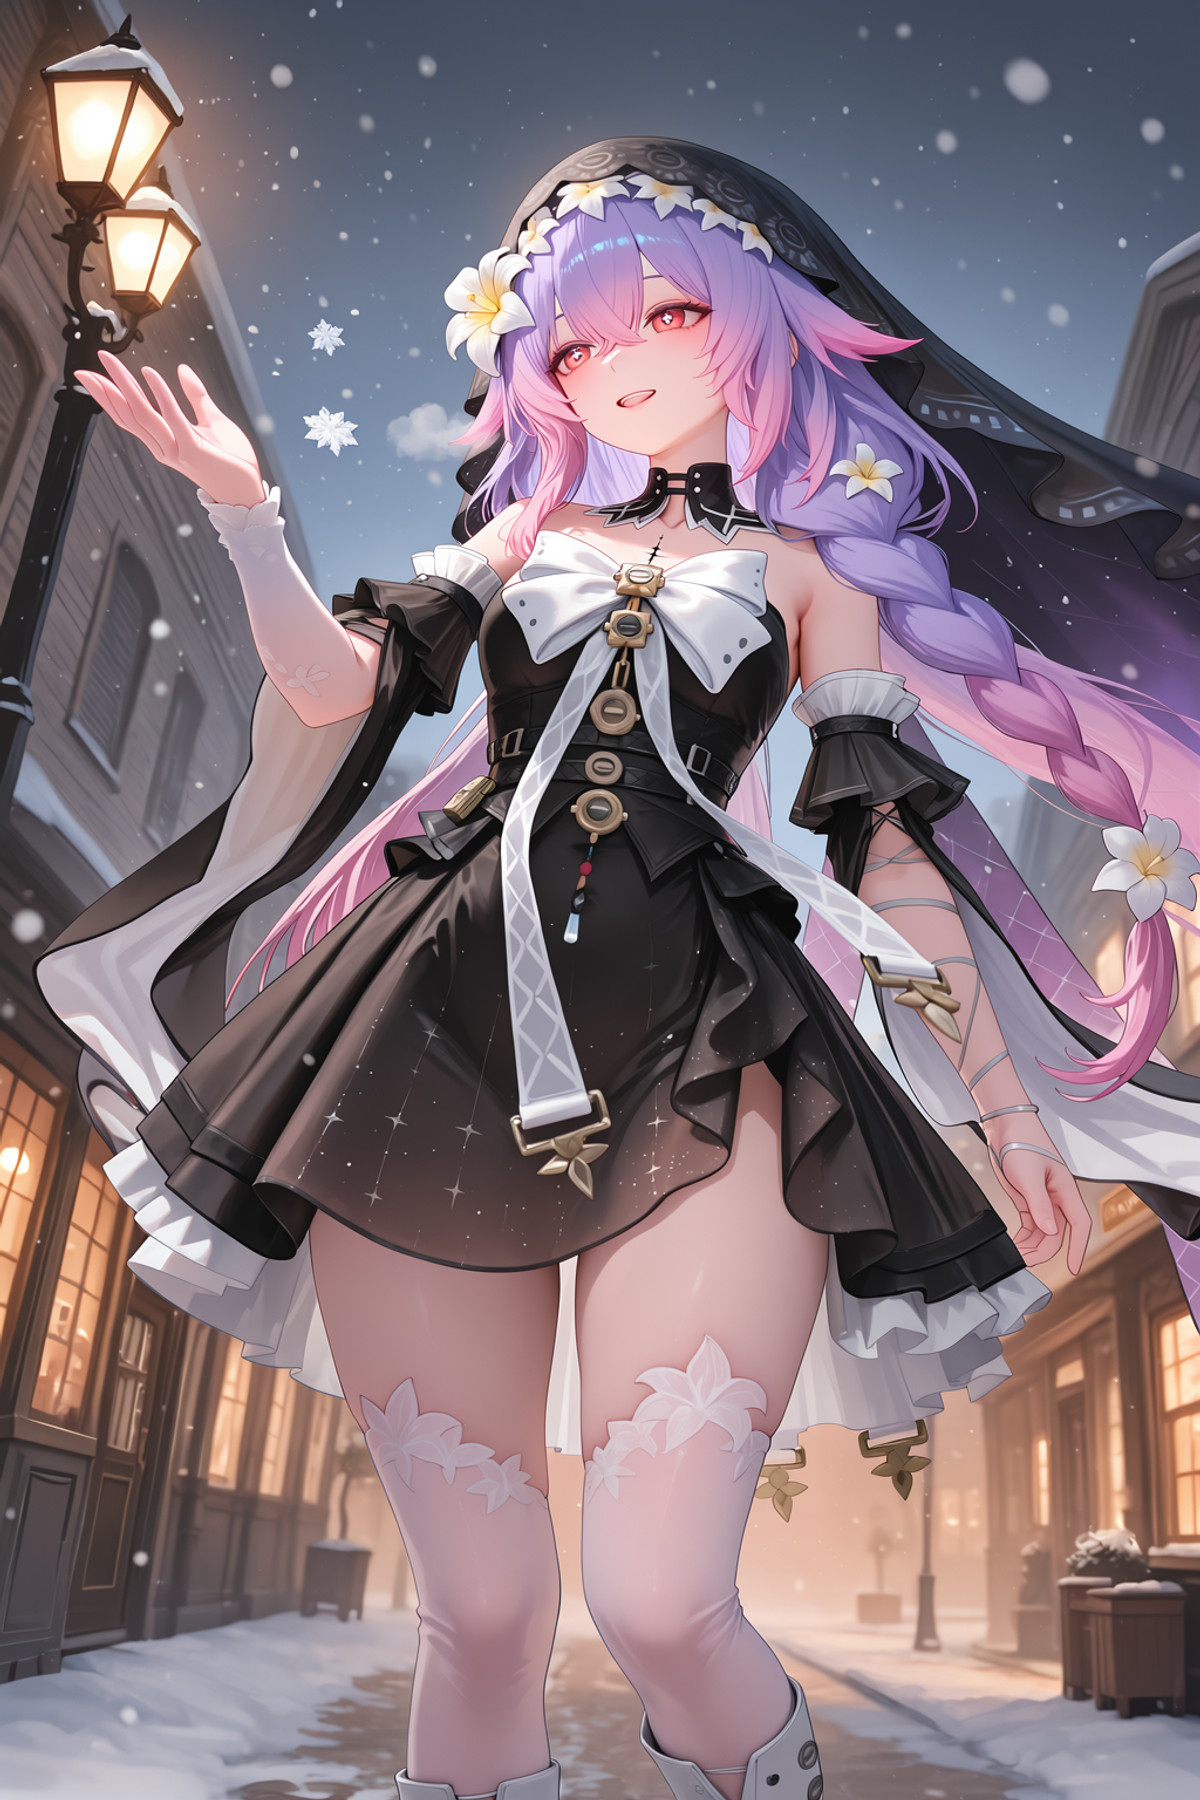
- Lily リリー — Wuthering Waves 鳴潮 [Anima+MOSS] · v1.0 MOSS Image — LoRA: A MOSS character LoRA for Lily from Wuthering Waves, trained with the same batch of images and annotations as the Anima version on the same page, with the same trigger words; the data is marked as paid download.
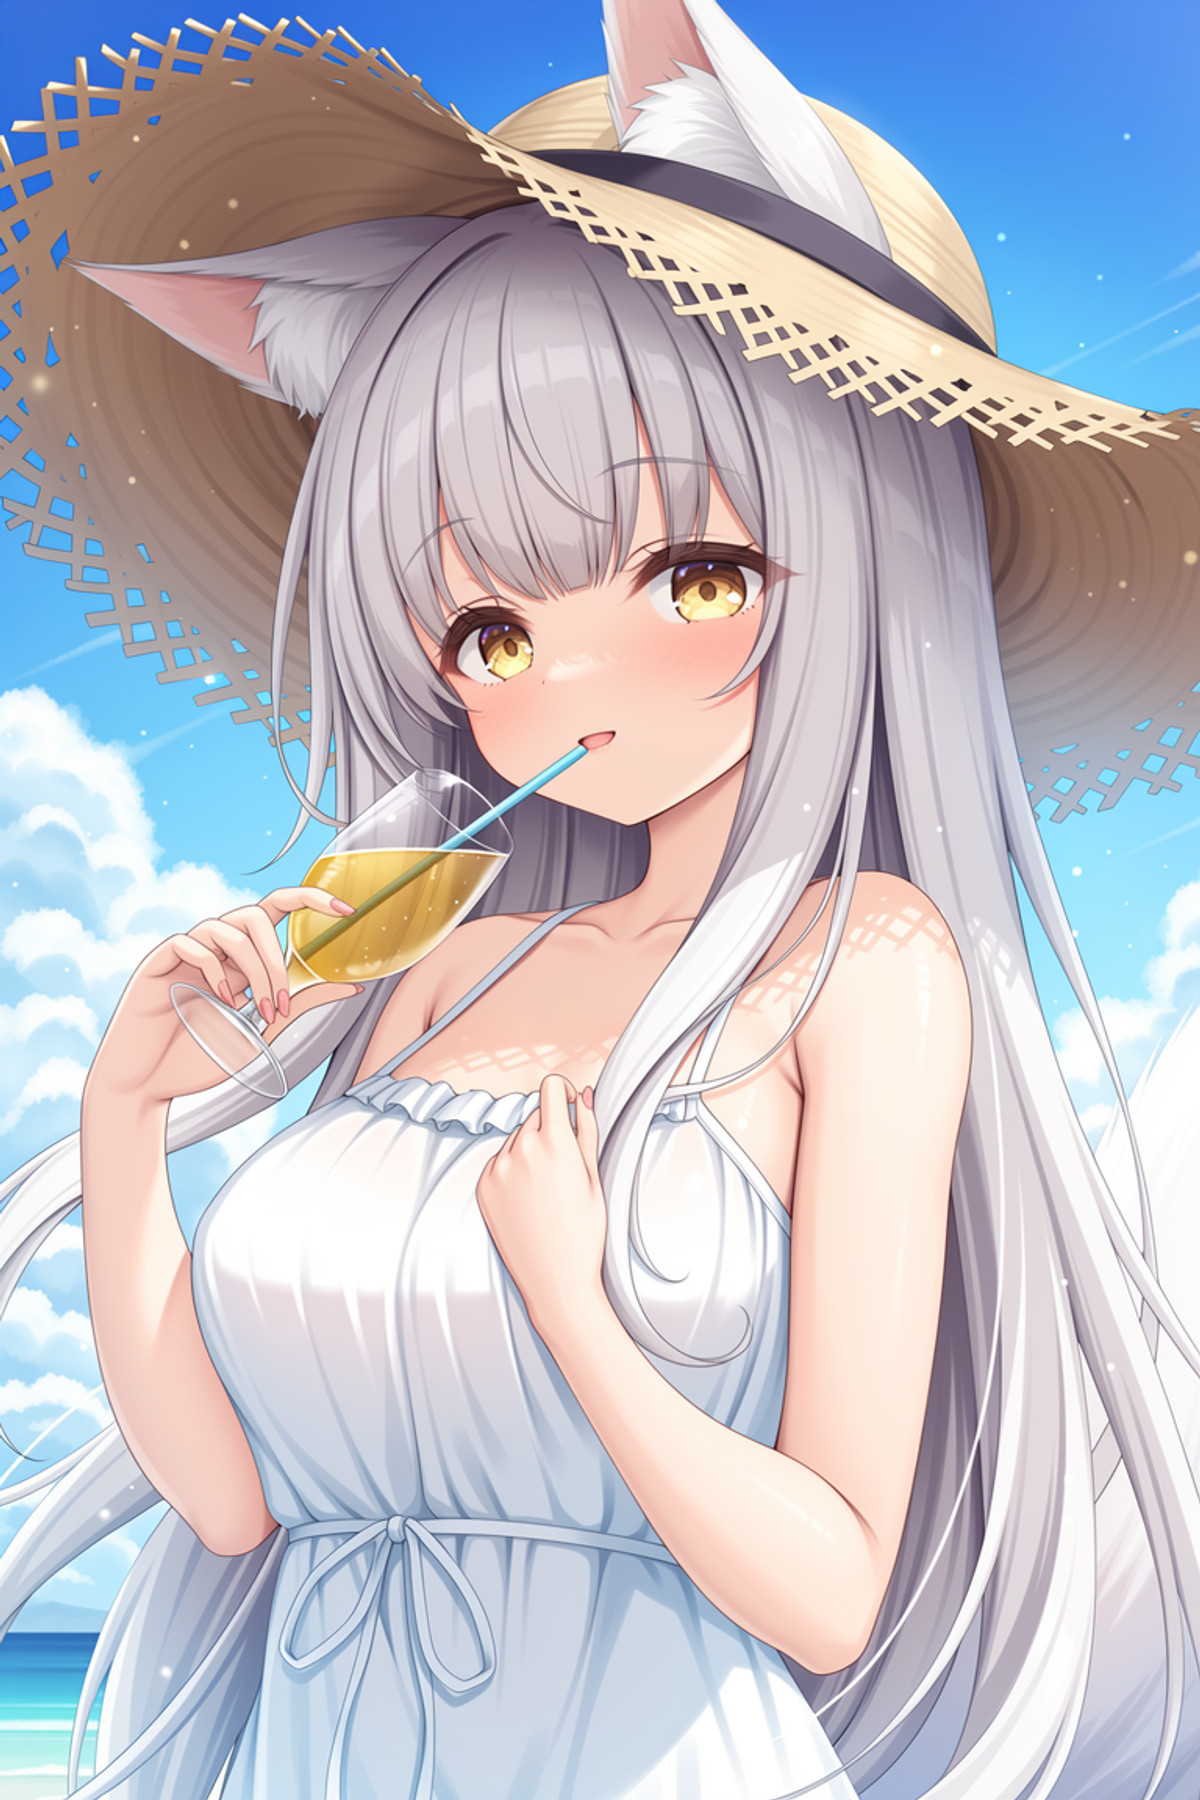
- Artist Style | Mikagami Mamizu | 水鏡まみず · base — LoRA: The MOSS Base version of the anime style LoRA for artist Mikagami Mamizu, with another weight file for SFT use on the same page.
Data: Civitai public API (base model MOSS Image), inclusion window 11-17 08:31 → 11-17 21:01 (Beijing Time). Recommendation reasons have been reviewed by editors; download counts only represent attention.