Zhenzhen's AI Radar · MiniMax H3 · 2026-11-04 Morning Report
This issue features 12 new versions: Strongly Recommended 0 · Recommended 1 · Worth Watching 6 · Listed Only 5
Editor's Note This issue reviews 12 new H3 versions. Top pick: the Hybrid merged base model, which mixes FL2VA and Ref2VA by layer and then integrates them with DMAD and PDMD distillation. The author claims 8-step video generation without needing an acceleration LoRA, but there are only 1 visible examples and no sampler or workflow provided, so it is rated A. The B tier includes a character replacement workflow v2.0 that preserves the original video's motion and camera work, a corrugated cardboard handmade style ported from Krea 2, a video technical quality check tool for pre-release, and English voice LoRAs for Black Clover and two Japanese Persona character voices. The voice LoRAs were downgraded from automatic A to B due to the lack of strength parameters and voice actor rights concerns; the two Persona voices with few examples, two workflows v2.0 with one-sentence descriptions, and standard fictional character LoRAs are rated C.
Recommended (1)
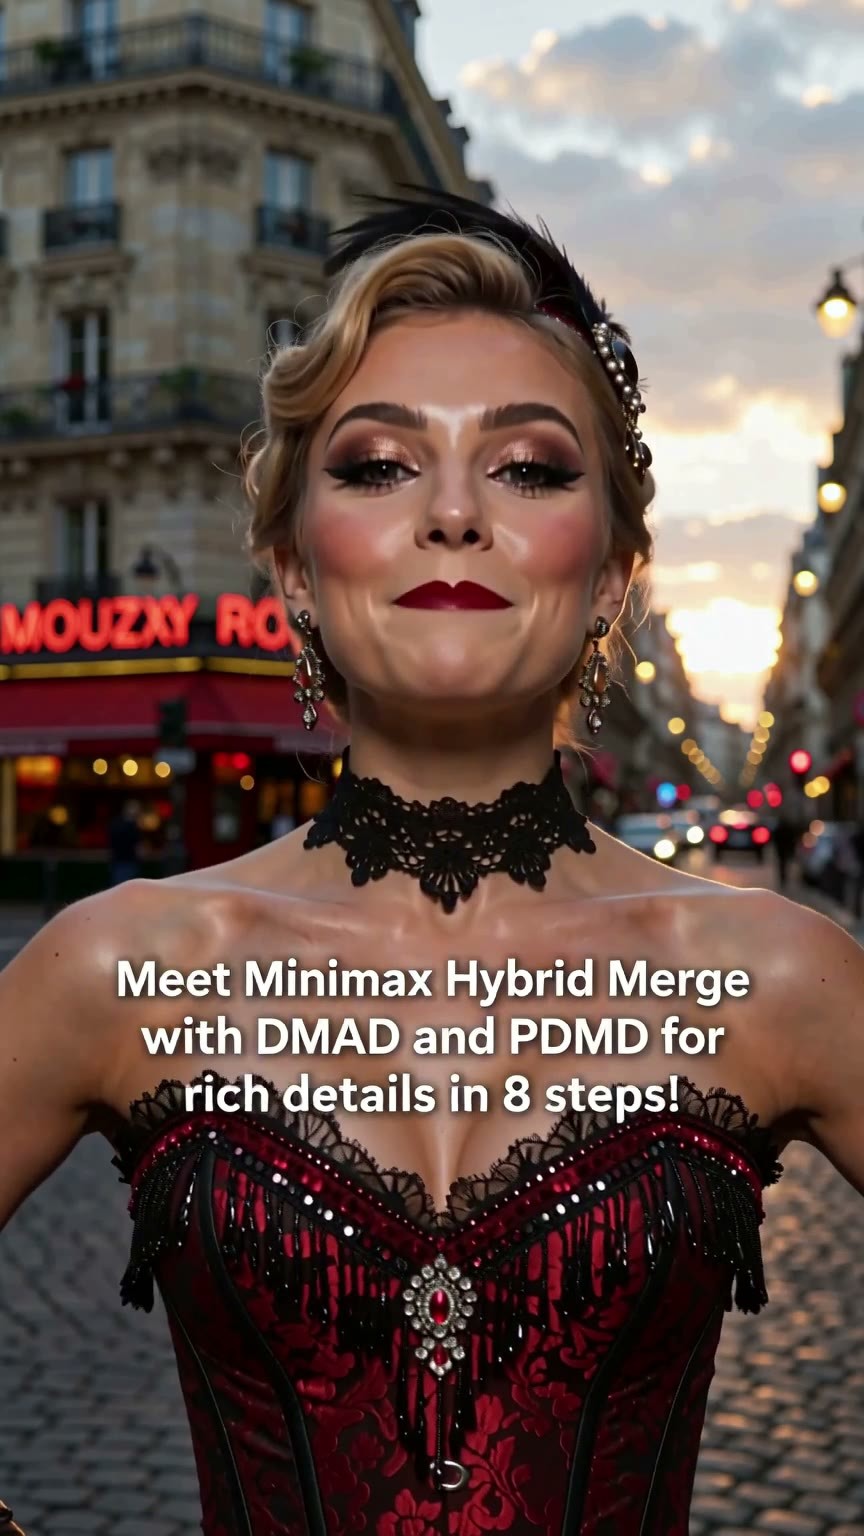
[A] MiniMax H3 Hybrid DMAD PDMD · MH3-Hybrid-DMAD-PDMD
Base Model / Checkpoint · New Model · Author 0l1v1aR0551 · Published 11-04 05:25 · Downloads 124
A merged INT8 base model that mixes H3's FL2VA and Ref2VA base models by layer and bakes in DMAD and PDMD distillation. The author claims 8-step video generation without needing an acceleration LoRA.
The only new base model in this group. It is recommended to compare it against the original Ref2VA using the same reference image, focusing on shadow details.
Images
Reasons for Recommendation
- New model: Addresses the weaknesses of the two original base models. The author claims FL2VA has good contrast and skin tones but poor multi-image/reference condition following, while Ref2VA follows references well but suffers from crushed blacks and dark color banding. This model uses FL2VA for layers 0–19, a cubic smoothing curve transition for layers 20–34, and Ref2VA for layers 35–49.
- Distillation is baked directly into the weights: 0.85 × DMAD (8-step critic distillation) + 0.333 × PDMD v6 (4-NFE flow distillation). The author claims no additional LoRAs are needed.
- Suitable for reference-image-to-video scenarios requiring character consistency while retaining the visual quality of FL2VA. It has undergone INT8 ConvRot pruning and quantization, with a single file size under 19 GB.
- Approximately 4 hours after release, it has 124 downloads and 15 likes (indicating attention only). It is free, and the license allows image generation, renting, selling, and selling fusions.
How to Use
- Download minimaxH3HybridDMAD_mh3HybridDMADPDMD.safetensors (INT8), replace the H3 base model load, set steps to 8, and do not load an acceleration LoRA.
- The author has not provided the sampler, CFG, resolution, or the node workflow for choosing between FL2VA and Ref2VA, nor is a workflow attached.
Risks and Limitations
- Only 1 video examples are visible (another 1 are hidden due to sensitivity). Claims of "lossless quality" and "deep reference following" are from the author, with no comparison examples provided.
- It is an INT8 quantized merged model, requiring ComfyUI nodes capable of loading this format. The author has not specified compatibility with original LoRAs.
- First version, with no update history. This entry has not been tested.
Worth Watching (6)
[B] Sadayo Kawakami Voice - Persona 5 - Audio Only [Minimax H3] · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-03 21:39 · Downloads 73
A Japanese voice LoRA for Sadayo Kawakami from Persona 5 Royal, affecting only the spoken voice generated by H3.
Images
Reasons for Recommendation
- New model: Trained on Japanese voice clips from the game. Action descriptions are in English, while dialogue is in Japanese. The author claims it can speak English lines, but they likely won't resemble the official English dub.
- Training dialogue focuses on everyday and caring tones (e.g., advising against dangerous activities, asking for help with chores). Emotional coverage includes shy, nervous, confident, relaxed, happy, excited, and intimate.
- Suitable for videos with audio requiring this character's Japanese voice. There are 3 example videos (another 1 are hidden), making it one of the entries with the most visible examples among this author's Persona voice LoRAs this issue.
- Free; 73 downloads (indicating attention only).
How to Use
- Load minimax-p5kawakami.safetensors in the H3 workflow and write dialogue in the training format: Kawakami says "<Japanese dialogue>".
- No trigger word registered; strength and steps are not provided by the author.
Risks and Limitations
- Audio only; character appearance must be configured separately. The data is entirely in Japanese, and the author is unsure of the quality when speaking English.
- Training data consists of official voice acting, involving voice actor rights. Although the license allows selling, commercial use requires self-assessment.
- 1 sensitive-level examples are hidden. Without seeing the examples, voice fidelity cannot be judged. This entry has not been tested.
[B] Fuuka Yamagishi Voice - Persona 3 - Audio Only [Minimax H3] · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-04 08:28 · Downloads 10
A Japanese voice LoRA for Fuuka Yamagishi from Persona 3 Reload, affecting only the spoken voice generated by H3.
Images
Reasons for Recommendation
- New model: Trained on Japanese voice clips from the Reload version. Descriptions are in English, while dialogue is in Japanese. The card provides three sample sentences (apologizing, noting that data functions are hard to read, and thanking the companion).
- Emotional coverage is consistent with the author's Persona series: shy, nervous, confident, relaxed, happy, excited, and intimate. The author claims it can speak English lines but does not guarantee similarity to the official English dub.
- Suitable for videos with audio requiring this character's Japanese voice. There are 3 example videos (another 1 are hidden).
- Released less than 1 hours ago with 10 downloads. It is free (indicating attention only).
How to Use
- Load minimax-p3fuuka.safetensors in the H3 workflow and write dialogue in the training format: Fuuka says "<Japanese dialogue>".
- No trigger word registered; strength and steps are not provided by the author.
Risks and Limitations
- Audio only; character appearance must be configured separately. The data is entirely in Japanese.
- Training data consists of official voice acting, involving voice actor rights. Although the license allows selling, commercial use requires self-assessment.
- Just released, with no user feedback yet. Without seeing the examples, voice fidelity cannot be judged. This entry has not been tested.
[B] Mimosa Vermillion Voice (Eng) - Black Clover - Audio Only [Minimax H3] (Commission) · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-03 21:24 · Downloads 65
An English voice LoRA for Mimosa Vermillion from Black Clover, affecting only the spoken voice generated by H3, not the visuals.
Images
Reasons for Recommendation
- New model: Trained on English voice clips from the anime. Annotations and transcriptions are in English, so writing English dialogue directly matches the training data. This differs from the author's other Persona voice LoRAs, which use Japanese voice acting.
- Training annotations include emotional adverbs, such as "Mimosa shyly asks" or "excitedly says," allowing tone specification in prompts using similar syntax. The author lists emotions including shy, tsundere, confident, relaxed, happy, and excited.
- Suitable for videos with audio requiring a fixed character voice, such as fan-made short dramas or character dialogue clips. This entry is a commissioned work.
- 2 example videos (another 1 are hidden). It is free, with 65 downloads (indicating attention only).
How to Use
- Load minimax-blackCloverMimosa.safetensors in the H3 workflow and write dialogue in the format: Mimosa says "..." or Mimosa shyly asks "...".
- No trigger word registered; strength and steps are not provided by the author.
Risks and Limitations
- Audio only; character appearance must be configured with a separate character LoRA or reference image.
- Training data consists of official voice acting, involving voice actor rights. Although the license allows selling, commercial use requires self-assessment.
- Without seeing the examples, voice fidelity cannot be judged. This entry has not been tested.
[B] mini max character replace - with turbo lora 4 steps · v2.0
Workflow · Version Update · Author kimimorgam · Published 11-04 07:09 · Downloads 16
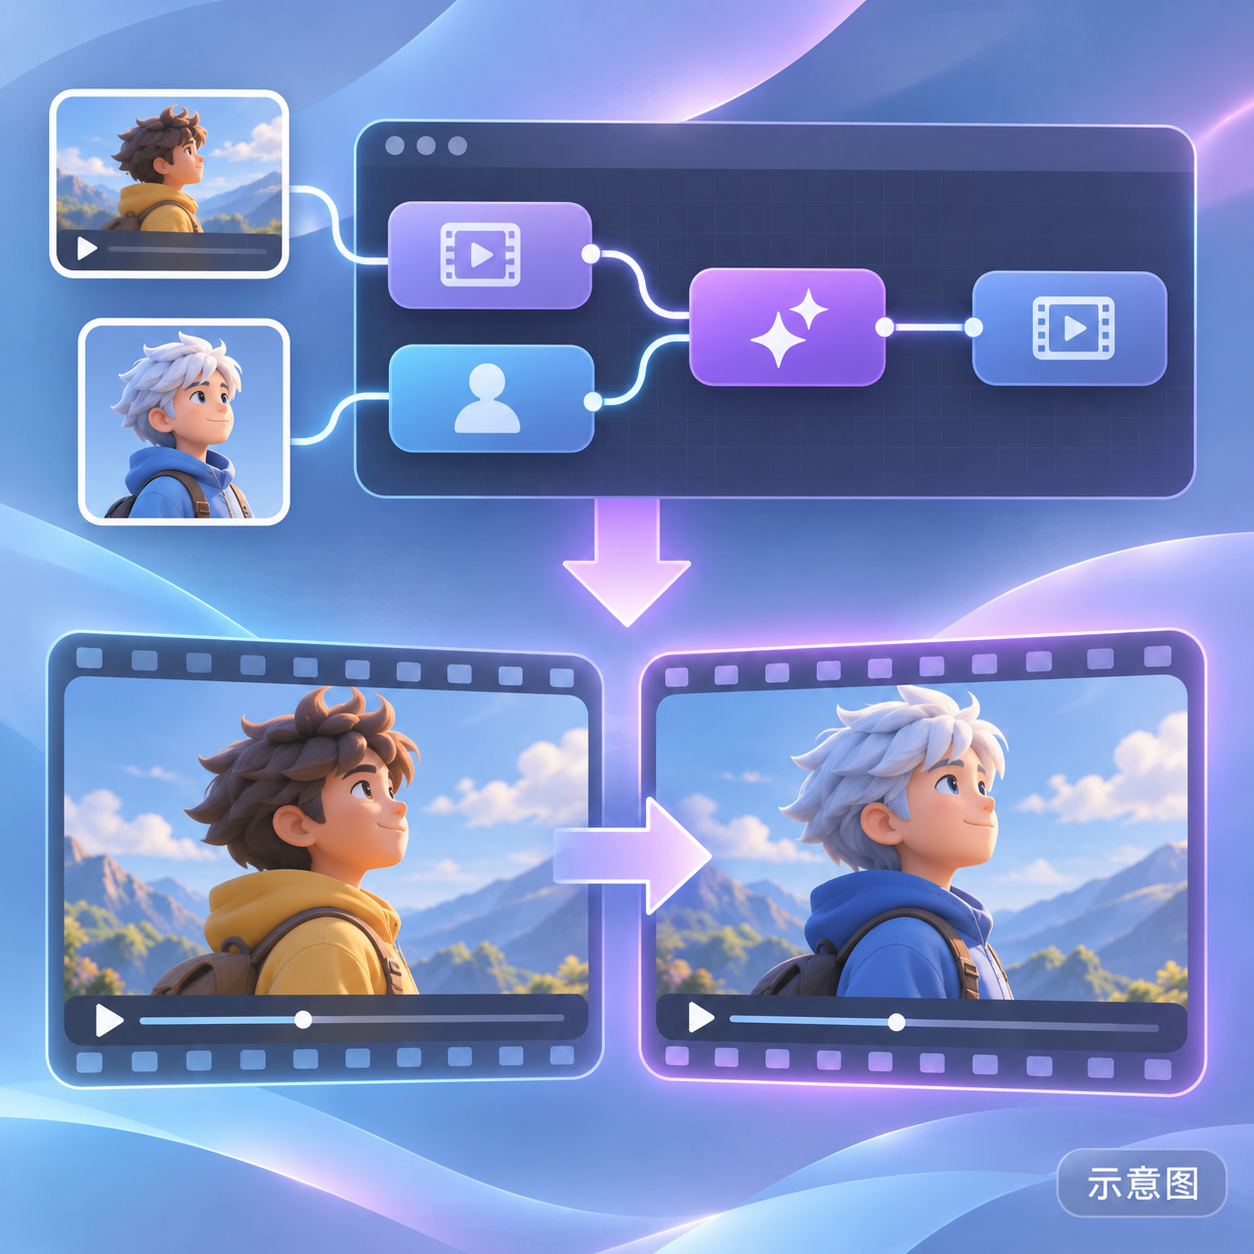
H3 character replacement workflow v2.0: Given a source video and a new character image, it preserves the original video's motion, camera work, and composition, replacing the person with the character from the reference image. It uses the Turbo LoRA to generate output in 4 steps.
Images
Reasons for Recommendation
- Version update: The update note for this version is just one sentence: "New workflow, works well," with no specific changes listed. The previous version 1.1 added long videos, long context, SAM masks, and segmentation by 5 seconds.
- Suitable for video character replacement: The source video provides motion, pose, camera work, rhythm, and scene composition, while the character image provides the new identity and appearance. The prompt is optional for fine-tuning.
- The author claims generation in 4 steps using the Turbo LoRA (pruned version), which is much faster than the standard 20-step workflow.
- Free; this version has 16 downloads, and the entire model has 2680 downloads (indicating attention only).
How to Use
- Import miniMaxCharacterReplace_v20.json (52 KB). Use MiniMax H3 Ref2VA Pruned INT8 ConvRot as the base model and MiniMax H3 Turbo for sampling, with 4 steps.
- Inputs: Source video + new character reference image + optional prompt. SAM mask nodes and models must be supplemented according to the workflow; the author has not provided a list.
Risks and Limitations
- No visible examples (1 are hidden), so the replacement effect cannot be seen.
- The author has not specified the exact changes in v2.0 compared to 1.1, and the model card body still contains descriptions from the old version.
- Replacing people in real-person videos involves portrait rights; material authorization must be confirmed independently. This entry has not been tested.
- The card image is an AI-generated diagram, not the actual model output. The author has not published any general-level examples.
[B] Corrugated Cardboard [Krea2] · Minimax v1.0
LoRA · Port · Author TeraWatt · Published 11-03 22:38 · Downloads 0 · Paid
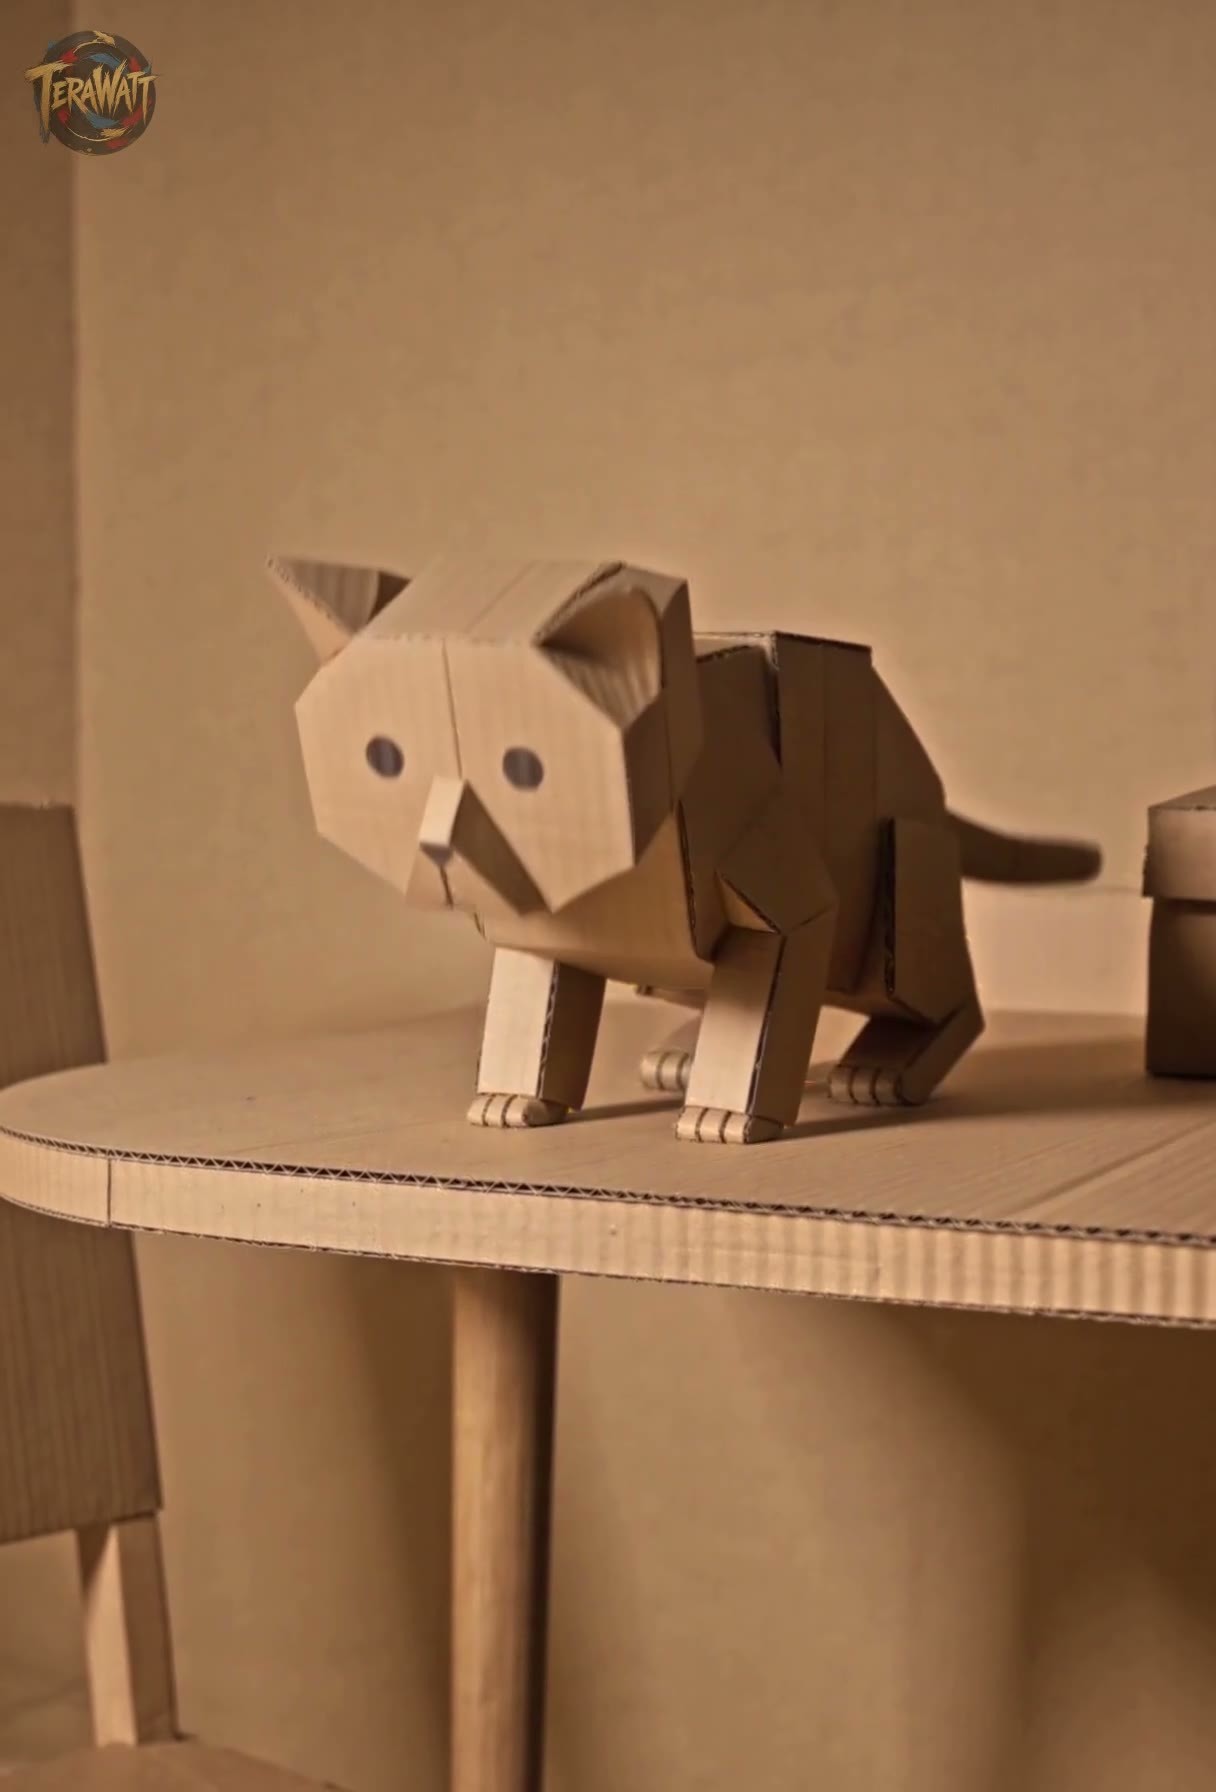
Corrugated Cardboard Handmade Style LoRA: Transforms images into handmade collage artworks made from corrugated cardboard, featuring cardboard textures, irregular edges, and a rough finish.
Images
Reasons to Recommend
- Port: The model of the same name was first released on Krea 2, and versions for H3 and MOSS Image were released on the same day; all three versions share the same trigger word. The card does not specify the training differences between the H3 version and the image version, only noting that the H3 examples were all generated using text-to-video.
- Unifies series style: The author gives examples of turning portraits, landscapes, and pets into a consistent set of cardboard handmade artworks, or maintaining a consistent texture across different characters and scenes.
- 11 example videos in the section (plus 1 hidden ones), allowing you to preview the style before deciding.
How to Use
- Load CorrugatedCardboard_TW_Minimax.safetensors in the H3 text-to-video workflow, and use the trigger word CorrugatedCardboard_TeraWatt in the prompt.
- The author did not provide strength or step count settings.
Risks and Limitations
- Requires payment (permanent paid access); this version has 0 downloads.
- The author only explained the text-to-video usage; applicability to image-to-video is not specified. This entry has not been tested.
Trigger Word: CorrugatedCardboard_TeraWatt
【B】Prophetero Final Check GLOBAL — Review Before You Release · v1.1
Workflow · New Model · Author Prophetero · Published 11-03 21:41 · Downloads 19
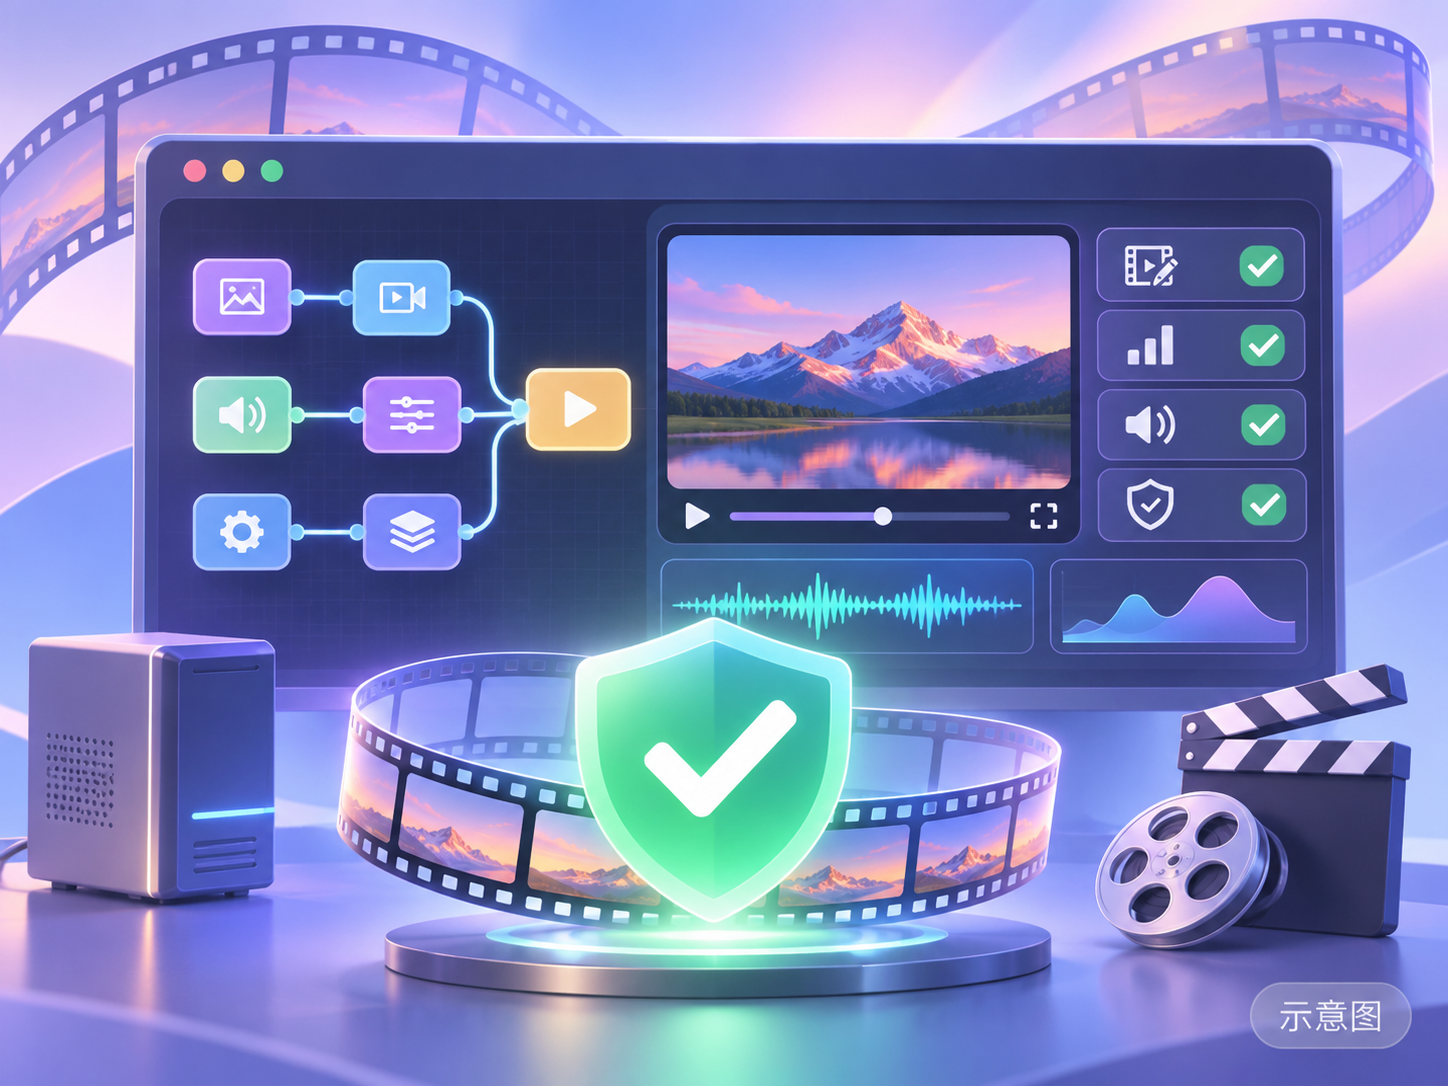
Prophetero Final Check Preview: Performs automatic technical checks on local videos before release, marking timestamps for black screens, nearly static frames, silence or missing audio tracks, and high audio peaks, followed by manual review of each item.
Images
Reasons to Recommend
- New Model: Serves the quality control stage before uploading finished videos; automatically checks for near-black frames, minimal inter-frame changes (which could be stuck frames or intentional static shots), silent segments and missing audio tracks, audio peaks near full scale, as well as technical information like resolution, frame rate, and encoding. It also identifies whether prompts/workflows are embedded in the video.
- Works in a separate browser tab: Add up to 8 segments at once, click timestamps to jump to issues, mark them as "To Review / Needs Fix / Intentional" and add notes. A JSON report can be downloaded; the exported report does not include full source paths or original prompts.
- Does not rely on any generative models; can check H3, LTX, and camera footage. Detection runs sequentially on CPU/FFmpeg and can be stopped midway. Selected segments can be passed to the author's Audio Fix, Loop Lab, and Take Compare tools.
- Free; 19 downloads (indicating popularity only).
How to Use
- Unzip propheteroFinalCheckGLOBAL_v11.zip (49 KB), stop the ComfyUI backend, then run START_HERE.cmd to install. After restarting, open Prophetero_Final_Check_GLOBAL.json and click Open Final Check to add videos.
- Requires aiohttp, PyAV, Pillow, and imageio-ffmpeg in the existing ComfyUI Python environment, which the author did not bundle. Detection duration and audio thresholds are adjustable, and individual checks can be disabled.
Risks and Limitations
- Preview version; only accepts SDR clips with vertical square pixels, 0.5–120 seconds long. The full card lists additional limits: 1–60 FPS, max 8 MP, single file 2 GiB / cumulative 6 GiB. It does not check for hand deformities, physics errors, or aesthetics; results are merely suggestions.
- The version notes for this release were mistakenly pasted from Take Compare's update content, and the version number format is inconsistent with the card. The installer is a Windows .cmd file.
- No visible examples (2 are hidden); the license does not allow derivatives, and the software itself cannot be resold. This entry has not been tested.
- The card image is an AI-generated diagram, not the actual model output; the author has no publicly available standard-level examples.
Included Only (5)
- Rise Kujikawa Voice - Persona 4 - Audio Only [Minimax H3] · Minimax H3 v1.0 — LoRA: A Japanese voice LoRA for Rise Kujikawa from Persona 4 Golden, affecting only the spoken voice generated by H3.
- MiniMax H3 Video to Video Workflow · v2.0 — Workflow: A v2.0 H3 video-to-video workflow. The author only provided the title and did not explain how it specifically modifies the original video.
- Diya Von Vergin · MiniMaxH3 — LoRA: A character LoRA for the author's original adult fictional character Diya Von Vergin (a high-fashion socialite from an Oxford family), in H3 video format.
- Tae Takemi Voice - Persona 5 - Audio Only [Minimax H3] · Minimax H3 v1.0 — LoRA: A Japanese voice LoRA for Tae Takemi from Persona 5 Royal, affecting only the spoken voice generated by H3.
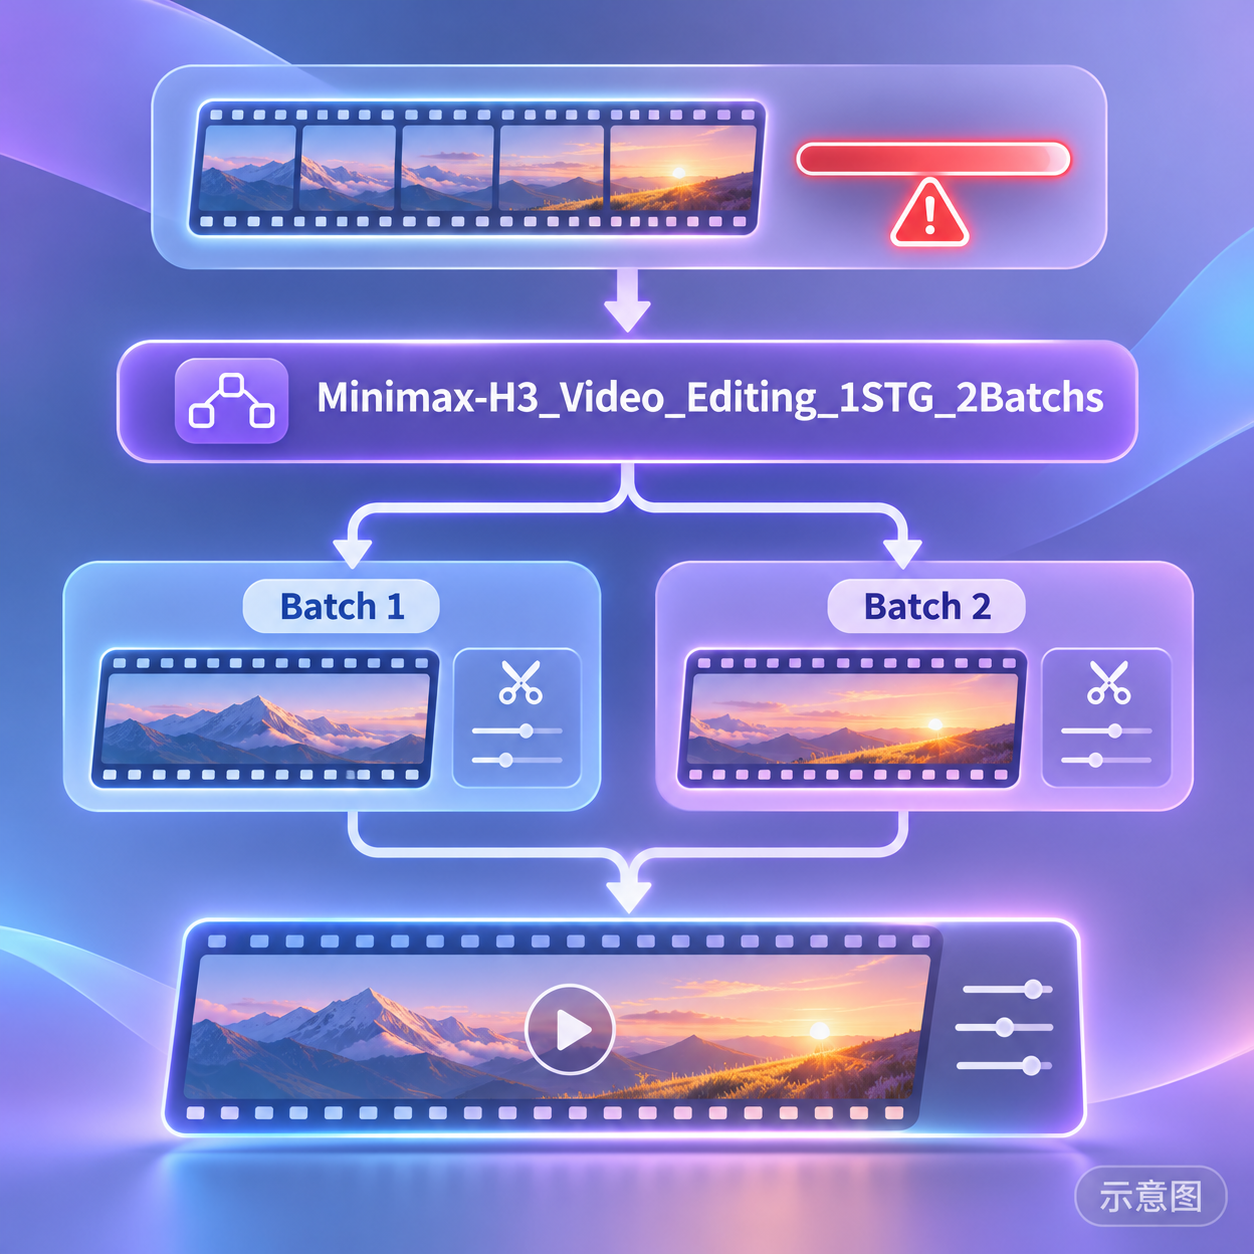
- Minimax-H3_Video_Editing_1STG_2Batchs · v2.0 — Workflow: H3 video editing workflow v2.0: Splits a shot into two batches for processing to avoid exceeding the maximum token count.
Data: Civitai Public API (Base Model MiniMax H3), inclusion window 11-03 20:31 → 11-04 09:01 (Beijing Time). Recommendation reasons have been editorially reviewed; download counts indicate popularity only.