Zhenzhen's AI Radar · MiniMax H3 · 2026-11-09 Morning Report
This issue features 15 new versions: Strongly Recommended 1 · Recommended 3 · Worth Watching 6 · Listed Only 5
Editor's Note This issue reviews 16 new H3 versions: 1 S, 3 A, 6 B, and 6 C. Top pick: the Lipsync / TLF2VA unified workflow, which lets a reference image lip-sync to existing songs or dialogue, or generates audio and video scene-by-scene from text and images, saving each segment so you can resume or restart from any specific segment. Other highlights: the Showrunner workflow for writing an entire multi-shot short film in a single node, the CROWN five-finger sword grip and two-person interlocking position swap LoRA, and the H3 image editing workflow that replaces 1–4 people in an image at once. The 1980s merged style LoRA and the Stone And Gold port lack trigger words and strength controls, so they are downgraded to B; DaSiWa's two new merged base models and the CROWN first-person LoRA lack visible examples, listed as B; three fictional character LoRAs, an image generation workflow that only provides video links, a MOSS workflow with a one-sentence description, and a paid face-slapping action LoRA are listed as C.
Strongly Recommended (1)
[S] MiniMaxH3 Lipsync / TLF2VA · Nova.1
Workflow · New Model · Author Rvage · Published 11-09 02:10 · Downloads 43
A unified H3 workflow: lets a reference image lip-sync to existing recordings such as songs or dialogue; it can also generate audio and video scene-by-scene using text, first frame, first and last frames, or reference images, saving each segment so you can resume, restart from a specific segment, or directly load old results to add subtitles.
The documentation is the most comprehensive this issue; the "resume / restart from segment N" saving mechanism is the most practical for long videos.
Images
Reasons for Recommendation
- New model (workflow); serves lip-sync MVs / dialogue videos, as well as text-to-video, image-to-video, and first/last frame multi-scene long videos
- Two paths share a single segmented rendering loop: one prompt per scene, cumulative preview, optional reference video analysis to automatically cut scenes and describe actions; YuE2 / MiniMax Music 3 background music, lyric extraction, and dynamic subtitles are optional groups
- Parameters are fully provided: native H3 presets Euler / simple, CFG 1, 8 steps; lip-sync preset 4 steps with two acceleration LoRAs enabled; the author states it was built under ComfyUI 0.42.1 and recommends testing with short clips first, disabling background music and subtitles, and generating only one segment at a time
- 1 video segments + 1 images with visible examples; published about 7 hours ago with 43 downloads (indicating attention only)
How to Use
- First install / update Eclipse Nova 1.0.30, SmartLLM Nova 1.1.12, and Smart Model Loader Nova 1.0.11, then import MMH3_Unified.json
- In START HERE, select Lip-sync or Native H3, and select the corresponding preset in Smart Model Loader and LoRA Stack (both must be switched manually); for lip-sync: enable Images and Audio override, load one image and one recording, select New run, Disk + Keep in output, and generate 1 segments at a time
- To resume: select the saved run and change to Resume saved run, set Restart part to 0; to restart from segment N: set Restart part to N and change the seed
Risks and Limitations
- High dependency: 3 Nova node packages, optional groups also require sol-attn and audio separation nodes; requires self-provided H3 diffusion model, Qwen3-VL 32B text encoder, video and audio VAE, and for lip-sync, a wav2vec2 audio encoder
- The base model saved by the native path is a community merged model, which needs to be replaced with your own H3 model and corresponding sampling settings
- The license does not allow commercial use, nor does it allow publishing derivative works; 1 examples are hidden due to rating
- The full documentation states that long scenes are split into multiple independent renders, with no guarantee of continuity in action and sound at the seams; this entry has not been run
Recommended (3)
[A] MiniMax Showrunner: Pro-Grade Video Director | Professional Video Director. · V2.5.2 Release Copy
Workflow · New Model · Author lonecatone23 · Published 11-09 04:29 · Downloads 67
An H3 multi-shot "director" workflow: write characters, scenes, and each shot in a single node, and one run generates all shots in sequence, combining them with sound and dialogue into a complete short film.
Images
Reasons for Recommendation
- New model (workflow); serves multi-shot narrative short films with fixed characters and scenes, usable for text-to-video and shots with fixed first/last frames
- Author claims: Keep rolling allows the next shot to continue from the previous shot's camera position, sound connects across shots, headshots + clothing images maintain character consistency, and 360 panoramic images allow changing camera angles in the same room without distortion; individual shots can be redone or have LoRAs attached separately, and the text and warnings actually sent to H3 for each shot are displayed before rendering
- The post-processing group handles frame interpolation to 48 fps, RTX deblurring and upscaling; node comments include multiple languages such as Chinese
- 1 video segments + 1 images with visible examples; published about 5 hours ago with 67 downloads and 12 likes (indicating attention only)
How to Use
- Import MMH3 Showrunner V2.5.2.json, install missing nodes from the author's GitHub (lonecatone23) ComfyUI_LC_AV_nodes; first run the built-in example story without changing anything, then go through Vision Assistant → Tour
- Prepare one headshot and one clothing image for each character, and one room image or 360 panoramic image for each scene; sampling steps and other parameters are not listed on the card by the author, see their User Guide
Risks and Limitations
- Relies on the author's own node package; the author states that listing on Comfy Manager may be delayed by about a day
- Claims of "seamless, no audio issues, consistent characters" are from the author; 1 examples are hidden behind age ratings
- The version name includes "Release Copy," and this is the only version on the page; its relationship to the author's previous versions is not explained
- The license only allows image generation and on-site rental; this entry has not been tested
【A】CROWN 3D Spatial Crossing & Five-Finger Hilt Grip Master | MiniMax H3 · v1.0 - VideoOnly r64
LoRA · New Model · Author: NineCrowns · Published 11-09 08:38 · Downloads 16
CROWN's weapon-action LoRA: Ensures characters grip the sword hilt below the guard with all five fingers, keeps the blade straight during swings, and prevents face or clothing swapping when two characters cross paths in foreground/background layers.
Complements the same author's previous special-effects combat LoRA: that one handles speed and effects, while this one handles sword gripping and two-character positioning.
Images
Reasons to Recommend
- New model; serves sword combat and two-character positioning shots; the author explicitly states support for Ref2VA / I2VA / T2VA
- Two trigger words handle separate tasks: crown_grip manages sword grip and blade rigidity, crown_spatial manages two-character X-shaped crossing swaps; crown_spatial_grip combines both
- Trained only on the video layer (Rank 64, Blocks 10–49); the author provided full test configurations: ref2va base model, 25 steps euler + beta, CFG 1.0, MiniMaxH3SigmaShift (shift_video 12.0, shift_audio 3.0)
- License allows commercial image generation and sales
How to Use
- Use prompts crown_grip / crown_spatial / crown_spatial_grip; apply this LoRA alone with strength 0.65–0.75 (author's example videos use 0.65); 25 steps euler + beta, CFG 1.0, shift_video 12.0, shift_audio 3.0
Risks and Limitations
- Only 1 video examples; claims of "100% retention of facial features and clothing, 0 face swapping" are from the author
- Published less than 1 hours ago, so download counts are not yet indicative; this entry has not been tested
Trigger Words: crown_spatial_grip, crown_grip, crown_spatial
【A】H3 Minimax Multi-character swap (1-4) · v1.3
Workflow · New Model · Author: yorgash · Published 11-09 06:07 · Downloads 50
A character replacement workflow for image editing using H3: Provide one original image and 1–4 character reference images to replace 1–4 people in the scene with the characters from the reference images in a single pass.
Images
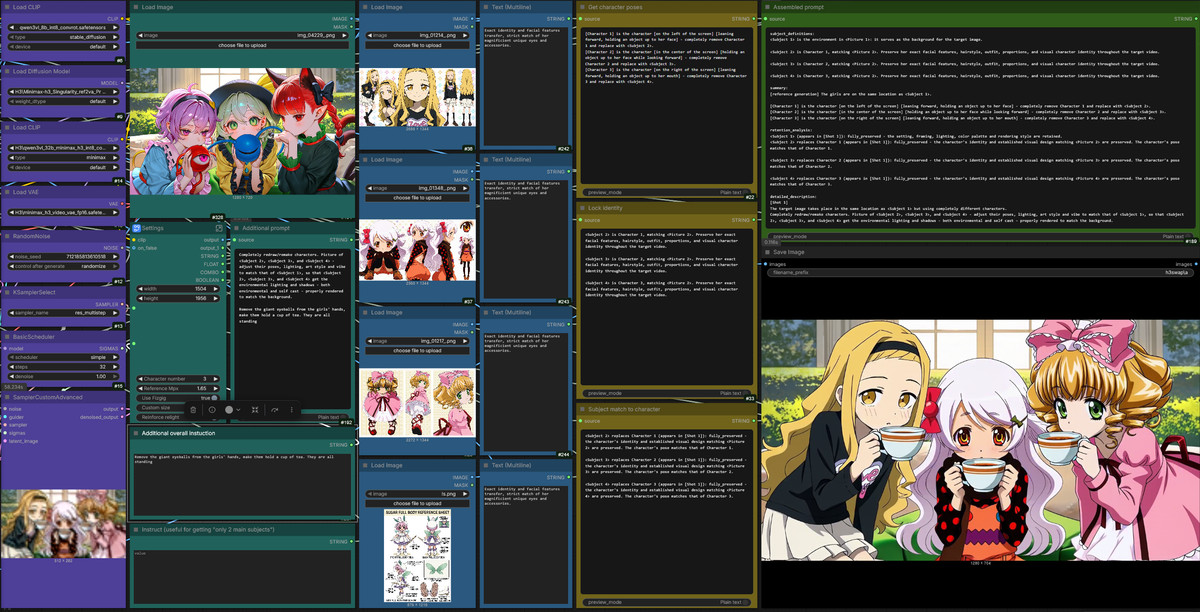
Reasons to Recommend
- New model (workflow); serves multi-person replacement in posters, group photos, and stills; input is a single image rather than a video
- Built-in "workflow nodes" automatically compare characters and assemble editing instructions; allows previewing which characters the model identified (typically left to right); final instructions are viewable
- Can add global instructions for restoration, pose changes, or background swaps; each character can have notes (e.g., shrink, age); Reinforce relight automatically adds a re-lighting instruction to blend characters into the scene
- 2 visible examples; published about 3 hours ago with 50 downloads (indicating attention only); license allows commercial use and sales
How to Use
- Import H3 Replacer v1.3.json; select the main text encoder, diffusion model, and auxiliary encoder for prompt assembly (author recommends qwen3vl_8b_int8_convrot)
- In Settings, set the number of characters 1–4 (required) and reference image size; without fizgig, it uses a single latent variable, which the author claims is about 20% faster, with diminishing speed gains as more characters are added; sampling steps and other parameters were not provided by the author
Risks and Limitations
- Character order recognition may vary; the author recommends checking the preview each time; character replacement involves portrait rights, so use only with authorized images
- Sampling parameters were not provided by the author; 1 examples are hidden behind age ratings; this entry has not been tested
Worth Watching (6)
【B】⛩️💀 DaSiWa MiniMax H3 💀⛩️ · DaSiWa GXS v5 Turbo
Base Model / Checkpoint · Version Update · Author: Darksidewalker · Published 11-09 06:46 · Downloads 146
DaSiWa GXS v5 Turbo Distilled Version: The same Graviton merge, now with Pika-H3-Flex-HD-Turbo added (REF2VA), generating output in 4 to 8 steps.
Image
Reasons for Recommendation
- Version Update: The update notes state that Pika-H3-Flex-HD-Turbo was added to the v4 × v5 × Singularity v2 merge; the previous version was the non-distilled GXS v5
- The author provided step tiers: 4 steps for quick preview (audio quality degrades), 6 steps for basic use, and 8 steps for quality; Turbo recommends euler / simple or LCM / simple, with Shift Video 6-12 and Shift Audio 3-5
- Also provides three quantizations: INT8, W4A8, and W6A8; this version has approximately 3 hours and 146 downloads (indicating popularity only)
How to Use
- Load as a replacement base model for H3 ref2va, using euler / simple or LCM / simple; start with 4 steps for preview, then use 8 steps for final output, with Shift Video 6-12 and Shift Audio 3-5
Risks and Limitations
- No visible examples (1 are hidden due to rating); the author explicitly states that audio quality degrades at 4 steps
- Large file size; the author claims to have obtained written authorization from MiniMax, but users are still bound by the H3 community license; this entry has not been tested
- The card image is an AI-generated diagram, not the actual model output; the author has no publicly available standard-rated examples
[B] ⛩️💀 DaSiWa MiniMax H3 💀⛩️ · DaSiWa GXS v5
Base Model / Checkpoint · Version Update · Author Darksidewalker · Published 11-09 06:46 · Downloads 189
New merged version of the DaSiWa H3 base model, GXS v5 (non-distilled): A complete ref2va weight set merging DaSiWa v4, v5, and Singularity v2.
Image
Reasons for Recommendation
- Version Update: The update notes state it is a Graviton merge of DaSiWa v4 × DaSiWa v5 × Singularity v2; the previous version was Hybrid v4
- The author provided recommended settings: res_multistep or euler / simple, Shift Video 10-12, Shift Audio 3-5, and 20-25 steps
- Provides three quantizations: INT8, W4A8, and W6A8; cumulative downloads on the same page are 71904, with this version having approximately 3 hours and 189 downloads (indicating popularity only)
How to Use
- Load as a replacement base model for H3 ref2va (select quantization from the download dropdown), using res_multistep / simple or euler / simple, 20-25 steps, Shift Video 10-12, and Shift Audio 3-5; see the author's workflow description for dependencies
Risks and Limitations
- No visible examples (1 are hidden due to rating); the author only states "see announcement" regarding changes after the merge
- Large file size; the author claims to have obtained written authorization from MiniMax, but users are still bound by the H3 community license and usage policy
- This entry has not been tested
- The card image is an AI-generated diagram, not the actual model output; the author has no publicly available standard-rated examples
[B] CROWN True First-Person Subjective POV & Interactive Gaze | MiniMax H3 · v2.0 - VideoOnly r64
LoRA · New Model · Author NineCrowns · Published 11-09 08:39 · Downloads 40
CROWN's first-person subjective POV LoRA: Allows "your own hands" to enter from the bottom edge of the frame to pour drinks or hold cups, and supports continuous low-angle and high-angle camera movements.
Image
Reasons for Recommendation
- New model; serves first-person vlogs and interactive romance subjective shots, with the author stating support for Ref2VA / I2VA / T2VA
- Addresses specific issues: H3 often has arms entering horizontally from the side or extra third hands appearing on characters; the author claims this LoRA ensures hands only enter from directly below the frame
- Trains only the video layer (Rank 64, Blocks 10–49); test configuration is complete: 25 steps euler + beta, CFG 1.0, shift_video 12.0, shift_audio 3.0
How to Use
- Use prompt trigger crown_pov, strength 0.80–0.85; 25 steps euler + beta, CFG 1.0, set shift_video 12.0 and shift_audio 3.0 in MiniMaxH3SigmaShift
Risks and Limitations
- The only example is hidden due to rating, so the effect cannot be seen; all functional descriptions are author claims
- The version name is v2.0, but the page only has this one version, with no v1 for comparison; this entry has not been tested
- The card image is an AI-generated diagram, not the actual model output; the author has no publicly available standard-rated examples
Trigger Words: crown_pov
【B】1980s Movies AiO LoRA · v1.0 - Minimax H3](https://civitai.com/models/3042369?modelVersionId=3458242)
LoRA · New Model · Author neph1 · Published 11-09 03:42 · Downloads 113
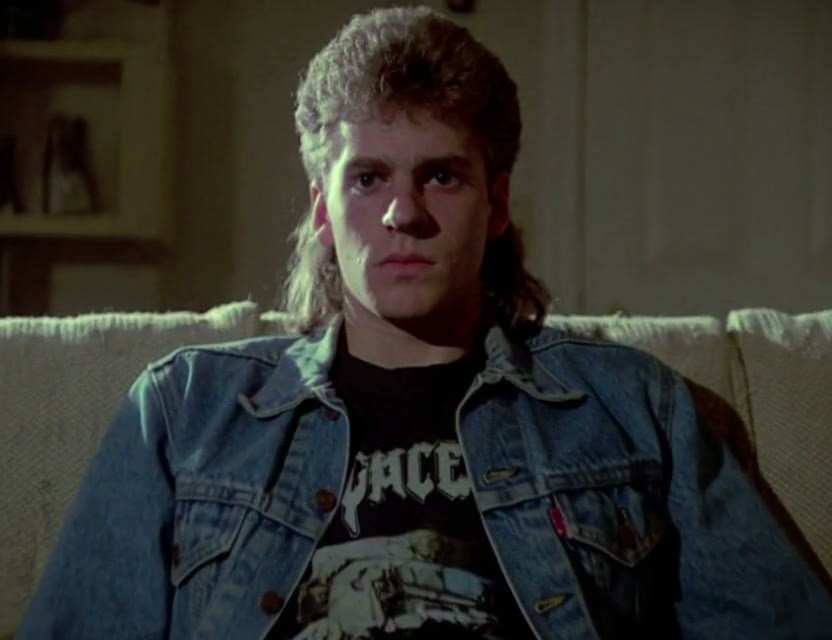
A style LoRA merging the author's three 1980s-era movie style H3 LoRAs using DARE TIES.
Image
Reasons for Recommendation
- New model; serves videos with an old movie / vintage TV texture, replacing three LoRAs with one file
- The author explains that individual concepts may be weaker than their original versions after merging, but claims the style is acceptable; examples intentionally use the same prompts and settings for easy comparison
- Approximately 6 hours after release, it has 113 downloads, ranking high in attention among non-sensitive entries this period (indicating popularity only); the license allows commercial use and sales
How to Use
- Load 1980s_aio_dare_ties_0_8.safetensors; the author did not provide trigger words or strength, refer to the example prompts
Risks and Limitations
- The description is very short, with no trigger words, strength, or sampling parameters
- Only 1 visible video segments, 2 are hidden due to rating; this entry has not been tested
[B] Stone And Gold · MiniMaxH3
LoRA · Port · Author MisterMR · Published 11-09 01:45 · Downloads 39
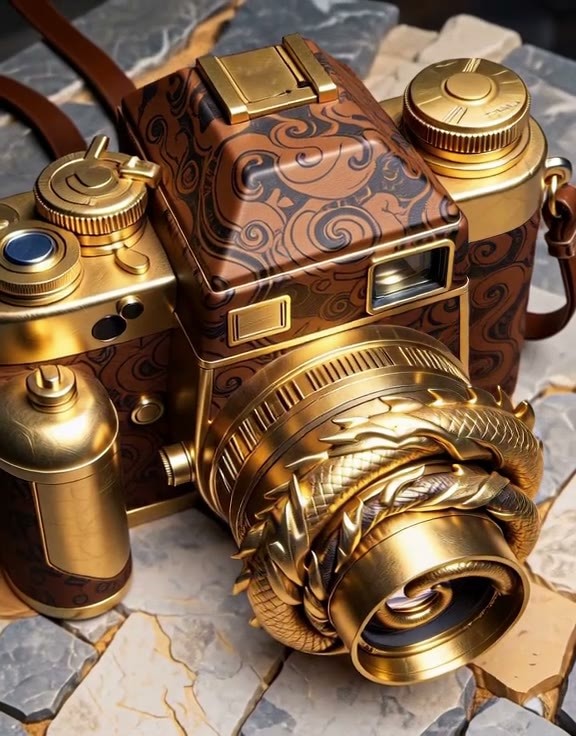
H3 port of the "Stone and Gold" material style LoRA: Renders objects in the scene with a texture of rough stone embedded with gold ornaments.
The original is an old LoRA from the SD 1.5 era, with adjectives copied directly from the description; the specific effect of the H3 version can only be judged by the examples.
Image
Reasons for Recommendation
- Port: The same page already has SD 1.5, SDXL 1.0, Krea 2, and ZImageTurbo versions; this is the newly added H3 video version; the description reuses the original promotional text without specifying differences in the H3 version
- Serves text-to-video / image-to-video with material stylization; cumulative downloads on the same page are 754 (indicating popularity of the original series only)
- Multiple visible video examples are available, allowing you to check the examples before deciding
How to Use
- Load MisterMR_StoneAndGold_MiniMaxH3.safetensors; the author did not provide trigger words, strength, or sampling parameters, refer to the examples
Risks and Limitations
- The description only contains style descriptions, with no usage parameters
- 8 examples are hidden due to rating; the license only allows on-site rental and does not allow derivatives; this entry has not been tested
[B] MInimax H3 Studio, Pixel Upscale Optimized for NVIDIA ONLY · v2.0
Workflow · New Model · Author hRUSTIN474 · Published 11-09 00:10 · Downloads 70
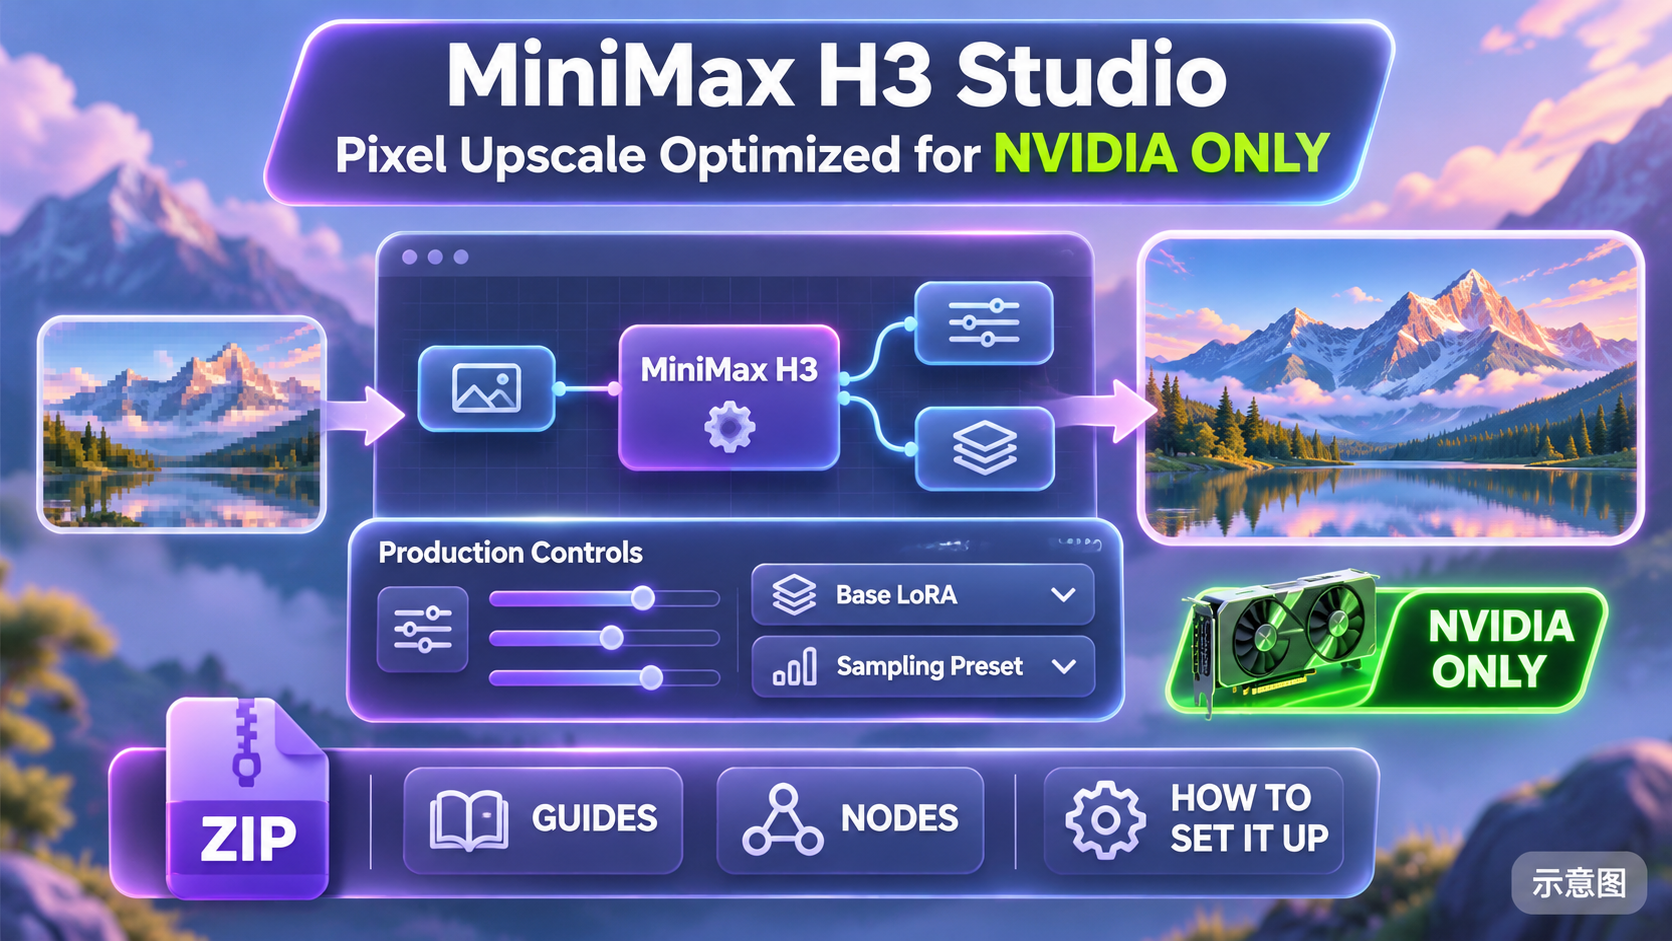
H3 multi-scene "Studio" workflow v2.0: Generates text-to-video / image-to-video / reference-image-to-video scene by scene according to a plan, then upscales and color-grades each segment individually to produce the final video; supports NVIDIA GPUs only.
Image
Reasons for Recommendation
- New model (workflow); the description for this version states that latent space upscaling was removed, switching to RelayVSR for individual segment upscaling
- Serves long video production: Each scene is a segment in the plan / edit node, allowing checks of duration, seed, and order; an optional local writer model can automatically rewrite prompts; dialogue must be labeled with language sentence by sentence (e.g., [English])
- The zip package includes a setup guide and nodes; there is also a sub-workflow for upscaling existing videos individually
How to Use
- After unzipping, install nodes according to the guide in the package; select the model, accompanying acceleration LoRA, and sampling preset in Production Controls, using default values for the first test; T2V does not use images, I2V uses the first frame image, and REF2V connects reference images and specifies what each image provides in the prompt
Risks and Limitations
- Supports NVIDIA only; the post-processing chain (RelayVSR, DLSS, RTX HDR) has many dependencies, and the full description states it performs HDR conversion rather than preserving original HDR
- All 2 examples are hidden due to rating, so the effect cannot be seen
- The version name is v2.0 but the zip file name is v1.0 Beta, with an additional txt file of unclear purpose; the license does not allow derivatives; this entry has not been tested
- The card image is an AI-generated diagram, not the actual model output; the author has no publicly available standard-rated examples
Included Only (5)
- Sophie Whitemoon · MiniMaxH3 — LoRA: A character LoRA for the fictional female character Sophie Whitemoon (steampunk archivist setting) for H3.
- MiniMax H3 image gen & Edit Workflow · v1.0 — Workflow: A compressed package containing an image generation and editing workflow for H3, with instructions consisting only of a YouTube tutorial link.
- Lillian Roccabruna · MiniMaxH3 — LoRA: A ported character LoRA for the fictional character Lillian Roccabruna (Florentine graphic designer setting) for H3.
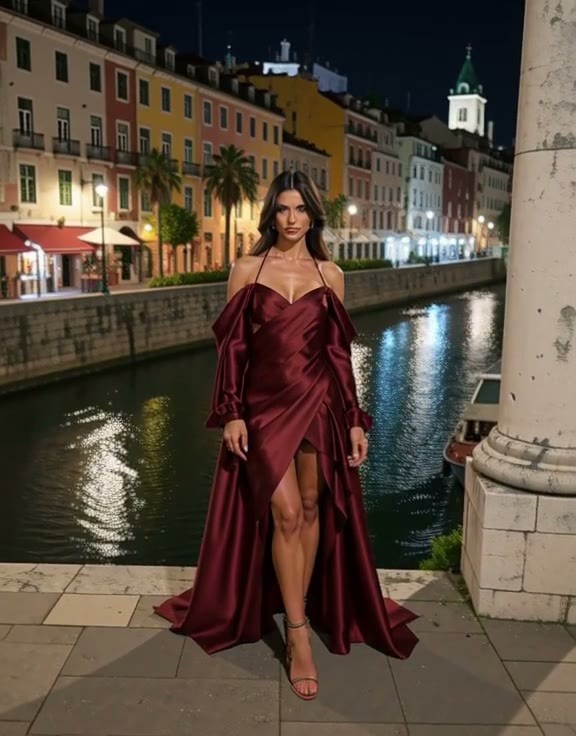
- Peyton Belwyn · MiniMaxH3 — LoRA: A ported character LoRA for the fictional character Peyton Belwyn (Bruges wine cellar owner setting) for H3.
- MOSS BBOX playround with Automatic box drawing using Qwen clips · v1.0 — Workflow: A "MOSS Layout Playground" workflow: uses the Qwen text encoder to automatically draw boxes, controlling the image layout based on these boxes.
Data: Civitai public API (base model MiniMax H3), collection window 11-08 20:31 → 11-09 09:18 (Beijing Time). Recommendations have been reviewed by editors; download counts only reflect attention levels.