Zhenzhen's AI Radar · MiniMax H3 · 2026-11-02 Morning Briefing
This issue features 22 new versions: Strongly Recommended 0 · Recommended 1 · Worth Watching 9 · Listed Only 12
Editor's Note This issue reviews 22 new H3 versions. Top pick: H3 Character Sheet Designer v1.3: an open-source ComfyUI node that uses a single character image and H3's reference image conditioning to generate static character sheets with up to 13 views. This version switches the template to the Pika Ref2VA LoRA and adds a 7 view preset with hands and feet on the right, upgrading from B to A. The Character Swap Workflow v2.0 adds secondary refinement, watercolor style LoRA trigger words, and intensity parity but is paid; both remain at B. AIKSK released 15 workflows at once; the cards contain structural descriptions, the author claims no inference verification was performed, and there are virtually no visible examples: the Sigma / OpenVDN / SelfLift sets for 4K generation, audio-driven digital humans and photo-dubbed characters, the standard version of video character swap, and video local repaint are rated B. The 768P duplicate version, the "face retouching/de-oiling" tool whose title and workflow do not match, the general SeedVR2 upscaler, and Hero Shot v2 whose description is copied from the previous version are downgraded to C. The "MiniMax version" of the Anima integrated workflow has no H3 description on the card and is downgraded from A to C.
Recommended (1)
[A] H3 Character Sheet Designer for ComfyUI - Image Generation · v1.3
Workflow · Version Update · Author ukr8b3g201 · Published 11-01 22:18 · Downloads 160
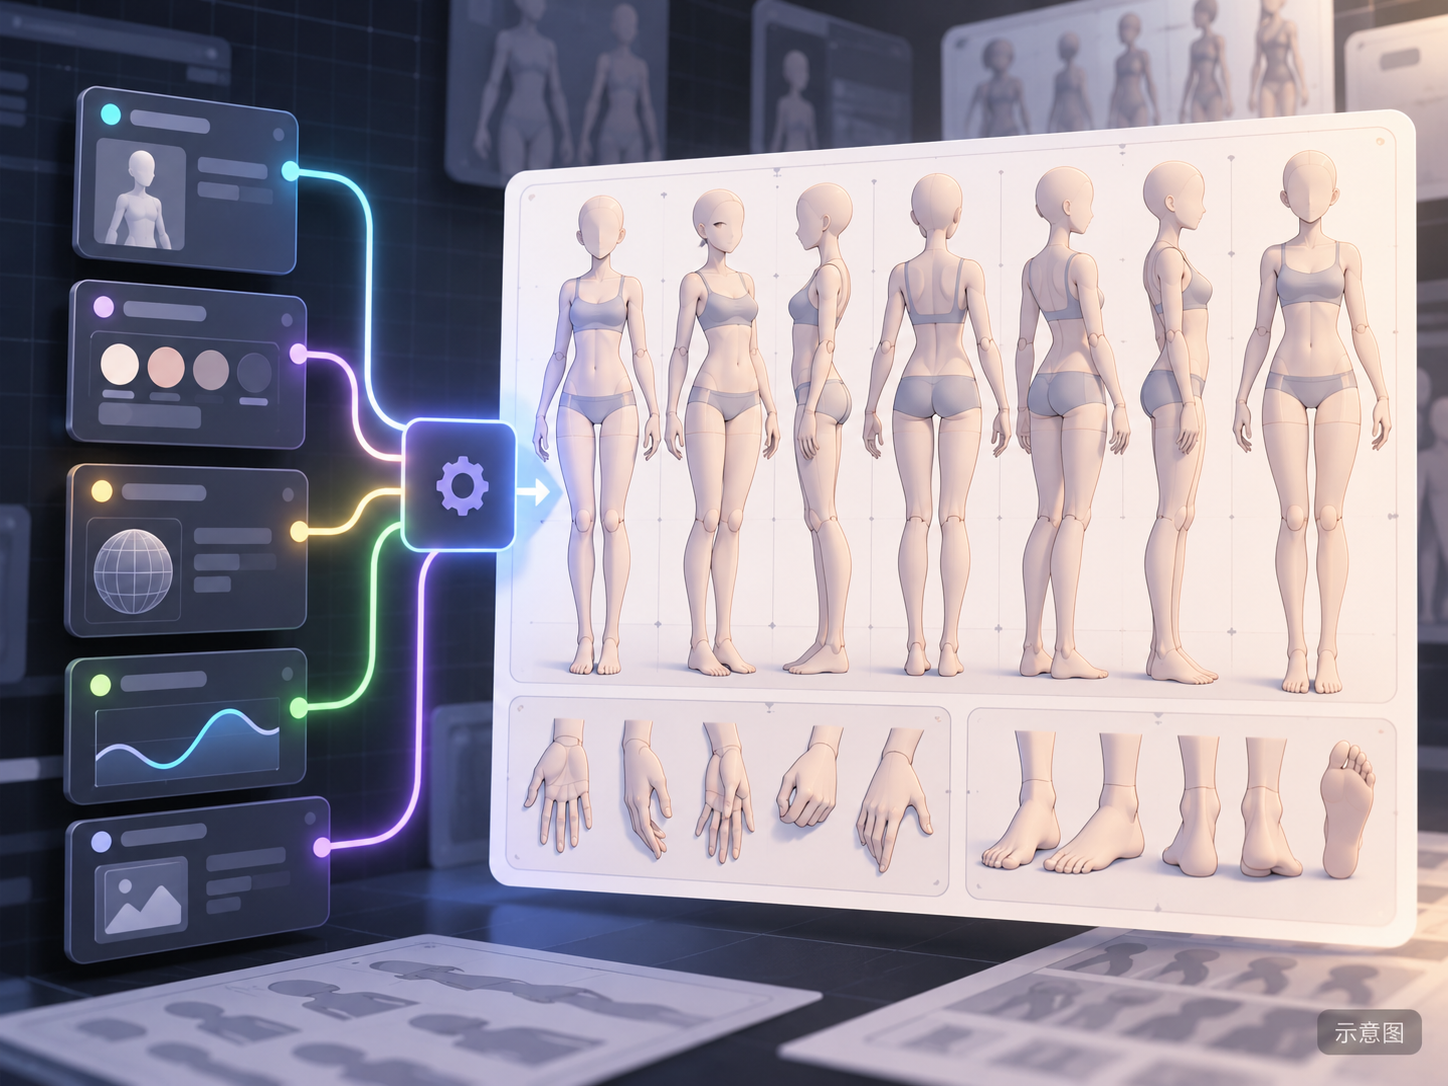
A ComfyUI custom node plus workflow: input a character image (optionally adding three reference images of the same character), and use H3's built-in reference image conditioning to generate multi-view character sheets (head, full body, front/back clothing, hands, shoes, up to 13 views) without needing a dedicated character sheet LoRA.
Upgraded from B to A: The node is open-source, installation steps and model lists are complete, v1.3 changes are specific, and limitations are stated frankly; points are deducted because this version has no visible examples.
Image
Reasons for Recommendation
- Version Update: The update notes section is empty, but the model card details v1.3 changes—the template switches to the Pika H3 Flex Ref2VA LoRA; a new MOSS-style preset is added, where the 7 view version places hands and feet on the right; the reference line layout shares a single set for on/off states with smaller margins and larger full-body frames; the interface is cleaner, with minor adjustments to clothing and 13 view prompts
- Serves the need to create character sheets for use as H3 reference images for video generation, maintaining character consistency; the author frankly states in the model card and GitHub README that v1.3 is only a minor update, and that clothing and full 13 views have not shown significant improvement, with potential residual human body artifacts or missing views
- Free, code is open-source on GitHub, license allows selling; this version has 160 downloads, the entire model has accumulated 2707 downloads and 111 likes (representing attention only)
How to Use
- Git clone the author's H3-Character-Sheet-Designer repository into ComfyUI/custom_nodes, restart, and load the v1.3 workflow from h3CharacterSheetDesigner_v13.zip (the package also retains the v1.2.2 workflow); the template also requires rgthree-comfy
- Place models according to the table on the card: use DaSiWa Hybrid V4 INT8 or official H3 Ref2VA INT8 for the diffusion model, H3 Qwen3-VL INT8 (or NVFP4 AWQ) for the text encoder, INT8 or FP16 for the video VAE, enable the Pika Ref2VA LoRA and disable the FL2VA LoRA; select 'minimax' for the CLIP loader type
- Check the desired views, adjust output size, and optionally add English part prompts to describe clothing details; the author suggests disabling 'Use Layout Image' initially and enabling it only when composition guidance is needed; use the template's default sampling parameters, as no separate settings are provided on the card
Risks and Limitations
- The author did not write update notes; v1.3 changes are described in the model card body
- This version has no visible examples (2 sensitive levels hidden); the GitHub README only contains interface screenshots, and no finished character sheets were seen for this entry
- The author states that automatic sizing increases rendering time and VRAM usage; output is static character sheets, not video; this entry was not run
- The card image is an AI-generated illustration, not the model's actual output; the author has no publicly available standard-level examples
Worth Watching (9)
[B] Minimax H3 IMG2IMG Character Swap Workflow · v2.0
Workflow · Version Update · Author MrAzor · Published 11-02 01:18 · Downloads 92
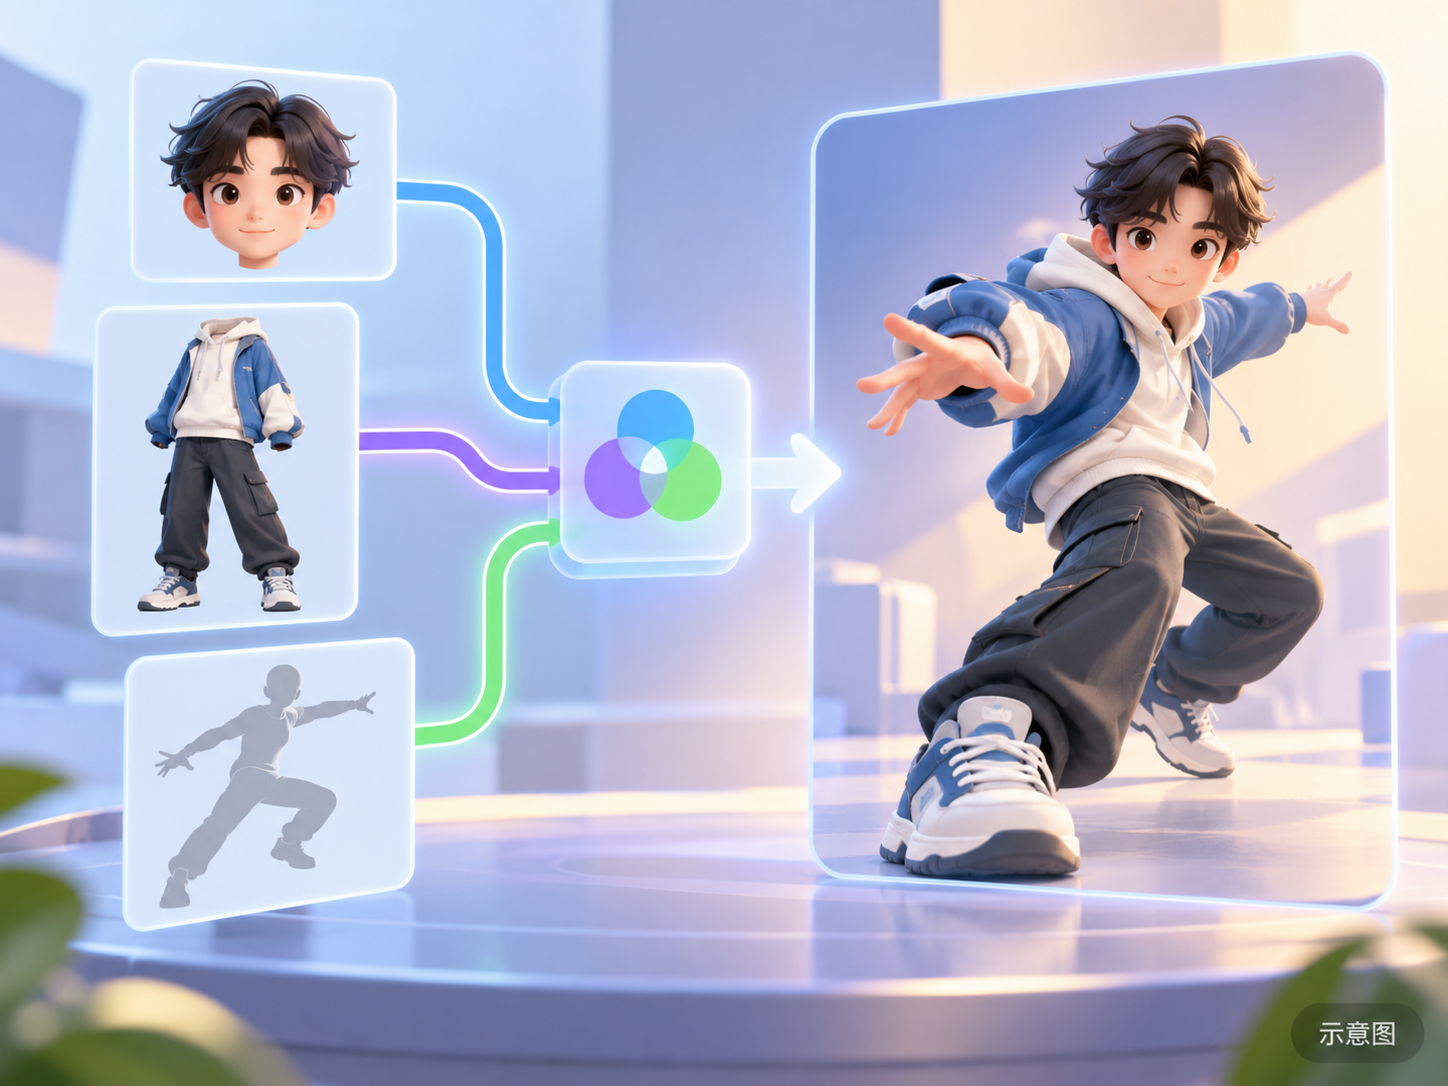
A ComfyUI workflow for "character swapping" using H3 and the NRDX Character Swap LoRA: it composites head and body reference images into a character reference, then generates a static image based on another pose image; v2.0 adds optional secondary refinement.
Image
[B] Watercolor [Minimax / MOSS / Krea2 / SD]🎨 🖌️ 🖼️ · Minimax v1.0
LoRA · Port · Author TeraWatt · Published 11-02 06:36 · Downloads 2 · Paid
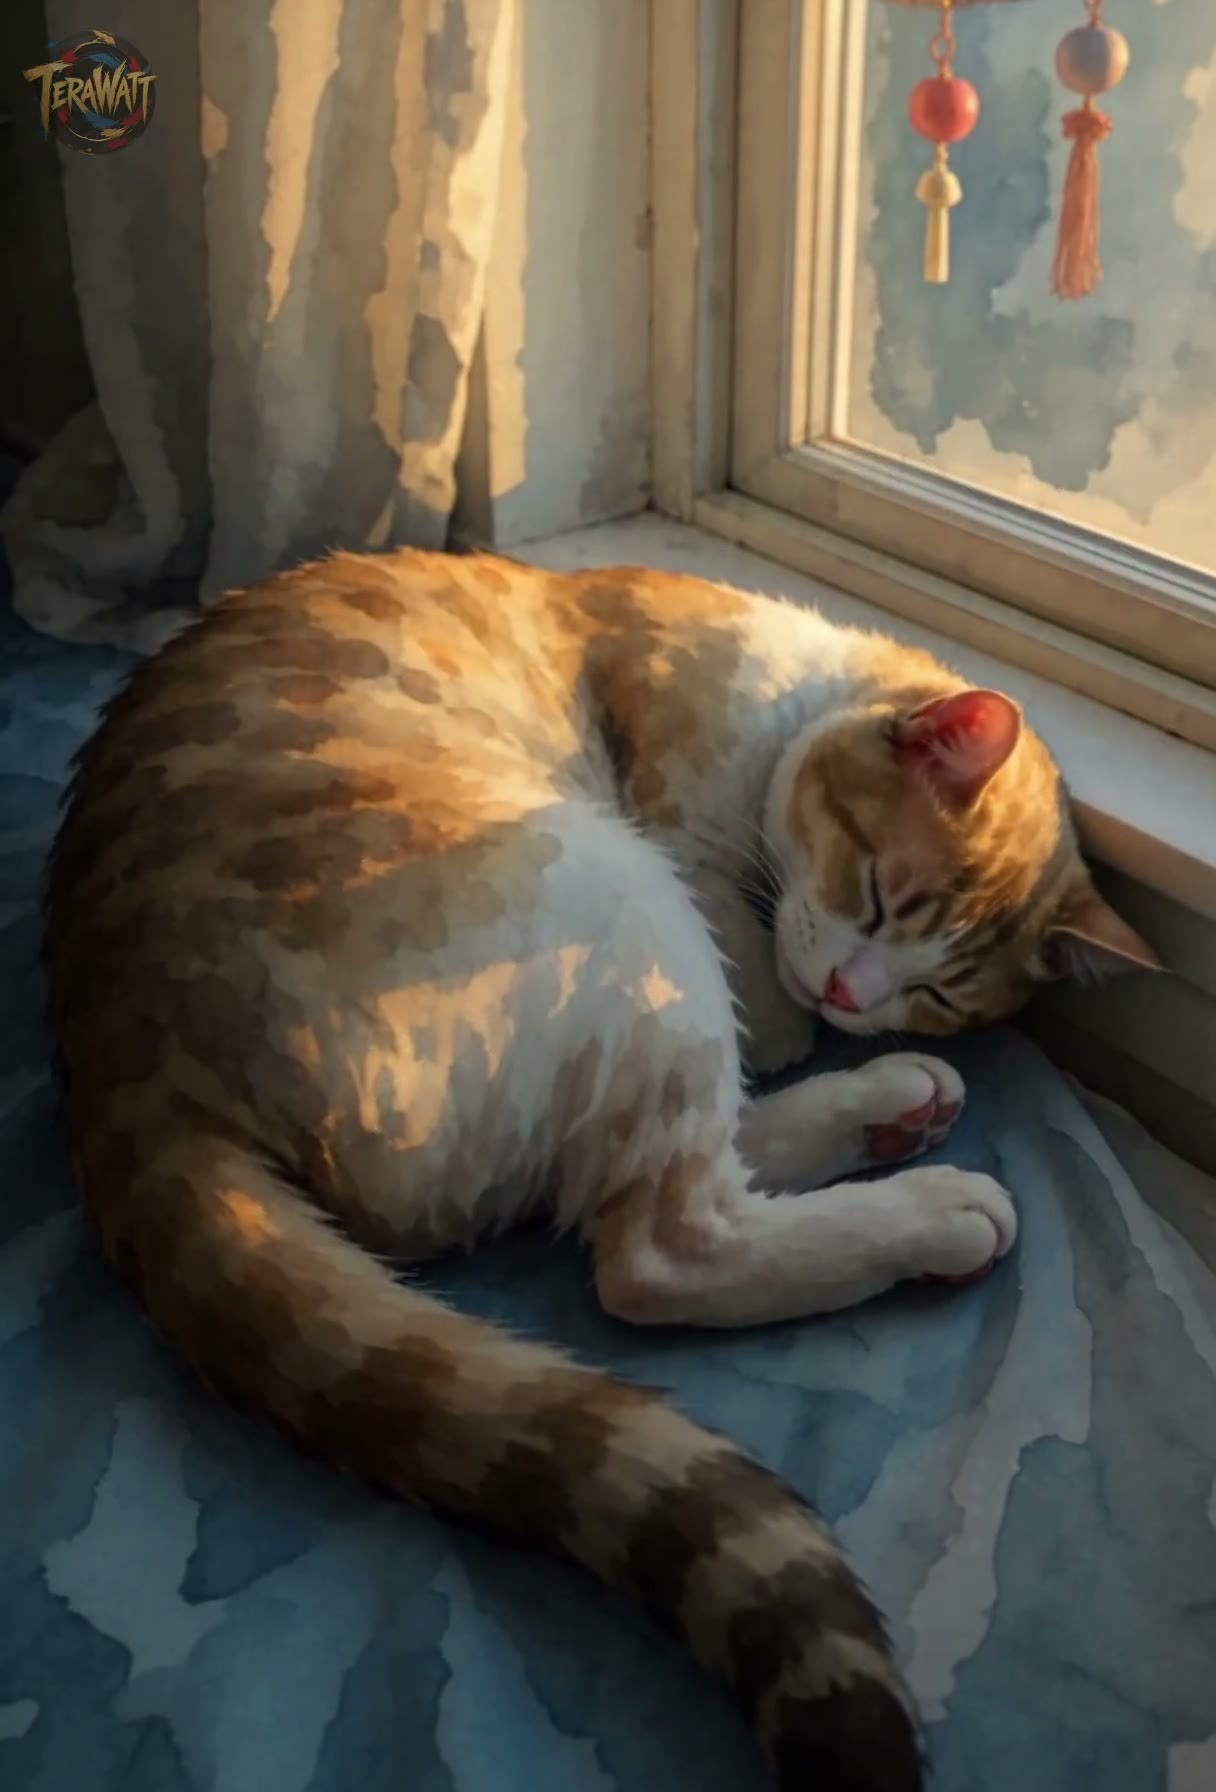
The H3 version of the watercolor style LoRA: it gives text-to-video outputs a watercolor texture; the author claims it can be used to unify portraits, landscapes, pets, etc., into a consistent series.
Image
[B] MiniMax H3 Sigma Enhanced Dual-Pass Universal Video Generation 4K · v1.0
Workflow · New Model · Author AIKSK · Published 11-02 04:39 · Downloads 33
AIKSK's H3 universal video generation workflow (Sigma Enhanced Dual-Pass · 4K target): generates video from a single reference image, first sampling at low resolution, then using learned latent space upscaling by 2x for refinement, followed by SeedVR2 upscaling to 2160 and 2x frame interpolation after decoding.
Image
[B] MiniMax H3 OpenVDN DMD8 Universal Video Generation 4K · v1.0
Workflow · New Model · Author AIKSK · Published 11-02 04:38 · Downloads 19
AIKSK's H3 universal video workflow (OpenVDN DMD8 · 4K target): generates video using a first frame and a last frame, with sampling handled by OpenVDN's vdn-minimax-h3 distillation scheme (stage_dmd_8nfe), followed by SeedVR2 upscaling to 2160, scaling to 3840×2160, and 2x frame interpolation after decoding.
Image
[B] MiniMax H3 SelfLift Universal Video Generation 4K · v1.0
Workflow · New Model · Author AIKSK · Published 11-02 04:39 · Downloads 22
AIKSK's H3 universal video workflow (SelfLift · 4K target): generates video from a single reference image; the SelfLift node internally generates at low resolution first, then refines using learned latent space upscaling, followed by SeedVR2 upscaling to 2160, scaling to 3840×2160, and 2x frame interpolation.
Image
[B] 10Eros Beta5 SelfLift Audio Digital Human Fine-tuning Workflow · v1.0
Workflow · New Model · Author AIKSK · Published 11-02 04:23 · Downloads 21
A workflow for driving H3 digital human videos with user-provided audio: two images provide the character and environment/composition respectively; a segment of source audio is cropped, encoded, and spliced into the reference conditions, then generated using two-stage SelfLift sampling, with the final video directly synced to the original audio.
Image
[B] MiniMax H3 ControlNet Union Local Repaint Workflow · v1.0
Workflow · New Model · Author AIKSK · Published 11-02 01:03 · Downloads 28
AIKSK's H3 video local repaint workflow: uses SeC to segment the regions to be modified in the source video, then feeds the expanded mask and source video into Fun ControlNet Union to repaint only the masked areas.
Image
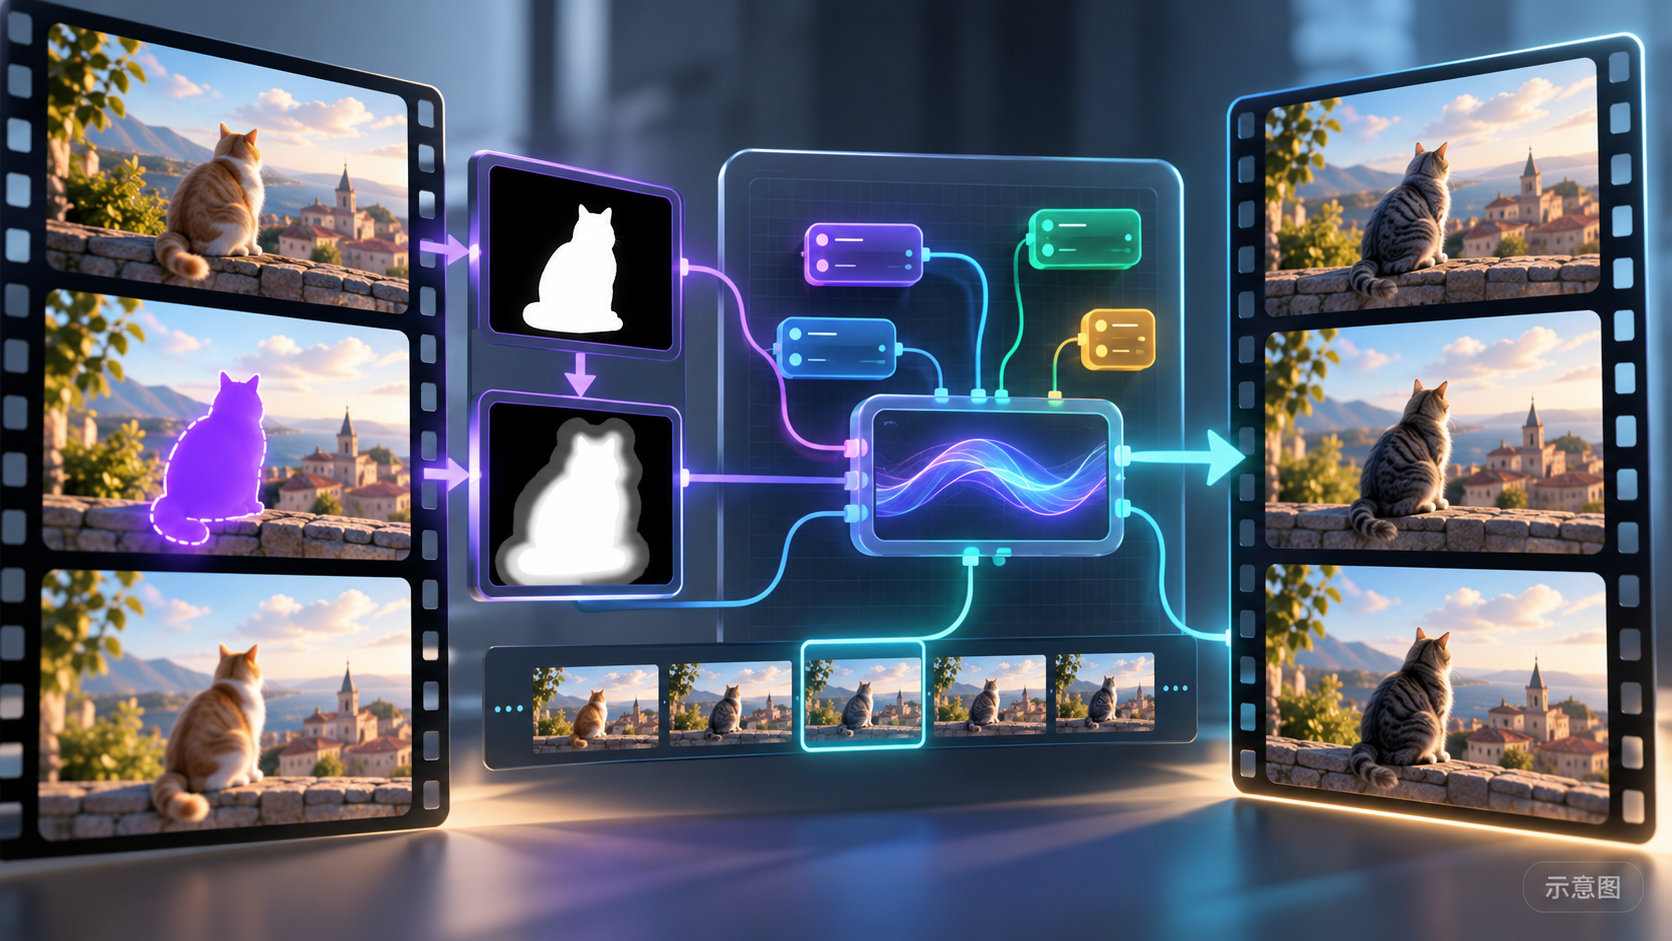
[B] MiniMax H3 Role Swap Reference Edit — Standard Version · v1.0
Workflow · New Model · Author AIKSK · Published 11-02 01:57 · Downloads 33
AIKSK's H3 video character swap workflow "Standard Version": uses SeC to segment the person in the source video, mixes RGB and depth into a reference, then repaints the character based on appearance reference images while injecting the source video's audio encoding to preserve the original voice.
Image
[B] MiniMax H3 General Video Generation with Audio-Driven Avatar (VDN 12-Step) · v1.0
Workflow · New Model · Author AIKSK · Published 11-02 01:02 · Downloads 27
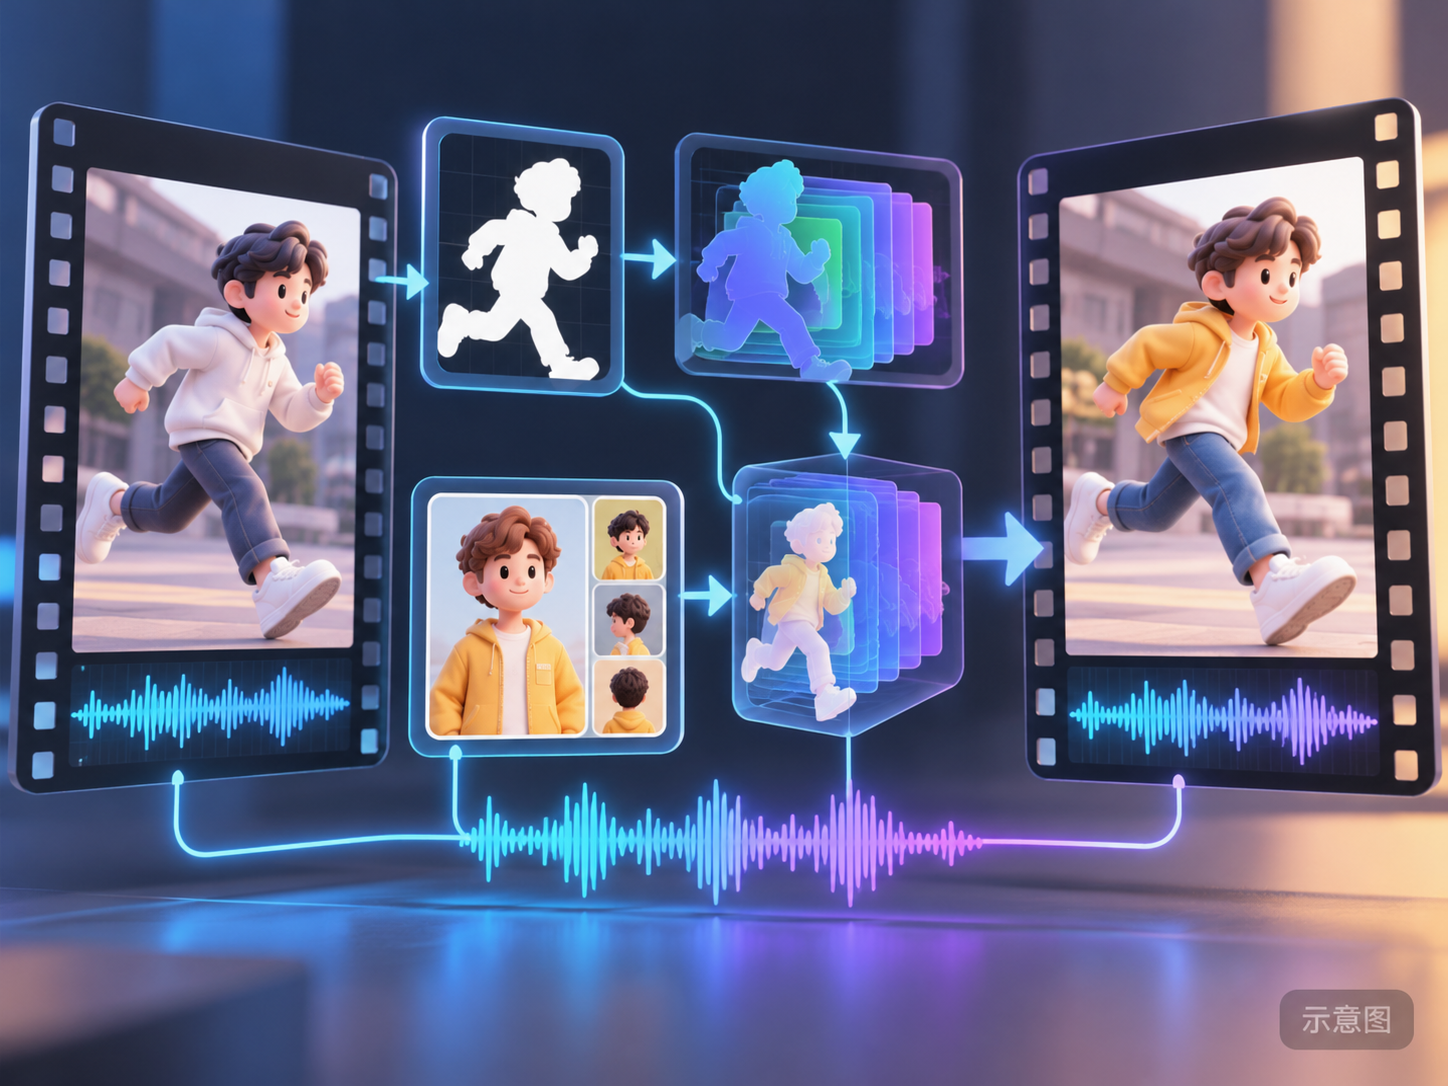
AIKSK's H3 audio-driven character workflow: One reference image plus an uploaded audio clip, separating the voice to encode it into audio latents injected into generation, and outputting with the selected original audio attached.
Image
Included Only (12)
- All in one Anima Made Easy Brain Edition: Complete ComfyUI Workflow with Wan Video or Minimax H3. Or Both! · v4.0 MiniMax edition — Workflow: A comprehensive ComfyUI workflow primarily focused on Anima image generation (sketch-to-HD, face/hand correction, upscaling, inpainting, four-person zone prompting, Wan 2.2 image-to-video). This version is named "MiniMax edition," but the model card does not specify how the H3 component is integrated.
- 10Eros Beta5 + FL2VA/Ref2VA Face Touch-up and Oil Removal Second-Pass Workflow · v1.0 — Workflow: Titled "Face touch-up and oil removal second-pass refinement," this 10Eros + H3 workflow's structural description on the card shows it as a two-stage refinement process involving video generation from three reference images plus 1.5x learning-based upscaling, without a dedicated face cropping and pasting-back process.
- Universal Video Upscaling SeedVR2 with DLSS Frame Interpolation · v1.0 — Workflow: A post-processing-only video workflow: reads existing video, upscales to 2160 using SeedVR2 (3B FP8), then performs 2x frame interpolation, preserving original audio and frame rate; does not involve H3 generation.
- MiniMax H3 OpenVDN DMD8 Universal Video Generation 768P · v1.0 — Workflow: The "768P" version of the OpenVDN DMD8 first-and-last-frame workflow: same VDN distilled sampling and 2x frame interpolation, but without SeedVR2 upscaling and the 4K scaling tail segment.
- MiniMax H3 SelfLift Universal Video Generation 768P · v1.0 — Workflow: The "768P" version of the SelfLift universal video workflow: same SelfLift two-stage sampling, 4-step accelerated LoRA, and 2x frame interpolation, without SeedVR2 and the 4K scaling tail segment.
- MiniMax H3 Role Swap Reference Edit — Silent Version · v1.0 — Workflow: AIKSK's H3 video character swap workflow "Silent Version": uses SeC to segment characters in the source video, mixes RGB and depth maps into references, then redraws the character based on one appearance reference image; this version bypasses the manual audio injection node.
- MiniMax H3 VDN Hero Shot · v2 — 12NFE 40-node export — Workflow: An H3 VDN second-pass refinement workflow for product showcase hero shots: reads source video and reference images, first performs 8-NFE low-resolution VDN, learning-based latent space upscaling by 2x, then 4-NFE refinement, outputting an approximately 1920×1088, 24 fps video with sound.
- MiniMax H3 ControlNet Union 2.0 Video Control with Audio Avatar (VDN 12-Step) · v1.0 — Workflow: AIKSK's H3 workflow: uses depth maps from the source video (DepthAnythingV2) for structural control, while encoding the voice into audio latents for injection, generating video that follows the motion and audio.
- MiniMax H3 ControlNet Union 2.0 Video Control and Inpaint (VDN 12-Step) · v1.0 — Workflow: AIKSK's H3 structural control workflow: the source video is preprocessed with Scribble line art and fed into Fun ControlNet Union to control the visual structure, with audio natively generated by H3.
- MiniMax-H3 All-in-One Video Workflow V5 - Latent Chunked Second-Sampling Edition · v1.0 — Workflow: Astral Starburst's H3 all-in-one video generation workflow V5 "Latent Chunked Second-Sampling Edition": combines text-to-video, image-to-video, and reference-to-video, automatically writes prompts, locks audio; the author claims it fixes distant face collapse, oily faces, and high-motion ghosting.
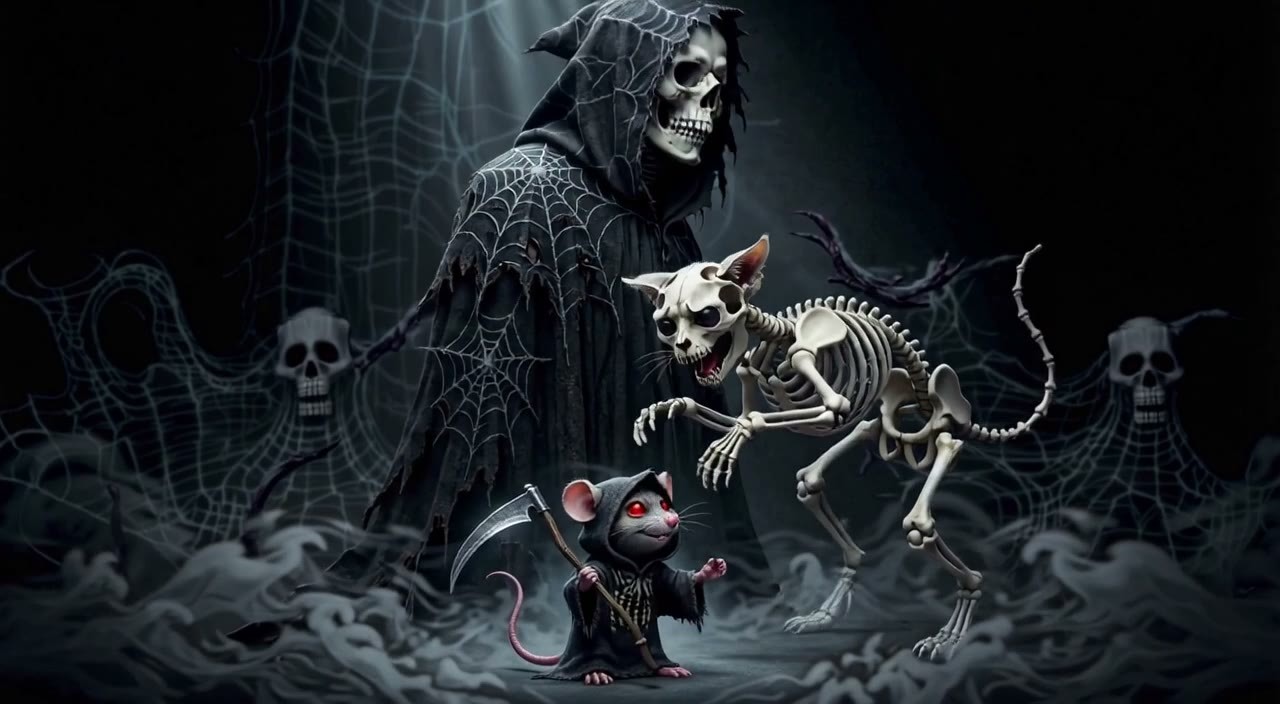
- LORU & RIBS: SALT FLAT SYMPHONY · v1 — LoRA: An H3 LoRA for a pair of fictional skeleton characters: Loru, a grim reaper wearing a tattered haute couture cloak and cargo pants, and Ribs, a skeleton cat wearing a hoodie and sneakers; the author claims it excels at contrasting bone and fabric textures and lighting in scenes like salt flats and neon.
- MiniMax-H3 V5 All-in-One Video Workflow - SelfLift Two-Pass Edition · v1.0 — Workflow: Astral Starburst's H3 all-in-one video generation workflow V5 "SelfLift Two-Pass Edition": combines text-to-video, image-to-video, and reference-to-video, uses official skills to automatically write prompts and lock audio, low VRAM second-pass sampling; the author claims it improves distant face collapse.
Data: Civitai public API (base model MiniMax H3), inclusion window 11-01 20:31 → 11-02 10:45 (Beijing Time). Recommendations are editorially reviewed; download counts only reflect attention.