Zhenzhen's AI Radar · MiniMax H3 · 2026-11-11 Morning Brief
This issue features 23 new versions: Strongly Recommended 2 · Recommended 3 · Worth Watching 9 · Included Only 9
Editor's Note This issue reviewed 23 new H3 versions, with 2 rated S, 3 rated A, 9 rated B, and 9 rated C. The top recommendation is AusBoss's H3 Image text-to-image + image editing workflow: generate 16 MP images with a single sentence or edit images using plain language, with support for up to seven reference images. The Fast mode uses pDMD to reduce steps from 6 to 2. Note that about half of the entries in this issue are H3 image versions ported to ComfyUI via 11-10, which only generate images, not videos. In the video category, the S-rated entries include the "friend's phone snapshot" style LoRA Friend's POV, while the smart glasses first-person LoRA and the Frieren: Beyond Journey's End art style LoRA are rated A. In the H3 Image quantization package, INT8 / INT4 variants with unclear documentation are downgraded to B / C, the voice LoRA is downgraded to B due to copyright issues, and the 5 original character LoRAs batch-ported by MisterMR are rated C due to missing trigger words and examples.
Strongly Recommended (2)
[S] MiniMax H3 Image Generate + Edit | 16 MP, 8 Pictures · v1.0
Workflow · New Model · Author AusBoss · Published 11-11 08:31 · Downloads 140
A ComfyUI text-to-image + image editing workflow for MiniMax H3 Image (the image version of H3): generate 16 MP images with a single sentence, or edit images using plain language. When editing, you can attach up to seven reference images and specify what to extract from each.
The first workflow since H3 Image launched that integrates generation, editing, multi-image reference, and upscaling, while also specifying the test version number. It serves as a suitable starting template for H3 Image.
Images
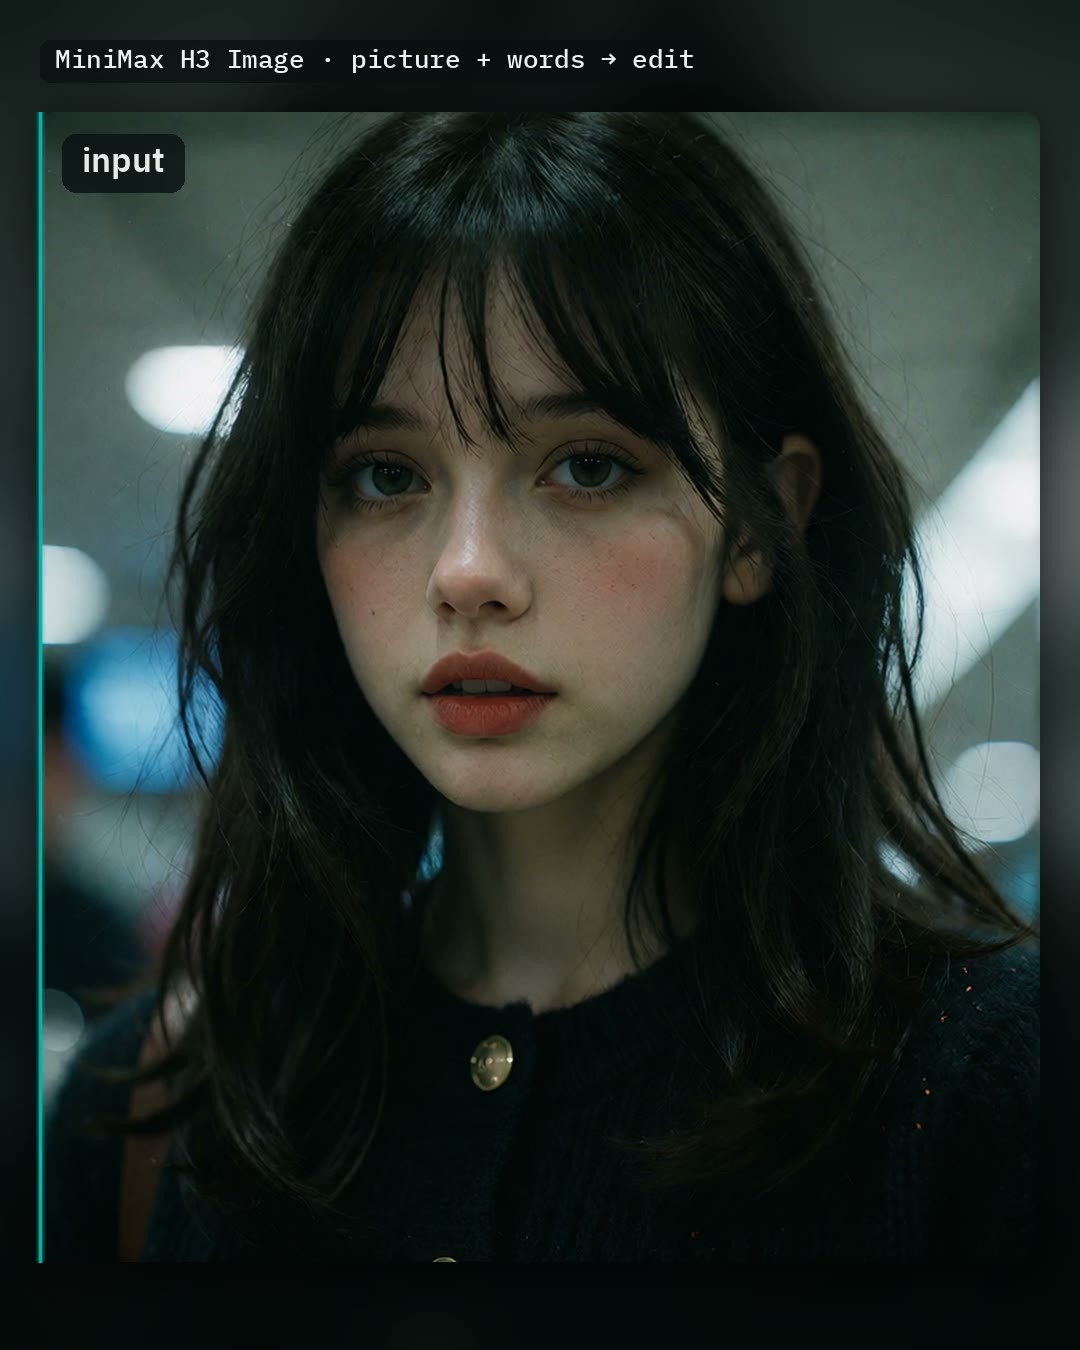
Reasons for Recommendation
- New model (workflow, not new weights); supports text-to-image, instruction-based editing, and multi-image reference composition for H3 Image, e.g., "Put the jacket from image 2 on the person in image 1"
- The author specifies the test environment (ComfyUI master branch commit ede4e5f + AusBoss nodes 2.22.0, tested on both high and low VRAM tiers) and lists required model files, placement directories, and sizes: High VRAM uses the int8 ConvRot base model (21.0 GB), Low VRAM uses w4a8 (12.5 GB), both sharing the Qwen3-VL 32B nvfp4 text encoder and H3 Image VAE
- Comprehensive switches: Auto prompt uses a small model to expand a few words into a long description; Size toggles between 4 MP / 16 MP; Fast uses a pDMD 2-step LoRA to reduce steps from 6 to 2; optional SeedVR2 upscales 4 MP results by 2x
- The author claims that on an RTX 5090, generating a new 16 MP image takes about 22 seconds, and editing a 16 MP image takes about 35 seconds; includes 1 video segments + 6 visible example images
How to Use
- First update ComfyUI to a version after 0.44.0 and AusBoss nodes to 2.22.0, then drag in the workflow and click Run directly; it comes with a complete default prompt
- For your own generation: write a full long description, or enable Auto prompt and write just a few words; for editing: enable Edit a picture, load an image, and write the changes (e.g., "Make it snow."); attach reference images sequentially from picture 2 to picture 8, and explicitly name them in the prompt as "picture 2"
- Put text that should appear in the image inside quotes; disable Auto prompt if the prompt is already very complete (the author notes that rewriting the opening prompt causes hand artifacts); do not enable Fast when creating posters or covers
Risks and Limitations
- Depends on new H3 Image support (only entered ComfyUI via 11-10) and AusBoss's custom nodes; older ComfyUI versions cannot run it; the full model set (base model + 32B text encoder + optional expansion model, acceleration LoRA, SeedVR2) requires a large download
- MiniMax-H3-Image community license: According to the Comfy quantization author's summary, it does not cover the EU, UK, South Korea, or the US; outputs cannot be used to improve other AI models; separate authorization is required if annual revenue exceeds 100 ten thousand USD or if offering hosting services
- This is the image model for H3, it does not generate videos; timing figures are as claimed by the author
[S] Friend's POV - MiniMax H3 · H3 V1
LoRA · New Model · Author AriaMaiven · Published 11-11 09:15 · Downloads 86
A video style LoRA for "friend's phone snapshot" aesthetics: wide composition, subjects pushed to the edges of the frame, flat phone lighting, and camera shake that follows the photographer's laughter.
Part of the same "amateur shooting perspective" series as the author's Smart Glasses POV, with consistent parameter syntax.
Images
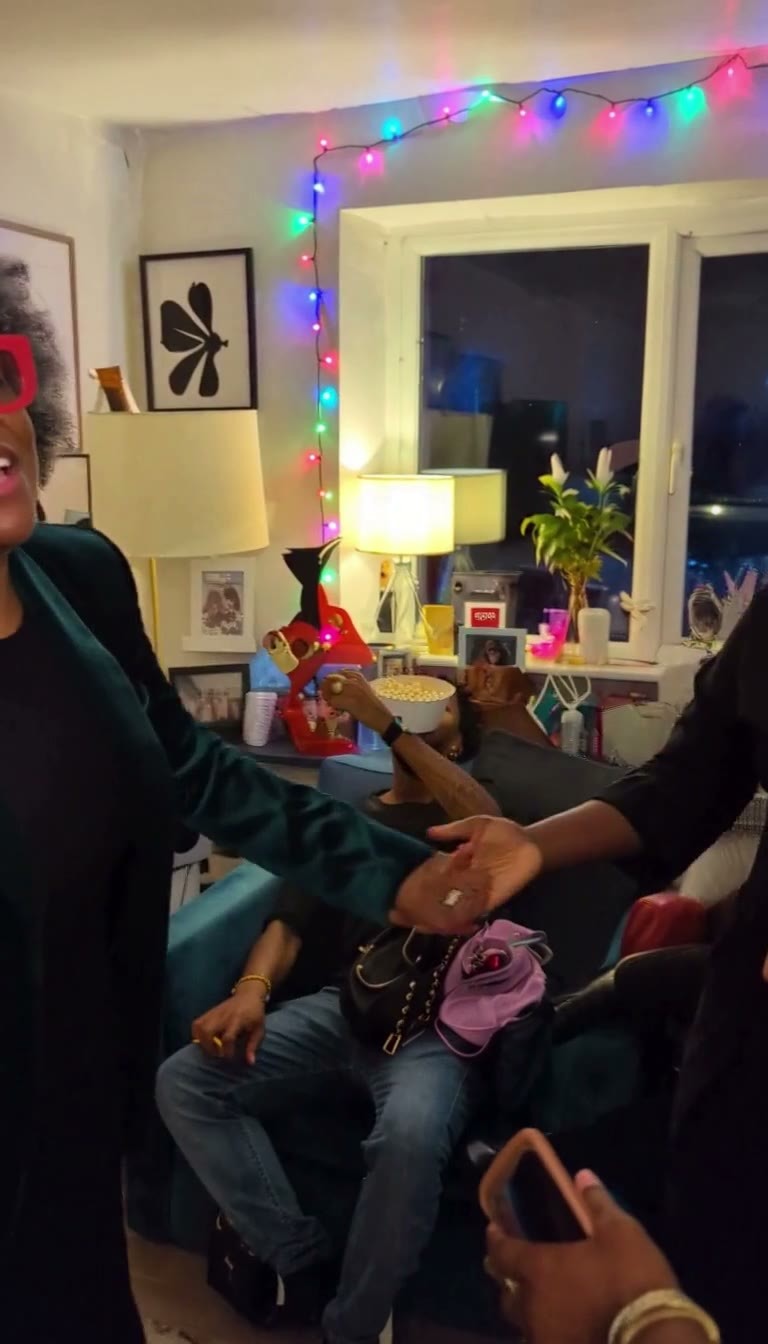
Reasons for Recommendation
- New model; suited for close-up lifestyle videos featuring people, such as parties, night streets, or supermarket aisles, aiming for the "video on a friend's phone" look rather than a cinematic feel
- The author provides complete usage instructions: trigger word celsint, use strength 0.65 for close-up faces (stable faces, retains phone feel), increase to 0.8 for distant subjects, backs turned, or no faces in frame (stronger style, but close faces may distort)
- Specific prompt writing advice: place the style in the first sentence of the H3 prompt; do not mention phone, handheld, shake, exposure, or grain, as these are handled by the trigger word; instead describe "what the friend being filmed is doing" (running behind, being pulled by the wrist, bumped by a guest), which makes the shake look more realistic
- Author's test configuration: MiniMax H3 FL2VA pruned int8 ConvRot text-to-video, 20 steps, res_multistep + simple, 768x1344, 5 seconds; 2 visible example videos
How to Use
- Trigger word celsint; strength 0.65 (close-up faces) to 0.8 (distant or no faces); write the first sentence of the prompt as [Shot 1] Live-action in the celsint style, a medium shot at chest height...
- Use standalone, do not stack with other body or action LoRAs; author tested with text-to-video 20 steps, res_multistep, simple, 768x1344
Risks and Limitations
- Commercial use allowed but requires attribution of the style source; reprinting or using its outputs to train other models requires prior permission from the author
- 1 examples are hidden; only text-to-video was tested, performance for image-to-video / Ref2VA is not specified by the author
Trigger Word: celsint
Recommended (3)
[A] Minimax H3 Image Quants - comfy-native - fp8_scaled / nvfp4 / GGUF Q6 / Q4 / Q3 / Q2_mix · v1.0
Base Model / Checkpoint · New Model · Author Thasmodius · Published 11-11 07:19 · Downloads 47
Supplementary precision pack for the H3 Image base model: fp8 scaled, NVFP4, and GGUF Q6_K / Q4_K / Q3_K / Q2_K mixed quantizations not available in the official Comfy repository, containing only the diffusion model.
Images
Reasons for Recommendation
- New model (quantized weights); for users wanting to run H3 Image text-to-image and editing on RTX 40 / 50 or any GPU but lacking VRAM for the official bf16
- Clear use cases for each tier: fp8 scaled 21.0 GB for RTX 40 / 50; NVFP4 12.5 GB runs natively only on RTX 50 and is fastest (author claims 2048x2048 at approx 3.4 steps/s on RTX PRO 6000, vs approx 2.1 steps/s for fp8); GGUF Q6_K 17.5 GB, Q4_K 12.5 GB, Q3_K 10.0 GB for any GPU; Q2_K mix 9.25 GB is experimental, author claims noticeable softening in image quality
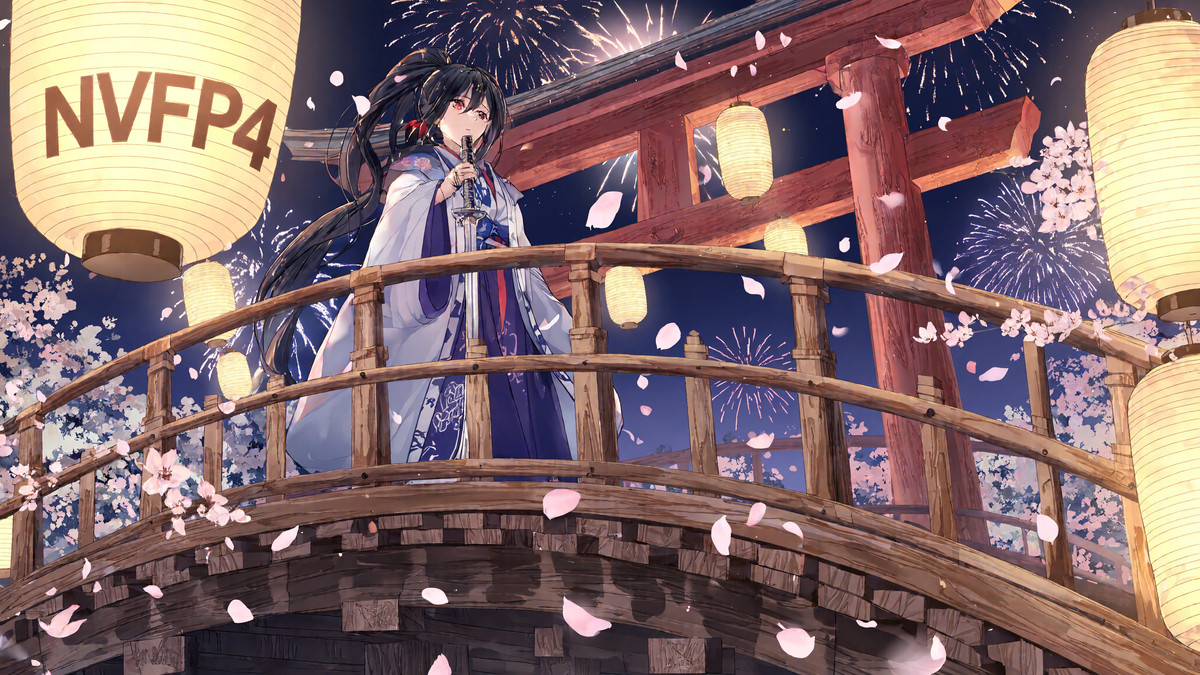
- Author states the quantization scope matches Comfy's official int8 / w4a8 (same 200 transformer layers, covering 95.8% of weights), with the rest remaining as official bf16, and provides a comparison page on HF; 8 visible example images
How to Use
- Requires ComfyUI 0.44 or newer; open the built-in "MiniMax H3 Image" template in ComfyUI and select the file in Load Diffusion Model; keep template settings at 6 steps, euler, simple, cfg 1
- Obtain the text encoder qwen3vl_32b_minimax_h3_nvfp4_awq (or int8 convrot) and VAE from the Comfy-Org MiniMax-H3-Image repository
- For GGUF, replace the loader node with Unet Loader (GGUF) and patch ComfyUI-GGUF first (run the author's patch script, or manually add "minimax_h3" to IMG_ARCH_LIST in loader.py), otherwise you will get an Unexpected architecture type error
- Author claims the model performs best between 4–20 MP, performs poorly at low resolutions, and requires long, detailed English prompts
Risks and Limitations
- MiniMax-H3-Image Community License: The author's original text states that the license does not cover the EU, UK, South Korea, or the US; the model and its outputs must not be used to improve other AI models; if annual revenue exceeds 100 USD or if offering hosting services, prior written permission from MiniMax is required; commercial products must label MiniMax-H3-Image
- GGUF dependencies rely on patches not yet merged upstream; 2 examples are hidden; this is an image model and does not generate video
【A】Smart Glasses POV - MiniMax H3 · H3 V1
LoRA · New Model · Author AriaMaiven · Published 11-11 09:15 · Downloads 122
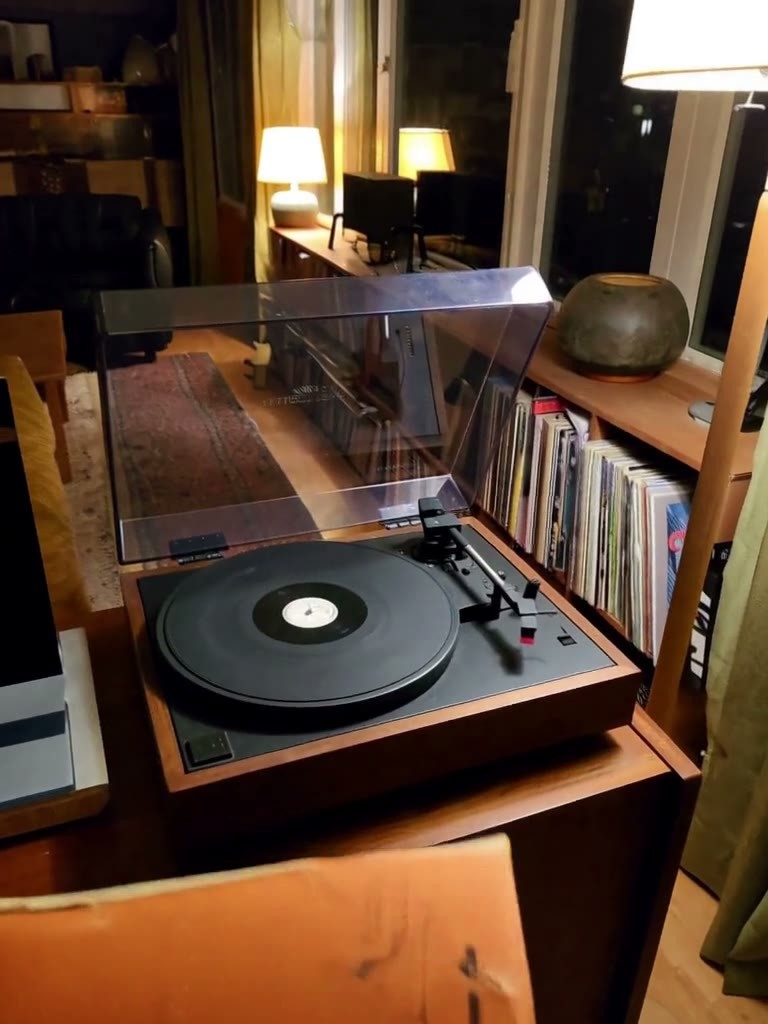
A first-person video style LoRA for smart glasses: wide-angle without distortion, head movement following the wearer looking down at their hands, and the wearer's own hands entering the frame from below.
Image
Reasons to Recommend
- New model; suitable for everyday first-person videos "seen from behind the eyes," such as cooking, cycling, pulling books from shelves, or opening doors to greet dogs
- Strength levels are clearly defined: 0.6 is recommended; 0.8 offers a stronger style but hands no longer follow descriptions; 1.0 is excessive
- The author reminds users to fully describe hands every time (skin tone, rings, watches, nails, sleeves; write "no tattoos" if there are none), as the LoRA will fill in unspecified parts; the author's test configuration was FL2VA pruned int8 ConvRot text-to-video, 20 steps, res_multistep + simple, 768x1024, 5 seconds
How to Use
- Trigger word povsint, strength 0.6; start the prompt with [Shot 1] Live-action in the povsint style, an eye-level shot...
- Do not write glasses, POV, first person, or fisheye, as the trigger word handles these; use alone, do not stack with body or action LoRAs
Risks and Limitations
- The author notes that hands sometimes appear one shade lighter, and small tattoos occasionally appear on wrists; check before publishing
- Only 1 visible example videos are shown (4 are hidden); permission from the author is required for reposting or using outputs to train other models
Trigger Word: povsint
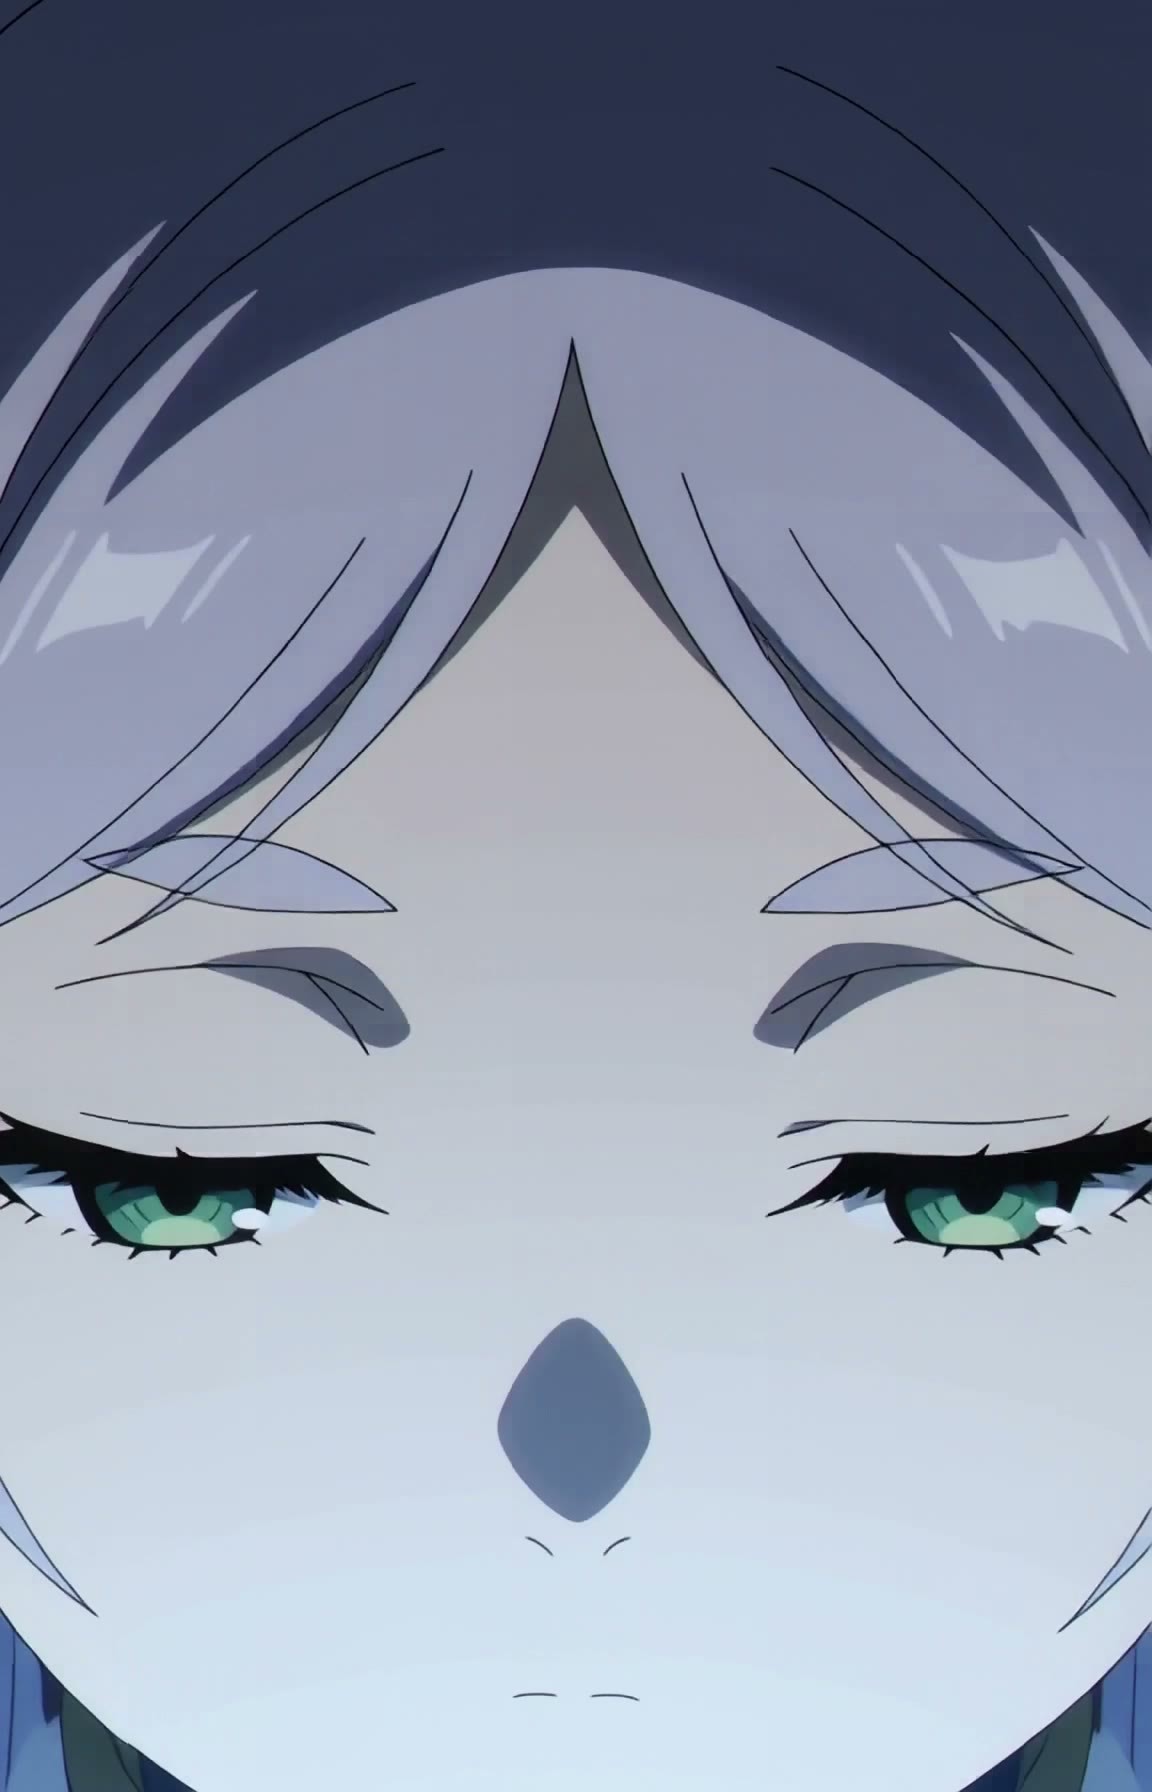
【A】Frieren Anime H3 Style Lora · v1.0
LoRA · New Model · Author tazmannner379 · Published 11-10 21:24 · Downloads 259
A video LoRA in the style of the anime "Frieren: Beyond Journey's End": reproduces the anime's art style, including some character voice lines and background music.
Image
Reasons to Recommend
- New model; suitable for creators making Frieren fan shorts, anime-style text-to-video / image-to-video, and projects requiring characters to speak
- Training data specified: 672 audio-containing episode clips + 721 screenshots; the author has posted a training report, prompt guide, and character design sheets with voice references for 27 characters on Hugging Face
- Provides checkpoints for 3 training steps (3150 / 3900 / 4200 steps), with the main file being the 4200 step checkpoint; 6 visible example videos, approximately 16 hours after release with 259 downloads and 36 likes
How to Use
- Start the prompt with the trigger word 2d anime style, Frieren style,
- The author's HF page recommends the 4200 step checkpoint at strength 1.0; trained on an FL2VA base model, it can also be used with character design sheets as reference images on a Ref2VA base model
- To consistently reproduce a specific character, follow the author's suggestion to pair with the character reference and voice references from the HF page
Risks and Limitations
- Trained using official anime footage and character voice acting (the author states on the HF page that they do not own the copyright and it is for learning purposes only); verify rights before public or commercial use
- Steps, CFG, and sampler are not listed on the Civitai page; check the guide on HF; 6 examples are hidden
Trigger Words: 2d anime style, Frieren style
Worth Watching (9)
【B】Minimax H3 Image INT8/INT6/INT4 · Minimax H3 IMAGE INT8
Base Model / Checkpoint · New Model · Author tsolful · Published 11-11 07:17 · Downloads 67
The INT8 ConvRot (W8A8) quantized version of the H3 Image base model, 19.54 GB; the author recommends this as the default choice among the three quantization levels.
Image
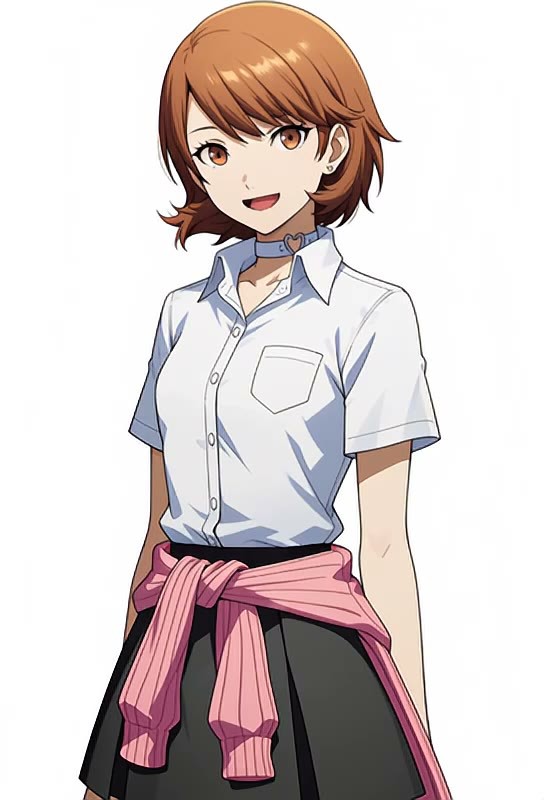
【B】Yukari Takeba Voice - Persona 3 - Audio Only [Minimax H3] · Minimax H3 v1.0
LoRA · New Model · Author OneMoreLurker · Published 11-11 12:04 · Downloads 20
A pure audio character voice LoRA: trained on the Japanese voice of Yukari Takeba from "Persona 3 Reload," enabling H3 to generate dialogue in this character's voice.
Image
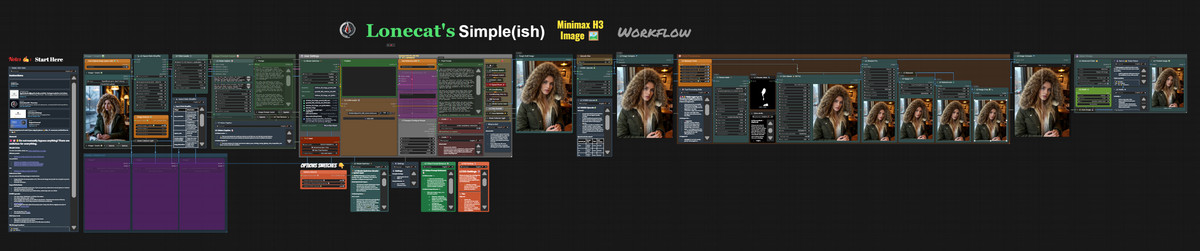
【B】Lonecat’s Simple Speed Boost 🚀 Workflows | 简易加速工作流 (MiniMax H3, Krea 2, Qwen 2.1, ZIT, Klein_9b, Illustrious, Flux, Wan2.2, Qwen Image Edit) · Simple Minimax Image 🖼️
Workflow · Version Update · Author lonecatone23 · Published 11-11 11:45 · Downloads 10
The newly added H3 Image version (Simple Minimax Image) in Lonecat's simple workflow collection: an annotated H3 Image reference image generation workflow, with the author adding a skin master node to improve skin texture.
Image
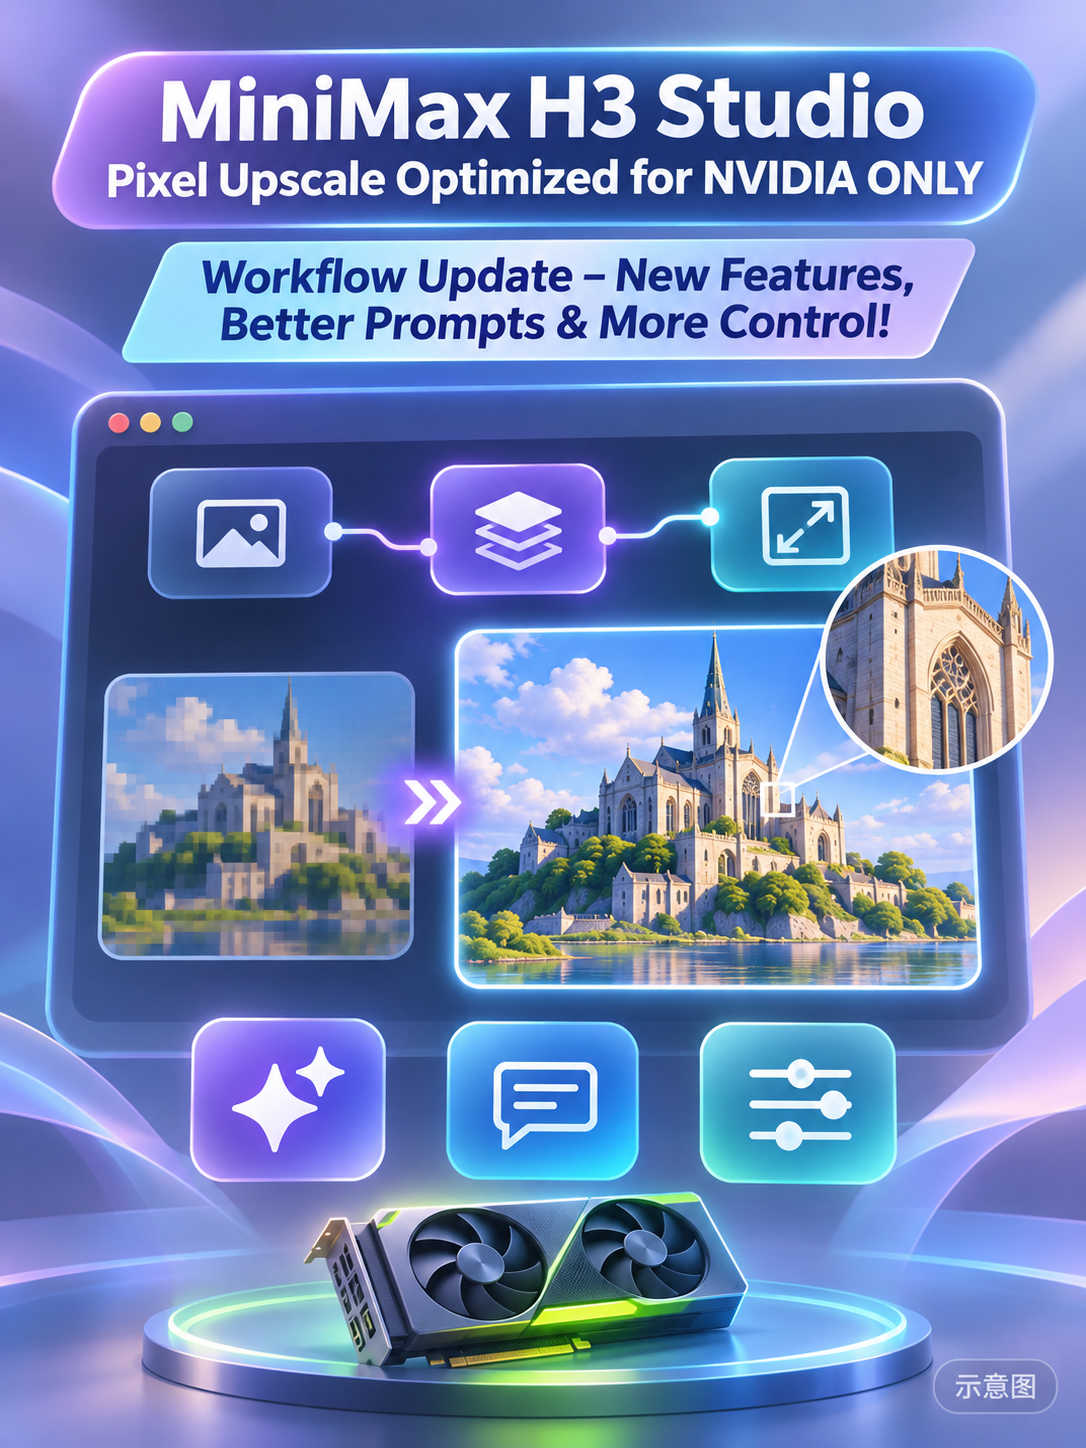
【B】MInimax H3 Studio, Pixel Upscale Optimized for NVIDIA ONLY · v3.0
Workflow · Version Update · Author hRUSTIN474 · Published 11-11 04:50 · Downloads 57
H3 Studio video workflow v3.0: includes three branches for text-to-video / image-to-video / reference-image-to-video with automatic prompt writing, multi-scene continuation, and post-processing with NVIDIA-specific upscaling and HDR after output.
Image
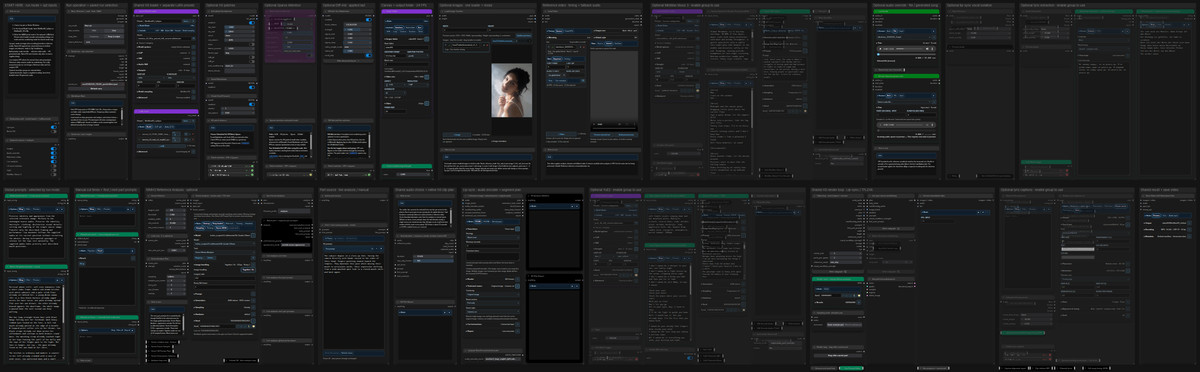
【B】MiniMaxH3 Lipsync / TLF2VA · Nova.3
Workflow · Version Update · Author Rvage · Published 11-11 00:44 · Downloads 50
H3 lip-sync / multi-scene video workflow Nova.3: uses character images + existing recordings to create singing or speaking lip-sync videos, or utilizes native H3 text-to-video / image-to-video / first-last frame generation, rendering by scene segments with the ability to pause and resume or restart from a specific segment.
Image
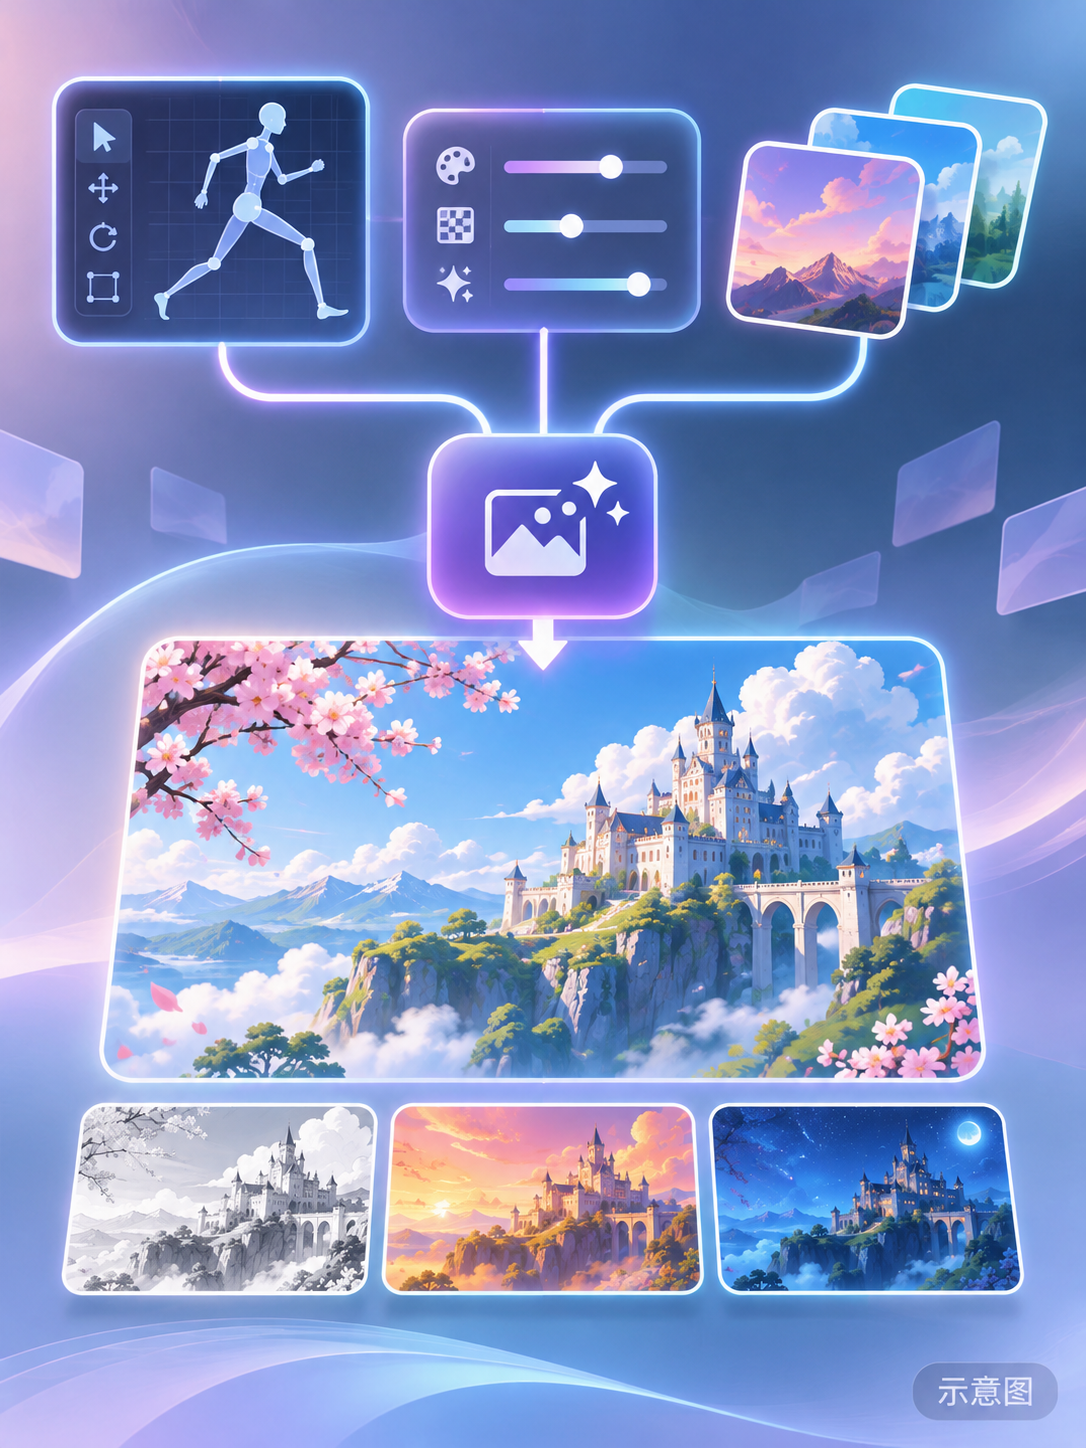
【B】H3 Image w/ Pose Studio + Other Advanced Features [FoxFurEssence] · v1.0
Workflow · New Model · Author foxydits · Published 11-11 08:56 · Downloads 159
A multi-functional H3 Image workflow: text-to-image / image-to-image / generation with up to 9 reference images, featuring a toggleable Pose Studio for posing, and the ability to extract a frame from video as a reference image.
Image
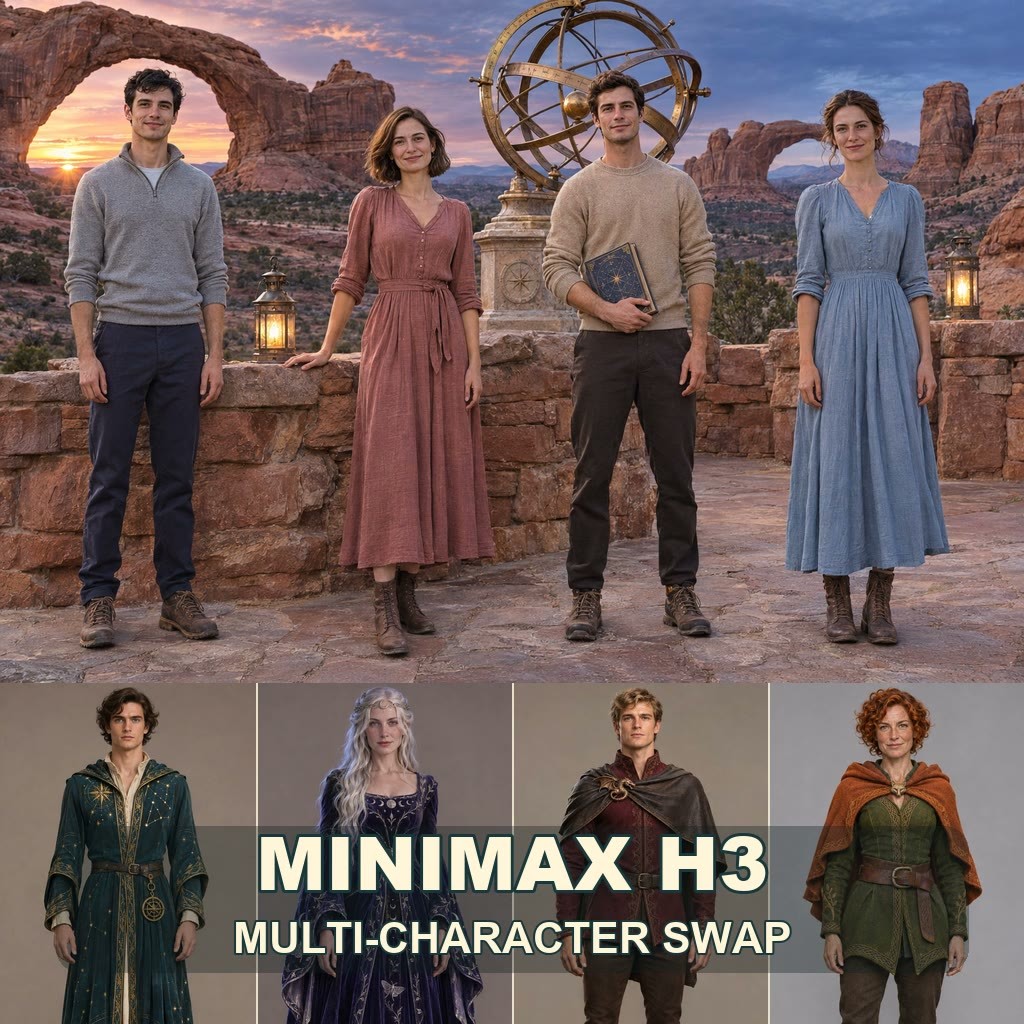
【B】MiniMax H3 Multi-Character Swap in Images | ComfyUI · v1.0
Workflow · New Model · Author BearGhasemian · Published 11-11 11:04 · Downloads 7
A character swap workflow for single-frame still images using the reference image node of the H3 video model: provide one reference image per character to replace 1–4 people in an image with specified characters.
Image
【B】Minimax H3 Image INT8/INT6/INT4 · Minimax H3 IMAGE INT6
Base Model / Checkpoint · Version Update · Author tsolful · Published 11-11 07:30 · Downloads 7
The INT6 (W6A8) quantized version of H3 Image on the same page, 15.61 GB, falling between INT8 and INT4; this level is not available in the official Comfy repository.
Image
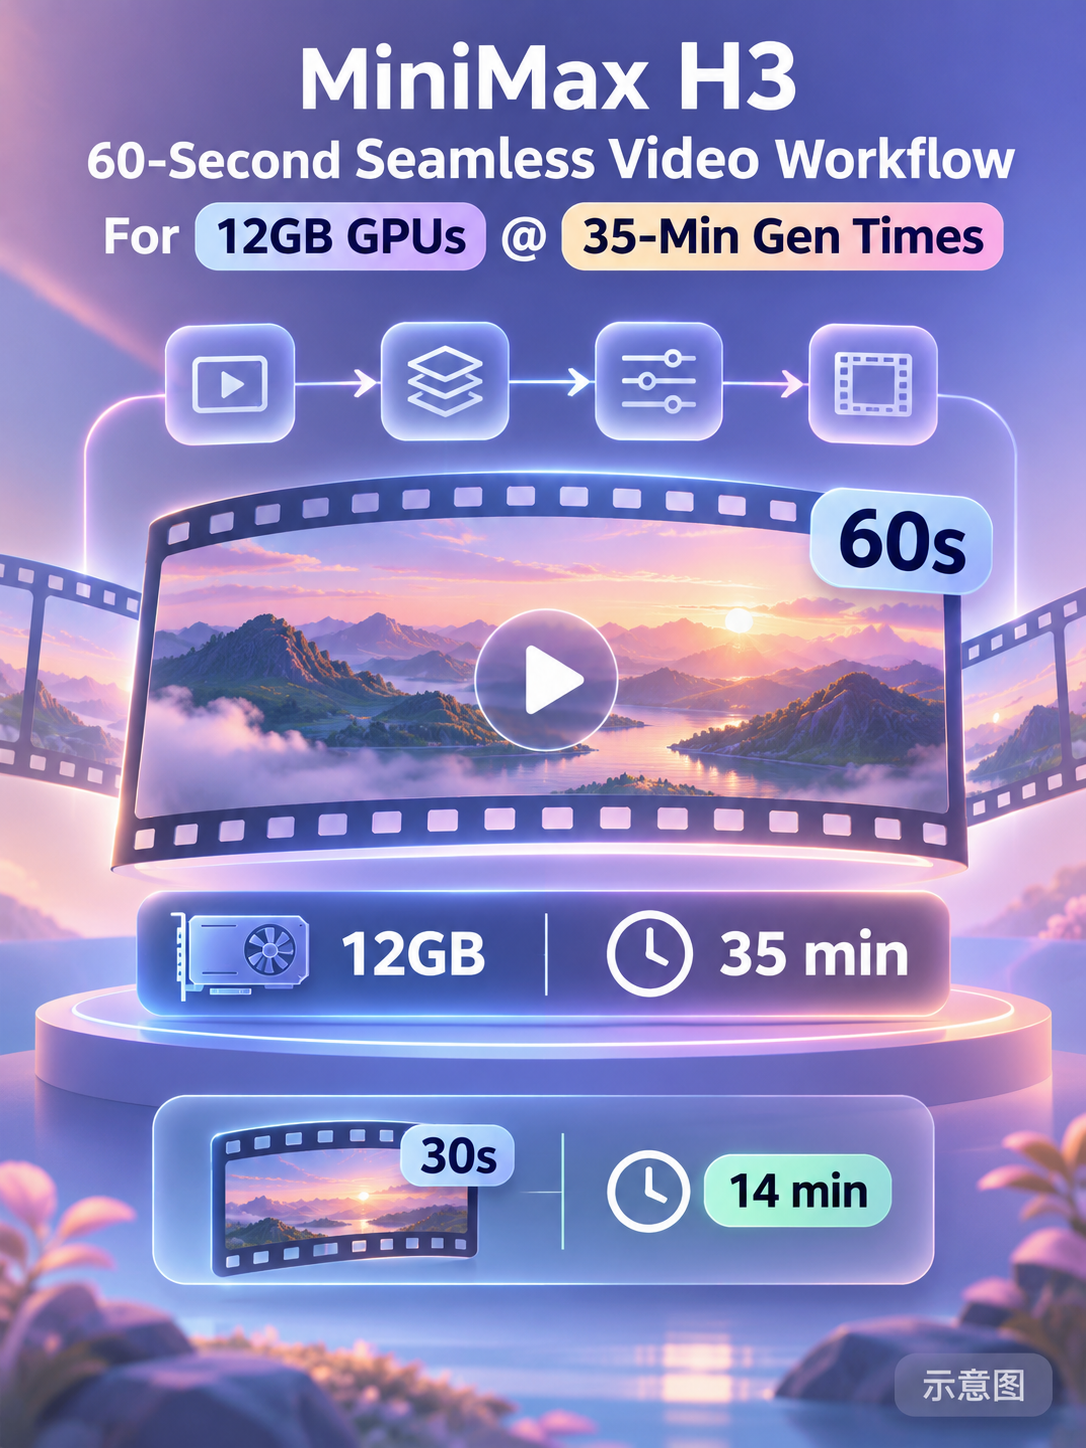
【B】MiniMax H3 60-Second Seamless Video Workflow For 12GB GPUs @ 35-Min Gen Times · v1.2
Workflow · New Model · Author vortis23 · Published 11-11 12:46 · Downloads 3
An H3 long video workflow v1.2 runnable on 12GB GPUs: uses the H3 Motion Director node to segment by timeline, with the author claiming it generates continuous tracking shots up to one minute long in approximately 35 minutes.
Image
Included Only (9)
- (prevent melting faces)MiniMax H3-Image base workflow · base workflow — Workflow: The "Prevent Melting Faces" H3 Image base image generation workflow; the model page description contains only a single period.
- Aliyah Belwyn · MiniMaxH3 — LoRA: A character LoRA for the author's original fictional character Aliyah Belwyn (a harpist from Bruges), ported from the Anima / ZImageTurbo version to H3.
- Minimax H3 Image INT8/INT6/INT4 · Minimax H3 IMAGE INT4 — Base Model / Checkpoint: The quantized version of the H3 Image INT4 (W4A8 GPTQ) from the same page, 12.77 GB, the smallest among the three tiers, saving only VRAM without increasing speed.
- MiniMax-H3-Image · v1.0 — Workflow: An image generation workflow named MiniMax-H3-Image; the description consists only of the title and "v1".
- mini max image - BETTER RESULTS workflow - very nice quality with FASTER prompt upsampler · v1.0 — Workflow: A simple workflow adapted from the Qwen 2.1 image generation workflow for use with H3 Image, named to indicate it includes a faster prompt upsampler.
- Esmae Belwyn · MiniMaxH3 — LoRA: A character LoRA for the author's original fictional character Esmae Belwyn (a florist by the canals of Bruges), ported from the MOSS Image version to H3.
- Faye Belwyn · MiniMaxH3 — LoRA: A character LoRA for the author's original fictional character Faye Belwyn (an antique textile restorer from Bruges), ported from the Krea 2 / ZImageTurbo / MOSS Image versions to H3.
- Anaya Von Vergin · MiniMaxH3 — LoRA: A character LoRA for the author's original fictional character Anaya Von Vergin (a museum curator from Oxford), ported to H3 from multiple versions including SDXL, Flux, Anima, and MOSS Image.
- Ruth Belwyn · MiniMaxH3 — LoRA: A character LoRA for the author's original fictional character Ruth Belwyn (a bookbinder from Bruges), released on H3 simultaneously with the Krea 2 version.
Data: Civitai public API (base model MiniMax H3), inclusion window 11-10 20:31 → 11-11 13:03 (Beijing Time). Recommendations have been reviewed by editors; download counts reflect only popularity.